Knowledgebase (2523)
Children categories
Add, Delete, and Modify Shapes in Word with JavaScript in React
2026-09-21 02:33:48 Written by Amy ZhaoWorking with shapes in Word documents is one of the most common requirements in day-to-day office development. Whether you are stamping a rounded-rectangle signature box onto a contract template, annotating approval steps with a group of flowchart shapes, cleaning up leftover decorative shapes in a document, or restyling the shapes in an old template to match a new brand palette, manipulating shapes dynamically keeps document content in sync with your business data. Spire.Doc for JavaScript handles Word shapes entirely in the browser via WebAssembly, using a virtual file system (VFS) to manage fonts, documents, and image resources — no backend server required.
This article covers three core features:
For installation and project setup, refer to Integrating Spire.Doc for JavaScript in a React Project. The examples below assume Spire.Doc is installed and the WebAssembly module is initialized.
Add Shapes to a Word Document
Adding shapes involves three phases: first, load the font files into the WASM virtual file system via FetchFileToVFS; then instantiate a Document, add a section and a paragraph in turn, and call Paragraph.AppendShape to insert a shape of the specified type and size into the paragraph, anchoring it to the page with HorizontalOrigin/VerticalOrigin while setting its absolute coordinates through HorizontalPosition/VerticalPosition; finally, save the document, read the generated file from VFS, wrap it as a Blob, and trigger a browser download.
function App() {
  const appendShape = async () => {

    const docModule = window.wasmModule?.spiredoc;

    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

      // Create a new document
    const doc = new docModule.Document();

      // Add a section
    let sec = doc.AddSection();

      // Add a paragraph to hold the shapes
    let paragraph = sec.AddParagraph();

    let x = 60, y = 40, lineCount = 0;
    for (let i = 1; i < 20; i++) {
      if (lineCount > 0 && lineCount % 8 == 0) {
        // Start a new page once 8 rows are filled, and reset the starting coordinates
        paragraph.AppendBreak(docModule.BreakType.PageBreak);
        x = 60;
        y = 40;
        lineCount = 0;
      }

        // Add a shape and set its size
      let shape = paragraph.AppendShape(50, 50, docModule.ShapeType.fromValue(i));

      // Position the shape in absolute coordinates relative to the page
      shape.HorizontalOrigin = docModule.HorizontalOrigin.Page;
      shape.HorizontalPosition = x;
      shape.VerticalOrigin = docModule.VerticalOrigin.Page;
      shape.VerticalPosition = y + 50;

      // Calculate the coordinates of the next shape
      x = x + shape.Width + 50;
      if (i > 0 && i % 5 == 0) {
        y = y + shape.Height + 120;
        lineCount++;
        x = 60;
        }
    }

    // Save the document
    const outputFileName = "Add Shapes.docx";
    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx });
    // Release resources
    doc.Dispose();

    const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([modifiedFileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

 return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add Shapes to a Word Document</h1>
      <button onClick={appendShape}>
        Generate
      </button>
    </div>
  );
}
export default App;
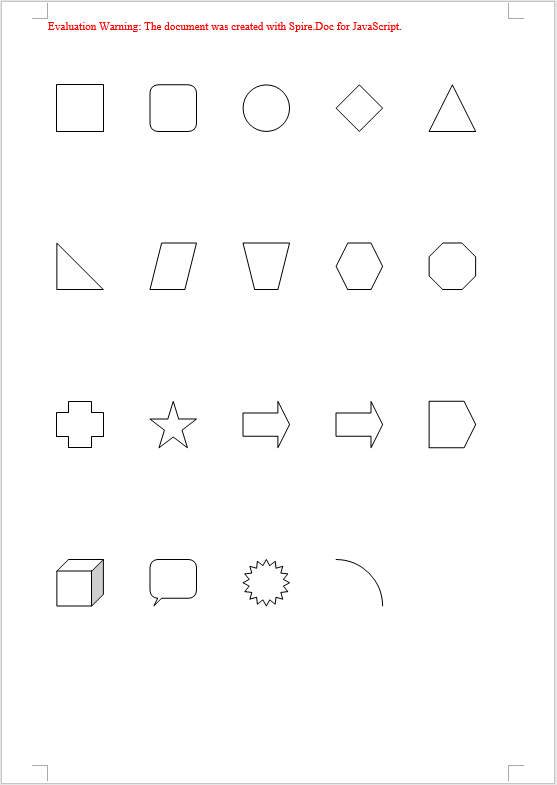
The code above inserts 19 different preset shapes in a loop, each 50×50, retrieving the shape type one by one with ShapeType.fromValue(i) and laying them out in rows and columns from the page origin — 5 shapes per row, and an automatic page break via AppendBreak once 8 rows are filled
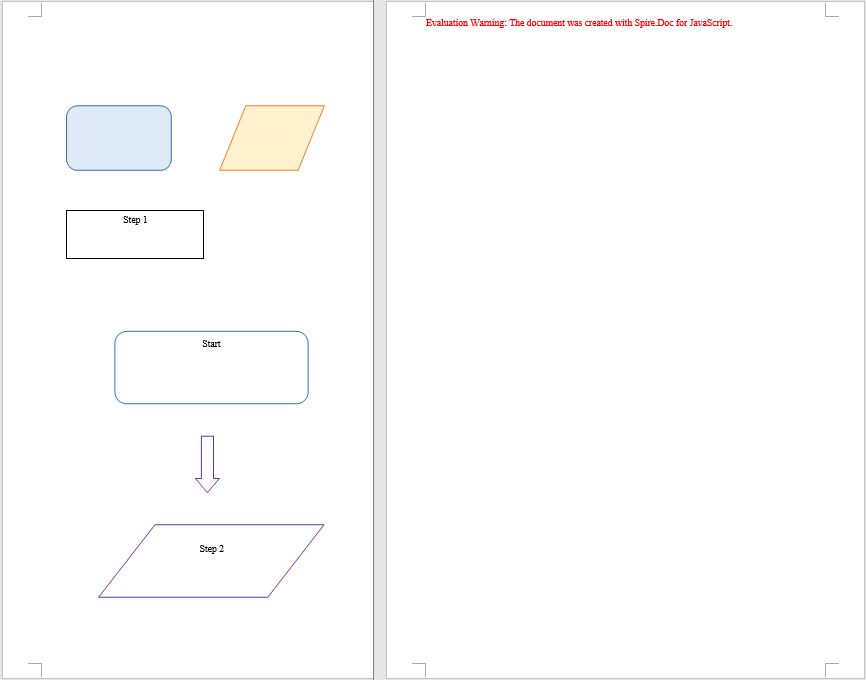
When you need to insert several related shapes at once — building a flowchart out of rectangles, parallelograms, and arrows, for example — you can instead call Paragraph.AppendShapeGroup to create a shape group first, then add text boxes, arrows, and other child shapes to it with ChildObjects.Add so they are laid out together. Coordinates inside a shape group are relative to the group itself, so you need to work out the scale factor with Width / 1000.0 and Height / 1000.0, then divide the target coordinates of each child shape by that factor before assigning them to HorizontalPosition/VerticalPosition. A text box is created with new wasmModule.TextBox(doc) and its outline specified through SetShapeType; its Format.LineColor sets the stroke color in exactly the same way as StrokeColor does for a regular shape.
Delete Shapes from a Word Document
Deleting shapes involves three phases: first, load the font files and the Word document to be processed into the WASM virtual file system via FetchFileToVFS; then instantiate a Document and load the file, walk the sections and paragraphs of the document level by level, and use DocumentObjectType to determine whether a child object in a paragraph is a shape — regular shapes and text boxes in a document both exist as type Shape, shape groups are ShapeGroup, while a text box created in memory with new wasmModule.TextBox(doc) and not yet saved is reported separately as TextBox, so all three types must be checked; once identified, collect the objects and remove them from the paragraph one by one with ChildObjects.Remove; finally, save the document, read the generated file from VFS, wrap it as a Blob, and trigger a browser download.
function App() {
  const removeShape = async () => {
    const docModule = window.wasmModule?.spiredoc;
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }
    const inputFileName = 'ShapeTemplate.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}static/data/`);

   // Load the document
    let doc = new docModule.Document();
    doc.LoadFromFile(inputFileName);

    let removedCount = 0;

    // Iterate over every section and paragraph and delete the shapes in each paragraph
    for (let i = 0; i < doc.Sections.Count; i++) {
      let sec = doc.Sections.get_Item(i);
      for (let j = 0; j < sec.Paragraphs.Count; j++) {
        let para = sec.Paragraphs.get_Item(j);

        // Collect the shapes in the paragraph in one pass: regular shapes and text boxes are Shape, shape groups are ShapeGroup
        let shapes = [];
        for (let k = 0; k < para.ChildObjects.Count; k++) {
          let docObj = para.ChildObjects.get_Item(k);
          let objType = docObj.DocumentObjectType;
          if (objType == docModule.DocumentObjectType.Shape
            || objType == docModule.DocumentObjectType.ShapeGroup
            || objType == docModule.DocumentObjectType.TextBox) {
              shapes.push(docObj);
    }
        }

        // Remove the shapes from the paragraph one by one
        for (let m = 0; m < shapes.length; m++) {
         para.ChildObjects.Remove(shapes[m]);
         removedCount++;
        }
      }
    }

    // Save the document
    const outputFileName = "Delete Shapes.docx";
    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx });

    // Release resources
    doc.Dispose();

    const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([modifiedFileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

 return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Delete Shapes from a Word Document</h1>
      <button onClick={removeShape}>
        Generate
      </button>
    </div>
  );
}
export default App;
The code above walks the document structure and removes every shape on the page, while the text content and formatting in the paragraphs stay unchanged
Modify Shapes in a Word Document
Modifying shapes involves three phases: first, load the font files and the Word document to be processed into the WASM virtual file system via FetchFileToVFS; then instantiate a Document and load the file, walk the sections and paragraphs to locate the shape objects within them, and for regular shapes and text boxes set FillColor and StrokeColor directly to change the colors and set Rotation, Width, and Height to adjust the rotation angle and size, while for a shape group you drill down into its ChildObjects and modify each child shape in turn; finally, save the document, read the generated file from VFS, wrap it as a Blob, and trigger a browser download.
function App() {
  const modifyShape = async () => {
    const docModule = window.wasmModule?.spiredoc;
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }
    const inputFileName = 'ShapeTemplate.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}static/data/`);

    // Load the document
    let doc = new docModule.Document();
    doc.LoadFromFile(inputFileName);

    // Iterate over every section and paragraph and modify the shapes in each paragraph
    for (let i = 0; i < doc.Sections.Count; i++) {
      let sec = doc.Sections.get_Item(i);
      for (let j = 0; j < sec.Paragraphs.Count; j++) {
        let para = sec.Paragraphs.get_Item(j);
        for (let k = 0; k < para.ChildObjects.Count; k++) {
          let docObj = para.ChildObjects.get_Item(k);
          let objType = docObj.DocumentObjectType;

          // Modify the fill color, outline color, rotation, and size of regular shapes and text boxes
          if (objType == docModule.DocumentObjectType.Shape) {
            docObj.FillColor = docModule.Color.get_Orange();
            docObj.StrokeColor = docModule.Color.get_Red();
            docObj.Rotation = 15;
            docObj.Width = docObj.Width * 1.2;
            docObj.Height = docObj.Height * 1.2;
          }

          // Modify a shape group: drill into the group and change the outline color of each child shape
          if (objType == docModule.DocumentObjectType.ShapeGroup) {
            for (let n = 0; n < docObj.ChildObjects.Count; n++) {
              let child = docObj.ChildObjects.get_Item(n);
              child.StrokeColor = docModule.Color.get_Purple();
            }
          }
        }
      }
    }

    // Save the document
    const outputFileName = "Modify Shapes.docx";
    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx });

    // Release resources
    doc.Dispose();

    const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([modifiedFileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

 return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Modify Existing Shapes in a Word Document</h1>
      <button onClick={modifyShape}>
        Generate
      </button>
    </div>
  );
}
export default App;
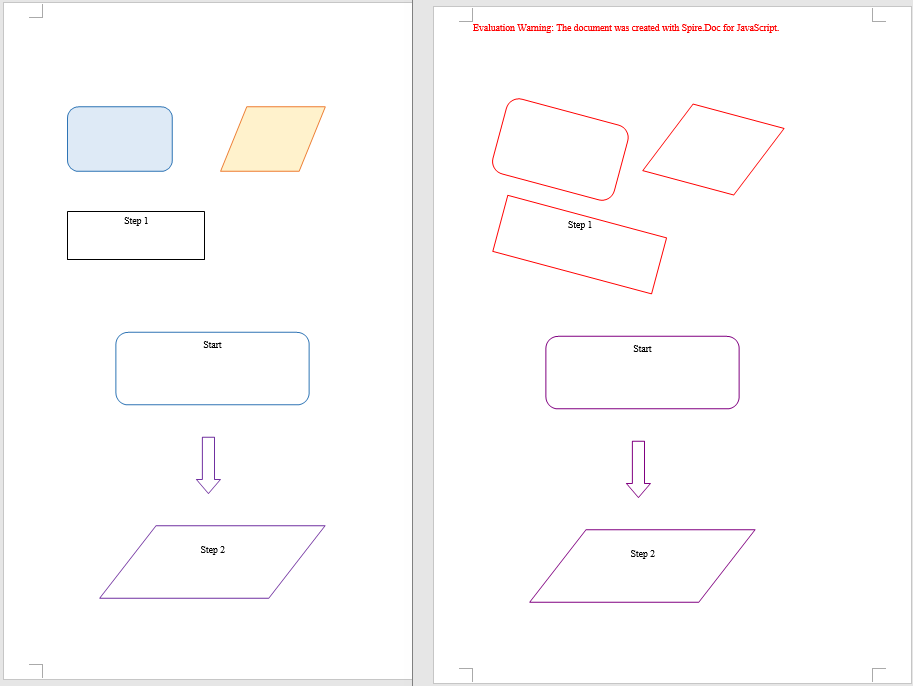
The code above keeps each shape's original position and text while restyling every shape in the document with an orange fill and a red outline, scaling it up to 120% and rotating it 15 degrees, and the child shapes inside shape groups get the new outline color as well
FAQ
Shapes end up misplaced or pushed off the page after being added
Cause: The meaning of the coordinates in HorizontalPosition/VerticalPosition depends on the frame of reference (the origin). If HorizontalOrigin/VerticalOrigin are not set explicitly, the coordinates default to the paragraph or the column, so they shift along with paragraph indentation and page margins, and the shape drifts away from the intended position.
Solution: Specify the frame of reference with HorizontalOrigin/VerticalOrigin first, and then set the coordinate values:
// Position the shape relative to the page
shape.HorizontalOrigin = wasmModule.HorizontalOrigin.Page;
shape.HorizontalPosition = x;
shape.VerticalOrigin = wasmModule.VerticalOrigin.Page;
shape.VerticalPosition = y + 50;
Some objects are missed when deleting shapes
Cause: In Spire.Doc a shape does not have just one DocumentObjectType: regular shapes and text boxes are uniformly Shape, shape groups are ShapeGroup, and a text box created in memory and not yet saved is TextBox. Checking only for Shape will miss shape groups and unsaved text boxes. On top of that, ChildObjects.Remove shifts the indexes of all subsequent child objects forward, so reading ChildObjects.Count while removing during the same loop will also skip some objects.
Solution: Collect all three types into an array in one pass first, then process the array one item at a time; when modifying the child shapes inside a shape group, drill down into its ChildObjects and iterate separately:
// Collect the shape objects of all three types first
if (objType == wasmModule.DocumentObjectType.Shape
  || objType == wasmModule.DocumentObjectType.ShapeGroup
  || objType == wasmModule.DocumentObjectType.TextBox) {
  shapes.push(docObj);
}

// Then remove them together
for (let m = 0; m < shapes.length; m++) {
  para.ChildObjects.Remove(shapes[m]);
}
Get a Free License
Spire.Doc for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Product catalogs, checklists, step-by-step instructions, and clause summaries all read most clearly in a PDF when they are laid out as lists. Typing them out one by one in an editor is workable, but once the entries have to follow the data — exporting a category table or a to-do list to PDF, for example — manual layout stops keeping up: the number of entries, the numbering order, and the indentation levels all have to come from the data.
This article shows how to use Spire.PDF for JavaScript to create unordered lists, ordered lists, and multilevel lists, where unordered lists come in two forms: built-in markers and image markers. It runs on WebAssembly to create and save PDF documents directly in the browser, doing all the work locally and reading and writing files through a virtual file system (VFS) with no backend involved.
This article covers four core features:
- Create an Unordered List in a PDF Page
- Create an Unordered List with Images in a PDF Page
- Create an Ordered List in a PDF Page
- Create a Multilevel List in a PDF Page
Different list types use different classes and marker objects. Pick from the table below:
| List type | List class | Marker configuration | Common values |
|---|---|---|---|
| Unordered list (built-in markers) | PdfList |
PdfMarker + PdfUnorderedMarkerStyle |
Disk, Square, Circle, Asterisk |
| Unordered list (image markers) | PdfList |
the image parameter of PdfMarker (the style becomes CustomImage automatically) |
Any image, scaled to the text line height |
| Ordered list (numbers) | PdfSortedList |
PdfOrderedMarker + PdfNumberStyle (Suffix changes the number suffix, StartNumber changes the starting number) |
Numeric, LowerLatin, UpperLatin, LowerRoman, UpperRoman |
| Multilevel list (nested) | PdfList / PdfSortedList + the list item's SubList |
each level's own Marker and Indent |
the top level and the sublevel can each use a different marker or number style |
For installation and project configuration, see Integrate Spire.PDF for JavaScript into a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Create an Unordered List in a PDF Page
Spire.PDF for JavaScript provides PdfList to create lists, switching the marker shape through the PdfUnorderedMarkerStyle enumeration.
function App() {
  const createBulletLists = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the font into the VFS for the list text
    await window.spire.FetchFileToVFS('ARIAL UNICODE MS.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Create a PDF document and add a blank page
    const doc = new pdfModule.PdfDocument();
    const page = doc.Pages.Add();

    // Font and item content for the list
    const font = new pdfModule.PdfTrueTypeFont({ fontFile: '/Library/Fonts/ARIAL UNICODE MS.TTF', size: 12 });
    const items = ['Fruit Juice', 'Condiments', 'Confectionery', 'Dairy Products', 'Grains & Cereals', 'Meat & Poultry', 'Fruits & Vegetables', 'Seafood'];

    // First list: add items one by one, with Square markers
    const list = new pdfModule.PdfList({ font: font });
    for (const item of items) {
      list.Items.Add(item);
    }
    list.Marker = new pdfModule.PdfMarker({ style: pdfModule.PdfUnorderedMarkerStyle.Square });
    // Brush affects both the marker and the list text
    list.Brush = new pdfModule.PdfSolidBrush({ pdfRGBColor: new pdfModule.PdfRGBColor({ color: pdfModule.Color.get_Navy() }) });
    list.Indent = 10;
    list.TextIndent = 6;
    const first = list.Draw({ page: page, x: 0, y: 40 });

    // Second list drawn below the first one, with Circle markers
    const list2 = new pdfModule.PdfList({ font: font });
    for (const item of items) {
      list2.Items.Add(item);
    }
    list2.Marker = new pdfModule.PdfMarker({ style: pdfModule.PdfUnorderedMarkerStyle.Circle });
    list2.Brush = pdfModule.PdfBrushes.get_Black();
    list2.Indent = 10;
    list2.TextIndent = 6;
    list2.Draw({ page: page, x: 0, y: first.Bounds.Bottom + 20 });

    // Save and read back from the VFS to trigger the download
    const outputFileName = 'BulletList.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Create an Unordered List</h1>
      <button onClick={createBulletLists}>
        Create
      </button>
    </div>
  );
}

export default App;
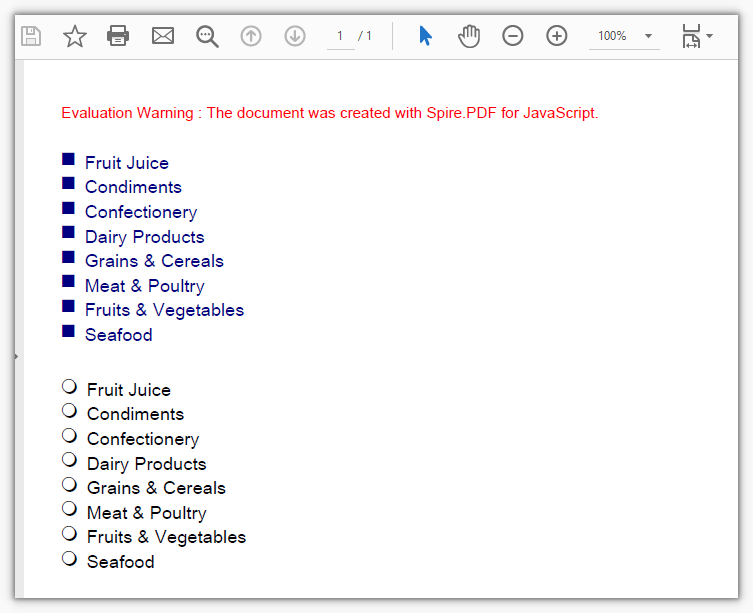
Two unordered lists of the same content, using Square and Circle markers
Create an Unordered List with Images in a PDF Page
Spire.PDF for JavaScript also provides PdfImage to read an image; hand it to PdfMarker and it becomes the bullet marker, with the style switching to CustomImage automatically.
function App() {
  const createImageBulletList = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the font and the bullet image into the VFS
    await window.spire.FetchFileToVFS('ARIAL UNICODE MS.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    await window.spire.FetchFileToVFS('logo.png', '', `${process.env.PUBLIC_URL}/data/`);

    // Create a PDF document and add a blank page
    const doc = new pdfModule.PdfDocument();
    const page = doc.Pages.Add();

    // Font and item content for the list
    const font = new pdfModule.PdfTrueTypeFont({ fontFile: '/Library/Fonts/ARIAL UNICODE MS.TTF', size: 12 });
    const items = ['Fruit Juice', 'Condiments', 'Confectionery', 'Dairy Products', 'Grains & Cereals', 'Meat & Poultry', 'Fruits & Vegetables', 'Seafood'];

    // Read the image and hand it to PdfMarker as the marker; the style becomes CustomImage automatically
    const image = pdfModule.PdfImage.FromFile('logo.png');
    const marker = new pdfModule.PdfMarker({ image: image });

    // Add items one by one and apply the image marker
    const list = new pdfModule.PdfList({ font: font });
    for (const item of items) {
      list.Items.Add(item);
    }
    list.Marker = marker;
    list.Brush = pdfModule.PdfBrushes.get_Black();
    list.Indent = 10;
    list.TextIndent = 6;
    list.Draw({ page: page, x: 0, y: 40 });

    // Save and read back from the VFS to trigger the download
    const outputFileName = 'ImageBulletList.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Create an Unordered List with Images</h1>
      <button onClick={createImageBulletList}>
        Create
      </button>
    </div>
  );
}

export default App;
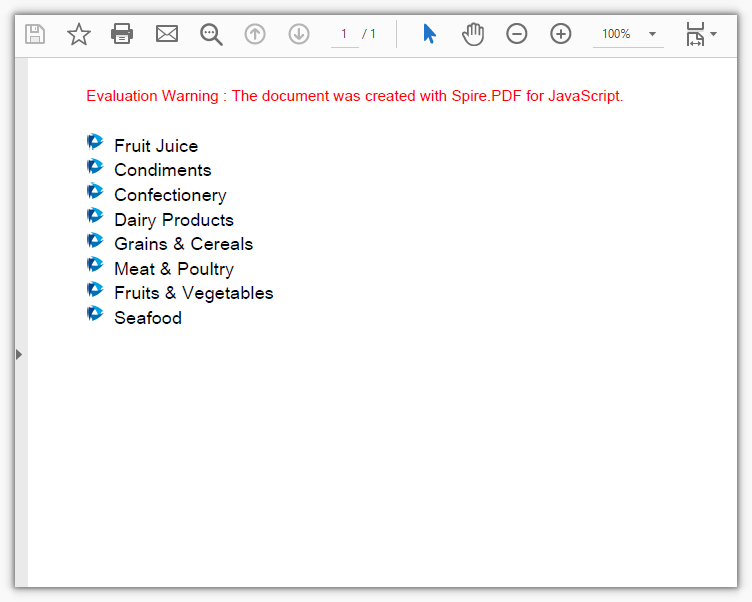
An unordered list using logo.png as the bullet marker
Create an Ordered List in a PDF Page
An ordered list is created by PdfSortedList, its numbers increment automatically with the items, and the number format is decided by the PdfNumberStyle enumeration on PdfOrderedMarker.
function App() {
  const createOrderedLists = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the font into the VFS for the list text
    await window.spire.FetchFileToVFS('ARIAL UNICODE MS.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Create a PDF document and add a blank page
    const doc = new pdfModule.PdfDocument();
    const page = doc.Pages.Add();

    // Font and item content for the list
    const font = new pdfModule.PdfTrueTypeFont({ fontFile: '/Library/Fonts/ARIAL UNICODE MS.TTF', size: 12 });
    const items = ['Fruit Juice', 'Condiments', 'Confectionery', 'Dairy Products'];

    // First list: Arabic numerals, with "." as the default number suffix
    const list = new pdfModule.PdfSortedList({
      marker: new pdfModule.PdfOrderedMarker({ style: pdfModule.PdfNumberStyle.Numeric, font: font }),
    });
    list.Font = font;
    for (const item of items) {
      list.Items.Add(item);
    }
    list.Indent = 12;
    list.TextIndent = 6;
    list.Brush = pdfModule.PdfBrushes.get_Black();
    const first = list.Draw({ page: page, x: 0, y: 40 });

    // Second list: uppercase Roman numerals, with the suffix changed to ")"
    const marker = new pdfModule.PdfOrderedMarker({ style: pdfModule.PdfNumberStyle.UpperRoman, font: font });
    marker.Suffix = ')';
    const list2 = new pdfModule.PdfSortedList({ marker: marker });
    list2.Font = font;
    for (const item of items) {
      list2.Items.Add(item);
    }
    list2.Indent = 12;
    list2.TextIndent = 6;
    list2.Brush = pdfModule.PdfBrushes.get_Black();
    list2.Draw({ page: page, x: 0, y: first.Bounds.Bottom + 20 });

    // Save and read back from the VFS to trigger the download
    const outputFileName = 'NumberedList.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Create an Ordered List</h1>
      <button onClick={createOrderedLists}>
        Create
      </button>
    </div>
  );
}

export default App;
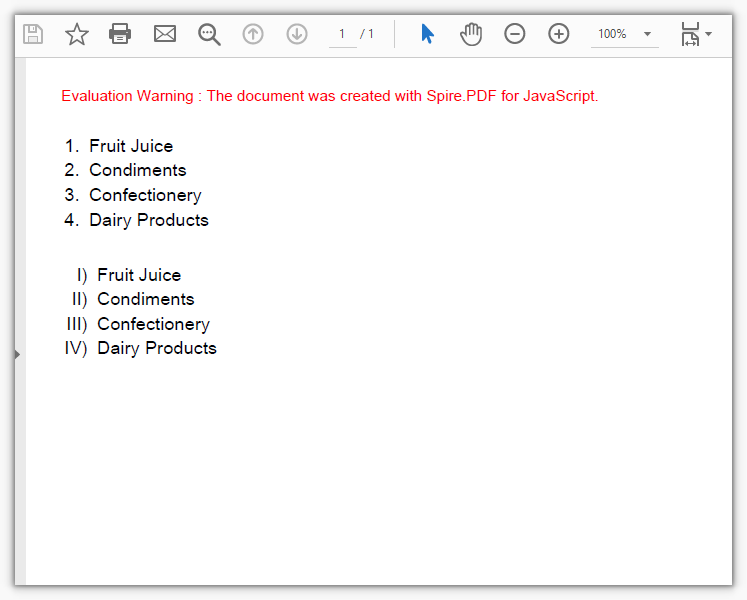
Ordered lists created with Arabic numerals and uppercase Roman numerals
Create a Multilevel List in a PDF Page
A multilevel list is built on the SubList property of an item: attach a sublist to an item and it gains one more level, with the indentation decided by the sublist's own Indent.
function App() {
  const createMultilevelList = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the font into the VFS for the list text
    await window.spire.FetchFileToVFS('ARIAL UNICODE MS.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Create a PDF document and add a blank page
    const doc = new pdfModule.PdfDocument();
    const page = doc.Pages.Add();

    // Font and grouped data for the list
    const font = new pdfModule.PdfTrueTypeFont({ fontFile: '/Library/Fonts/ARIAL UNICODE MS.TTF', size: 12 });
    const groups = [
      { title: 'Beverages & Dairy', children: ['Fruit Juice', 'Dairy Products'] },
      { title: 'Fresh Produce & Grains', children: ['Grains & Cereals', 'Fruits & Vegetables'] },
      { title: 'Meat & Seafood', children: ['Meat & Poultry', 'Seafood'] },
    ];

    // Top-level list: Arabic numerals
    const root = new pdfModule.PdfSortedList({
      marker: new pdfModule.PdfOrderedMarker({ style: pdfModule.PdfNumberStyle.Numeric, font: font }),
    });
    root.Font = font;
    root.Indent = 10;
    root.TextIndent = 6;
    root.Brush = pdfModule.PdfBrushes.get_Black();

    // Attach a sublist to each top-level item, with Disk markers indented by 18 points
    for (const group of groups) {
      const item = root.Items.Add(group.title);
      const sub = new pdfModule.PdfList({ font: font });
      for (const child of group.children) {
        sub.Items.Add(child);
      }
      sub.Marker = new pdfModule.PdfMarker({ style: pdfModule.PdfUnorderedMarkerStyle.Disk });
      sub.Indent = 18;
      sub.TextIndent = 6;
      sub.Brush = pdfModule.PdfBrushes.get_Black();
      item.SubList = sub;
    }

    // Draw the whole multilevel list starting from the top of the page
    root.Draw({ page: page, x: 0, y: 40 });

    // Save and read back from the VFS to trigger the download
    const outputFileName = 'MultilevelList.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Create a Multilevel List</h1>
      <button onClick={createMultilevelList}>
        Create
      </button>
    </div>
  );
}

export default App;
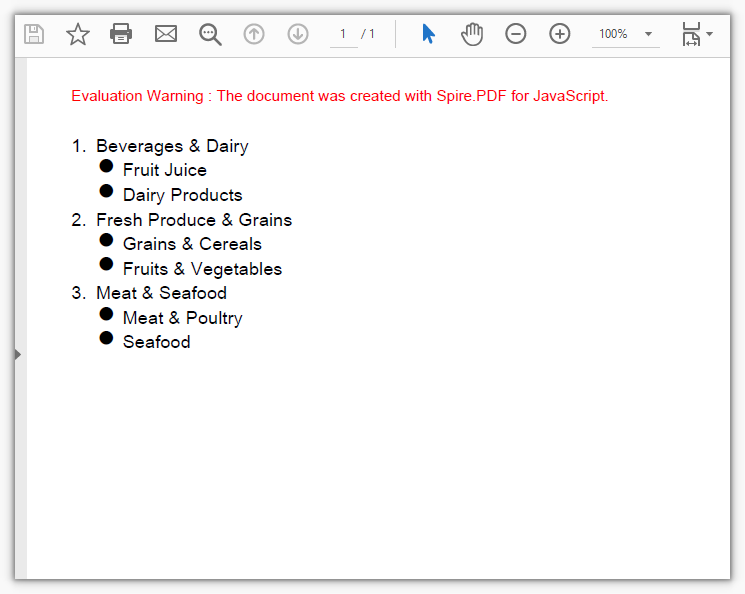
A two-level list made of numbered top-level items and bulleted sublists
FAQ
The list item text does not show up
Cause: List items use the font on the Font property. If it is not set, or the font file has not been loaded into the virtual file system yet, only the bullet markers are left on the page and the text never appears.
Solution: Load the font file into /Library/Fonts/ first, then hand the font object to the list's Font:
// Load the font file into the virtual file system
await window.spire.FetchFileToVFS('ARIAL UNICODE MS.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

// Create the font from that file and pass it in when constructing the list (assigning it to list.Font afterwards works the same way)
const font = new pdfModule.PdfTrueTypeFont({ fontFile: '/Library/Fonts/ARIAL UNICODE MS.TTF', size: 12 });
const list = new pdfModule.PdfList({ font: font });
"Ambiguous call" is thrown when creating a list
Cause: PdfList, PdfSortedList, and PdfMarker all have multiple overloads, so positional arguments leave the runtime unable to tell which one to use; it throws Ambiguous call: arguments (object) match multiple overloads. and lists the available key names in the error. Positional arguments in list.Draw(page, x, y) are rejected the same way.
Solution: Switch to object notation and spell out the parameter names:
// This throws: new pdfModule.PdfList(font)
const list = new pdfModule.PdfList({ font: font });
const sortedList = new pdfModule.PdfSortedList({ marker: marker });
const marker2 = new pdfModule.PdfMarker({ style: pdfModule.PdfUnorderedMarkerStyle.Disk });

// Drawing works the same way: list.Draw(page, 0, 40) throws, so write
list.Draw({ page: page, x: 0, y: 40 });
"IO_FileNotFound_FileName" is thrown when using an image as the bullet marker
Cause: PdfImage.FromFile reads a path inside the virtual file system, so it throws IO_FileNotFound_FileName when the image has not been loaded with FetchFileToVFS first — having the image on disk does not count.
Solution: Load the image into the virtual file system first, then read it with the same file name:
// Load the image into the virtual file system
await window.spire.FetchFileToVFS('logo.png', '', `${process.env.PUBLIC_URL}/data/`);

// Read it with the same file name
const image = pdfModule.PdfImage.FromFile('logo.png');
const marker = new pdfModule.PdfMarker({ image: image });
Get a Free License
If you want to remove the evaluation message from the resulting documents, or to get rid of the feature limitations, contact sales for a temporary license valid for 30 days.
In tendering, the technical bid response is a step every bid must go through, and one of the easiest to get wrong. A tender document runs to dozens or hundreds of pages, and its "Technical Requirements" chapter holds anywhere from dozens to hundreds of clauses. A bidder has to respond to each clause and state the deviation, and a single unanswered clause can invalidate the bid. The responses must also line up with the bidder's own product parameters, test reports and project references — content that is too generic is scored as non-responsive, while inventing parameters or references to pad out a "fully compliant" answer creates far worse contractual and compliance risk if the bid wins. Traditionally a bidding specialist reads clause by clause, looks up the materials and fills in the table row by row. That takes days per bid, and the depth and wording of the responses vary widely between projects and between people.
Compared with the Traditional SDK API
| Traditional Spire.Office for .NET API | Spire.Agent.Office | |
|---|---|---|
| Driving method | Code handles every clause: load the tender document → split clauses with regex → match enterprise materials by keyword → fill the response table row by row, each step controlled in code | Describe the response requirements in natural language; the AI splits the clauses and matches responses clause by clause |
| Code volume | Substantial code to maintain clause-splitting rules, material-matching logic and table filling | Configuration code plus one natural language instruction |
| Clause splitting | Relies on clause numbers and ★▲ symbols as regex anchors; cross-page tables and multi-level numbering are easily split wrongly or dropped | The AI reads semantics together with numbering, so hierarchy and page breaks lose no clauses |
| Material matching | Keyword hits only; two different wordings of the same capability never match | Semantic matching; a capability description in the product manual maps onto a specific clause |
| Deviation assessment | Assessment rules must be hard-coded; better-than / equal / missing is hard to formalize | Each clause is judged against the criteria given in the instruction, and the AI downgrades when evidence is thin |
| Maintainability | A change in tender format or assessment criteria means code changes and a new release | Assessment criteria and chapter structure are adjusted in natural language at any time |
This article shows how to use the Word AI capability of Spire.Agent.Office to hand the tender document and your enterprise technical materials to the AI together and generate, in one pass, a complete technical bid response document containing the technical response table and the technical proposal body. Both single-lot and multi-lot batch usage are covered.
- Single lot: one tender document, one complete technical bid
- Multiple lots: batch output from several tender documents, one consistent standard
For product installation and SpireToken configuration, see Integrating Spire.Agent.Office into a .NET project. The examples below assume Spire.Agent.Office is installed and SpireToken is configured.
Technical Bid Response Generation
Technical bid response generation is the process of extracting the technical requirement clauses from a tender document, writing a response for each clause against the bidder's own technical materials, assessing the deviation, and organizing the result into a submittable technical bid document. The core approach: pass the tender document and the enterprise technical materials to the AI as attachments, have the AI generate a "technical response table" clause by clause under the tender document's original numbering, then continue into the technical proposal body based on those responses — producing the complete technical bid response document in one pass.
This addresses three difficulties the traditional approach cannot get around:
- Semantic correspondence: the tender says "supports deployment in a domestic xinchuang environment" while the enterprise materials say "adaptation for Kylin and UOS completed" — different wording for the same thing, and only semantic understanding maps the two. Keyword matching cannot.
- No omissions: the number of response clauses matches the technical requirements in the tender document exactly, with no merging and nothing dropped, which removes the risk of an invalid bid at the source.
- No fabrication: any clause without support in the enterprise materials is assessed as "Partially Compliant" with the missing items noted, instead of writing extra content to reach "Fully Compliant".
Single lot: one tender document, one complete technical bid
using Spire.Agent.Office.AI;
using Spire.Agent.Office.Extensions;
using Spire.Doc;

// Tender document and enterprise technical materials (data source files)
string[] attachmentPaths = new string[] {
    @"E:\Input\XX-Project-Tender-Document.docx",
    @"E:\Input\Enterprise-Technical-Materials.docx"
};
// Save path
string savePath = @"E:\Output\XX-Project-Technical-Bid-Response.docx";
// SpireToken key
string key = "**************************";
// Natural language instruction
string instruction =
    "Based on the attached tender document and enterprise technical materials, write a technical bid response document: generate a Technical Response Table clause by clause under the tender document's original numbering (No. | Tender Requirement | Our Response | Deviation | Notes), one to one with the requirements and with none omitted; " +
    "deviation takes only Fully Compliant / Partially Compliant / Non-Compliant, and the response must cite the matching model, parameters or project reference from the materials, while any clause without support is assessed Partially Compliant with the missing items noted and nothing invented; " +
    "after the table, continue with a five-chapter technical proposal body: project understanding, technical solution, implementation plan, quality assurance and after-sales service.";

// Call the Word document processing function
AIResult result = ExecuteDemoWord(instruction, savePath, key, attachmentPaths);


// Run the Word document AI processing
static AIResult ExecuteDemoWord(string instruction, string savePath, string key, string[] attachmentPaths)
{
    // Create the AIOptions configuration object
    AIOptions options = new AIOptions();
    // Set the single-call timeout budget (ms)
    options.TimeoutMs = 3600000;
    // Set the SpireToken key
    options.SpireToken = key;

    // Process the Word document with a Document object
    using (Document doc = new Document())
    {
        // Create the AI document processor
        AIDocumentProcessor processor = doc.AI(options);

        // Execute the AI instruction
        return processor.ExecuteInstruction(doc, instruction, savePath, attachmentPaths);
    }
}
The technical bid response document generated by the AI (technical response table + technical proposal body):
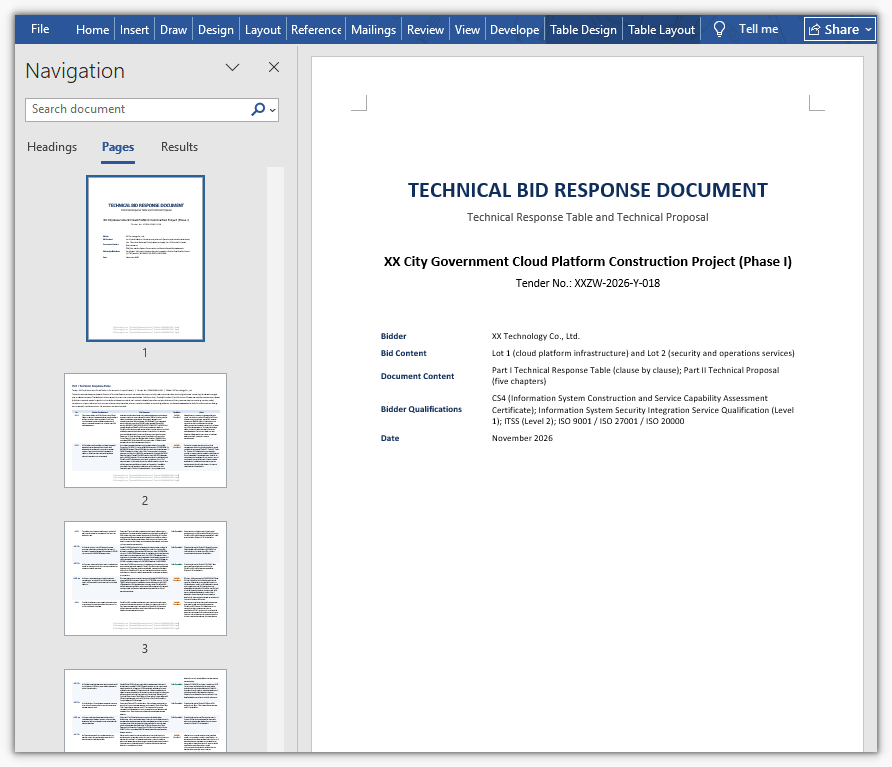
In the generated document the technical response table follows the tender document's original clause numbers one by one, and each row states the response and the deviation. Clauses with matching evidence cite specific product models and project references; the proposal body expands from the response table into the five chapters on project understanding, technical solution, implementation plan, quality assurance and after-sales service. The bidding specialist only has to check that the deviation assessments match reality and supply the materials that are missing, then move on to internal sign-off.
Multiple lots: batch output from several tender documents, one consistent standard
When a project is divided into several lots, each lot's tender document carries different technical requirements, but all lots use the same enterprise technical materials, which makes a single batch call a good fit. Set options.WorkDir to the output directory, pass null as savePath, and hand in every lot's tender document as an attachment — one call then produces several files, each named by the AI after its lot. Because all lots share the same materials and the same instruction, the assessment standard stays consistent by construction.
One caveat: a single call runs against a timeout budget (about 300 seconds by default), so a multi-lot batch should raise options.TimeoutMs; otherwise the call is cut off when the budget runs out.
using Spire.Agent.Office.AI;
using Spire.Agent.Office.Extensions;
using Spire.Doc;

// Tender documents for the lots (data source files)
string[] lotFiles = new string[] {
    @"E:\Input\Lot-1-Technical-Requirements.docx",  // Lot 1 tender document
    @"E:\Input\Lot-2-Technical-Requirements.docx"   // Lot 2 tender document
};
// All lots share the same enterprise technical materials
string materialPath = @"E:\Input\Enterprise-Technical-Materials.docx";
// Output directory
string OutDir = @"E:\Output";
// SpireToken key
string key = "**************************";
// Natural language instruction
string instruction =
    "Based on the attached tender documents and enterprise technical materials, generate a Technical Response Table clause by clause under that lot's original numbering (No. | Tender Requirement | Our Response | Deviation | Notes), one to one with that lot's requirements and with none omitted; " +
    "deviation takes only Fully Compliant / Partially Compliant / Non-Compliant, assessed as met or better → Fully Compliant, differences that do not affect use → Partially Compliant, cannot be met → Non-Compliant; " +
    "the response must cite the matching model, parameters or project reference from the materials, while any clause without support is assessed Partially Compliant with the missing items noted and nothing invented; " +
    "after the table, continue with a five-chapter technical proposal body: project understanding, technical solution, implementation plan, quality assurance and after-sales service; " +
    "the attachments hold two lots, so produce one document per lot, 2 files in total, each named with an 'output' prefix plus the lot and written directly into the working directory with no .csx script.";

// Attachments: two lot tender documents + the shared enterprise technical materials
string[] attachmentPaths = new string[] { lotFiles[0], lotFiles[1], materialPath };

// Call the Word document processing function
AIResult result = ExecuteDemoWordMultiLot(instruction, null, key, OutDir, attachmentPaths);


// Run the Word document AI processing
static AIResult ExecuteDemoWordMultiLot(string instruction, string? savePath, string key, string output, string[] attachmentPaths)
{
    // Create the AIOptions configuration object
    AIOptions options = new AIOptions();
    // Set the working directory to the output directory
    options.WorkDir = output;
    // Set the single-call timeout budget (ms)
    options.TimeoutMs = 3600000;
    // Set the SpireToken key
    options.SpireToken = key;

    // Process the Word document with a Document object
    using (Document doc = new Document())
    {
        // Create the AI document processor
        AIDocumentProcessor processor = doc.AI(options);

        // Execute the AI instruction
        return processor.ExecuteInstruction(doc, instruction, savePath, attachmentPaths);
    }
}
The technical bid response documents generated in batch by the AI (one per lot, named after the lot)
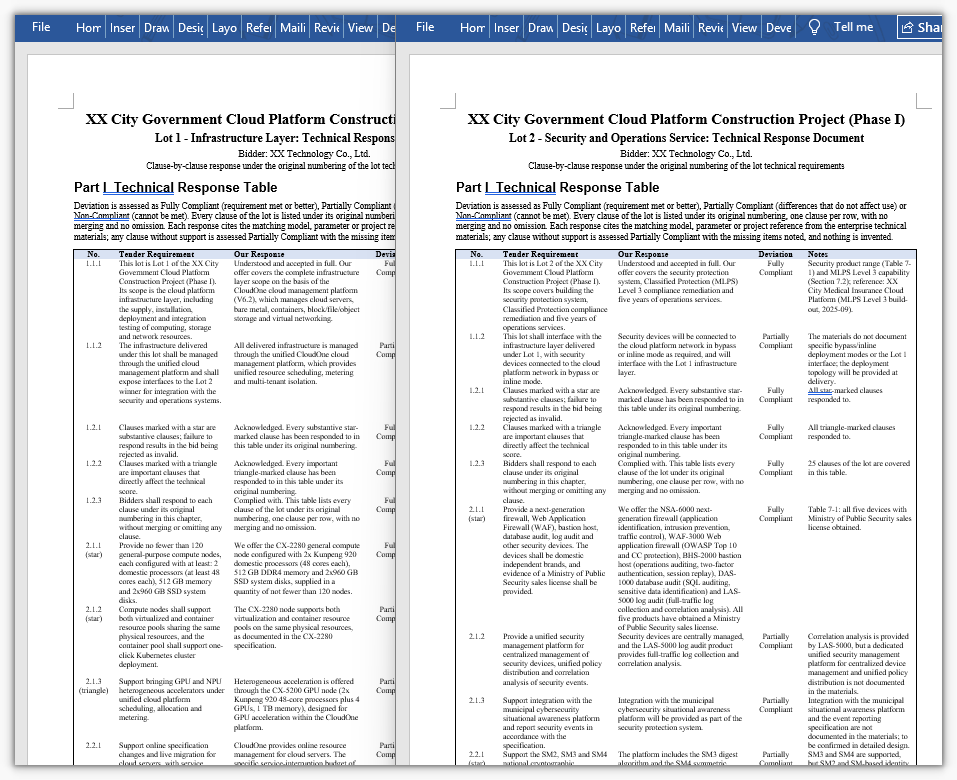
One call produces one independent response document per lot, named after the lot so that each can be submitted separately. Because all lots share the same deviation criteria and the same technical materials, the response standard stays consistent across lots — the same capability is not assessed "Fully Compliant" in one lot and "Partially Compliant" in another.
Common Questions
Response clauses are missing and the count does not match the tender document
Cause: the technical requirements in a tender document are often laid out as multi-level numbering, cross-page tables or even images, and the AI may merge adjacent clauses when splitting, or miss the entries that continue on the following page.
Solution: state in the instruction that each clause must be extracted individually and never merged or summarized, and require that the number of response clauses match the technical requirements in the tender document. For projects with many clauses, first have the AI output a clause list on its own (number + original text), check the count manually, and only then generate the responses — a two-step flow of "split first, respond second".
Responses are generic and do not reflect the company's actual capability
Cause: only the tender document was attached and no enterprise technical materials, so the AI can only write generic wording.
Solution: attach product manuals, test reports, qualification certificates and references for similar projects, and require in the instruction that "clauses with matching evidence must cite the specific product model, technical parameters or project reference".
Invented parameters, certificates or project references appear
Cause: when tender requirements and enterprise materials diverge, the AI tends to write extra content to fill the response table.
Solution: state in the instruction that "inventing parameters, certificates or project references to reach full compliance is forbidden; anything that cannot be confirmed is left blank and marked for manual confirmation", and write "any clause with no corresponding content in the materials is assessed as Partially Compliant" in as a hard rule.
Every deviation is assessed as "Fully Compliant"
Cause: no deviation criteria were given, so the AI sets its own standard, which usually leans lenient.
Solution: write the assessment standard into the instruction, for example "tender requirements fully met or better → Fully Compliant; differences that do not affect use → Partially Compliant; cannot be met → Non-Compliant". For stricter assessment, add "Fully Compliant may be assessed only when the enterprise materials provide explicit parameters or project references".
The response table layout breaks down and long clauses run together
Cause: a response table has many columns and long cell contents, so the AI may reorder columns or produce abnormal row heights when laying it out.
Solution: fix the column names and column order in the instruction (No. | Tender Requirement | Our Response | Deviation | Notes), and add layout requirements as needed (table centered, header row bold, body 12 pt, 1.5 line spacing); for very long clauses, require that "the Tender Requirement column keeps the original sentence, truncated at 80 characters with a trailing ellipsis".
Get the SpireToken Key
- Contact [email protected] or visit https://www.e-iceblue.com/TemLicense.html for a trial or commercial API key
Configure it in code:
AIOptions options = new AIOptions();
options.SpireToken = key;