Edit PDF Using Python: A Practical Guide to PDF Modification
PDFs are widely used in reports, invoices, and digital forms due to their consistent formatting across platforms. However, their fixed layout makes editing difficult without specialized tools. For developers looking to edit PDF using Python, Spire.PDF for Python provides a comprehensive and easy-to-use solution. This Python PDF editor enables you to modify PDF files programmatically—changing text, replacing images, adding annotations, handling forms, and securing files—without relying on Adobe Acrobat or any external software.
In this article, we will explore how to use Spire.PDF for Python to programmatically edit PDFs in Python applications.
- Why Use Python and Spire.PDF to Edit PDF Documents?
- Getting Started with Spire.PDF for Python
- How to Edit an Existing PDF Using Spire.PDF for Python
- Frequently Asked Questions
Why Use Python and Spire.PDF to Edit PDF Documents?
Python is a highly versatile programming language that provides an excellent platform for automating and managing PDF documents. When it comes to edit PDF Python tasks, Spire.PDF for Python stands out as a comprehensive and easy-to-use solution for all your PDF manipulation needs.
Benefits of Using Python for PDF Editing
- Automation and Batch Processing: Streamline repetitive PDF editing tasks efficiently.
- Cost-Effective: Reduce manual work, saving time and resources when you Python-edit PDF files.
- Integration: Seamlessly incorporate PDF editing into existing Python-based systems and workflows.
Advantages of Spire.PDF for Python
Spire.PDF for Python is a standalone library that enables developers to create, read, edit, convert, and save PDF files without relying on external software. As a trusted Python PDF editor, it offers powerful features such as:
- Text and Image Editing
- Annotations and Bookmark Management
- Form Field Handling
- Security Settings (Encryption and Permissions)
- Conversion to Word, Excel, HTML, and Images
To learn more about these specific features, visit the Spire.PDF for Python tutorials.
With its intuitive API design, Spire.PDF makes it easier than ever to edit PDF files in Python quickly and effectively, ensuring a smooth development experience.
Getting Started with Spire.PDF for Python
Installation:
To install Spire.PDF for Python, simply run the following pip command:
pip install spire.pdf
Alternatively, you can install Free Spire.PDF for Python, a free version suitable for small projects, by running:
pip install spire.pdf.free
You can also download the library manually from the links.
Basic Setup Example:
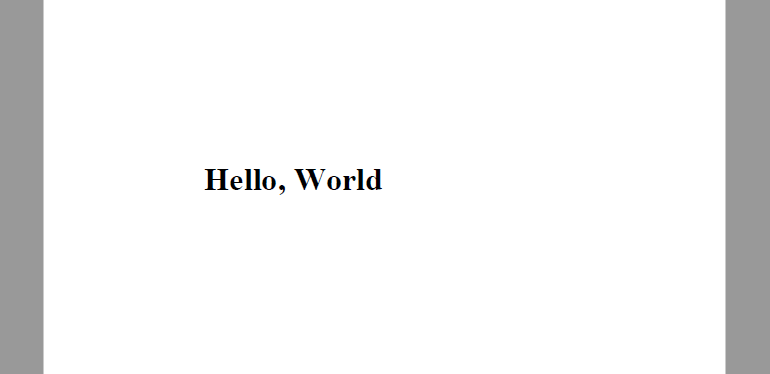
The following example demonstrates how to create a simple PDF using Spire.PDF for Python:
- Python
from spire.pdf import PdfDocument, PdfFont, PdfBrushes, PdfFontFamily, PdfFontStyle

# Create a new PDF document
pdf = PdfDocument()
# Add a new page to the document
page = pdf.Pages.Add()
# Create a font
font = PdfFont(PdfFontFamily.TimesRoman, 28.0, PdfFontStyle.Bold)
# Create a brush
brush = PdfBrushes.get_Black()
# Draw the string using the font and brush
page.Canvas.DrawString("Hello, World", font, brush, 100.0, 100.0)
# Save the document
pdf.SaveToFile("output/NewPDF.pdf")
pdf.Close()
Result: The generated PDF displays the text "Hello, World" using Times Roman Bold.
With Spire.PDF installed, you're now ready to edit PDFs using Python. The sections below explain how to manipulate structure, content, security, and metadata.
How to Edit an Existing PDF Using Spire.PDF for Python
Spire.PDF for Python provides a simple yet powerful way to edit PDF using Python. With its intuitive API, developers can automate a wide range of PDF editing tasks including modifying document structure, page content, security settings, and properties. This section outlines the core categories of editing and their typical use cases.
Edit PDF Pages and Structure with Python
Structure editing lets you manipulate PDF page order, merge files, or insert/delete pages—ideal for document assembly workflows.
- Insert or Delete Pages
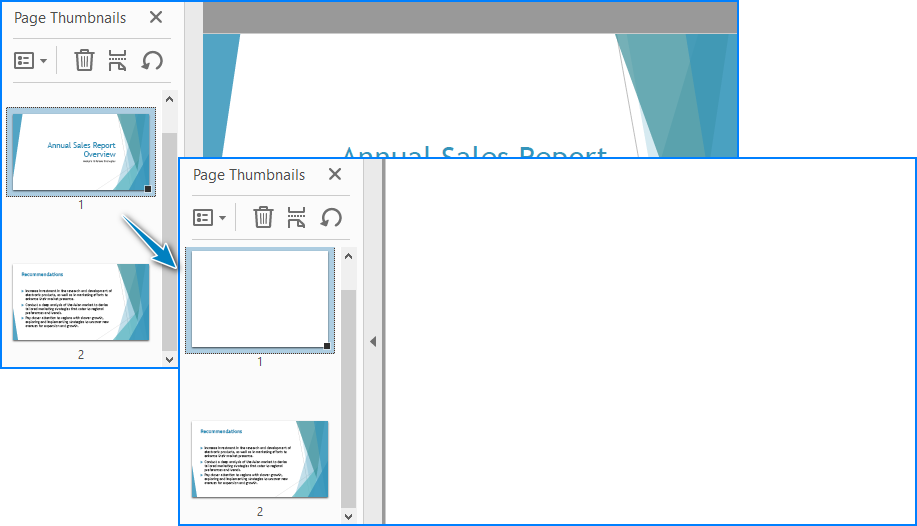
Use the Pages.Insert() and Pages.RemoveAt() methods of the PdfDocument class to insert or delete pages at specific positions.
Code Example
- Python
from spire.pdf import PdfDocument, PdfPageSize, PdfMargins, PdfPageRotateAngle

# Load a PDF document
pdf = PdfDocument()
pdf.LoadFromFile("Sample.pdf")

# Insert and delete pages
# Insert at beginning
pdf.Pages.Insert(0, PdfPageSize.A4(), PdfMargins(50.0, 60.0), PdfPageRotateAngle.RotateAngle90)
# Delete second page
pdf.Pages.RemoveAt(1)

# Save the document
pdf.SaveToFile("output/InsertDeletePage.pdf")
pdf.Close()
Result:
- Merge Two PDF Files
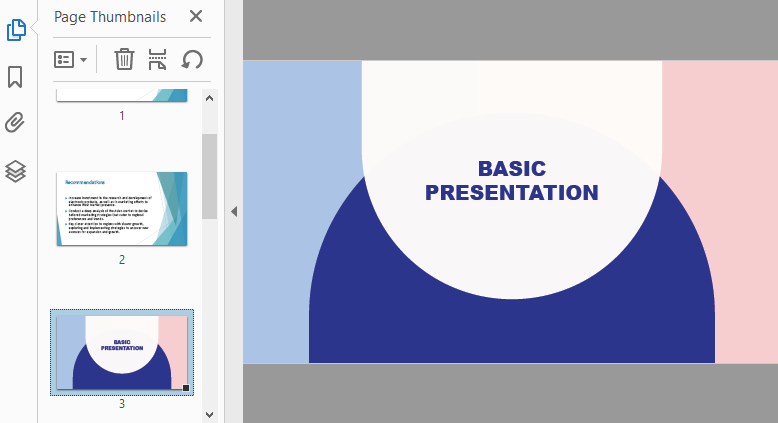
The AppendPage() method allows you to combine PDFs by inserting pages from one document into another.
Code Example
- Python
import os
from spire.pdf import PdfDocument

# Specify the PDF file path
pdfPath = "PDFs/"
# Read the PDF file names from the path and add them to a list
files = [pdfPath + file for file in os.listdir(pdfPath) if file.endswith(".pdf")]

# Load the first PDF file
pdf = PdfDocument()
pdf.LoadFromFile(files[0])
# Iterate through the other PDF files
for i in range(1, len(files)):
    # Load the current PDF file
    pdf2 = PdfDocument()
    pdf2.LoadFromFile(files[i])
    # Append the pages from the current PDF file to the first PDF file
    pdf.AppendPage(pdf2)

# Save the merged PDF file
pdf.SaveToFile("output/MergePDFs.pdf")
pdf.Close()
Result:
You may also like: Splitting PDF Files with Python Code
Edit PDF Content with Python
As a Python PDF editor, Spire.PDF supports a variety of content-level operations, including modifying text, images, annotations, and interactive forms.
- Replace Text in a PDF
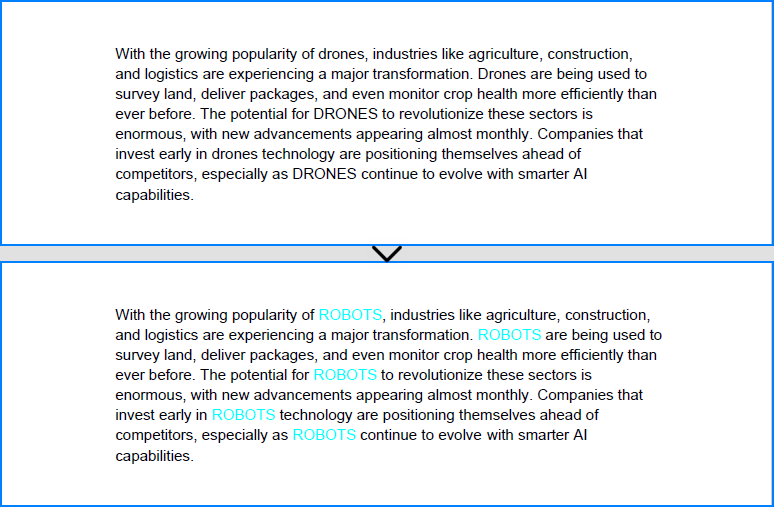
The PdfTextReplacer class can be used to find and replace text from a page. Note that precise replacement may require case and layout-aware handling.
Code Example
- Python
from spire.pdf import PdfDocument, PdfTextReplacer, ReplaceActionType, Color

# Load the PDF file
pdf = PdfDocument()
pdf.LoadFromFile("Sample.pdf")

# Iterate through the pages
for i in range(pdf.Pages.Count):
    page = pdf.Pages.get_Item(i)
    # Create a PdfTextReplacer object
    replacer = PdfTextReplacer(page)
    # Set the replacement options
    replacer.Options.ReplaceType = ReplaceActionType.IgnoreCase
    # Replace the text
    replacer.ReplaceAllText("drones", "ROBOTS", Color.get_Aqua()) # Setting the color is optional

# Save the merged PDF file
pdf.SaveToFile("output/ReplaceText.pdf")
pdf.Close()
Result:
- Replace Images in a PDF
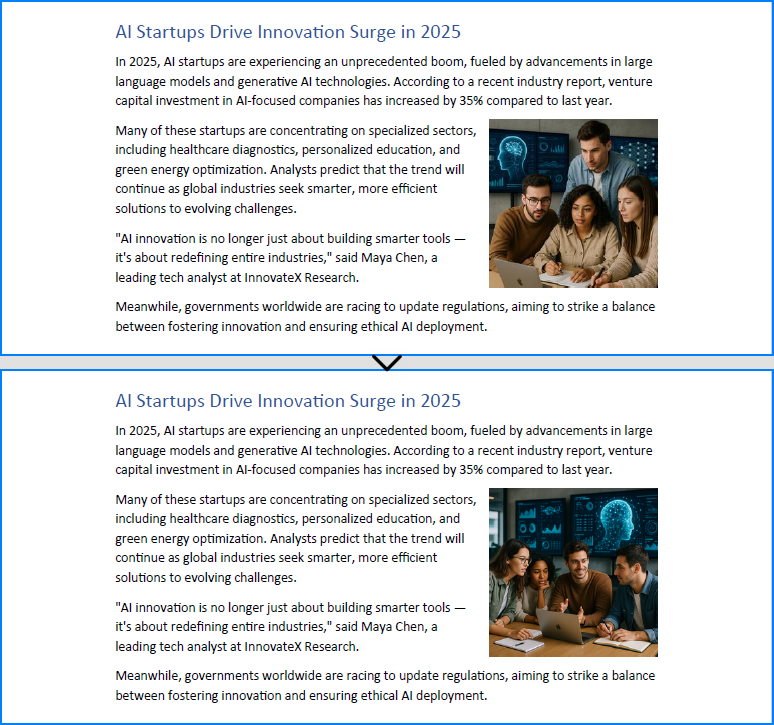
Spire.PDF for Python provides the PdfImageHelper class to help you replace images in a PDF file with ease. By retrieving image information from a specific page, you can use the ReplaceImage() method to directly substitute the original image with a new one.
Code Example
- Python
from spire.pdf import PdfDocument, PdfImageHelper, PdfImage

# Load the PDF file
pdf = PdfDocument()
pdf.LoadFromFile("Sample.pdf")

# Get a page
page = pdf.Pages.get_Item(0)

# Create a PdfImageHelper instance
imageHelper = PdfImageHelper()
# Get the image info of the first image on the page
imageInfo = imageHelper.GetImagesInfo(page)[0]
# Load a new image
newImage = PdfImage.FromFile("Image.png")
# Replace the image
imageHelper.ReplaceImage(imageInfo, newImage)

# Save the PDF file
pdf.SaveToFile("output/ReplaceImage.pdf")
pdf.Close()
Result:
- Add Comments or Notes
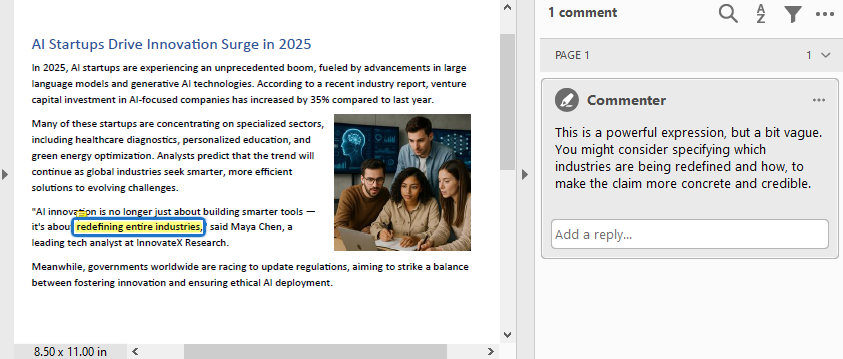
To add comments or notes with Python, use the PdfTextMarkupAnnotation class and add it to the page’s AnnotationsWidget collection.
Code Example
- Python
from spire.pdf import PdfDocument, PdfTextFinder, PdfTextMarkupAnnotation, PdfRGBColor, Color

# Load the PDF file
pdf = PdfDocument()
pdf.LoadFromFile("Sample.pdf")

# Get a page
page = pdf.Pages.get_Item(0)

#Create a PdfTextFinder instance and set the options
finder = PdfTextFinder(page)
finder.Options.Parameter.IgnoreCase = False
finder.Options.Parameter.WholeWord = True
# Find the text to comment
text = finder.Find("redefining entire industries")[0]

# Get the bound of the text
bound = text.Bounds[0]

# Add comment
commentText = ("This is a powerful expression, but a bit vague. "
                "You might consider specifying which industries are "
                "being redefined and how, to make the claim more "
                "concrete and credible.")
comment = PdfTextMarkupAnnotation("Commenter", commentText, bound)
comment.TextMarkupColor = PdfRGBColor(Color.get_Yellow())
page.AnnotationsWidget.Add(comment)

# Save the PDF file
pdf.SaveToFile("output/CommentNote.pdf")
pdf.Close()
Result:
- Edit or Read Form Fields
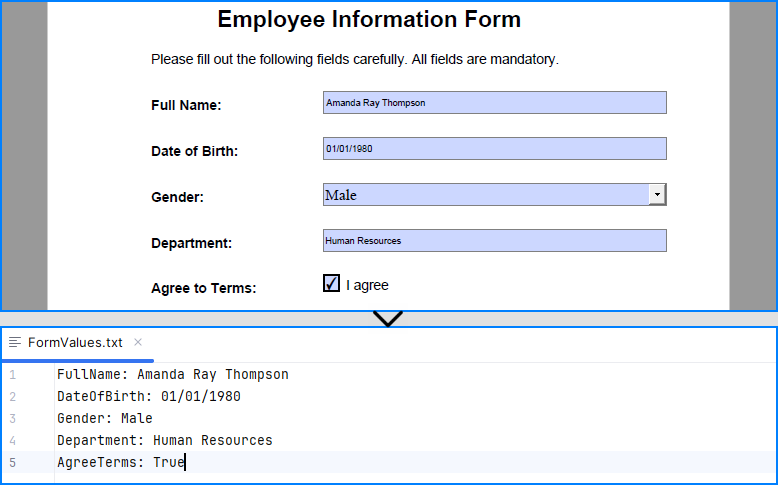
Spire.PDF for Python allows you to programmatically fill out and read form fields in a PDF document. By accessing the FieldsWidget property of a PdfFormWidget object, you can iterate through all interactive form elements, such as text boxes, combo boxes, and checkboxes, and update or extract their values.
Code Example
- Python
from spire.pdf import PdfDocument, PdfFormWidget, PdfComboBoxWidgetFieldWidget, PdfCheckBoxWidgetFieldWidget, PdfTextBoxFieldWidget

# Load the PDF file
pdf = PdfDocument()
pdf.LoadFromFile("EmployeeInformationForm.pdf")

forms = pdf.Form
formWidgets = PdfFormWidget(forms).FieldsWidget

# Fill the forms
for i in range(formWidgets.Count):
    formField = formWidgets.get_Item(i)
    if formField.Name == "FullName":
        textBox = PdfTextBoxFieldWidget(formField)
        textBox.Text = "Amanda Ray Thompson"
    elif formField.Name == "DateOfBirth":
        textBox = PdfTextBoxFieldWidget(formField)
        textBox.Text = "01/01/1980"
    elif formField.Name == "Gender":
        comboBox = PdfComboBoxWidgetFieldWidget(formField)
        comboBox.SelectedIndex  = [ 1 ]
    elif formField.Name == "Department":
        formField.Value = "Human Resources"
    elif formField.Name == "AgreeTerms":
        checkBox = PdfCheckBoxWidgetFieldWidget(formField)
        checkBox.Checked = True

# Read the forms
formValues = []

for i in range(formWidgets.Count):
    formField = formWidgets.get_Item(i)
    if isinstance(formField, PdfTextBoxFieldWidget):
        formValues.append(formField.Name + ": " + formField.Text)
    elif isinstance(formField, PdfComboBoxWidgetFieldWidget):
        formValues.append(formField.Name + ": " + formField.SelectedValue)
    elif isinstance(formField, PdfCheckBoxWidgetFieldWidget):
        formValues.append(formField.Name + ": " + str(formField.Checked))

# Write the form values to a file
with open("output/FormValues.txt", "w") as file:
    file.write("\n".join(formValues))

# Save the PDF file
pdf.SaveToFile("output/FilledForm.pdf")
pdf.Close()
Result:
Explore more: How to Insert Page Numbers to PDF Using Python
Manage PDF Security with Python
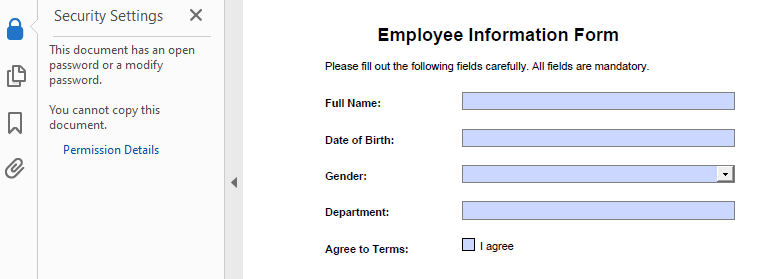
PDF security editing is essential when dealing with sensitive documents. Spire.PDF supports encryption, password protection, digital signature handling, and permission settings.
- Add a Password and Set Permissions
The Encrypt() method lets you secure a PDF with user/owner passwords and define allowed actions like printing or copying.
Code Example
- Python
from spire.pdf import PdfDocument, PdfEncryptionAlgorithm, PdfDocumentPrivilege, PdfPasswordSecurityPolicy

# Load the PDF file
pdf = PdfDocument()
pdf.LoadFromFile("EmployeeInformationForm.pdf")

# Create a PdfSecurityPolicy object and set the passwords and encryption algorithm
securityPolicy = PdfPasswordSecurityPolicy("userPSD", "ownerPSD")
securityPolicy.EncryptionAlgorithm = PdfEncryptionAlgorithm.AES_128

# Set the document privileges
pdfPrivileges = PdfDocumentPrivilege.ForbidAll()
pdfPrivileges.AllowPrint = True
pdfPrivileges.AllowFillFormFields  = True
# Apply the document privileges
securityPolicy.DocumentPrivilege = pdfPrivileges

# Encrypt the PDF with the security policy
pdf.Encrypt(securityPolicy)

# Save the PDF file
pdf.SaveToFile("output/EncryptedForm.pdf")
pdf.Close()
Result
- Remove the Password from a PDF
To open a protected file, provide the user password when calling LoadFromFile(), use Decrypt() to decrypt the document, and save it again unprotected.
Code Example
- Python
from spire.pdf import PdfDocument

# Load the encrypted PDF file with the owner password
pdf = PdfDocument()
pdf.LoadFromFile("output/EncryptedForm.pdf", "ownerPSD")

# Decrypt the PDF file
pdf.Decrypt()

# Save the PDF file
pdf.SaveToFile("output/DecryptedForm.pdf")
pdf.Close()
Recommended for you: Use Python to Add and Remove Digital Signature in PDF
Edit PDF Properties with Python
Use Spire.PDF to read and edit PDF metadata and viewer preferences—key features for document presentation and organization.
- Update Document Metadata
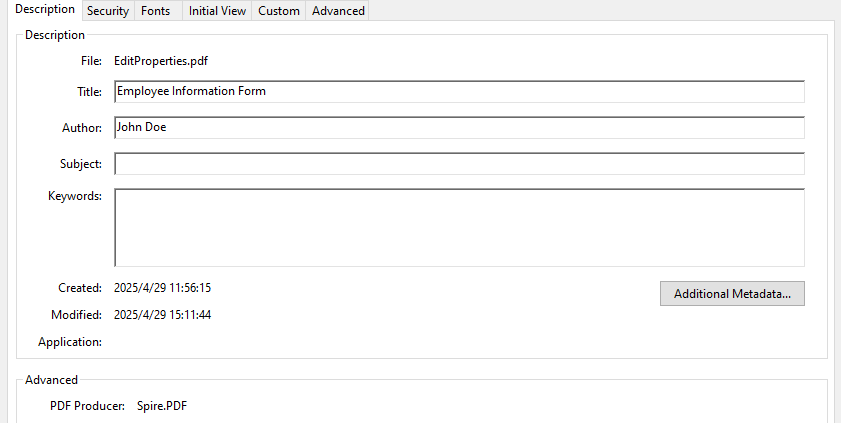
Update metadata such as title, author, or subject via the DocumentInformation property of the PDF document.
Code Example
- Python
from spire.pdf import PdfDocument

# Load the PDF file
pdf = PdfDocument()
pdf.LoadFromFile("EmployeeInformationForm.pdf")

# Set document metadata
pdf.DocumentInformation.Author = "John Doe"
pdf.DocumentInformation.Title = "Employee Information Form"
pdf.DocumentInformation.Producer  = "Spire.PDF"

# Save the PDF file
pdf.SaveToFile("output/EditProperties.pdf")
pdf.Close()
Result:
- Set View Preferences
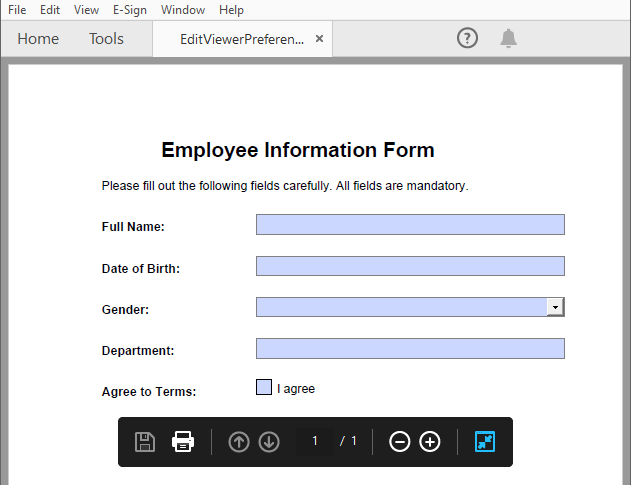
The ViewerPreferences property allows you to customize the viewing mode of a PDF (e.g., two-column layout).
Code Example
- Python
from spire.pdf import PdfDocument, PdfPageLayout, PrintScalingMode

# Load the PDF file
pdf = PdfDocument()
pdf.LoadFromFile("EmployeeInformationForm.pdf")

# Set the viewer preferences
pdf.ViewerPreferences.DisplayTitle = True
pdf.ViewerPreferences.HideToolbar = True
pdf.ViewerPreferences.HideWindowUI = True
pdf.ViewerPreferences.FitWindow = False
pdf.ViewerPreferences.HideMenubar = True
pdf.ViewerPreferences.PrintScaling = PrintScalingMode.AppDefault
pdf.ViewerPreferences.PageLayout = PdfPageLayout.OneColumn

# Save the PDF file
pdf.SaveToFile("output/EditViewerPreference.pdf")
pdf.Close()
Result:
Similar topic: Change PDF Version Easily with Python Code
Conclusion
Editing PDFs using Python is both practical and efficient with Spire.PDF for Python. Whether you're building automation tools, editing digital forms, or securing sensitive reports, Spire.PDF equips you with a comprehensive suite of editing features—all accessible via clean and simple Python code.
With capabilities that span content editing, form interaction, document structuring, and security control, this Python PDF editor is a go-to solution for developers and organizations aiming to streamline their PDF workflows.
Frequently Asked Questions
Q: Can I edit a PDF using Python?
A: Yes, Python offers powerful libraries like Spire.PDF for Python that enable you to edit text, images, forms, annotations, and even security settings in a PDF file.
Q: How to edit a PDF using coding?
A: By using libraries such as Spire.PDF for Python, you can load an existing PDF, modify its content or structure programmatically, and save the changes with just a few lines of code.
Q: What is the Python library for PDF editor?
A: Spire.PDF for Python is a popular choice. It offers comprehensive functionalities for creating, reading, editing, converting, and securing PDF documents without the need for additional software.
Q: Can I modify a PDF for free?
A: Yes, you can use the free edition of Spire.PDF for Python to edit PDF files, although it comes with some limitations, such as processing up to 10 pages per document. Additionally, you can apply for a 30-day temporary license that removes all limitations and watermarks for full functionality testing.
Spire.PDF 11.4.10 supports printing using .NET Standard DLL
We're pleased to announce the release of Spire.PDF 11.4.10. This version supports printing using .NET Standard DLL and retrieving PdfHideAction in buttons. Moreover, some known issues that occurred when converting PDF to images and saving files have also been successfully fixed. More details are listed below.
Here is a list of changes made in this release
| Category | ID | Description |
| New feature | SPIREPDF-7372 | Supports retrieving PdfHideAction in buttons.
//Initialize an instance of the PdfDocument instance
PdfDocument doc = new PdfDocument();

//Load a PDF document
doc.LoadFromFile(inputFile);

//Initialize an instance of the StringBuilder class
StringBuilder sb = new StringBuilder();

//Get the form from the document
PdfFormWidget formWidget = doc.Form as PdfFormWidget;

//Iterate through all fields in the form
for (int i = 0; i < formWidget.FieldsWidget.List.Count; i++)
{

    PdfField field = formWidget.FieldsWidget.List[i] as PdfField;

    //Get the ButtonField
    if (field is PdfButtonWidgetFieldWidget)
    {
        PdfButtonWidgetFieldWidget buttonField = field as PdfButtonWidgetFieldWidget;
        // Get the field name
        string filename = buttonField.Name;

        // Get the action
        PdfAction action = buttonField.Actions.MouseDown;
        if (buttonField.Actions.MouseDown != null && buttonField.Actions.MouseDown is PdfHideAction)
        {
            var btnAction = (PdfHideAction)buttonField.Actions.MouseDown;
            sb.AppendLine(filename + "-MouseDown-Hide-" + btnAction.IsHide.ToString());
            sb.AppendLine(filename + "-MouseDown-fname-" + btnAction.FieldName[0].ToString());
        }
    }
}
File.WriteAllText(outputFile, sb.ToString());
doc.Dispose();
|
| New feature | SPIREPDF-7376 SPIREPDF-7391 SPIREPDF-7467 | Supports printing on Windows and Linux systems using .NET Standard DLL.
PdfDocument doc = new PdfDocument();
    doc.LoadFromFile(pdffile);
    doc.PrintSettings.SelectPageRange(1, 5);
    if(doc.PrintSettings.CanDuplex)
    {
        doc.PrintSettings.Duplex = PdfDuplex.Vertical;
    }
   doc.Print();
|
| Bug | SPIREPDF-7361 | Fixes the issue that adding PdfTextMarkupAnnotation produced incorrect effects. |
| Bug | SPIREPDF-7380 | Fixes the issue where the text was garbled when converting PDF to images. |
| Bug | SPIREPDF-7388 | Fixes the issue where the application threw the “NullReferenceException” when accessing PdfDocumentLinkAnnotationWidget.Destination. |
| Bug | SPIREPDF-7414 | Fixes the issue where the text was truncated when entering multi-line content into PdfTextBoxField. |
| Bug | SPIREPDF-7420 | Fixes the issue where the application threw the “PdfDocumentException” when using the PdfDocument.IsPasswordProtected() method. |
| Bug | SPIREPDF-7424 | Fixes the issue where the application threw the “ArgumentOutOfRangeException” when converting PDF to images. |
| Bug | SPIREPDF-7426 | Fixes the issue that the/DA structure was incorrect in TextBox fields. |
| Bug | SPIREPDF-7429 | Fixes the issue where the application threw the "Empty convert-string" error when saving PDF documents. |
| Bug | SPIREPDF-7431 | Fixes the issue where the result was incorrect when setting FieldsWidget.BorderColor = PdfRGBColor.Empty. |
Spire.Doc for Python 13.4.6 supports matching and finding all keywords within paragraphs
We are excited to announce the release of Spire.Doc for Python 13.4.6. The latest version supports matching and finding all keywords within paragraphs. Besides, some known bugs are fixed in this update, such as the issue that the text was garbled when converting Word to TXT. More details are listed below.
Here is a list of changes made in this release
| Category | ID | Description |
| New feature | SPIREDOC-10348 SPIREDOC-11127 |
Supports matching and finding all keywords within paragraphs.
#Create word document
document = Document()

#Load the document from disk.
document.LoadFromFile(inputFile)

#Insert the paragraphs of document
for i in range(document.Sections.Count):
    section = document.Sections.get_Item(i)
    for j in range(section.Paragraphs.Count):
        paragraph = section.Paragraphs.get_Item(j)
        textSelections = paragraph.FindAllString("The", False, True)
        for selection in textSelections:
            #highlight
            selection.GetAsOneRange().CharacterFormat.HighlightColor = Color.get_Yellow()

#Save doc file.
document.SaveToFile(outputFile, FileFormat.Docx)
|
| New feature | SPIREDOC-10659 | Supports creating charts in Word.
def AppendCharts(section, chartType, width, heigh):
section.AddParagraph().AppendText("{0:s} chart.".format(chartType))
newPara = section.AddParagraph()
# Support adding the BarChart/LineChart/ColumnChart/Surface3DChart/BubbleChart/PieChart/ScatterChart type
shape = newPara.AppendChart(chartType, float(width), float(heigh))
chart = shape.Chart
chart.Series.Clear()
chart.Series.Add("E-iceblue Test Series 1", ["Word", "PDF", "Excel", "GoogleDocs", "Office"], [
                 float(1900000), float(850000), float(2100000), float(600000), float(1500000)])
chart.Series.Add("E-iceblue Test Series 2", ["Word", "PDF", "Excel", "GoogleDocs", "Office"], [
                 float(900000), float(50000), float(1100000), float(400000), float(2500000)])
chart.Series.Add("E-iceblue Test Series 3", ["Word", "PDF", "Excel", "GoogleDocs", "Office"], [
                 float(500000), float(820000), float(1500000), float(400000), float(100000)])

#Create word document
document = Document()

#Add section
section = document.AddSection()

AppendCharts(section, ChartType.Bar, 500, 300)
#Save
document.SaveToFile("AppendCharts.docx", FileFormat.Docx)
|
| New feature | SPIREDOC-10963 | Supports obtaining the line index position where the found content is located.
document = Document()
document.LoadFromFile(inputFile)
textSelections = document.FindAllString("Ceshi", True, True)
sb = []
ranges = []
for selection in textSelections:
  tr = selection.GetAsOneRange()
  ranges.append(tr)
   layoutDoc = FixedLayoutDocument(document)
   for tr in ranges:
    spans = layoutDoc.GetLayoutEntitiesOfNode(tr)
    for i in range(spans.Count):
      tempSpan = spans[i]
      fs = FixedLayoutSpan(tempSpan)
         tempfl = fs.Parent
      line = FixedLayoutLine(tempfl)
         if line.Parent.Type == LayoutElementType.Column:
        lines = line.Parent.Lines
        index = lines.IndexOf(line)
        # print(index)
        sb.append("position:" + str(index))

File.AppendAllText(outputFile, sb)
|
| New feature | SPIREDOC-11001 | Supports enabling and disabling revision tracking mode.
document = Document()
#Load the file from disk.
document.LoadFromFile(inputFile)
document.TrackChanges = True
document.StartTrackRevisions("user")
range = document.LastParagraph.AppendText("Revise4")
range.InsertRevision.Author = "test01"
document.LastParagraph.Text = "remove"
range.DeleteRevision.Author = "test01"
document.StopTrackRevisions()
document.SaveToFile(outputFile)
|
| New feature | SPIREDOC-11015 | Supports setting "Document.LayoutOptions.UseHarfBuzzTextShaper" when converting Word to PDF.
Document doc = new Document();
doc.LoadFromFile("input.docx");
doc.LayoutOptions.UseHarfBuzzTextShaper = true;
doc.SaveToFile("result.pdf", Spire.Doc.FileFormat.PDF);
|
| New feature | SPIREDOC-11114 | Supports detecting whether a document is encrypted.
value1 = Document.IsEncrypted(inputFile_1) |
| New feature | SPIREDOC-11157 | Supports converting OfficeMath to MathMLCode.
doc = Document()
section=doc.AddSection()
officeMath = OfficeMath(doc)
officeMath.FromLatexMathCode("x^{2}+\\sqrt{{x^{2}+1}}+1")
officeMath.ToMathMLCode()
|
| Bug | SPIREDOC-10502 | Fixes the issue where adding and extracting formulas would throw an "Arg_InvalidCastException" exception. |
| Bug | SPIREDOC-10646 | Fixes the issue that the text was garbled when converting Word to TXT. |
| Bug | SPIREDOC-10860 | Fixes the issue where using FixedLayoutRow.Table would throw an "Arg_NullReferenceException" exception. |
| Bug | SPIREDOC-10886 | Fixes the issue that the return value of Document.IsContainMacro was incorrect. |
| Bug | SPIREDOC-10924 | Fixes the issue that "Cannot remove because there is no parent" exception occurred when converting HTML to Word. |
| Bug | SPIREDOC-10996 | Fixes the issue that "System.ArgumentNullException" occurred when converting Word to HTML. |
| Bug | SPIREDOC-11014 | Fixes the issue where PreserveFormFields=True did not take effect. |
| Bug | SPIREDOC-11077 SPIREDOC-11101 | Fixes the issue that list numbering was incorrect when converting Word to PDF. |
| Bug | SPIREDOC-11166 | Fixes the issue that the "'Document' is not defined" error occurred when using Span.ParentNode. |
| Bug | SPIREDOC-11168 | Fixes the issue that formulas were blurry when converting Word to HTML. |
Spire.PDF for Android via Java 10.4.0 adds a new feature
We are delighted to announce the release of Spire.PDF for Android via Java 10.4.0. This version supports setting 'PreserveAllowedMetadata=true' when using PdfStandardsConverter. More details are listed below.
Here is a list of changes made in this release
| Category | ID | Description |
| New feature | SPIREPDF-6921 | Supports setting 'PreserveAllowedMetadata=true' when using PdfStandardsConverter.
PdfStandardsConverter converter = new PdfStandardsConverter(stream); converter.Options.PreserveAllowedMetadata = true; |
Spire.XLS 15.4.4 adds support for several formulas
We're pleased to announce the release of Spire.XLS 15.4.4. This version adds support for several new formulas, and also supports auto-fitting row height in merged cells spanning multiple columns in a single row. Besides, some issues that occurred when converting Excel to PDF and saving files have been successfully fixed. More details are shown below.
Here is a list of changes made in this release
| Category | ID | Description |
| New feature | SPIREXLS-5697 | Supports auto-fitting row height in merged cells spanning multiple columns in a single row.
Workbook workbook = new Workbook(); workbook.LoadFromFile(@"in.xlsx"); Worksheet sheet= workbook.Worksheets[0]; AutoFitterOptions options = new AutoFitterOptions(); options.AutoFitMergedCells = true; //the first parameter is the merged row sheet.AutoFitRow(9, 1, sheet.LastColumn, options); workbook.SaveToFile(@"out.xlsx", Spire.Xls.FileFormat.Version2016); workbook.Dispose(); |
| New feature | SPIREXLS-5746 SPIREXLS-5768 SPIREXLS-5769 SPIREXLS-5774 |
Supports the GAMMALN.PRECISE, LOGNORM.INV, LOGNORM.DIST, and GAUSS formulas.
sheet.Range["C2"].Formula = "=GAUSS(A1)"; sheet.Range["C3"].Formula = "=LOGNORM.DIST(A2, A3, A4, A5)"; sheet.Range["C4"].Formula = "=GAMMALN.PRECISE(1.5)"; sheet.Range["C5"].Formula = "=LOGNORM.INV(0.5, 0, 1)"; |
| Bug | SPIREXLS-5555 | Fixes the issue where data was incomplete when converting Excel to PDF with the SheetFitToPage=true property. |
| Bug | SPIREXLS-5724 | Fixes the inconsistency issue when converting Excel to PDF. |
| Bug | SPIREXLS-5725 | Fixes the issue where the text was displayed incorrectly when converting Excel to PDF. |
| Bug | SPIREXLS-5767 | Fixes the issue that the XML data for ColumnWidth did not comply with OpenXML standards. |
| Bug | SPIREXLS-5775 | Fixes the issue that it was where failed to update the associated sheets when modifying the row count in a sheet. |
| Bug | SPIREXLS-5777 | Fixes the issue where shapes were incorrect in the saved Excel file. |
| Bug | SPIREXLS-5778 | Fixed the issue that the IFERROR formula returned incorrect values. |
Spire.Office for Java 10.4.0 is released
We are excited to announce the release of Spire.Office for Java 10.4.0. In this version, Spire.Doc for Java enhances the conversions from Word to HTML/PDF; Spire.XLS for Java supports creating a slicer using table data; Spire.Presentation for Java enhances the conversion from PowerPoint to images; Spire.PDF for Java supports signing with "digitalsignatures.PdfCertificate" using byte[] certificate data. Besides, a lot of known issues are fixed successfully in this version. More details are listed below.
Here is a list of changes made in this release
Spire.Doc for Java
| New feature | SPIREDOC-11117 | Optimizes the time-consuming issue of Word to PDF conversion.
|
| Bug | SPIREDOC-11123 | Fixes the issue that the program threw the "AssertionError" exception when converting Word documents to HTML. |
| Bug | SPIREDOC-11139 | Fixes the issue that the program threw an exception when retrieving content of the saved documents. |
| Bug | SPIREDOC-11144 | Fixes the issue that the program threw the "NullPointerException" exception when converting Word documents to HTML. |
| Bug | SPIREDOC-11153 | Fixes the issue that the result was incorrect when obtaining OLE NativeDataBytes. |
| Bug | SPIREDOC-11162 | Fixes the issue that the layout was incorrect when converting Word to PDF. |
Spire.XLS for Java
| Category | ID | Description |
| New feature | - | Supports creating a slicer using table data.
Workbook wb = new Workbook();
//Get the first worksheet of workbook
Worksheet worksheet = wb.getWorksheets().get(0);
worksheet.getRange().get("A1").setValue("fruit");
worksheet.getRange().get("A2").setValue("grape");
worksheet.getRange().get("A3").setValue("blueberry");
worksheet.getRange().get("A4").setValue("kiwi");
worksheet.getRange().get("A5").setValue("cherry");
worksheet.getRange().get("A6").setValue("grape");
worksheet.getRange().get("A7").setValue("blueberry");
worksheet.getRange().get("A8").setValue("kiwi");
worksheet.getRange().get("A9").setValue("cherry");

worksheet.getRange().get("B1").setValue("year");
worksheet.getRange().get("B2").setValue2(2020);
worksheet.getRange().get("B3").setValue2(2020);
worksheet.getRange().get("B4").setValue2(2020);
worksheet.getRange().get("B5").setValue2(2020);
worksheet.getRange().get("B6").setValue2(2021);
worksheet.getRange().get("B7").setValue2(2021);
worksheet.getRange().get("B8").setValue2(2021);
worksheet.getRange().get("B9").setValue2(2021);

worksheet.getRange().get("C1").setValue("amount");
worksheet.getRange().get("C2").setValue2(50);
worksheet.getRange().get("C3").setValue2(60);
worksheet.getRange().get("C4").setValue2(70);
worksheet.getRange().get("C5").setValue2(80);
worksheet.getRange().get("C6").setValue2(90);
worksheet.getRange().get("C7").setValue2(100);
worksheet.getRange().get("C8").setValue2(110);
worksheet.getRange().get("C9").setValue2(120);

//Get slicer collection
XlsSlicerCollection slicers = worksheet.getSlicers();

//Create a super table with the data from the specific cell range.
IListObject table = worksheet.getListObjects().create("Super Table", worksheet.getRange().get("A1:C9"));

int count = 3;
int index = 0;
for (Object styletype : SlicerStyleType.values())
{
	SlicerStyleType type = (SlicerStyleType)styletype;
	count += 5;
	//Add a Slicer through pivot table data : here invoke Add(IListObject, string, int) api.
	String range = "E" + count;
	index = slicers.add(table, range.toString(), 0);

	//Style setting
	XlsSlicer xlsSlicer = slicers.get(index);
	xlsSlicer.setName("slicers_" + count);
	xlsSlicer.setStyleType(type);

}

//Save to file
wb.saveToFile(outputFile_xlsx, ExcelVersion.Version2013);
|
| New feature | - | Supports creating a slicer using pivot table data.
Workbook wb = new Workbook();
//Get the first worksheet of workbook
Worksheet worksheet = wb.getWorksheets().get(0);
worksheet.getRange().get("A1").setValue("fruit");
worksheet.getRange().get("A2").setValue("grape");
worksheet.getRange().get("A3").setValue("blueberry");
worksheet.getRange().get("A4").setValue("kiwi");
worksheet.getRange().get("A5").setValue("cherry");
worksheet.getRange().get("A6").setValue("grape");
worksheet.getRange().get("A7").setValue("blueberry");
worksheet.getRange().get("A8").setValue("kiwi");
worksheet.getRange().get("A9").setValue("cherry");

worksheet.getRange().get("B1").setValue("year");
worksheet.getRange().get("B2").setValue2(2020);
worksheet.getRange().get("B3").setValue2(2020);
worksheet.getRange().get("B4").setValue2(2020);
worksheet.getRange().get("B5").setValue2(2020);
worksheet.getRange().get("B6").setValue2(2021);
worksheet.getRange().get("B7").setValue2(2021);
worksheet.getRange().get("B8").setValue2(2021);
worksheet.getRange().get("B9").setValue2(2021);

worksheet.getRange().get("C1").setValue("amount");
worksheet.getRange().get("C2").setValue2(50);
worksheet.getRange().get("C3").setValue2(60);
worksheet.getRange().get("C4").setValue2(70);
worksheet.getRange().get("C5").setValue2(80);
worksheet.getRange().get("C6").setValue2(90);
worksheet.getRange().get("C7").setValue2(100);
worksheet.getRange().get("C8").setValue2(110);
worksheet.getRange().get("C9").setValue2(120);

// Get pivot table collection
PivotTablesCollection pivotTables = worksheet.getPivotTables();

//Add a PivotTable to the worksheet
CellRange dataRange = worksheet.getRange().get("A1:C9");
PivotCache cache = wb.getPivotCaches().add(dataRange);

//Cell to put the pivot table
PivotTable pt = worksheet.getPivotTables().add("TestPivotTable", worksheet.getRange().get("A12"), cache);

//Drag the fields to the row area.
IPivotField pf = pt.getPivotFields().get("fruit");
pf.setAxis(AxisTypes.Row);
IPivotField pf2 = pt.getPivotFields().get("year");
pf2.setAxis(AxisTypes.Column);

//Drag the field to the data area.
pt.getDataFields().add(pt.getPivotFields().get("amount"), "SUM of Count", SubtotalTypes.Sum);

//Set PivotTable style
pt.setBuiltInStyle(PivotBuiltInStyles.PivotStyleMedium10);


//Get slicer collection
XlsSlicerCollection slicers = worksheet.getSlicers();

//Add a Slicer through pivot table data: here invoke Add(IPivotTable, string, int) api.
int index = slicers.add(pt, "E12", 0);

XlsSlicer xlsSlicer = slicers.get(index);
xlsSlicer.setName("test_xlsSlicer");
xlsSlicer.setWidth(100);
xlsSlicer.setHeight(120);
xlsSlicer.setStyleType(SlicerStyleType.SlicerStyleLight2);
xlsSlicer.isPositionLocked(true);

//Get SlicerCache object of current slicer
XlsSlicerCache slicerCache = xlsSlicer.getSlicerCache();
slicerCache.setCrossFilterType(SlicerCacheCrossFilterType.ShowItemsWithNoData);

//Style setting
XlsSlicerCacheItemCollection slicerCacheItems = xlsSlicer.getSlicerCache().getSlicerCacheItems();
XlsSlicerCacheItem xlsSlicerCacheItem = slicerCacheItems.get(0);
xlsSlicerCacheItem.isSelected(false);

XlsSlicerCollection slicers_2 = worksheet.getSlicers();

IPivotField r1 = pt.getPivotFields().get("year");
int index_2 = slicers_2.add(pt, "I12", r1);

XlsSlicer xlsSlicer_2 = slicers.get(index_2);
xlsSlicer_2.setRowHeight(40);
xlsSlicer_2.setStyleType(SlicerStyleType.SlicerStyleLight3);
xlsSlicer_2.isPositionLocked(false);

//Get SlicerCache object of current slicer
XlsSlicerCache slicerCache_2 = xlsSlicer_2.getSlicerCache();
slicerCache_2.setCrossFilterType(SlicerCacheCrossFilterType.ShowItemsWithDataAtTop);

//Style setting
XlsSlicerCacheItemCollection slicerCacheItems_2 = xlsSlicer_2.getSlicerCache().getSlicerCacheItems();
XlsSlicerCacheItem xlsSlicerCacheItem_2 =  slicerCacheItems_2.get(1);
xlsSlicerCacheItem_2.isSelected(false);
pt.calculateData();

//Save to file
wb.saveToFile("out.xlsx", ExcelVersion.Version2013);
|
| New feature | - | Supports retrieving slicer information.
Workbook wb = new Workbook();
wb.loadFromFile(inputFile);

// Get slicer collection of first worksheet
Worksheet worksheet = wb.getWorksheets().get(0);

XlsSlicerCollection slicers = worksheet.getSlicers();
StringBuilder builder = new StringBuilder();
builder.append("slicers.Count:" + slicers.getCount()+"\r\n");

XlsSlicer xlsSlicer = slicers.get(1);

builder.append("xlsSlicer.Name:" + xlsSlicer.getName()+"\r\n");
builder.append("xlsSlicer.Caption:" + xlsSlicer.getCaption()+"\r\n");
builder.append("xlsSlicer.NumberOfColumns:" + xlsSlicer.getNumberOfColumns()+"\r\n");
builder.append("xlsSlicer.ColumnWidth:" + xlsSlicer.getColumnWidth()+"\r\n");
builder.append("xlsSlicer.RowHeight:" + xlsSlicer.getRowHeight()+"\r\n");
builder.append("xlsSlicer.ShowCaption:" + xlsSlicer.isShowCaption()+"\r\n");
builder.append("xlsSlicer.PositionLocked:" + xlsSlicer.isPositionLocked()+"\r\n");
builder.append("xlsSlicer.Width:" + xlsSlicer.getWidth()+"\r\n");
builder.append("xlsSlicer.Height:" + xlsSlicer.getHeight()+"\r\n");

//Get SlicerCache object of current slicer
XlsSlicerCache slicerCache = xlsSlicer.getSlicerCache();

builder.append("slicerCache.SourceName:" + slicerCache.getSourceName()+"\r\n");
builder.append("slicerCache.IsTabular:" + slicerCache.isTabular()+"\r\n");
builder.append("slicerCache.Name:" + slicerCache.getName()+"\r\n");

XlsSlicerCacheItemCollection slicerCacheItems = slicerCache.getSlicerCacheItems();
XlsSlicerCacheItem xlsSlicerCacheItem = slicerCacheItems.get(1);


builder.append("xlsSlicerCacheItem.Selected:" + xlsSlicerCacheItem.isSelected() +"\r\n");

FileWriter fw = new FileWriter(outputFile_T);
fw.write(builder.toString());
fw.flush();
fw.close();
wb.dispose();
|
| Bug | SPIREXLS-5569 | Fixes the issue that OLE objects failed to open correctly after converting Excel to XLSB format. |
| Bug | SPIREXLS-5673 | Fixes the issue that alignment was incorrect when converting Excel to PDF. |
| Bug | SPIREXLS-5752 | Optimizes the text rendering effect of grouped shapes when converting Excel to PDF. |
| Bug | SPIREXLS-5757 | Fixes the issue that some formula values were calculated incorrectly when converting Excel to images. |
Spire.Presentation for Java
| New feature | SPIREPPT-2668 | Fixes the issue where the content was incorrect when converting PowerPoint to images.
|
| Bug | SPIREPPT-2669 | Fixes the issue where the text shadow effect was lost when converting PowerPoint to images. |
| Bug | SPIREPPT-2672 | Fixes the issue where the text layout was incorrect when converting PowerPoint to images. |
| Bug | SPIREPPT-2693 | Fixes the issue where the layout was incorrect when opening merged PowerPoint documents in WPS. |
| Bug | SPIREPPT-2731 | Fixes the issue where the charts were incorrect when converting PowerPoint to PDF. |
| Bug | SPIREPPT-2732 | Fixes the issue where the program hung when running the packaged .jar file after setting setCustomFontsFolder while converting a PowerPoint to HTML. |
| Bug | SPIREPPT-2779 | Fixes the issue where the content auto-fit effect was incorrect in merged PowerPoint documents. |
Spire.PDF for Java
| Category | ID | Description |
| New feature | SPIREPDF-7460 | Supports using the byte[] certificate data when signing with "digitalsignatures. PdfCertificate".
PdfDocument pdf = new PdfDocument();
pdf.loadFromFile(inputFile);
FileInputStream instream = new FileInputStream(inputFile_pfx);
byte[] data = FileUtil.getStreamBytes(instream);
PdfCertificate x509 = new PdfCertificate(data, "e-iceblue");
PdfOrdinarySignatureMaker signatureMaker = new PdfOrdinarySignatureMaker(pdf, x509);
signatureMaker.makeSignature("signName");
pdf.saveToFile(outputFile, FileFormat.PDF);
pdf.dispose();
|
| Bug | SPIREPDF-7457 | Fixes the problem that the program threw “NullPointerException” when setting isFlatten(true). |
| Bug | SPIREPDF-7458 | Fixes the issue that some contents were incorrect after converting PDF to PDF/A. |
| Bug | SPIREPDF-7463 | Fixes the issue that the format and font were incorrect after converting PDF to PowerPoint. |
| Bug | SPIREPDF-7462 | Fixes the issue that the data extracted from tables was incorrect. |
Spire.PDF for Java 11.4.2 supports signing with "digitalsignatures.PdfCertificate" using byte[] certificate data
We are excited to announce the release of Spire.PDF for Java 11.4.2. This version supports using the byte[] certificate data when signing with "digitalsignatures. PdfCertificate". It also enhances the conversion from PDF to PDF/A and PowerPoint. Moreover, some known issues are fixed successfully in this version, such as the issue that the data extracted from tables was incorrect. More details are listed below.
Here is a list of changes made in this release
| Category | ID | Description |
| New feature | SPIREPDF-7460 | Supports using the byte[] certificate data when signing with "digitalsignatures. PdfCertificate".
PdfDocument pdf = new PdfDocument();
pdf.loadFromFile(inputFile);
FileInputStream instream = new FileInputStream(inputFile_pfx);
byte[] data = FileUtil.getStreamBytes(instream);
PdfCertificate x509 = new PdfCertificate(data, "e-iceblue");
PdfOrdinarySignatureMaker signatureMaker = new PdfOrdinarySignatureMaker(pdf, x509);
signatureMaker.makeSignature("signName");
pdf.saveToFile(outputFile, FileFormat.PDF);
pdf.dispose();
|
| Bug | SPIREPDF-7457 | Fixes the problem that the program threw “NullPointerException” when setting isFlatten(true). |
| Bug | SPIREPDF-7458 | Fixes the issue that some contents were incorrect after converting PDF to PDF/A. |
| Bug | SPIREPDF-7463 | Fixes the issue that the format and font were incorrect after converting PDF to PowerPoint. |
| Bug | SPIREPDF-7462 | Fixes the issue that the data extracted from tables was incorrect. |
Spire.Presentation 10.4.6 supports inserting formulas in table cells
We're glad to announce the release of Spire.Presentation 10.4.6. This version supports inserting formulas in table cells and reading CustomerData of Shape. In addition, some issues that occurred when converting PPTX to PDF/SVG and opening PowerPoint files have been successfully fixed. Check below for more details.
Here is a list of all changes made in this release.
| Category | ID | Description |
| New feature | SPIREPPT-2772 | Supports reading CustomerData of Shape.
Presentation ppt = new Presentation();
ppt.LoadFromFile(inputFile);
List dataList = ppt.Slides[0].Shapes[1].CustomerDataList;
Console.WriteLine(dataList.Count);
for(int i = 0; i < dataList.Count; i++)
{
   string name = dataList[i].Name;
   string content = dataList[i].XML;
    File.WriteAllText(outputFile + name, content);

}
|
| New feature | SPIREPPT-2782 | Supports inserting formulas in table cells.
//Create a PPT document
Presentation presentation = new Presentation();


Double[] widths = new double[] { 100, 100, 150, 100, 100 };
Double[] heights = new double[] { 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15, 15 };

//Add new table to PPT
ITable table = presentation.Slides[0].Shapes.AppendTable(presentation.SlideSize.Size.Width / 2 - 275, 90, widths, heights);

String[,] dataStr = new String[,]{
{"Name",    "Capital",  "Continent",    "Area", "Population"},
{"Venezuela",   "Caracas",  "South America",    "912047",   "19700000"},
{"Bolivia", "La Paz",   "South America",    "1098575",  "7300000"},
{"Brazil",  "Brasilia", "South America",    "8511196",  "150400000"},
{"Canada",  "Ottawa",   "North America",    "9976147",  "26500000"},
{"Chile",   "Santiago", "South America",    "756943",   "13200000"},
{"Colombia",    "Bagota",   "South America",    "1138907",  "33000000"},
{"Cuba",    "Havana",   "North America",    "114524",   "10600000"},
{"Ecuador", "Quito",    "South America",    "455502",   "10600000"},
{"Paraguay",    "Asuncion","South America", "406576",   "4660000"},
{"Peru",    "Lima", "South America",    "1285215",  "21600000"},
{"Jamaica", "Kingston", "North America",    "11424",    "2500000"},
{"Mexico",  "Mexico City",  "North America",    "1967180",  "88600000"}
};

//Add data to table
for (int i = 0; i < 13; i++)
    for (int j = 0; j < 5; j++)
    {
        //Fill the table with data
        table[j, i].TextFrame.Text = dataStr[i, j];

        //Set the Font
        table[j, i].TextFrame.Paragraphs[0].TextRanges[0].LatinFont = new TextFont("Arial Narrow");
    }

//Set the alignment of the first row to Center
for (int i = 0; i < 5; i++)
{
    table[i, 0].TextFrame.Paragraphs[0].Alignment = TextAlignmentType.Center;
}
string latexMathCode = @"x^{2}+\sqrt{x^{2}+1}=2";
table[2, 3].TextFrame.Paragraphs.AddParagraphFromLatexMathCode(latexMathCode);
//Set the style of table
table.StylePreset = TableStylePreset.LightStyle3Accent1;

//Save the document
presentation.SaveToFile("Output.pptx", FileFormat.Pptx2010);
|
| Bug | SPIREPPT-2421 | Fixes the issue where the text was garbled when converting PowerPoint to PDF. |
| Bug | SPIREPPT-2691 | Fixes the issue that the application threw a "System.NullReferenceException" error when adding a GroupShape to a new PowerPoint file. |
| Bug | SPIREPPT-2798 | Fixes the issue where the text was lost when converting PowerPoint to PDF. |
| Bug | SPIREPPT-2804 | Fixes the issue where opening a file saved using the Presentation.GetStream() method would cause an error. |
| Bug | SPIREPPT-2824 | Fixes the issue where the position of shapes changed after using the Ungroup() method. |
| Bug | SPIREPPT-2840 | Fixes the issue that the application threw a "NullReferenceException" error when converting PowerPoint to SVG. |
| Bug | SPIREPPT-2851 | Fixes the issue where the shapes were incorrect when converting PowerPoint to SVG. |
Detect and Remove Blank Pages from PDF Files in Python
PDF documents may occasionally include blank pages. These pages can affect the reading experience, increase the file size and lead to paper waste during printing. To improve the professionalism and usability of a PDF document, detecting and removing blank pages is an essential step.
This article shows how to accurately detect and remove blank pages—including those that appear empty but actually contain invisible elements—using Python, Spire.PDF for Python, and Pillow.
Install Required Libraries
This tutorial requires two Python libraries:
- Spire.PDF for Python: Used for loading PDFs and detecting/removing blank pages.
- Pillow: A library for image processing that helps detect visually blank pages, which may contain invisible content.
You can easily install both libraries using pip:
pip install Spire.PDF Pillow
Need help installing Spire.PDF? Refer to this guide:
How to Install Spire.PDF for Python on Windows
How to Effectively Detect and Remove Blank Pages from PDF Files in Python
Spire.PDF provides a method called PdfPageBase.IsBlank() to check if a page is completely empty. However, some pages may appear blank but actually contain hidden content like white text, watermarks, or background images. These cannot be reliably detected using the PdfPageBase.IsBlank() method alone.
To ensure accuracy, this tutorial adopts a two-step detection strategy:
- Use the PdfPageBase.IsBlank() method to identify and remove fully blank pages.
- Convert non-blank pages to images and analyze them using Pillow to determine if they are visually blank.
⚠️ Important:
If you don’t use a valid license during the PDF-to-image conversion, an evaluation watermark will appear on the image, potentially affecting the blank page detection.
Contact the E-iceblue sales team to request a temporary license for proper functionality.
Steps to Detect and Remove Blank Pages from PDF in Python
Follow these steps to implement blank page detection and removal in Python:
1. Define a custom is_blank_image() Method
This custom function uses Pillow to check whether the converted image of a PDF page is blank (i.e., if all pixels are white).
2. Load the PDF Document
Load the PDF using the PdfDocument.LoadFromFile() method.
3. Iterate Through Pages
Loop through each page to check if it’s blank using two methods:
- If the PdfPageBase.IsBlank() method returns True, remove the page directly.
- If not, convert the page to an image using the PdfDocument.SaveAsImage() method and analyze it with the custom is_blank_image() method.
4. Save the Result PDF
Finally, save the PDF with blank pages removed using the PdfDocument.SaveToFile() method.
Code Example
- Python
import io
from spire.pdf import PdfDocument
from PIL import Image

# Custom function: Check if the image is blank (whether all pixels are white)
def is_blank_image(image):
        # Convert to RGB mode and then get the pixels
        img = image.convert("RGB")
        # Get all pixel points and check if they are all white
        white_pixel = (255, 255, 255)
        return all(pixel == white_pixel for pixel in img.getdata())

# Load the PDF document
pdf = PdfDocument()
pdf.LoadFromFile("Sample1111.pdf")

# Iterate through each page in reverse order to avoid index issues when deleting
for i in range(pdf.Pages.Count - 1, -1, -1):
    page = pdf.Pages.get_Item(i)
    # Check if the current page is completely blank
    if page.IsBlank():
        # If it's completely blank, remove it directly from the document
        pdf.Pages.RemoveAt(i)
    else:
        # Convert the current page to an image
        with pdf.SaveAsImage(i) as image_data:
            image_bytes = image_data.ToArray()
            pil_image = Image.open(io.BytesIO(image_bytes))
            # Check if the image is blank
            if is_blank_image(pil_image):
                # If it's a blank image, remove the corresponding page from the document
                pdf.Pages.RemoveAt(i)

# Save the resulting PDF
pdf.SaveToFile("RemoveBlankPages.pdf")
pdf.Close()

Frequently Asked Questions (FAQs)
Q1: What is considered a blank page in a PDF file?
A: A blank page may be truly empty or contain hidden elements such as white text, watermarks, or transparent objects. This solution detects both types using a dual-check strategy.
Q2: Can I use this method without a Spire.PDF license?
A: Yes, you can run it without a license. However, during PDF-to-image conversion, an evaluation watermark will be added to the output images, which may affect the accuracy of blank page detection. It's best to request a free temporary license for testing.
Q3: What versions of Python are compatible with Spire.PDF?
A: Spire.PDF for Python supports Python 3.7 and above. Ensure that Pillow is also installed to perform image-based blank page detection.
Q4: Can I modify the script to only detect blank pages without deleting them?
A: Absolutely. Just remove or comment out the pdf.Pages.RemoveAt(i) line and use print() or logging to list detected blank pages for further review.
Conclusion
Removing unnecessary blank pages from PDF files is an important step in optimizing documents for readability, file size, and professional presentation. With the combined power of Spire.PDF for Python and Pillow, developers can precisely identify both completely blank pages and pages that appear empty but contain invisible content. Whether you're generating reports, cleaning scanned files, or preparing documents for print, this Python-based solution ensures clean and efficient PDFs.
Get a Free License
To fully experience the capabilities of Spire.PDF for Python without any evaluation limitations, you can request a free 30-day trial license.
Create Word Documents with JavaScript in React
Creating dynamic documents is essential for many applications. This guide will explore how to generate a Word document using Spire.Doc for JavaScript within a React environment. We will cover the essential features needed for effective document creation, including adding titles, headings, and paragraphs to structure your content effectively.
You'll also learn how to enhance your documents by incorporating images, creating lists for organized information, and adding tables to present data clearly. By the end of this tutorial, you'll be equipped with the skills to produce professional documents directly from your React applications.
- Add Titles, Headings, and Paragraphs to Word
- Add an Image to Word
- Add a List to Word
- Add a Table to Word
Install Spire.Doc for JavaScript
To get started with creating Word documents in a React application, you can either download Spire.Doc for JavaScript from our website or install it via npm with the following command:
npm i spire.officeThe downloaded product package integrates Spire.Doc for JavaScript, Spire.XLS for JavaScript, Spire.PDF for JavaScript, and Spire.Presentation for JavaScript. To use the features of Spire.Doc for JavaScript, you need to copy the corresponding files (spire.doc.js, Spire.Doc.Wasm.zip, spire.common.js, Spire.Common.Wasm.zip, and the _framework folder) to the public folder of your project. To ensure proper text rendering, you can add relevant font files with a custom path. In the following example, the font is added to the path: public\static\font.
For more details, refer to the documentation: How to Integrate Spire.Doc for JavaScript in a React Project
Add Titles, Headings, and Paragraphs to Word in React
To add a title, headings, and paragraphs to a Word document, you primarily utilize the Document and Section classes provided by Spire.Doc for JavaScript. The AddParagraph() method creates new paragraphs, while AppendText() allows you to insert text into those paragraphs.
Paragraphs can be formatted using built-in styles (e.g., Title, Heading 1-4) for consistent structure, or customized with specific fonts, sizes, and colors through user-defined styles for tailored document design.
Steps for adding titles, headings, and parargraphs to a Word documents in React:
- Import the necessary font files into the virtual file system (VFS).
- Create a Document object using new wasmModule.Document().
- Include a new section in the document with Document.AddSection().
- Add paragraphs to the document using Section.AddParagraph().
- Use Paragraph.ApplyStyle() to apply built-in styles (Title, Heading1, Heading2, Heading3) to specific paragraphs.
- Define a custom paragraph style with new wasmModule.ParagraphStyle() and apply it to a designated paragraph.
- Save the document as a DOCX file and initiate the download.
- JavaScript
import React, { useState, useEffect } from 'react';

function App() {
  const [wasmModule, setWasmModule] = useState(null);
  // Load Spire.Doc
  useEffect(() => {
    (async () => {
      try {
        const publicUrl = process.env.PUBLIC_URL || '';
        const spireModule = await import(/* webpackIgnore: true */ `${publicUrl}/spire.doc.js`);
        const rawModule = spireModule.default || spireModule;
        window.wasmModule = typeof rawModule === 'function'
          ? await rawModule({ locateFile: p => p.endsWith('.wasm') ? `${publicUrl}/${p}` : p })
          : rawModule;
        setWasmModule(window.wasmModule);
      } catch (error) {
        console.error('Failed to load spire.doc.js WASM module:', error);
      }
    })();
  }, []);

  // Function to add text to word
  const AddText = async () => {
    const wasmModule = window.wasmModule.spiredoc;

    if (wasmModule) {
      // Load the font files into the virtual file system (VFS)
      await window.spire.FetchFileToVFS('times.ttf', '/Library/Fonts/', `${process.env.PUBLIC_URL}/static/font/`);
      await window.spire.FetchFileToVFS('timesbd.ttf', '/Library/Fonts/', `${process.env.PUBLIC_URL}/static/font/`);
      await window.spire.FetchFileToVFS('timesbi.ttf', '/Library/Fonts/', `${process.env.PUBLIC_URL}/static/font/`);
      await window.spire.FetchFileToVFS('timesi.ttf', '/Library/Fonts/', `${process.env.PUBLIC_URL}/static/font/`);

      // Create an instance of the Document class
      const doc = new wasmModule.Document();

      // Add a section
      let section = doc.AddSection();

      // Set page margins
      section.PageSetup.Margins.All = 60;

      // Add a title paragraph
      let title_para = section.AddParagraph();
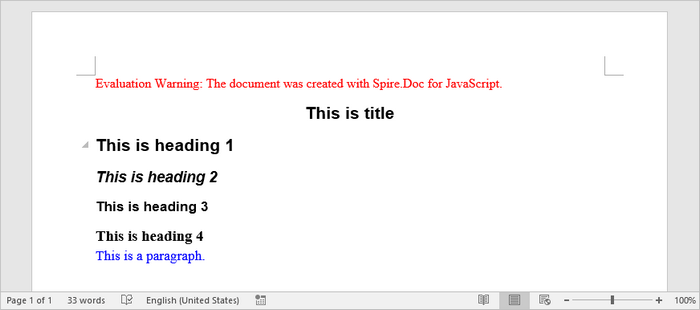
      title_para.AppendText('This is title');
      title_para.ApplyStyle({ builtinStyle: wasmModule.BuiltinStyle.Title });

      // Add heading paragraphs
      let heading_one = section.AddParagraph();
      heading_one.AppendText('This is heading 1');
      heading_one.ApplyStyle({ builtinStyle: wasmModule.BuiltinStyle.Heading1 });

      let heading_two = section.AddParagraph();
      heading_two.AppendText('This is heading 2');
      heading_two.ApplyStyle({ builtinStyle: wasmModule.BuiltinStyle.Heading2 });

      let heading_three = section.AddParagraph();
      heading_three.AppendText('This is heading 3');
      heading_three.ApplyStyle({ builtinStyle: wasmModule.BuiltinStyle.Heading3 });

      let heading_four = section.AddParagraph();
      heading_four.AppendText('This is heading 4');
      heading_four.ApplyStyle({ builtinStyle: wasmModule.BuiltinStyle.Heading4 });

      // Add a normal paragraph
      let normal_para = section.AddParagraph();
      normal_para.AppendText('This is a paragraph.');

      // Create a paragraph style,specifying font name, font size, and text color
      let paragraph_style =new wasmModule.ParagraphStyle(doc);
      paragraph_style.Name = 'newStyle';
      paragraph_style.CharacterFormat.FontName = 'Times New Roman'
      paragraph_style.CharacterFormat.FontSize = 13;
      paragraph_style.CharacterFormat.TextColor = wasmModule.Color.get_Blue();

      // Add the style to the document
      doc.Styles.Add(paragraph_style);

      // Apply the style to the paragraph
      normal_para.ApplyStyle(paragraph_style.Name);

      // Save the document
      const outputFileName = 'output.docx';
      doc.SaveToFile({ fileName: outputFileName, fileFormat: wasmModule.FileFormat.Docx2013 });

      // Create a Blob for the downloaded file
      const modifiedFileArray =window.dotnetRuntime.Module.FS.readFile(outputFileName);
      const modifiedFile = new Blob([modifiedFileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
      const url = URL.createObjectURL(modifiedFile);

      // Trigger file download
      const a = document.createElement('a');
      a.href = url;
      a.download = outputFileName;
      document.body.appendChild(a);
      a.click();
      document.body.removeChild(a);
      URL.revokeObjectURL(url);

      // Clean up resources
      doc.Dispose();
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add Text to a Word Document in React</h1>
      <button onClick={AddText} disabled={!wasmModule}>
        Generate
      </button>
    </div>
  );
}

export default App;
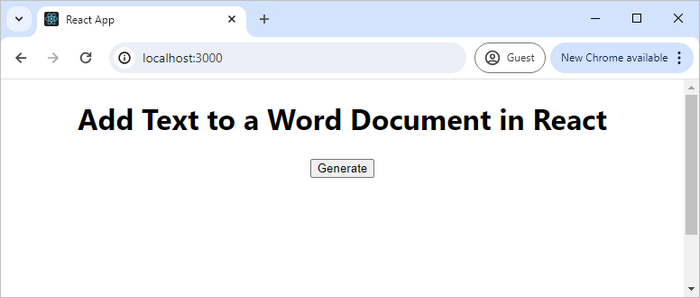
Run the code to launch the React app at localhost:3000. Click "Generate", and a "Save As" window will appear, prompting you to save the output file in your chosen folder.
Below is a screenshot of the generated Word file that includes a title, several headings, and a normal paragraph:
Add an Image to Word in React
Inserting images into a Word document involves using the AppendPicture() method, which allows you to add a picture to a specific paragraph. The process begins by loading the image file into the virtual file system (VFS), ensuring that the image is accessible for insertion.
Steps for adding an image to a Word doucment in React:
- Load an image file into the virtual file system (VFS).
- Create a Document object using new wasmModule.Document().
- Add a new section to the document with Document.AddSection().
- Insert a new paragraph in the section using Section.AddParagraph().
- Use the Paragraph.AppendPicture() method to add the loaded image to the paragraph.
- Save the document as a DOCX file and trigger the download.
- JavaScript
import React, { useState, useEffect } from 'react';

function App() {
  const [wasmModule, setWasmModule] = useState(null);
  // Load Spire.Doc
  useEffect(() => {
    (async () => {
      try {
        const publicUrl = process.env.PUBLIC_URL || '';
        const spireModule = await import(/* webpackIgnore: true */ `${publicUrl}/spire.doc.js`);
        const rawModule = spireModule.default || spireModule;
        window.wasmModule = typeof rawModule === 'function'
          ? await rawModule({ locateFile: p => p.endsWith('.wasm') ? `${publicUrl}/${p}` : p })
          : rawModule;
        setWasmModule(window.wasmModule);
      } catch (error) {
        console.error('Failed to load spire.doc.js WASM module:', error);
      }
    })();
  }, []);

  // Function to add image to word
  const AddImage = async () => {
    const wasmModule = window.wasmModule.spiredoc;

    if (wasmModule) {
      // Load the font files into the virtual file system (VFS)
      await window.spire.FetchFileToVFS('times.ttf', '/Library/Fonts/', `${process.env.PUBLIC_URL}/static/font/`);

      // Specify the input file name and the output file name
      const inputImageFile = 'logo.png';
      const outputFileName = 'output.docx';

      // Fetch the input file and add it to the VFS
      await window.spire.FetchFileToVFS(inputImageFile, '', `${process.env.PUBLIC_URL}/static/data/`);

      // Create an instance of the Document class
      const doc = new wasmModule.Document();

      // Add a section
      let section = doc.AddSection();

      // Set page margins
      section.PageSetup.Margins.All = 60;

      // Add a paragraph
      let image_para = section.AddParagraph();

      // Add an image to the paragraph
      image_para.AppendPicture({ imgFile: inputImageFile });

      // Save the document
      doc.SaveToFile({ fileName: outputFileName, fileFormat: wasmModule.FileFormat.Docx2013 });

      // Create a Blob for the downloaded file
      const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
      const modifiedFile = new Blob([modifiedFileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
      const url = URL.createObjectURL(modifiedFile);

      // Trigger the download
      const a = document.createElement('a');
      a.href = url;
      a.download = outputFileName;
      document.body.appendChild(a);
      a.click();
      document.body.removeChild(a);
      URL.revokeObjectURL(url);

      // Clean up resources
      doc.Dispose();
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add image to a Word Document in React</h1>
      <button onClick={AddImage} disabled={!wasmModule}>
        Generate
      </button>
    </div>
  );
}

export default App;
Add a List to Word in React
To create lists in your Word document, utilize the ListStyle class to define the appearance of your lists, such as bulleted or numbered formats. The ApplyStyle() method associates paragraphs with the defined list style, enabling consistent formatting across multiple items.
Steps for adding a list to a Word document in React:
- Load the required font files into the virtual file system (VFS).
- Create a Document object using new wasmModule.Document().
- Add a section to the document with Document.AddSection().
- Define a list style using doc.Styles.Add({ listType: wasmModule.ListType.Bulleted, name: "bulletedList" }).
- Insert several paragraphs in the section using Section.AddParagraph().
- Apply the defined list style to the paragraphs using Paragraph.ListFormat.ApplyStyle().
- Save the document as a DOCX file and trigger the download.
- JavaScript
import React, { useState, useEffect } from 'react';

function App() {
  const [wasmModule, setWasmModule] = useState(null);
  // Load Spire.Doc
  useEffect(() => {
    (async () => {
      try {
        const publicUrl = process.env.PUBLIC_URL || '';
        const spireModule = await import(/* webpackIgnore: true */ `${publicUrl}/spire.doc.js`);
        const rawModule = spireModule.default || spireModule;
        window.wasmModule = typeof rawModule === 'function'
          ? await rawModule({ locateFile: p => p.endsWith('.wasm') ? `${publicUrl}/${p}` : p })
          : rawModule;
        setWasmModule(window.wasmModule);
      } catch (error) {
        console.error('Failed to load spire.doc.js WASM module:', error);
      }
    })();
  }, []);

  // Function to add list to word
  const AddList = async () => {
    const wasmModule = window.wasmModule.spiredoc;

    if (wasmModule) {
      // Load the font files into the virtual file system (VFS)
      await window.spire.FetchFileToVFS('times.ttf', '/Library/Fonts/', `${process.env.PUBLIC_URL}/static/font/`);

      // Create an instance of the Document class
      const doc = new wasmModule.Document();

      // Add a section
      let section = doc.AddSection();

      // Set page margins
      section.PageSetup.Margins.All = 60;

      // Define a bullet list style
      let list_style = doc.Styles.Add({ listType: wasmModule.ListType.Bulleted, name: "bulletedList" });
      list_style.ListRef.Levels.get_Item(0).BulletCharacter = '\u00B7';
      list_style.ListRef.Levels.get_Item(0).CharacterFormat.FontName = 'Symbol';
      list_style.ListRef.Levels.get_Item(0).CharacterFormat.FontSize = 14;
      list_style.ListRef.Levels.get_Item(0).TextPosition = 20;


      // Add title paragraph
      let paragraph = section.AddParagraph();
      let text_range = paragraph.AppendText('Fruits:');
      paragraph.Format.AfterSpacing = 5;
      text_range.CharacterFormat.FontName = 'Times New Roman'
      text_range.CharacterFormat.FontSize = 14;

      // Add items to the bullet list
      const fruits = ['Apple', 'Banana', 'Watermelon', 'Mango'];
      fruits.forEach(fruit => {
        paragraph = section.AddParagraph();
        let text_range = paragraph.AppendText(fruit);
        paragraph.ListFormat.ApplyStyle(list_style.Name);
        paragraph.ListFormat.ListLevelNumber = 0;
        text_range.CharacterFormat.FontName = 'Times New Roman'
        text_range.CharacterFormat.FontSize = 14;
      });

      // Save the document
      const outputFileName = 'output.docx';
      doc.SaveToFile({ fileName: outputFileName, fileFormat: wasmModule.FileFormat.Docx2013 });

      // Create a Blob for the downloaded file
      const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
      const modifiedFile = new Blob([modifiedFileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
      const url = URL.createObjectURL(modifiedFile);

      // Trigger file download
      const a = document.createElement('a');
      a.href = url;
      a.download = outputFileName;
      document.body.appendChild(a);
      a.click();
      document.body.removeChild(a);
      URL.revokeObjectURL(url);

      // Clean up resources
      doc.Dispose();
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add Lists to a Word Document in React</h1>
      <button onClick={AddList} disabled={!wasmModule}>
        Generate
      </button>
    </div>
  );
}

export default App;
Add a Table to Word in React
To create tables, use the AddTable() method where you can specify the number of rows and columns with ResetCells(). Once the table is created, you can populate individual cells by using the AddParagraph() and AppendText() methods to insert text content. Additionally, the AutoFit() method can be employed to automatically adjust the table layout based on its contents, ensuring a clean and organized presentation of your data.
Steps for adding a table to a Word document in React:
- Load the required font files into the virtual file system (VFS).
- Create a Document object using new wasmModule.Document().
- Add a section to the document with Document.AddSection().
- Create a two-dimensional array to hold the table data, including headers and values.
- Use Section.AddTable() to create a table, specifying visibility options like borders.
- Call Table.ResetCells() to define the number of rows and columns in the table based on your data.
- Iterate through the data array, adding text to each cell using the TableCell.AddParagraph() and Paragraph.AppendText() methods.
- Use the Table.AutoFit() method to adjust the table size according to the content.
- Save the document as a DOCX file and trigger the download.
- JavaScript
import React, { useState, useEffect } from 'react';

function App() {
  const [wasmModule, setWasmModule] = useState(null);
  // Load Spire.Doc
  useEffect(() => {
    (async () => {
      try {
        const publicUrl = process.env.PUBLIC_URL || '';
        const spireModule = await import(/* webpackIgnore: true */ `${publicUrl}/spire.doc.js`);
        const rawModule = spireModule.default || spireModule;
        window.wasmModule = typeof rawModule === 'function'
          ? await rawModule({ locateFile: p => p.endsWith('.wasm') ? `${publicUrl}/${p}` : p })
          : rawModule;
        setWasmModule(window.wasmModule);
      } catch (error) {
        console.error('Failed to load spire.doc.js WASM module:', error);
      }
    })();
  }, []);

  // Function to add table to word
  const AddTable = async () => {
    const wasmModule = window.wasmModule.spiredoc;

    if (wasmModule) {
      // Load the font files into the virtual file system (VFS)
      await window.spire.FetchFileToVFS('times.ttf', '/Library/Fonts/', `${process.env.PUBLIC_URL}/static/font/`);

      // Create an instance of the Document class
      const doc = new wasmModule.Document();

      // Add a section
      let section = doc.AddSection();

      // Set page margins
      section.PageSetup.Margins.All = 60;

      // Define table data
      let data =
        [
          ['Product', 'Unit Price', 'Quantity', 'Sub Total'],
          ['A', '$29', '120', '$3,480'],
          ['B', '$35', '110', '$3,850'],
          ['C', '$68', '140', '$9,520'],
        ];

      // Add a table
      let table = section.AddTable({ showBorder: true });

      // Set row number and column number
      table.ResetCells(data.length, data[0].length);

      // Write data to cells
      for (let r = 0; r < data.length; r++) {
        let data_row = table.Rows.get_Item(r);
        data_row.Height = 20;
        data_row.HeightType = wasmModule.TableRowHeightType.Exactly;
        data_row.RowFormat.BackColor = wasmModule.Color.Empty();
        for (let c = 0; c < data[r].length; c++) {

          let cell = data_row.Cells.get_Item(c);
          cell.CellFormat.VerticalAlignment = wasmModule.VerticalAlignment.Middle;
          let text_range = cell.AddParagraph().AppendText(data[r][c]);
          text_range.CharacterFormat.FontName = 'Times New Roman'
          text_range.CharacterFormat.FontSize = 14;
        }
      }

      // Automatically fit the table to the cell content
      table.AutoFit(wasmModule.AutoFitBehaviorType.AutoFitToContents);

      // Save the document
      const outputFileName = 'output.docx';
      doc.SaveToFile({ fileName: outputFileName, fileFormat: wasmModule.FileFormat.Docx2013 });

      // Create a Blob for the downloaded file
      const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
      const modifiedFile = new Blob([modifiedFileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
      const url = URL.createObjectURL(modifiedFile);

      // Trigger file download
      const a = document.createElement('a');
      a.href = url;
      a.download = outputFileName;
      document.body.appendChild(a);
      a.click();
      document.body.removeChild(a);
      URL.revokeObjectURL(url);

      // Clean up resources
      doc.Dispose();
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add Tables to a Word Document in React</h1>
      <button onClick={AddTable} disabled={!wasmModule}>
        Generate
      </button>
    </div>
  );
}

export default App;
Get a Free License
To fully experience the capabilities of Spire.Doc for JavaScript without any evaluation limitations, you can request a free 30-day trial license.