Encrypting or Decrypting PDF Documents in React with JavaScript
Once a contract, a quotation or a financial statement leaves the office as a PDF, its content is essentially wide open — anyone can open it, save a copy, edit it and send it on. Setting a password, or allowing reading only while switching off printing and copying, is the most direct way to close that gap at the distribution stage. Doing this used to mean either desktop software, which is hard to embed in a web workflow, or uploading the file to a server, which means the document leaves the user's device.
Spire.PDF for JavaScript loads, modifies and saves PDF documents directly in the browser based on WebAssembly, so the whole encryption process runs locally and reads and writes files through a virtual file system (VFS), with no backend service required.
This article covers three core features:
For installation and project configuration, refer to Integrating Spire.PDF for JavaScript in a React Project. The following examples assume Spire.PDF is installed and the WebAssembly module has been initialized.
Encrypting a PDF Document
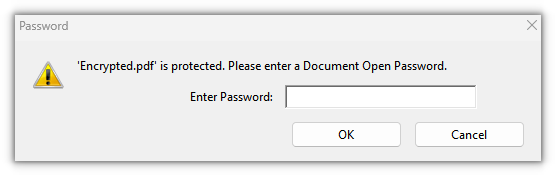
The constructor of PdfPasswordSecurityPolicy takes two arguments: a user password and an owner password. Whoever receives the document needs the first one to open it; the second stays with the document owner and is used to lift the restrictions later. The algorithm is set through EncryptionAlgorithm, here AES-128; DocumentPrivilege decides which operations are allowed once the document is open, and get_AllowAll() grants all of them.
function App() {
  const encryptPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be encrypted into the VFS
    const inputFileName = 'ContractTemplate.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Create the password security policy: the first argument is the user password, the second the owner password
    const policy = new pdfModule.PdfPasswordSecurityPolicy('spire123', 'owner123');

    // Specify the encryption algorithm
    policy.EncryptionAlgorithm = pdfModule.PdfEncryptionAlgorithm.AES_128;

    // Specify the privileges: get_AllowAll() means no operation is restricted
    policy.DocumentPrivilege = pdfModule.PdfDocumentPrivilege.get_AllowAll();

    // Apply the policy and save the document
    doc.Encrypt(policy);
    const outputFileName = 'Encrypted.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Encrypt a PDF</h1>
      <button onClick={encryptPdf}>
        Start Encrypting
      </button>
    </div>
  );
}

export default App;
The PDF document after a user password and an owner password are set
Restricting the Permissions of a PDF Document
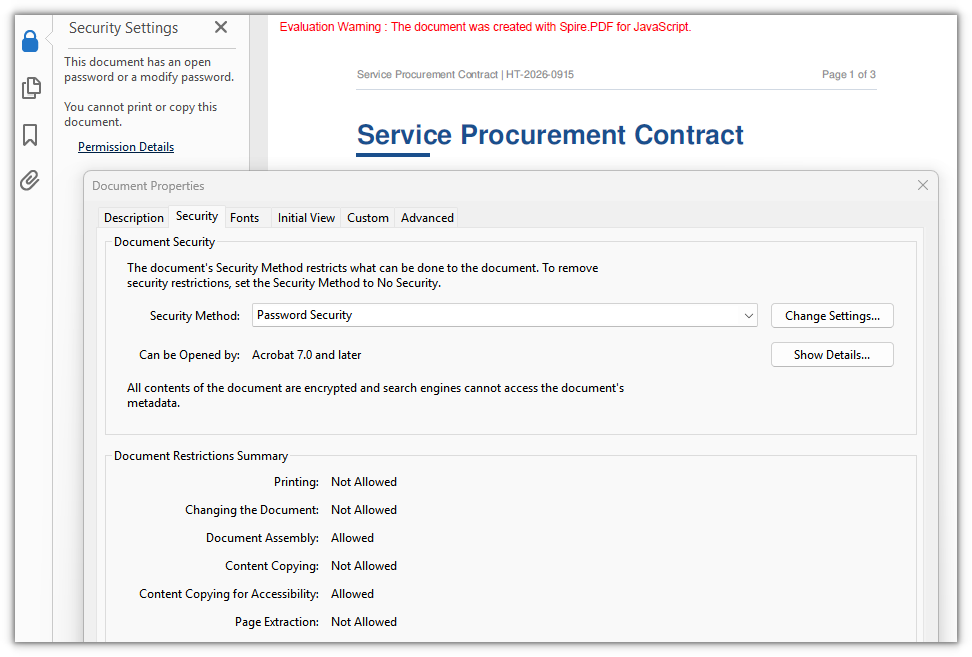
Leave the user password empty and set only an owner password, and the document opens without a password while printing, copying and editing are granted or forbidden item by item — a good fit for distribution scenarios where the file may be read but not taken away. The permissions themselves are described by PdfDocumentPrivilege: start from a fully permissive baseline, then switch off what is not needed. Here printing, copying content and modifying content are switched off.
function App() {
  const restrictPdfPermissions = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be processed into the VFS
    const inputFileName = 'ContractTemplate.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Leave the user password empty: the document opens directly; the owner password lifts the restrictions later
    const policy = new pdfModule.PdfPasswordSecurityPolicy('', 'owner123');
    policy.EncryptionAlgorithm = pdfModule.PdfEncryptionAlgorithm.AES_128;

    // Start from full permissions and switch off the ones that are not needed
    const privilege = pdfModule.PdfDocumentPrivilege.get_AllowAll();
    privilege.AllowPrint = false;
    privilege.AllowContentCopying = false;
    privilege.AllowModifyContents = false;
    policy.DocumentPrivilege = privilege;

    // Apply the policy and save the document
    doc.Encrypt(policy);
    const outputFileName = 'PermissionRestricted.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Restrict PDF Permissions</h1>
      <button onClick={restrictPdfPermissions}>
        Start Restricting
      </button>
    </div>
  );
}

export default App;
A PDF document that opens without a password but whose printing, copying and editing are forbidden
Decrypting a PDF Document
Decryption means removing the existing password protection, and it presupposes that the password is at hand. If only the user password is available, Decrypt needs the owner password as well before the restrictions can be lifted; calling the parameterless Decrypt() with just the user password is rejected.
function App() {
  const decryptPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be decrypted into the VFS
    const inputFileName = 'EncryptedContract.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the encrypted document with its user password
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName, 'spire123');

    // Confirm that the document really is password protected
    if (!doc.IsEncrypted) {
      alert('This document is not encrypted, no decryption needed');
      return;
    }

    // Remove the protection with the owner password
    doc.Decrypt('owner123');

    const outputFileName = 'Decrypted.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Decrypt a PDF</h1>
      <button onClick={decryptPdf}>
        Start Decrypting
      </button>
    </div>
  );
}

export default App;
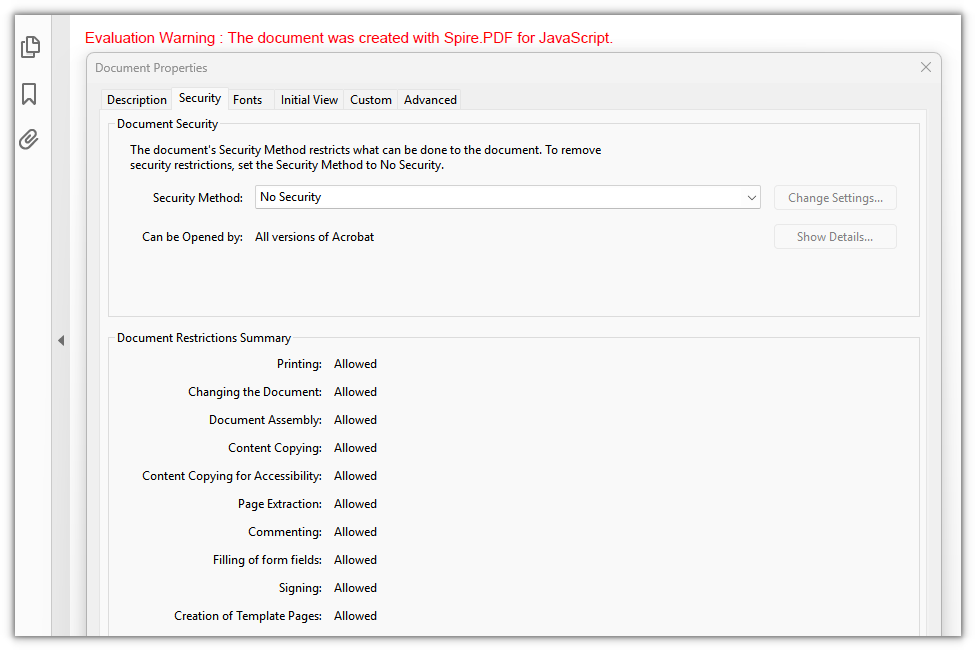
The PDF document after the password protection is removed, ready to open directly
FAQ
Opening an encrypted document reports an invalid password
Reason: LoadFromFile was called without a password, or the password passed in does not match the user password of the document. In that case Spire.PDF throws Can not open an encrypted document. The password is invalid. instead of returning an empty PdfDocument.
Solution: Pass the user password as the second argument of LoadFromFile:
// The second argument is the user password
doc.LoadFromFile(inputFileName, 'spire123');
Calling Decrypt() reports "Cannot decrypt documents without permission password"
Reason: The document was loaded with the user password, so only reading rights are available. Removing the encryption is an owner-level operation and requires the owner password (also called the permissions password).
Solution: Both forms work — load with the owner password and call the parameterless Decrypt(), or keep the user password for loading and hand the owner password to Decrypt:
// Form 1: load with the owner password, then remove the protection directly
doc.LoadFromFile(inputFileName, 'owner123');
doc.Decrypt();

// Form 2: load with the user password and pass the owner password to Decrypt
doc.LoadFromFile(inputFileName, 'spire123');
doc.Decrypt('owner123');
Which encryption algorithm should I choose
Reason: PdfEncryptionKeySize and PdfEncryptionAlgorithm list RC4_40, RC4_128, AES_128, AES_256 and more, but the WebAssembly build that runs in the browser does not support AES-256 yet — setting EncryptionAlgorithm to AES_256 throws Cryptography_AlgorithmNotSupported.
Solution: Use AES_128 on the web; when a legacy reader that only understands RC4 really has to be supported, switch to RC4_128:
// Recommended on the web: AES-128
policy.EncryptionAlgorithm = pdfModule.PdfEncryptionAlgorithm.AES_128;

// For legacy readers: RC4-128
policy.EncryptionAlgorithm = pdfModule.PdfEncryptionAlgorithm.RC4_128;
Get a Free License
If you wish to remove the evaluation message from the result document or remove feature limitations, please contact sales to obtain a temporary license valid for 30 days.
Extract PDF Attachments in React Using JavaScript
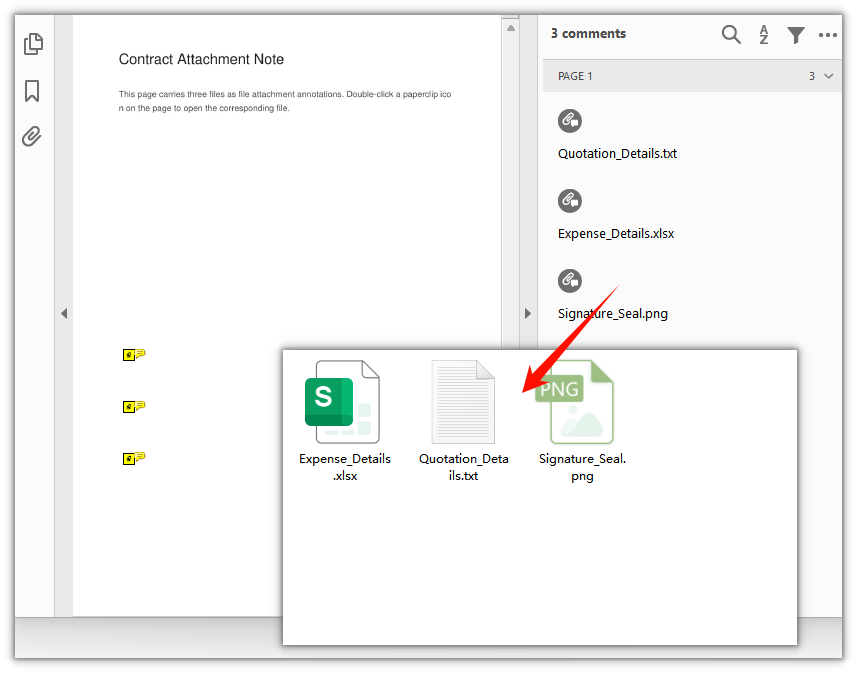
A PDF document can carry attachments — images, spreadsheets, supplementary notes — and distribute them together with the document. This "document package" form is common in contracts, quotations, and reports. Attachments in a PDF exist in two forms: document attachments, which are attached to the whole document and listed together in the reader's "Attachments" panel, and annotation attachments, which appear as paperclip icons on a page and open the attached file when double-clicked. When we receive a PDF with attachments, we often need to pull the attachments out for separate use, and these two kinds of attachments are read in different ways, requiring different APIs.
Spire.PDF for JavaScript processes PDF documents directly in the browser based on WebAssembly, managing input and output files through a virtual file system (VFS) with no backend service required. The two kinds of attachments are read through different entry points, but both yield the file name and content through FileName and Data: document attachments use PdfDocument.Attachments with PdfEmbeddedFileSpecification, while annotation attachments require visiting PdfPage.Annotations page by page and filtering out PdfAttachmentAnnotationWidget.
This article covers two core features:
For installation and project setup, see Integrate Spire.PDF for JavaScript in a React Project. The examples below assume that Spire.PDF is installed and that the WebAssembly module has been initialized.
Related Knowledge
Attachments in a PDF file come in two kinds: document-level attachments and annotation-level attachments. The table below explains the differences between them and how each is represented in Spire.PDF for JavaScript.
| Attachment Type | Representation | Definition |
|---|---|---|
| Document attachment | PdfDocument.Attachments, read through PdfEmbeddedFileSpecification |
An attachment added at the document level is not displayed on the PDF page, but can be viewed in the "Attachments" panel of a PDF reader. |
| Annotation attachment | PdfAttachmentAnnotationWidget |
A file attached as an annotation can be found on the page or in the "Attachments" panel. An annotation attachment appears as a paperclip icon on the page; you can double-click the icon to open the file while reading the document. |
Extract Attachments from a PDF Document
PdfDocument.Attachments returns all document-level attachments. Iterate the collection, and after wrapping each attachment with new PdfEmbeddedFileSpecification(attachment.H), write the attachment content into the VFS through its FileName and Data. Once everything has been written out, use JSZip to package the files into a single zip file for download. This approach suits saving or migrating all attachments of a document at once.
import JSZip from 'jszip';

function App() {
  const extractDocumentAttachments = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be processed into the VFS
    const inputFileName = 'SampleWithAttachments.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Get the attachment collection of the document
    let collection = doc.Attachments;

    // Create a temporary directory in the VFS to hold the extracted attachments
    const outputDirectoryName = 'attachmentFiles/';
    window.dotnetRuntime.Module.FS.mkdirTree(outputDirectoryName);

    // Take out each attachment and write it into the temporary directory under its own file name
    for (let i = 0; i < collection.Count; i++) {
      let attachment = collection.get_Item(i);

      // Wrap the underlying handle H with PdfEmbeddedFileSpecification to read the attachment content
      let embeddedFileSpecification = new pdfModule.PdfEmbeddedFileSpecification(attachment.H);
      window.dotnetRuntime.Module.FS.writeFile(
        outputDirectoryName + embeddedFileSpecification.FileName,
        embeddedFileSpecification.Data
      );
    }

    // Release the document resources
    doc.Close();

    // Package all attachments in the temporary directory into a single zip file
    const zip = new JSZip();
    let items = await window.dotnetRuntime.Module.FS.readdir(outputDirectoryName);
    items = items.filter((item) => item !== '.' && item !== '..');
    for (const item of items) {
      const fileData = window.dotnetRuntime.Module.FS.readFile(outputDirectoryName + item);
      zip.file(item, fileData);
    }
    const zipBlob = await zip.generateAsync({ type: 'blob' });

    // Trigger the download
    const outputFileName = 'DocumentAttachments.zip';
    const url = URL.createObjectURL(zipBlob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Extract Attachments from a PDF Document</h1>
      <button onClick={extractDocumentAttachments}>
        Start Extraction
      </button>
    </div>
  );
}

export default App;
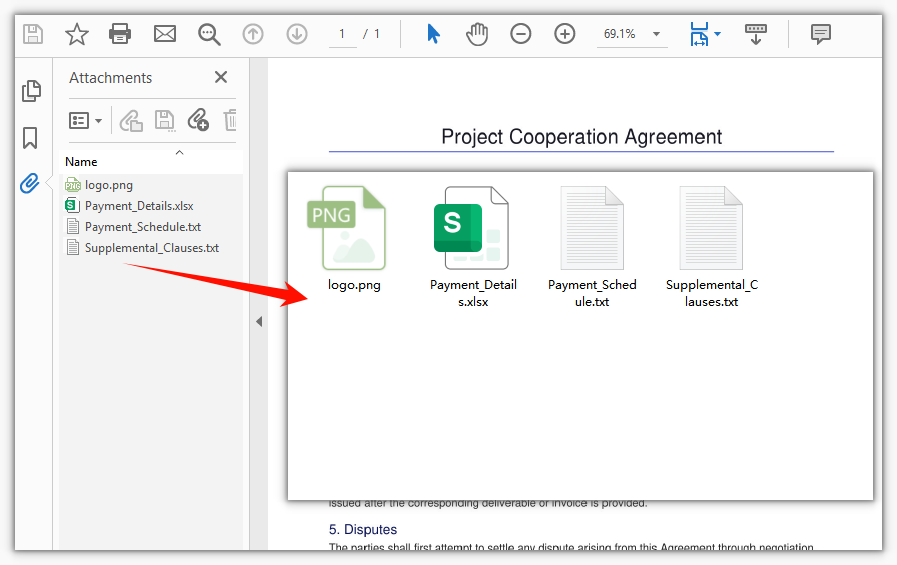
The zip file packaged from all document-level attachments after batch export
Extract Attachments from PDF Annotations
Annotation attachments are read differently from document attachments: they belong to page annotations and cannot be obtained through doc.Attachments. You first iterate doc.Pages to visit PdfPage.Annotations page by page, then use instanceof to test whether each annotation is a PdfAttachmentAnnotationWidget (an attachment annotation). For the matched annotations, FileName and Data are the name and content of the attached file. Because attachment annotations may be spread across different pages, the outer loop must cover every page to extract all annotation attachments in the document.
import JSZip from 'jszip';

function App() {
  const extractAnnotationAttachments = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be processed into the VFS
    const inputFileName = 'AnnotationAttachmentSample.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Create a temporary directory in the VFS to hold the extracted attachments
    const outputDirectoryName = 'annotationFiles/';
    window.dotnetRuntime.Module.FS.mkdirTree(outputDirectoryName);

    // Iterate page by page and extract attachments from the annotations
    for (let p = 0; p < doc.Pages.Count; p++) {
      let page = doc.Pages.get_Item(p);

      // Get the annotation collection of the current page
      let annotations = page.Annotations;

      for (let i = 0; i < annotations.Count; i++) {
        let annotation = annotations.get_Item(i);

        // Handle only attachment annotations; skip other annotations (text, link, and so on)
        if (annotation instanceof pdfModule.PdfAttachmentAnnotationWidget) {
          // FileName is the attached file name, and Data is the binary content of the attachment
          window.dotnetRuntime.Module.FS.writeFile(
            outputDirectoryName + annotation.FileName,
            annotation.Data
          );
        }
      }
    }

    // Release the document resources
    doc.Close();

    // Package all attachments in the temporary directory into a single zip file
    const zip = new JSZip();
    let items = await window.dotnetRuntime.Module.FS.readdir(outputDirectoryName);
    items = items.filter((item) => item !== '.' && item !== '..');
    for (const item of items) {
      const fileData = window.dotnetRuntime.Module.FS.readFile(outputDirectoryName + item);
      zip.file(item, fileData);
    }
    const zipBlob = await zip.generateAsync({ type: 'blob' });

    // Trigger the download
    const outputFileName = 'AnnotationAttachments.zip';
    const url = URL.createObjectURL(zipBlob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Extract Attachments from PDF Annotations</h1>
      <button onClick={extractAnnotationAttachments}>
        Start Extraction
      </button>
    </div>
  );
}

export default App;
The zip file packaged from the attachments extracted from page annotations
FAQ
Why don't the paperclip attachments visible on the page show up in doc.Attachments
Cause: Attachments in a PDF fall into two levels, document-level and annotation-level. PdfDocument.Attachments returns only document-level attachments (listed in the reader's "Attachments" panel), whereas the paperclip icons on a page are annotation-level attachments — part of the page annotations — and never appear in the Attachments collection.
Solution: To extract annotation attachments, visit the page annotation collection page by page and filter for attachment annotations by type:
for (let p = 0; p < doc.Pages.Count; p++) {
  let annotations = doc.Pages.get_Item(p).Annotations;
  for (let i = 0; i < annotations.Count; i++) {
    if (annotations.get_Item(i) instanceof pdfModule.PdfAttachmentAnnotationWidget) {
      // Handle the attachment annotation
    }
  }
}
Why must the type be checked when iterating page.Annotations
Cause: A page can hold many kinds of annotations at the same time, such as text annotations, link annotations, and stamp annotations, and their properties differ. Only the attachment annotation PdfAttachmentAnnotationWidget provides FileName and Data; reading these two properties on an arbitrary annotation is not reliable.
Solution: Use instanceof PdfAttachmentAnnotationWidget to test the type first, then read the properties:
let annotation = annotations.get_Item(i);
if (annotation instanceof pdfModule.PdfAttachmentAnnotationWidget) {
  let fileName = annotation.FileName;
  let data = annotation.Data;
}
Why only some of the annotation attachments are extracted
Cause: Annotation attachments are attached to a specific page, and different pages may each carry some. If you visit only doc.Pages.get_Item(0), attachment annotations on the remaining pages are missed.
Solution: Iterate doc.Pages in an outer loop and examine the annotation collection of every page:
for (let p = 0; p < doc.Pages.Count; p++) {
  let annotations = doc.Pages.get_Item(p).Annotations;
  // Examine the annotations of this page one by one
}
Get a Free License
If you want to remove the evaluation message from the result documents or get rid of the feature limitations, please contact sales to obtain a temporary license valid for 30 days.
Adding or Deleting PDF Pages in React with JavaScript
A PDF document is organized page by page, and reading, printing and archiving all follow that structure. In practice, you often need to adjust the pages of an existing PDF: add a signature page to a contract, append a summary page at the end of a report, or remove a page that no longer belongs. Doing this with desktop software or a server-side re-layout means exporting and uploading files back and forth. Handling it directly in the browser keeps the document on the user's device and shortens the whole path.
Spire.PDF for JavaScript loads, modifies and saves PDF documents directly in the browser based on WebAssembly, managing input and output files through a virtual file system (VFS), with no backend service required.
This article covers three core features:
For installation and project configuration, refer to Integrating Spire.PDF for JavaScript in a React Project. The following examples assume Spire.PDF is installed and the WebAssembly module has been initialized.
Adding a Page to a PDF
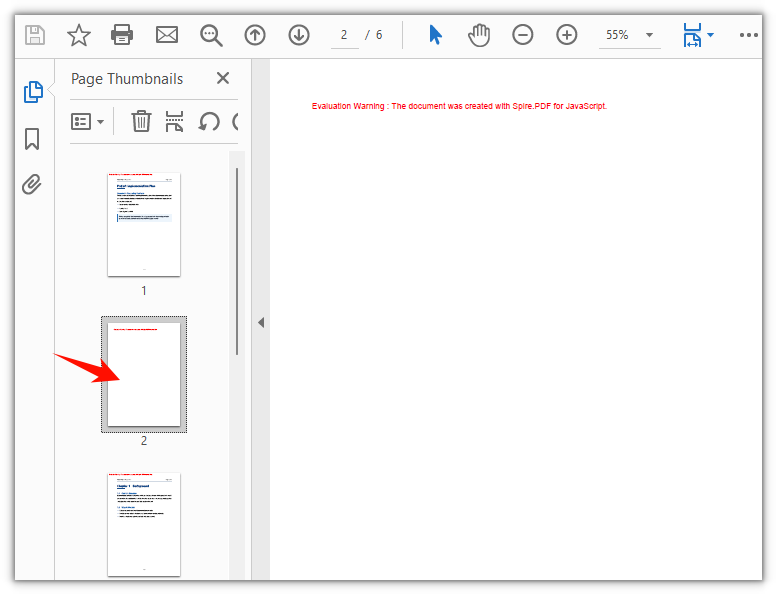
Adding a page means inserting one item into the PdfPageCollection. Use Pages.Insert(index) to insert at a specific position; the index is 0-based, and the pages after the insertion point shift back by one. Here the blank page goes into the second position and the existing pages move onward, which suits adding a page in the middle of a document.
function App() {
  const addPageToPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file into the VFS
    const inputFileName = 'Multipage_Document.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Insert a blank page as the second page (the index is 0-based, so index 1 is the second page)
    doc.Pages.Insert(1);

    // Define the output file name and save the document
    const outputFileName = 'Page_Inserted.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add a Page to PDF</h1>
      <button onClick={addPageToPdf}>
        Start Adding
      </button>
    </div>
  );
}

export default App;
The PDF document after a blank page is inserted as the second page
Adding a Blank Page at the End of a Document
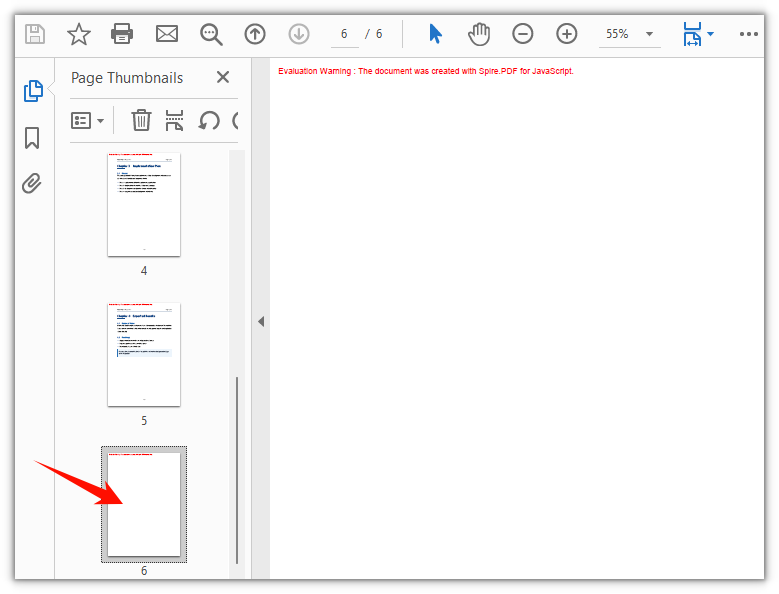
Spire.PDF for JavaScript also provides the Pages.Add() method, which appends a blank page at the end of a document. It uses A4 as the default page size and 40-point margins on all four sides; when needed, you can set the page size and margins yourself.
function App() {
  const appendPageToPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file into the VFS
    const inputFileName = 'Multipage_Document.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Append a blank A4 page with zero margins on all four sides
    doc.Pages.Add(pdfModule.PdfPageSize.A4(), new pdfModule.PdfMargins(0.0, 0.0));

    // Define the output file name and save the document
    const outputFileName = 'Page_Appended.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Append a Blank Page to PDF</h1>
      <button onClick={appendPageToPdf}>
        Start Adding
      </button>
    </div>
  );
}

export default App;
The PDF document after a blank A4 page is appended at the end
Deleting a Page from a PDF
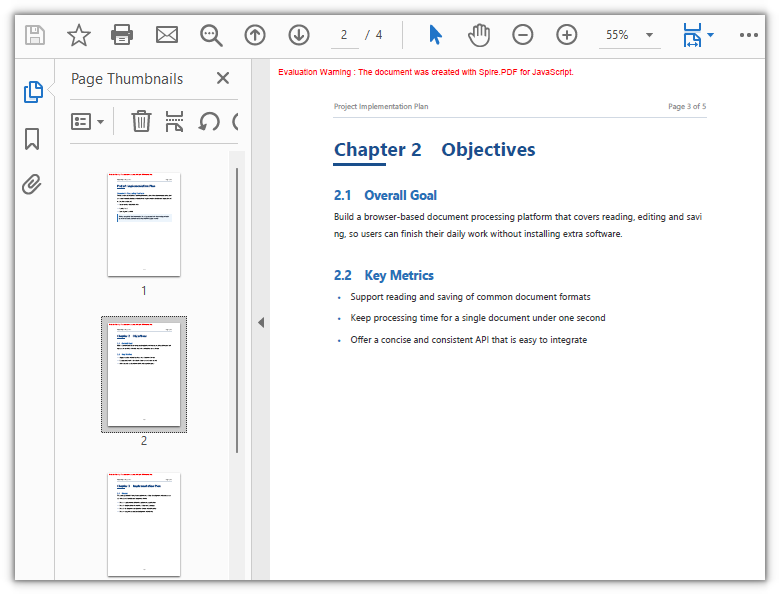
Deleting a page also works through the page collection: Pages.RemoveAt(index) removes one page by index, starting at 0, and the indexes of the pages after it shift forward by one. Before writing the delete logic, check the current page count with Pages.Count so the index stays in range. Here the second page of the sample document is removed and the remaining pages keep their original order.
function App() {
  const deletePageFromPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file into the VFS
    const inputFileName = 'Multipage_Document.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Delete the second page (the index is 0-based, so index 1 is the second page)
    doc.Pages.RemoveAt(1);

    // Define the output file name and save the document
    const outputFileName = 'Page_Deleted.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Delete a Page from PDF</h1>
      <button onClick={deletePageFromPdf}>
        Start Deleting
      </button>
    </div>
  );
}

export default App;
The PDF document after the second page is deleted
FAQ
How do I set the page size and margins of a new blank page
Reason: Pages.Add and Pages.Insert create blank pages of a regular size with default margins. When a new page has to match a specific paper size or margin, both values need to be passed in.
Solution: The paper size comes from PdfPageSize, such as PdfPageSize.A4() or PdfPageSize.A3(); the margins come from PdfMargins, where the two-argument form new PdfMargins(0.0, 0.0) sets both the vertical and horizontal margins to 0. To control each side separately, pass the named fields:
// A blank A4 page with zero margins on all four sides
doc.Pages.Add(pdfModule.PdfPageSize.A4(), new pdfModule.PdfMargins(0.0, 0.0));

// Set the top, bottom, left and right margins individually
doc.Pages.Add(pdfModule.PdfPageSize.A4(),
  new pdfModule.PdfMargins({ left: 40, top: 40, right: 40, bottom: 40 }));
Why does deleting a page report an index out of range
Reason: RemoveAt(index) is 0-based, and its valid range is 0 to Pages.Count - 1. Without checking the page count first, passing a value equal to or greater than Count goes out of range.
Solution: Check the page count with Pages.Count before deleting and keep the index within range. To delete the last page, for example, the index should be Count - 1:
let total = doc.Pages.Count;

if (total > 0) {
  // Delete the last page
  doc.Pages.RemoveAt(total - 1);
}
What should I watch out for when adding or deleting several pages in a row
Reason: Every insert or delete shifts the indexes of all pages after it. Deleting several pages by fixed indexes from front to back easily removes the wrong ones — once one page is gone, the later indexes recorded earlier have already moved forward.
Solution: Insert, Add and RemoveAt each handle a single page, so repeat the call for batch operations. When deleting several pages, work from back to front so the indexes do not drift:
// Delete from back to front, so the indexes do not shift after each removal
for (let i = doc.Pages.Count - 1; i >= 3; i--) {
  doc.Pages.RemoveAt(i);
}
Get a Free License
If you wish to remove the evaluation message from the result document or remove feature limitations, please contact sales to obtain a temporary license valid for 30 days.
Draw Shapes in PDF Documents Using JavaScript in React
Adding shapes to PDF documents is a common requirement in many business scenarios: marking key areas with lines and boxes, adding a prominent border around content outside a table, distinguishing sections with filled color blocks, or overlaying pie and ellipse shapes on drawings and reports. Doing this by hand in a design tool each time is slow and hard to scale. With the drawing capabilities of Spire.PDF for JavaScript, you can write various shapes directly to PDF pages in the browser and let your code handle the annotation and diagramming work automatically.
Spire.PDF for JavaScript is based on WebAssembly and loads, edits, and saves PDF documents directly in the browser, managing input and output files through a virtual file system (VFS) without any backend service. The core object for drawing shapes on a PDF is the page drawing canvas PdfPage.Canvas: it provides methods such as DrawLine, DrawPie, DrawRectangle, and DrawEllipse.
This article covers four core features:
- Draw Lines on a PDF Page
- Draw a Pie on a PDF Page
- Draw a Rectangle on a PDF Page
- Draw an Ellipse on a PDF Page
For installation and project configuration, refer to How to Integrate Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Draw Lines on a PDF Page
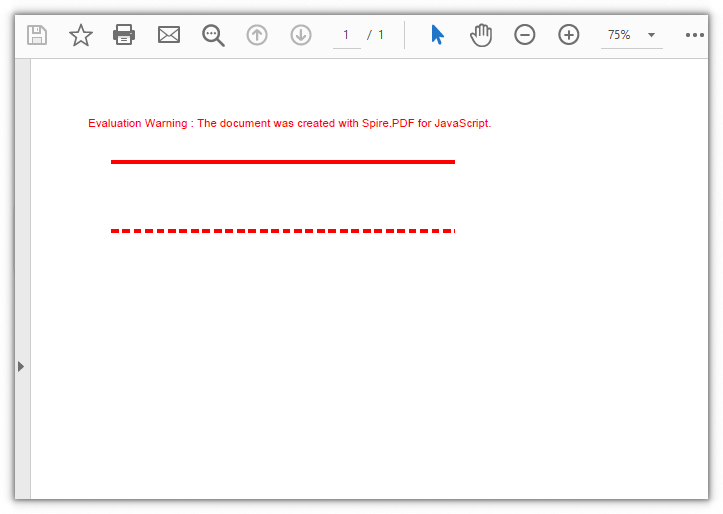
When drawing lines you can set the color and thickness, and choose between solid and dashed lines—the dash style is controlled by DashStyle and DashPattern.
function App() {
  const drawLines = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Create a PDF document and add a blank page
    let doc = new pdfModule.PdfDocument();
    let page = doc.Pages.Add();

    // Save the current graphics state
    let state = page.Canvas.Save();

    // Create a red pen for drawing lines
    let pen = new pdfModule.PdfPen({
      pdfRGBColor: new pdfModule.PdfRGBColor({ color: pdfModule.Color.get_Red() }),
      width: 2,
    });

    // Starting coordinates and length of the lines
    let x = 30.0;
    let y = 50.0;
    let width = 300.0;

    // Draw a solid line
    page.Canvas.DrawLine({ pen: pen, x1: x, y1: y, x2: x + width, y2: y });

    // Set the dash style and dash pattern
    pen.DashStyle = pdfModule.PdfDashStyle.Dash;
    pen.DashPattern = [3.0, 2.0];

    // Draw a dashed line
    page.Canvas.DrawLine({ pen: pen, x1: x, y1: y + 60.0, x2: x + width, y2: y + 60.0 });

    // Restore the graphics state
    page.Canvas.Restore({ state: state });

    // Define the output file name and save the document
    const outputFileName = 'DrawLines_result.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Draw Lines in PDF</h1>
      <button onClick={drawLines}>
        Draw
      </button>
    </div>
  );
}

export default App;
The result of drawing one solid line and one dashed line on a PDF page
Draw a Pie on a PDF Page
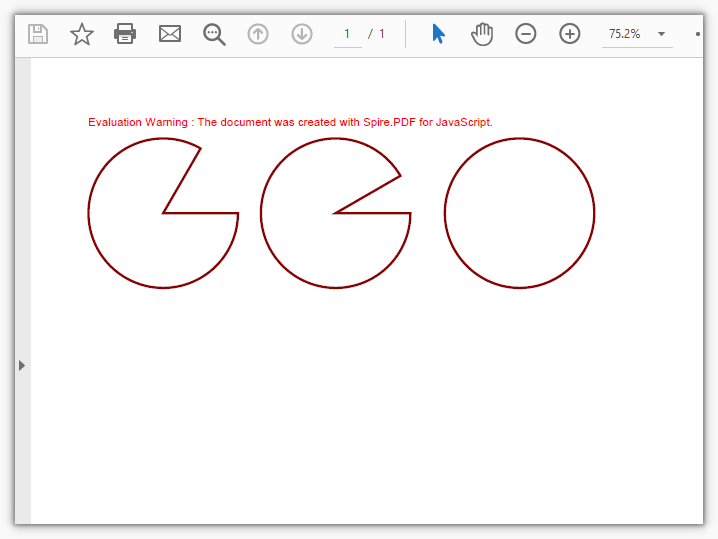
Pies express proportions: the bounding rectangle sets the position and size, while startAngle and sweepAngle set the opening angle of the sector.
function App() {
  const drawPie = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Create a PDF document and add a blank page
    let doc = new pdfModule.PdfDocument();
    let page = doc.Pages.Add();

    // Save the current graphics state
    let state = page.Canvas.Save();

    // Create a dark red pen
    let pen = new pdfModule.PdfPen({
      pdfRGBColor: new pdfModule.PdfRGBColor({ color: pdfModule.Color.get_DarkRed() }),
      width: 2,
    });

    // Draw the first pie
    page.Canvas.DrawPie({ pen: pen, x: 10.0, y: 30.0, width: 130.0, height: 130.0, startAngle: 360.0, sweepAngle: 300.0 });

    // Draw the second pie
    page.Canvas.DrawPie({ pen: pen, x: 160.0, y: 30.0, width: 130.0, height: 130.0, startAngle: 360.0, sweepAngle: 330.0 });

    // Draw the third pie
    page.Canvas.DrawPie({ pen: pen, x: 320.0, y: 30.0, width: 130.0, height: 130.0, startAngle: 360.0, sweepAngle: 360.0 });

    // Restore the graphics state
    page.Canvas.Restore({ state: state });

    // Define the output file name and save the document
    const outputFileName = 'DrawPie_result.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Draw a Pie in PDF</h1>
      <button onClick={drawPie}>
        Draw
      </button>
    </div>
  );
}

export default App;
The result of drawing three pies on a PDF page
Draw a Rectangle on a PDF Page
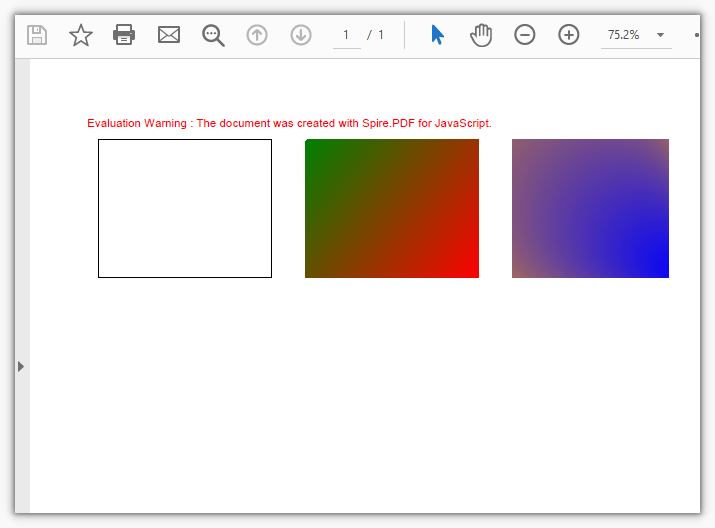
A rectangle can be drawn as an outline only, or filled. Besides a solid color (PdfSolidBrush), the fill also supports a linear gradient (PdfLinearGradientBrush) and a radial gradient (PdfRadialGradientBrush).
function App() {
  const drawRectangle = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Create a PDF document and add a blank page
    let doc = new pdfModule.PdfDocument();
    let page = doc.Pages.Add();

    // Save the current graphics state
    let state = page.Canvas.Save();

    // Create a black pen
    let pen = new pdfModule.PdfPen({
      pdfRGBColor: new pdfModule.PdfRGBColor({ color: pdfModule.Color.get_Black() }),
      width: 1,
    });

    // Draw a rectangle outline with the pen
    page.Canvas.DrawRectangle({
      pen: pen,
      rectangle: new pdfModule.RectangleF({
        location: new pdfModule.PointF(20.0, 30.0),
        size: new pdfModule.SizeF({ width: 150.0, height: 120.0 }),
      }),
    });

    // Create a linear gradient brush
    let linearGradientBrush = new pdfModule.PdfLinearGradientBrush({
      point1: new pdfModule.PointF(200.0, 30.0),
      point2: new pdfModule.PointF(350.0, 150.0),
      color1: new pdfModule.PdfRGBColor({ color: pdfModule.Color.get_Green() }),
      color2: new pdfModule.PdfRGBColor({ color: pdfModule.Color.get_Red() }),
    });

    // Draw a filled rectangle with the linear gradient brush
    page.Canvas.DrawRectangle({
      brush: linearGradientBrush,
      rectangle: new pdfModule.RectangleF({
        location: new pdfModule.PointF(200.0, 30.0),
        size: new pdfModule.SizeF({ width: 150.0, height: 120.0 }),
      }),
    });

    // Create a radial gradient brush
    let radialGradientBrush = new pdfModule.PdfRadialGradientBrush({
      centreStart: new pdfModule.PointF(380.0, 30.0),
      radiusStart: 150.0,
      centreEnd: new pdfModule.PointF(530.0, 150.0),
      radiusEnd: 150.0,
      colorStart: new pdfModule.PdfRGBColor({ color: pdfModule.Color.get_Orange() }),
      colorEnd: new pdfModule.PdfRGBColor({ color: pdfModule.Color.get_Blue() }),
    });

    // Draw a filled rectangle with the radial gradient brush
    page.Canvas.DrawRectangle({
      brush: radialGradientBrush,
      rectangle: new pdfModule.RectangleF({
        location: new pdfModule.PointF(380.0, 30.0),
        size: new pdfModule.SizeF({ width: 150.0, height: 120.0 }),
      }),
    });

    // Restore the graphics state
    page.Canvas.Restore({ state: state });

    // Define the output file name and save the document
    const outputFileName = 'DrawRectangle_result.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Draw a Rectangle in PDF</h1>
      <button onClick={drawRectangle}>
        Draw
      </button>
    </div>
  );
}

export default App;
The result of drawing a rectangle outline and gradient-filled rectangles on a PDF page
Draw an Ellipse on a PDF Page
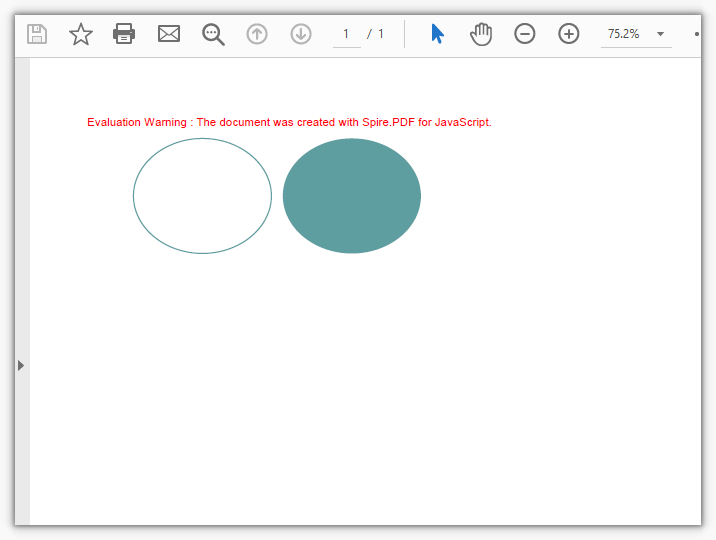
An ellipse likewise supports outlines and fills: use PdfPen for the outline and PdfSolidBrush for the fill, or take one of the preset pens from PdfPens.
function App() {
  const drawEllipse = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Create a PDF document and add a blank page
    let doc = new pdfModule.PdfDocument();
    let page = doc.Pages.Add();

    // Save the current graphics state
    let state = page.Canvas.Save();

    // Create a CadetBlue pen
    let pen = pdfModule.PdfPens.get_CadetBlue();

    // Draw the ellipse outline
    page.Canvas.DrawEllipse({ pen: pen, x: 50.0, y: 30.0, width: 120.0, height: 100.0 });

    // Create a fill brush
    let brush = new pdfModule.PdfSolidBrush({
      pdfRGBColor: new pdfModule.PdfRGBColor({ color: pdfModule.Color.get_CadetBlue() }),
    });

    // Draw the filled ellipse
    page.Canvas.DrawEllipse({ brush: brush, x: 180.0, y: 30.0, width: 120.0, height: 100.0 });

    // Restore the graphics state
    page.Canvas.Restore({ state: state });

    // Define the output file name and save the document
    const outputFileName = 'DrawEllipse_result.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Draw an Ellipse in PDF</h1>
      <button onClick={drawEllipse}>
        Draw
      </button>
    </div>
  );
}

export default App;
The result of drawing an ellipse outline and a filled ellipse on a PDF page
FAQ
Why does the drawn shape appear at the edge of the page or outside the visible area
Cause: The coordinates used by DrawLine, DrawPie, DrawRectangle, and DrawEllipse have their origin at the bottom-left corner of the page, with the x-axis pointing right and the y-axis pointing up, in units of points. If you copy screen coordinates directly (where the origin is at the top-left), the drawn shape will end up in the opposite position or outside the page.
Solution: Convert the coordinates using the bottom-left corner of the page as the origin. You can read the page size first and then lay out the shape, for example by using PdfPage.Size to get the page width and height and calculating the shape's position from them:
// Get the page size and calculate coordinates with the bottom-left corner as the origin
let size = page.Size;
let x = size.Width / 4;
let y = size.Height / 3;
page.Canvas.DrawRectangle({ pen: pen, x: x, y: y, width: 200, height: 120 });
Why does the existing content on the page shift after drawing
Cause: Drawing modifies the canvas's current transform and graphics state. If you change the coordinate system with ScaleTransform, TranslateTransform, and similar methods before drawing, or fail to restore the state afterward, subsequent content will be affected.
Solution: Use Canvas.Save and Canvas.Restore in pairs, wrapping the drawing operations between them, to make sure the canvas state is restored to its previous level once drawing is complete:
// Save the state before drawing
let state = page.Canvas.Save();
// ... perform drawing ...
// Restore the state after drawing
page.Canvas.Restore({ state: state });
Why can't I see the drawn shape in the saved PDF
Cause: Shapes are drawn onto the canvas object. If you do not call doc.SaveToFile to write the document back to a file after drawing, or if the output file and the file read for download are not the same name, you will still see the original content.
Solution: Make sure you call doc.SaveToFile(outputFileName) to save after drawing, and read and download from the virtual file system using the same outputFileName:
// Save the document to the specified file name
doc.SaveToFile(outputFileName);
doc.Close();

// Read from the VFS using the same file name to trigger a download
const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
Get a Free License
If you want to remove the evaluation message from the result documents or get rid of the feature limitations, please contact our sales team to obtain a temporary license valid for 30 days.
Extracting PDF Bookmarks in React with JavaScript
A bookmark in a PDF records the document's outline structure, and a bookmark can hold child bookmarks of its own, nesting level by level into a tree. Reading that information has plenty of practical uses — exporting it as a table of contents, generating site navigation from bookmark titles, or locating a specific page for further processing. All of it calls for a program that can walk the whole bookmark tree and pull out the content of each node.
Spire.PDF for JavaScript processes PDF documents directly in the browser based on WebAssembly, managing input and output files through a virtual file system (VFS), with no backend service required. The core entry point for extracting bookmarks is the PdfDocument.Bookmarks property, which returns a PdfBookmarkCollection; each PdfBookmark object in it exposes its own child bookmark collection, so together they form the complete bookmark tree. Every bookmark node provides properties such as Title and DisplayStyle for reading its appearance, and Destination.Page combined with PdfPageCollection.IndexOf gives you the page number the bookmark points to.
This article covers two core features:
For installation and project configuration, refer to Integrating Spire.PDF for JavaScript in a React Project. The following examples assume Spire.PDF is installed and the WebAssembly module has been initialized.
Extracting All PDF Bookmarks
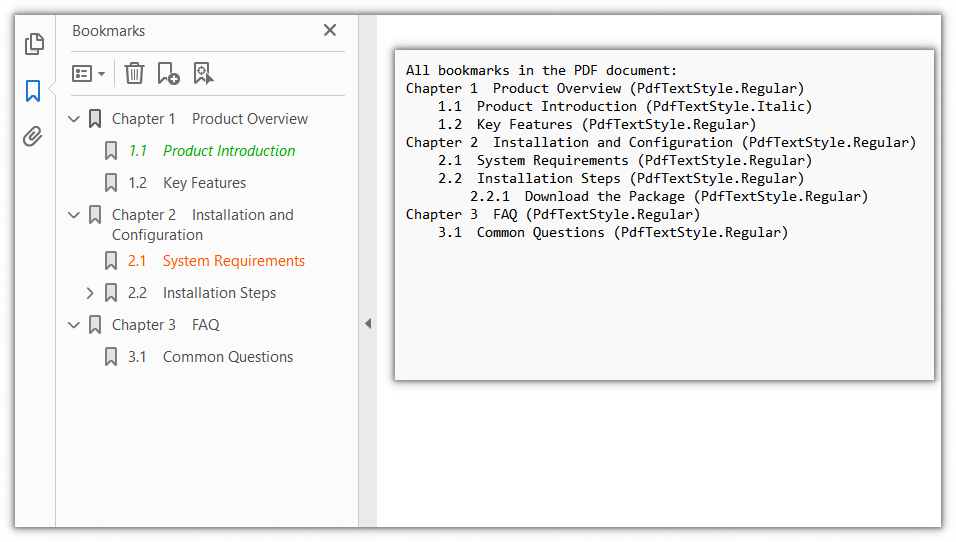
PdfDocument.Bookmarks returns only the top-level bookmark collection, while bookmarks themselves can contain child bookmarks. To read out every bookmark in the document you need a recursive function that walks the PdfBookmarkCollection level by level, reads the Title (bookmark title) and DisplayStyle (text style) of each node, and records them with indentation by level, producing a complete outline list in the end.
function App() {
  const extractAllBookmarks = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be processed into the VFS
    const inputFileName = 'Sample.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // String that holds the extracted result
    let content = 'All bookmarks in the PDF document:\r\n';

    // Recursively traverse the bookmark collection, recording each title and text style with indentation by level
    const collectBookmarks = (bookmarks, indent) => {
      for (let i = 0; i < bookmarks.Count; i++) {
        let bookmark = bookmarks.get_Item(i);

        // Record the title and text style of the current bookmark
        content += indent + bookmark.Title + ' (' + bookmark.DisplayStyle.toString() + ')\r\n';

        // If there are child bookmarks, process them recursively with more indentation
        if (bookmark.Count > 0) {
          collectBookmarks(bookmark, indent + '    ');
        }
      }
    };

    // Start extracting from the top-level bookmarks
    collectBookmarks(doc.Bookmarks, '');

    // Write the extracted result to a file and trigger the download
    const outputFileName = 'AllBookmarks.txt';
    window.dotnetRuntime.Module.FS.writeFile(outputFileName, content);
    doc.Close();

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'text/plain' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Extract All PDF Bookmarks</h1>
      <button onClick={extractAllBookmarks}>
        Start Extracting
      </button>
    </div>
  );
}

export default App;
The list of all bookmark titles and text styles extracted recursively
Getting the Page Number of a Bookmark
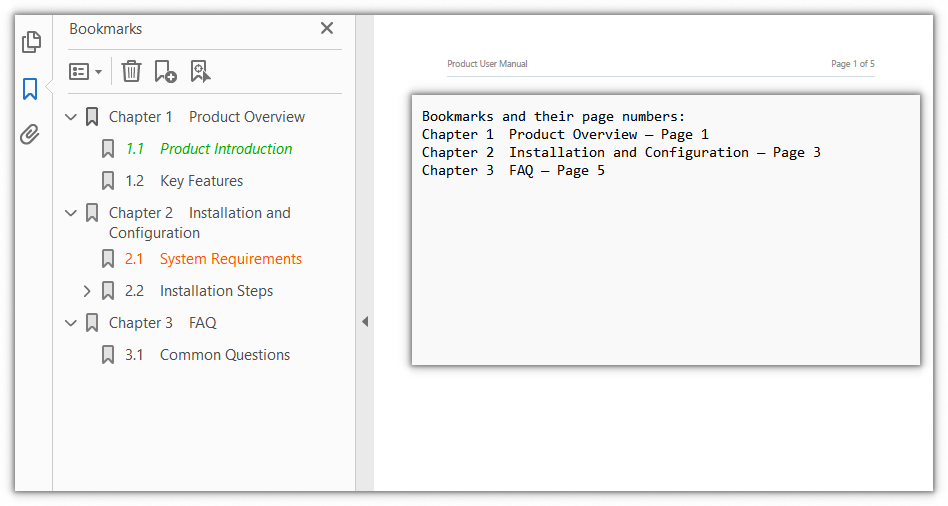
Besides its title, a bookmark also carries a jump destination. Through PdfBookmark.Destination.Page you can obtain the PdfPage object the bookmark points to, and then use PdfPageCollection.IndexOf to get its index within the document. Because the index starts from 0, adding 1 gives the page number shown in a reader. This is commonly used to export a bookmark list as a "title — page number" table of contents.
function App() {
  const getBookmarkPageNumber = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be processed into the VFS
    const inputFileName = 'Sample.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Read the page number each top-level bookmark points to, one by one
    let content = 'Bookmarks and their page numbers:\r\n';
    for (let i = 0; i < doc.Bookmarks.Count; i++) {
      let bookmark = doc.Bookmarks.get_Item(i);

      // Destination.Page gives the page the bookmark points to; IndexOf returns its 0-based index
      let pageNumber = doc.Pages.IndexOf(bookmark.Destination.Page) + 1;

      content += bookmark.Title + ' — Page ' + pageNumber + '\r\n';
    }

    // Write the extracted result to a file and trigger the download
    const outputFileName = 'BookmarkPageNumber.txt';
    window.dotnetRuntime.Module.FS.writeFile(outputFileName, content);
    doc.Close();

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'text/plain' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Get the Page Number of a Bookmark</h1>
      <button onClick={getBookmarkPageNumber}>
        Start Extracting
      </button>
    </div>
  );
}

export default App;
The title of each bookmark and the page number it points to
FAQ
Why is the number of extracted bookmarks smaller than the outline shown in a reader
Reason: doc.Bookmarks returns only the top-level bookmark collection, and its Count counts only the nodes at that level. Child bookmarks nested under a chapter are reached through the node's own collection and are otherwise not counted.
Solution: Traverse the whole bookmark tree recursively and add up the nodes at every level:
function countBookmarks(bookmarks) {
  let total = 0;
  for (let i = 0; i < bookmarks.Count; i++) {
    total += 1;
    // Recursively add the child bookmarks
    total += countBookmarks(bookmarks.get_Item(i));
  }
  return total;
}

const total = countBookmarks(doc.Bookmarks);
Why is the extracted DisplayStyle always Regular
Reason: PdfBookmark.DisplayStyle returns the text style a bookmark is displayed with in the outline panel. Only when the bookmark itself is explicitly set to a style such as Bold or Italic will the value read back differ from the default Regular. It reflects the bookmark's appearance setting, not the font used by the bookmark title in the page content.
Solution: Record the enum value as it is; if you only need to tell whether it is bold or italic, compare it against the PdfTextStyle values one by one:
let style = 'Regular';
if (bookmark.DisplayStyle === pdfModule.PdfTextStyle.Bold) {
  style = 'Bold';
} else if (bookmark.DisplayStyle === pdfModule.PdfTextStyle.Italic) {
  style = 'Italic';
}
Why does the page number from Destination.Page differ from the one shown in a reader
Reason: PdfPageCollection.IndexOf returns the page's index within the collection, counting from 0, while a reader shows page numbers from 1, so using the index directly is off by one.
Solution: Add 1 to the index to match what the reader shows:
// The index is 0-based, so add 1 to get the page number shown in a reader
let pageNumber = doc.Pages.IndexOf(bookmark.Destination.Page) + 1;
In addition, if a bookmark points to a page that no longer exists (for example, the target page was deleted), Destination may be empty, so check for null before reading it:
if (bookmark.Destination && bookmark.Destination.Page) {
  let pageNumber = doc.Pages.IndexOf(bookmark.Destination.Page) + 1;
}
Get a Free License
If you wish to remove the evaluation message from the result document or remove feature limitations, please contact sales to obtain a temporary license valid for 30 days.
How to Reconstruct Word Structure with Spire.Agent.Office in C#
Editing content in Word is not difficult, but realigning the table of contents, page numbers, headers and footers afterwards is often more troublesome. As soon as a document goes through a few rounds of additions and deletions, chapter order adjustments, or migration from another template, its original table of contents entries, page numbers, and the chapter name in the header easily fall out of sync with the body text — clicking a TOC entry jumps to the wrong page, page numbers fail to continue from a certain section onward, and the header still carries the chapter title from the previous version. Checking item by item by hand is time-consuming and prone to omissions, and the longer the document, the harder it is to guarantee consistency.
Comparison with Traditional SDK API Processing
| Traditional Spire.Office for .NET API | Spire.Agent.Office | |
|---|---|---|
| Driving approach | Write code to handle each item: iterate paragraphs to determine levels → update the TOC field → reorder page numbers → modify headers and footers; every step requires code control | Describe in natural language which structures to reconstruct, and AI completes it automatically |
| Code volume | The TOC field, sectioned page numbers, header fields and so on each require a separate set of processing logic | Only configuration code + 1 natural language instruction |
| Heading level recognition | Relies on rigid judgment by style name or outline level, which is easily misjudged when styles are not standardized | AI determines heading levels by combining semantics and styles |
| Section and field handling | Section breaks, page number start values, and fields such as PAGE/STYLEREF must each be set manually | Automatically identifies sections and field reference relationships and updates them as a group |
| Maintainability | After the document template or structure changes, the code must be modified and a new version released | The reconstruction scope and rules can be adjusted at any time in natural language |
This article explains how to use the Word AI capability of Spire.Agent.Office to complete document structure reconstruction, covering two typical categories of problems, from the table of contents to page numbers, headers and footers: first let AI scan the heading levels and section information and regenerate the table of contents according to the actual headings in the body, then refresh page numbers and update the dynamic fields in headers and footers, keeping the table of contents, page numbers, headers and footers consistent with the body text.
For product installation and SpireToken configuration, refer to Integrating Spire.Agent.Office in a .NET Project. The examples below assume Spire.Agent.Office is installed and SpireToken is configured.
Table of Contents Structure Reconstruction
A table of contents that no longer matches is usually because the TOC was not updated after the body text was modified, or because the original TOC was static text typed by hand. The core idea of structure reconstruction is: load the existing document, let AI scan the headings at each level in the body, determine the hierarchical relationships and check the section positions, and regenerate a table of contents field with page numbers according to the actual headings in the body, making the TOC entries and levels correspond one-to-one with the body text, while only adjusting heading styles and not touching the body content.
using Spire.Agent.Office.AI;
using Spire.Agent.Office.Extensions;
using Spire.Doc;

// The document whose structure is to be reconstructed
string inputPath = "E:\\Input\\XX_Project_Implementation_Plan.docx";
// Save path
string savePath = "E:\\Output\\XX_Project_Implementation_Plan-Reconstructed.docx";
// SpireToken Key
string key = "**********************";
// Natural language instruction
string instruction =
    "Please reconstruct the table of contents structure of the current document: " +
    "1. Scan the headings in the body, identify the hierarchical relationships of the headings at each level, and unify the heading styles (use Heading 1 for level-1 headings, Heading 2 for level-2 headings, and so on); " +
    "2. Check the positions of the section breaks to ensure the chapter divisions are consistent with the heading levels; " +
    "3. Delete the original table of contents and regenerate a table of contents field before the body, containing headings at each level with their corresponding page numbers, fully consistent with the actual headings and levels in the body; " +
    "4. Only adjust the heading styles and the table of contents, and keep the body content unchanged. " +
    "Finally save and output in DOCX format";

// Call the Word document processing function
AIResult result = ExecuteDemoWord(instruction, inputPath, savePath, key, null);

// Execute Word document AI processing
static AIResult ExecuteDemoWord(string instruction, string inputPath, string savePath, string key, string[] attachmentPaths)
{
    // Create an AIOptions configuration object
    AIOptions options = new AIOptions();
    // Set the SpireToken Key
    options.SpireToken = key;

    // Use the Document object to process the Word document
    using (Document doc = new Document())
    {
        // Load the document whose structure is to be reconstructed
        if (!string.IsNullOrEmpty(inputPath) && File.Exists(inputPath))
        {
            doc.LoadFromFile(inputPath);
        }
        // Create the AI document processor
        AIDocumentProcessor processor = doc.AI(options);

        // Execute the AI instruction
        return processor.ExecuteInstruction(doc, instruction, savePath, attachmentPaths);
    }
}
Reconstructed table of contents
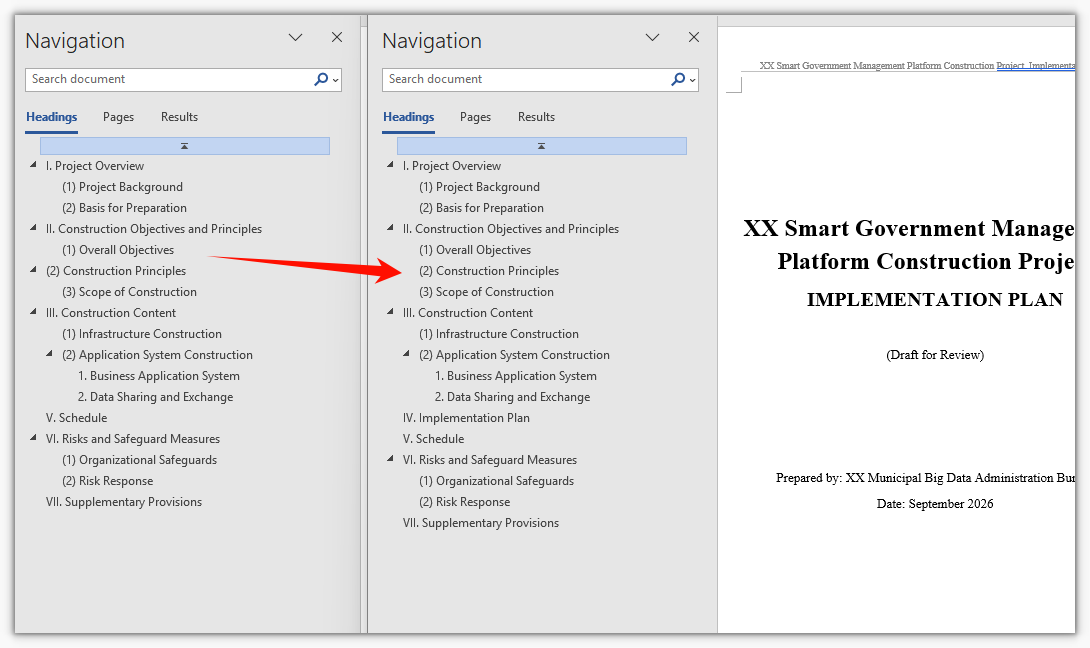
After reconstruction, the TOC entries and levels correspond one-to-one with the body headings, and clicking an entry jumps to the correct position, with no more entries pointing to old chapters or missing. For documents with major structural changes, regenerating the TOC directly is more convenient than manually adding and deleting TOC entries, and far less likely to miss a change.
Page Number, Header and Footer Refresh
After the TOC is reconstructed, the page numbers, headers and footers also need to be realigned. Page number misalignment usually comes from the section settings, and the chapter name or total page count in the header shows the old value of the field. The core idea of this step is: let AI refresh the page numbers of the whole document and set the start value and continuation method according to sections, and at the same time update the dynamic fields in the headers and footers (such as chapter name, total page count, and date) so that the values of these fields match the current content of the body.
using Spire.Agent.Office.AI;
using Spire.Agent.Office.Extensions;
using Spire.Doc;

// The document whose page numbers are to be refreshed (can follow the reconstructed document from the previous section)
string inputPath = "E:\\Input\\XX_Project_Implementation_Plan-Reconstructed.docx";
// Save path
string savePath = "E:\\Output\\XX_Project_Implementation_Plan-Final.docx";
// SpireToken Key
string key = "**********************";
// Natural language instruction
string instruction =
    "Please refresh the page numbers of the current document and update the dynamic fields in the headers and footers: " +
    "1. Recalculate and refresh the page numbers of the whole document, with the body page numbers numbered consecutively starting from page 1; " +
    "2. Set page numbers by section, do not number the cover page and the table of contents, and start the body on a separate page with restarted numbering; " +
    "3. Update the dynamic fields such as the chapter name in the header (taken from the heading at the corresponding level) and the total page count, so that they match the current content of the body; " +
    "4. Unify the footer page number format as \"Page X of Y\". " +
    "Only update the above structural information, do not modify the body content, and finally save and output in DOCX format";

// Call the Word document processing function
AIResult result = ExecuteDemoWord(instruction, inputPath, savePath, key, null);

// Execute Word document AI processing
static AIResult ExecuteDemoWord(string instruction, string inputPath, string savePath, string key, string[] attachmentPaths)
{
    // Create an AIOptions configuration object
    AIOptions options = new AIOptions();
    // Set the SpireToken Key
    options.SpireToken = key;

    // Use the Document object to process the Word document
    using (Document doc = new Document())
    {
        // Load the document whose page numbers are to be refreshed
        if (!string.IsNullOrEmpty(inputPath) && File.Exists(inputPath))
        {
            doc.LoadFromFile(inputPath);
        }
        // Create the AI document processor
        AIDocumentProcessor processor = doc.AI(options);

        // Execute the AI instruction
        return processor.ExecuteInstruction(doc, instruction, savePath, attachmentPaths);
    }
}
Document after refreshing the page numbers, headers and footers
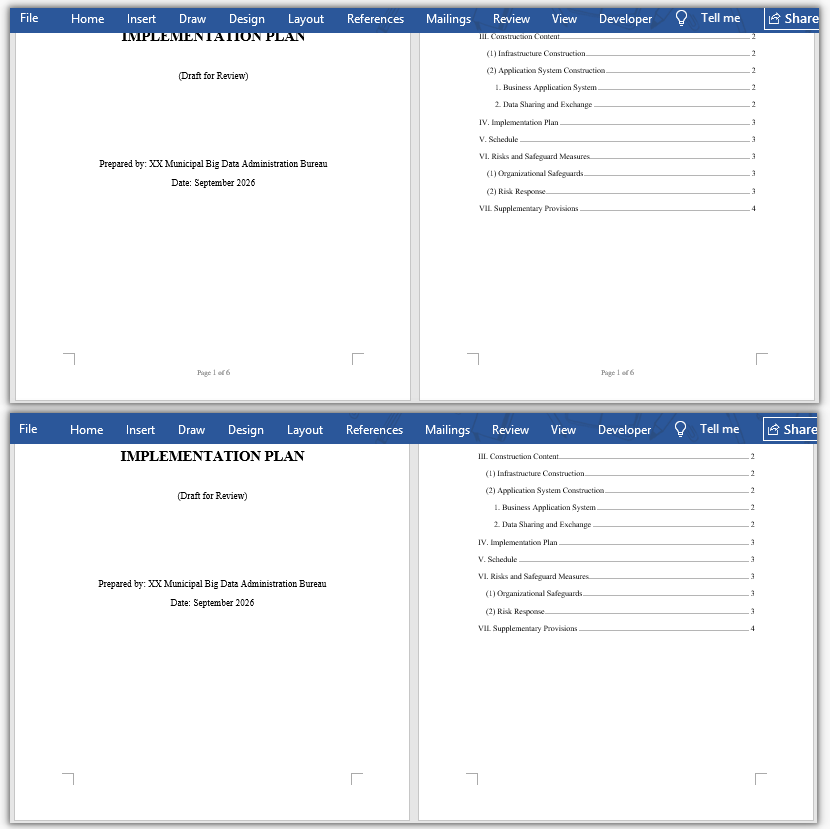
After refreshing, the body page numbers are consecutive, the section start values are correct, and the chapter name and total page count in the header stay consistent with the body. For documents processed in batches, the same set of instructions can be used to unify the page number rules and the header and footer formats, saving the time of opening each document and checking each item.
FAQ
The reconstructed table of contents still shows old entries or gains extra items
Reason: The original document's table of contents is static text rather than a TOC field, or the heading styles are not unified, causing deviations in the recognized levels.
Solution: In the instruction, explicitly require "delete the original table of contents and regenerate a table of contents field according to the body headings", and state the basis for recognizing headings (by style name or outline level) to reduce misjudgment.
Page numbers do not match starting from a certain section or repeat
Reason: The page number start value and continuation method of the section breaks do not meet the requirements, and it is easy to miss a section when setting them manually.
Solution: Write out the page number requirements of each section one by one in the instruction, such as "do not number the cover page and the table of contents, start the body from page 1, and number each section consecutively", and let AI set them uniformly by section.
The chapter name or total page count in the header does not change
Reason: The chapter name and total page count are mostly dynamic fields such as STYLEREF and NUMPAGES, and still show cached values when not refreshed.
Solution: Require "update the values of all dynamic fields in the headers and footers", and explain the source of the fields, such as the chapter name taken from the heading at the corresponding level and the total page count taken from the whole document.
The body formatting is changed along with the structure reconstruction
Reason: The operation scope was not limited, and AI adjusted the fonts and paragraph formats of the body while unifying the heading styles.
Solution: In the instruction, clearly state "only adjust structural information such as heading styles, the table of contents, page numbers, headers and footers, and keep the body fonts and paragraph formats unchanged".
Get the SpireToken Key
- Contact [email protected] or visit https://www.e-iceblue.com/TemLicense.html to obtain a trial/commercial API key
Configure it in your code:
AIOptions options = new AIOptions();
options.SpireToken = key;
Expanding or Collapsing PDF Bookmarks in React with JavaScript
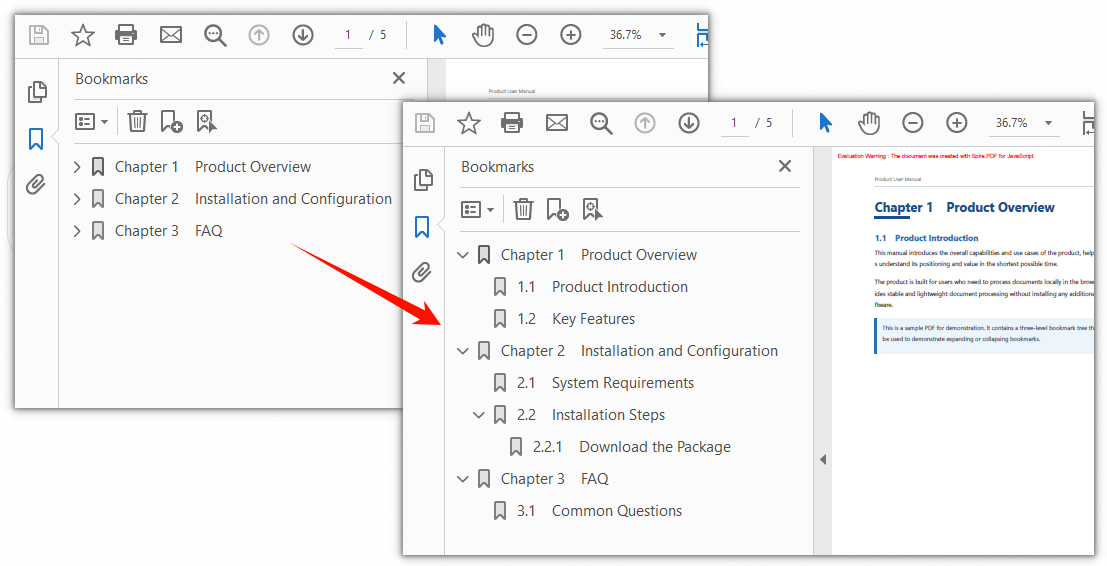
Bookmarks in a PDF document organize the document outline as a tree, and they are a core tool for quickly navigating long documents. When a document contains multi-level bookmarks, the default expanded or collapsed state directly affects the outline a reader sees when opening the document. With Spire.PDF for JavaScript, you can reset the expanded and collapsed state of bookmarks in a React application so that the document opens with exactly the outline levels you need.
Spire.PDF for JavaScript processes PDF documents directly in the browser based on WebAssembly, managing input and output files through a virtual file system (VFS), with no backend service required. The key to controlling whether a bookmark is expanded or collapsed is the ExpandBookmark property of the bookmark object: set it to true to expand the node and its child bookmarks, or false to collapse and hide its children. For multi-level bookmarks, you can recursively traverse the PdfBookmarkCollection to set them all at once, or locate a specific node by index to control it individually.
This article covers two core features:
For installation and project configuration, refer to Integrating Spire.PDF for JavaScript in a React Project. The following examples assume Spire.PDF is installed and the WebAssembly module has been initialized.
Expanding All PDF Bookmarks
Spire.PDF for JavaScript can retrieve the bookmark collection of a document through PdfDocument.Bookmarks. Because bookmarks support multiple nesting levels, you need a recursive function that traverses the PdfBookmarkCollection: recursively process the child bookmarks first, then set the ExpandBookmark property of the current node to true, so that every level of bookmarks is fully expanded when the document is opened.
function App() {
  const expandAllBookmarks = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be processed into the VFS
    const inputFileName = 'Sample.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Recursively traverse the bookmark collection and expand all levels
    function expandBookmarks(collection, expand) {
      // Stop the recursion when the collection is empty
      if (collection.Count === 0) {
        return;
      }

      for (let i = 0; i < collection.Count; i++) {
        let bookmark = collection.get_Item(i);

        // Process the child bookmarks first
        expandBookmarks(bookmark, expand);

        // Then set the expanded state of the current bookmark
        bookmark.ExpandBookmark = expand;
      }
    }

    // Expand all bookmarks in the document
    expandBookmarks(doc.Bookmarks, true);

    // Save the document and trigger the download
    const outputFileName = "ExpandAllBookmarks.pdf";
    doc.SaveToFile(outputFileName);
    doc.Close();

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: "application/pdf" });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Expand All PDF Bookmarks</h1>
      <button onClick={expandAllBookmarks}>
        Start Expanding
      </button>
    </div>
  );
}

export default App;
The document after recursively expanding the bookmarks at every level
Expanding or Collapsing Specific PDF Bookmarks
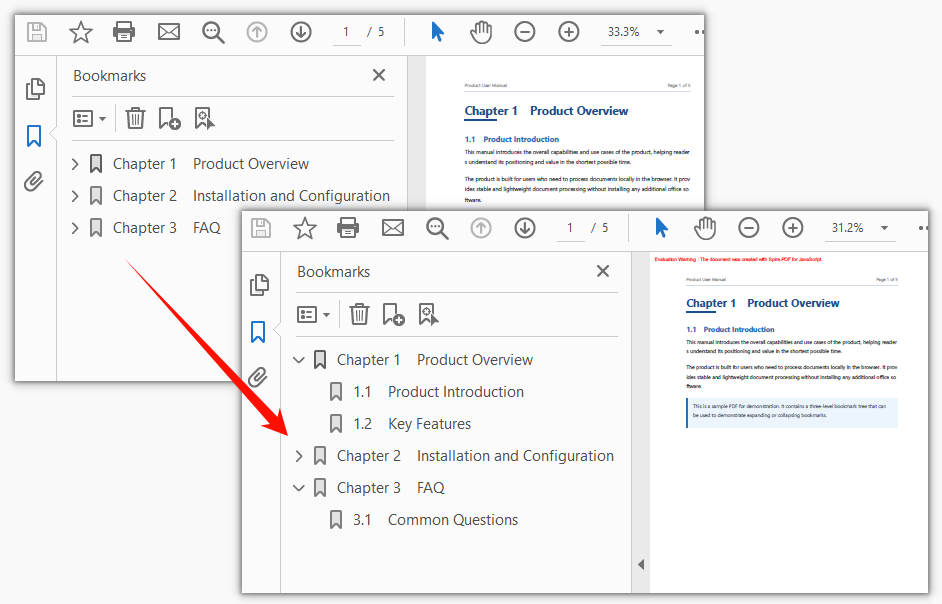
If you only need to control a few bookmark nodes, you can use PdfBookmarkCollection.get_Item to locate the target bookmark by index, and then set its ExpandBookmark property individually. Setting the ExpandBookmark of a node to true expands the child bookmarks under it, while setting it to false collapses them, which gives you precise control over a partially expanded, partially collapsed outline.
function App() {
  const toggleSpecificBookmarks = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be processed into the VFS
    const inputFileName = 'Sample.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Expand the first bookmark (Chapter 1); its child bookmarks are shown as well
    doc.Bookmarks.get_Item(0).ExpandBookmark = true;

    // Collapse the second bookmark (Chapter 2); its child bookmarks are hidden
    doc.Bookmarks.get_Item(1).ExpandBookmark = false;

    // Expand the third bookmark (Chapter 3)
    doc.Bookmarks.get_Item(2).ExpandBookmark = true;

    // Save the document and trigger the download
    const outputFileName = "ToggleSpecificBookmarks.pdf";
    doc.SaveToFile(outputFileName);
    doc.Close();

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: "application/pdf" });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Expand or Collapse Specific PDF Bookmarks</h1>
      <button onClick={toggleSpecificBookmarks}>
        Start Processing
      </button>
    </div>
  );
}

export default App;
The document after expanding or collapsing the specified bookmarks by index
FAQ
Why do child bookmarks still not appear after setting ExpandBookmark
Reason: ExpandBookmark controls whether the child bookmarks of that node are shown. If the parent node of a bookmark is collapsed, then the bookmark itself will not be displayed no matter how its own ExpandBookmark is set, because its parent is collapsed.
Solution: Expand level by level starting from the root node, or simply set ExpandBookmark to true for the entire bookmark tree with a recursive function:
function expandBookmarks(collection) {
  for (let i = 0; i < collection.Count; i++) {
    let bookmark = collection.get_Item(i);
    bookmark.ExpandBookmark = true;
    expandBookmarks(bookmark);
  }
}

expandBookmarks(doc.Bookmarks);
How to expand only one level of a multi-level bookmark
Reason: Bookmarks form a tree structure, and each node of a PdfBookmarkCollection also exposes its child collection through get_Item, so you need to locate the target level by descending one level at a time.
Solution: Locate the parent node of the target level first, then set the ExpandBookmark of that node. For example, to expand only the first child bookmark under Chapter 2:
// Get the second bookmark (Chapter 2)
let chapterTwo = doc.Bookmarks.get_Item(1);

// Get the first child bookmark under that chapter
let sectionOne = chapterTwo.get_Item(0);

// Expand that child bookmark
sectionOne.ExpandBookmark = true;
Where is the expanded or collapsed state of ExpandBookmark stored
Reason: The expanded or collapsed state of a bookmark is written into the outline (Outlines) structure of the PDF along with the bookmark itself. It is part of the document content, not a temporary setting of the viewer.
Solution: After setting and saving, any viewer that supports the standard PDF outline (such as the bookmark panel of Adobe Acrobat, Edge or the built-in Chrome viewer) will display the state as it was saved. To restore a fully collapsed outline, simply set the ExpandBookmark of the corresponding nodes to false and save again:
// Collapse the first bookmark
doc.Bookmarks.get_Item(0).ExpandBookmark = false;
doc.SaveToFile(outputFileName);
Get a Free License
If you wish to remove the evaluation message from the result document or remove feature limitations, please contact sales to obtain a temporary license valid for 30 days.
Adding, Editing, or Deleting PDF Bookmarks in React with JavaScript
Bookmarks in PDF documents are essential tools for navigating document content, especially for long documents where bookmarks help readers quickly locate target sections. With Spire.PDF for JavaScript's bookmark management capabilities, you can directly add multi-level bookmarks, modify existing bookmark titles and styles, or delete unwanted bookmarks in React applications, all completed in the browser via WebAssembly without relying on backend services.
Spire.PDF for JavaScript processes PDF documents directly in the browser based on WebAssembly, managing input and output files through a virtual file system (VFS).
This article covers three core features:
For installation and project configuration, refer to Integrating Spire.PDF for JavaScript in a React Project. The following examples assume Spire.PDF is installed and the WebAssembly module has been initialized.
Adding PDF Bookmarks
Spire.PDF for JavaScript allows you to batch add multi-level bookmarks to existing PDF documents. By iterating through the PdfDocument.Pages collection, you can create parent and child bookmarks for each page, use PdfDestination to specify the jump target page and position, and add child bookmarks via PdfBookmarkCollection.Add to form a hierarchical structure.
function App() {
  const addPdfBookmarks = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be processed into VFS
    const inputFileName = 'Sample.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Iterate through each page of the PDF, adding parent and child bookmarks for each page
    for (let i = 0; i < doc.Pages.Count; i++) {
      let page = doc.Pages.get_Item(i);

      // Set the parent bookmark title and target position
      let bookmarkTitle = "Bookmark-" + (i + 1);
      let bookmarkDest = new pdfModule.PdfDestination({ page: page, location: new pdfModule.PointF(0, 0) });

      // Create and configure the parent bookmark
      let bookmark = doc.Bookmarks.Add(bookmarkTitle);
      bookmark.Color = new pdfModule.PdfRGBColor({ color: pdfModule.Color.get_SaddleBrown() });
      bookmark.DisplayStyle = pdfModule.PdfTextStyle.Bold;
      bookmark.Action = new pdfModule.PdfGoToAction({ destination: bookmarkDest });

      // Set the child bookmark title and target position
      let childBookmarkTitle = "Sub-Bookmark-" + (i + 1);
      let childBookmarkDest = new pdfModule.PdfDestination({ page: page, location: new pdfModule.PointF(0, 100) });

      // Create child bookmark via PdfBookmarkCollection.Add of the parent bookmark
      let childBookmark = bookmark.Add(childBookmarkTitle);
      childBookmark.Color = new pdfModule.PdfRGBColor({ color: pdfModule.Color.get_Coral() });
      childBookmark.DisplayStyle = pdfModule.PdfTextStyle.Italic;
      childBookmark.Action = new pdfModule.PdfGoToAction({ destination: childBookmarkDest });
    }

    // Save the document and trigger download
    const outputFileName = "AddBookmark.pdf";
    doc.SaveToFile(outputFileName);
    doc.Close();

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: "application/pdf" });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add PDF Bookmarks</h1>
      <button onClick={addPdfBookmarks}>
        Start Adding
      </button>
    </div>
  );
}

export default App;
Document after batch adding multi-level bookmarks by iterating through PDF pages

Editing PDF Bookmarks
For existing PDF documents, you can load them and edit the bookmarks within. Use PdfDocument.Bookmarks.get_Item to retrieve a bookmark node at a specified index, then modify its Title, Color, and DisplayStyle properties. Bookmarks support hierarchical structure, and you can recursively traverse and edit all child bookmark nodes.
function App() {
  const editPdfBookmarks = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be processed into VFS
    const inputFileName = 'AddBookmark.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Function to recursively edit child bookmarks
    function editChildBookmarks(parentBookmark) {
      for (let i = 0; i < parentBookmark.Count; i++) {
        let childBookmark = parentBookmark.get_Item(i);
        childBookmark.Color = new pdfModule.PdfRGBColor({ color: pdfModule.Color.get_Blue() });
        childBookmark.DisplayStyle = pdfModule.PdfTextStyle.Regular;
        editChildBookmarks(childBookmark);
      }
    }

    // Get the first bookmark and modify its properties
    let bookmark = doc.Bookmarks.get_Item(0);
    bookmark.Title = "Modified Bookmark";
    bookmark.Color = new pdfModule.PdfRGBColor({ color: pdfModule.Color.get_Black() });
    bookmark.DisplayStyle = pdfModule.PdfTextStyle.Bold;

    // Recursively edit all child bookmarks
    editChildBookmarks(bookmark);

    // Save the document and trigger download
    const outputFileName = "EditBookmark.pdf";
    doc.SaveToFile(outputFileName);
    doc.Close();

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: "application/pdf" });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Edit PDF Bookmarks</h1>
      <button onClick={editPdfBookmarks}>
        Start Editing
      </button>
    </div>
  );
}

export default App;
Document effect after editing PDF bookmarks

Deleting PDF Bookmarks
To remove unwanted bookmarks from a PDF document, you can use the PdfDocument.Bookmarks.RemoveAt method to remove a specified bookmark by index. If you need to delete all bookmarks, you can iterate through the collection and delete them one by one, or use RemoveAt(0) in a loop until the collection is empty.
function App() {
  const deletePdfBookmarks = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be processed into VFS
    const inputFileName = 'AddBookmark.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Delete the first bookmark
    doc.Bookmarks.RemoveAt(0);

    // Save the document and trigger download
    const outputFileName = "DeleteBookmark.pdf";
    doc.SaveToFile(outputFileName);
    doc.Close();

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: "application/pdf" });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Delete PDF Bookmarks</h1>
      <button onClick={deletePdfBookmarks}>
        Start Deleting
      </button>
    </div>
  );
}

export default App;
Document after deleting specified PDF bookmarks

Frequently Asked Questions
How to Add Multi-Level Nested Bookmarks
Reason: PDF bookmarks support hierarchical structure, allowing you to create parent and child bookmarks for document navigation.
Solution: You can add child bookmarks through the parent bookmark's Add method to form a nested structure. The following code demonstrates how to create two-level bookmarks:
// Create a parent bookmark
let parentBookmark = doc.Bookmarks.Add("Chapter 1");
parentBookmark.DisplayStyle = pdfModule.PdfTextStyle.Bold;

// Add a child bookmark via the parent bookmark's Add method
let childBookmark = parentBookmark.Add("1.1 Section");
childBookmark.DisplayStyle = pdfModule.PdfTextStyle.Regular;
What Properties Can Be Modified When Editing Bookmarks
Reason: Spire.PDF for JavaScript provides rich bookmark property settings for customizing bookmark appearance.
Solution: The following properties can be modified:
Title: Bookmark title textColor: Bookmark color, set usingPdfRGBColorDisplayStyle: Display style, options includeBold(bold),Italic(italic),Underline(underline),Regular(normal)Action: Bookmark jump action, set usingPdfGoToAction
let bookmark = doc.Bookmarks.get_Item(0);
bookmark.Title = "New Title";
bookmark.Color = new pdfModule.PdfRGBColor({ color: pdfModule.Color.get_Blue() });
bookmark.DisplayStyle = pdfModule.PdfTextStyle.Bold | pdfModule.PdfTextStyle.Italic;
How to Delete All Bookmarks from a PDF
Reason: Sometimes you need to clear all bookmarks from a document, such as when regenerating or removing sensitive navigation information.
Solution: You can delete them one by one by repeatedly calling RemoveAt(0), since after each deletion, the bookmarks at index 0 are removed and subsequent bookmarks automatically shift forward:
while (doc.Bookmarks.Count > 0) {
  doc.Bookmarks.RemoveAt(0);
}
Get a Free License
If you wish to remove the evaluation message from the result document or remove feature limitations, please contact sales to obtain a temporary license valid for 30 days.
How to Add, Hide and Delete PDF Layers with JavaScript in React
PDF layers partition the content on a page into multiple "Optional Content Groups" (OCGs). This is most commonly seen in CAD drawings where walls, furniture, and electrical plans are separated onto layers, in maps where roads, water systems, and labels are separated, and in pages that need to switch between several plans or several languages on demand. Unlike erasing content, layers let you hide content and then bring it back at any time without destroying the document structure, which greatly increases the reuse value of the same PDF.
Spire.PDF for JavaScript runs on WebAssembly and completes the loading, drawing, and saving of PDFs entirely in the browser, managing input and output files through a virtual file system (VFS) with no backend required.
This article covers three core functions:
For installation and project configuration, refer to Integrating Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module has been initialized.
Adding Layers to a PDF
To add a layer, first create a document and add a page, then create a named layer with doc.Layers.AddLayer({ name, state }) (the state argument lets you specify the initial visibility), and call the layer's layer.CreateGraphics(page.Canvas) to obtain a drawing context bound to the page canvas. From then on, methods such as DrawLine and DrawRectangle can draw lines, color blocks, and other content "into" that layer. The example below creates three layers named red line, blue line, and green line, draws one horizontal line and one small color block of the corresponding color into each layer, and staggers the three lines at different heights.
function App() {
  const addLayers = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Create a PdfDocument and add a page
    let doc = new pdfModule.PdfDocument();
    let page = doc.Pages.Add();

    // Get the page size for positioning content relative to the page
    const width = page.Canvas.Size.Width;
    const height = page.Canvas.Size.Height;

    // Define a local function that draws a horizontal line with a small
    // color block of the same color into the layer with the given name
    const drawRow = (layerName, centerY, brush) => {
      // Add a layer to the document and set its initial state to visible
      let layer = doc.Layers.AddLayer({ name: layerName, state: pdfModule.PdfVisibility.On });

      // Get the drawing context of the layer
      let g = layer.CreateGraphics(page.Canvas);

      // Draw a colored horizontal line that spans about 20% to 80% of the page width
      g.DrawLine({
        pen: new pdfModule.PdfPen({ brush: brush, width: 2 }),
        point1: new pdfModule.PointF(width * 0.2, centerY),
        point2: new pdfModule.PointF(width * 0.8, centerY)
      });

      // Draw a small color block at the left end of the line as an indicator of the layer color
      g.DrawRectangle({
        brush: brush,
        rectangle: new pdfModule.RectangleF({ x: width * 0.12, y: centerY - 6, width: 12, height: 12 })
      });
    };

    // Place the three lines from top to bottom at 25%, 50%, and 75% of the page height
    drawRow('red line', height * 0.25, pdfModule.PdfBrushes.get_Red());
    drawRow('blue line', height * 0.5, pdfModule.PdfBrushes.get_Blue());
    drawRow('green line', height * 0.75, pdfModule.PdfBrushes.get_Green());

    // Define the output file name and save the document
    const outputFileName = 'AddLayers.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add Layers To PDF</h1>
      <button onClick={addLayers}>
        Generate
      </button>
    </div>
  );
}

export default App;
PDF page after adding the red line, blue line and green line layers
Hiding a Specified Layer
When the content of a layer should not be shown temporarily but may be needed again later, you do not have to delete it. Simply set the Visibility property of the layer to PdfVisibility.Off to "hide" it. The content then no longer displays, but the layer and the objects inside it are still kept in the PDF, and readers can turn them back on any time in the Layers panel of a PDF viewer. The example below takes the AddLayers.pdf produced in the previous section (it already contains the red line, blue line, and green line layers), fetches two of the layers by name with get_Item({ name }), and sets their Visibility to invisible, so only the green line layer remains on the page.
function App() {
  const hideLayers = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF that contains the layers into the VFS
    const inputFileName = 'AddLayers.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Get the "red line" and "blue line" layers by name and set them to invisible,
    // so only "green line" remains on the page
    doc.Layers.get_Item({ name: 'red line' }).Visibility = pdfModule.PdfVisibility.Off;
    doc.Layers.get_Item({ name: 'blue line' }).Visibility = pdfModule.PdfVisibility.Off;

    // Define the output file name and save the document
    const outputFileName = 'HideLayers.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Hide Layers In PDF</h1>
      <button onClick={hideLayers}>
        Generate
      </button>
    </div>
  );
}

export default App;
After hiding the red line and blue line layers, only the green line layer remains on the page
Deleting a Layer
When a layer and its content are no longer needed, you can remove it from the document's layer collection with doc.Layers.RemoveLayer: just pass the layer name, for example RemoveLayer({ name: 'red line' }) removes the entire layer named red line. The content of that layer no longer displays afterward and cannot be restored through the Layers panel either. The example below takes the AddLayers.pdf produced in the first section (it already contains the red line, blue line, and green line layers), and deletes the red line layer by name, so only the blue line and green line layers remain on the page.
function App() {
  const deleteLayer = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF that contains the layers into the VFS
    const inputFileName = 'AddLayers.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Delete the "red line" layer by name; its content no longer shows on the page
    doc.Layers.RemoveLayer({ name: 'red line' });

    // Define the output file name and save the document
    const outputFileName = 'DeleteLayers.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Delete PDF Layer</h1>
      <button onClick={deleteLayer}>
        Generate
      </button>
    </div>
  );
}

export default App;
After deleting the red line layer, only the blue line and green line layers remain on the page
FAQ
What is the difference between hiding and deleting a layer
Reason: Both hiding and deleting make content "invisible" on the page, so it is easy to confuse the difference between the two in terms of the document structure.
Solution: Hiding sets the Visibility of a layer to Off; the layer and the objects inside it are still kept in the PDF, and you can turn them back on at any time in the Layers panel of the viewer. Deleting, on the other hand, removes the layer from doc.Layers entirely with RemoveLayer, and its content no longer displays and cannot be restored. In short: hide it when you do not need to see it for a while, delete it when you will never need it again:
// Hide: the content stays in the document and can be turned back on at any time
doc.Layers.get_Item({ name: 'red line' }).Visibility = pdfModule.PdfVisibility.Off;

// Delete: the layer is removed from the collection and cannot be turned back on
doc.Layers.RemoveLayer({ name: 'red line' });
How do I control whether a layer is visible when I add it
Reason: A layer created by AddLayer is visible by default, but sometimes you want a layer to start out hidden (for example, an alternative plan that is preset but not shown yet).
Solution: The state argument of AddLayer specifies the initial visibility of a layer. Passing PdfVisibility.Off creates it as invisible, while passing On (or omitting it) makes it visible immediately after creation. After creation you can switch it at any time with the Visibility property:
// Create a new layer that is invisible initially
doc.Layers.AddLayer({ name: 'Alternative Plan', state: pdfModule.PdfVisibility.Off });
How do I locate a layer by name or index
Reason: With a document that contains multiple layers, you often need to operate on one particular layer, and the Layers collection holds several elements, so you need an accurate way to locate it.
Solution: doc.Layers is the layer collection. Count gives the total number of layers, get_Item({ name }) retrieves a layer by its name, and get_Item(i) retrieves one by its index. To control layers in bulk, iterate through all of them, for example to set every layer invisible at once:
// Iterate through the layer collection and set all layers to invisible
for (let i = 0; i < doc.Layers.Count; i++) {
  doc.Layers.get_Item(i).Visibility = pdfModule.PdfVisibility.Off;
}
Get a Free Temporary License
If you want to remove the evaluation message from the result documents, or get rid of the function limitations, please contact our sales team to get a temporary license that is valid for 30 days.
How to Create and Identify PDF Portfolios with JavaScript in React
PDF keeps its layout fixed and renders consistently across devices, which makes it ideal for distributing contracts, manuals, and reports. In business, however, a set of materials often consists of multiple related PDFs: a product manual, for example, usually goes together with a quotation, a technical specification, and frequently asked questions. Sending each file separately is scattered and easy to miss. The PDF "portfolio" mechanism provides a standard way to solve this problem — it lets you package several documents into a single PDF. The recipient opens one file and can view, expand, and save each member file from the portfolio view of their PDF viewer, which makes unified delivery and archiving convenient.
Spire.PDF for JavaScript runs on WebAssembly and completes the loading, drawing, and saving of PDFs entirely in the browser, managing input and output files through a virtual file system (VFS) with no backend required. Two operations are commonly used around portfolios: creating one — load a main document with PdfDocument, then add each member file that has been loaded into the VFS one by one through the file collection's root folder doc.Collection.Folders and its AddFile method, using CreateSubfolder to build subfolders and group members when needed; and identifying one — read the doc.IsPortfolio property directly to tell whether a PDF is a portfolio.
This article covers two core functions:
For installation and project configuration, refer to Integrating Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module has been initialized.
Creating a PDF Portfolio
Portfolio members are not limited to PDFs — Word, Excel, and image files can be added as well, and subfolders can be used to group them. The packaging logic is straightforward: first load a main document with PdfDocument to act as the carrier of the portfolio; load each member file to be packaged into the virtual file system with FetchFileToVFS; then iterate over the members and add each one to the file collection's root folder with doc.Collection.Folders.AddFile({ filePath }). If you want some files to live in a subfolder of their own, create the subfolder first with CreateSubfolder, then call AddFile on it to add the files. When every member has been added, save the document to obtain a PDF portfolio that packages the main document together with all of its member files.
function App() {
  const createPortfolio = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF used as the main document of the portfolio into the VFS
    const mainFileName = 'Product_Manual.pdf';
    await window.spire.FetchFileToVFS(mainFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the main document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(mainFileName);

    // Load each member file placed under the root of the portfolio into the VFS and add it to the folder of the file collection
    const rootFiles = ['Quotation.pdf', 'Technical_Specification.pdf', 'logo.png', 'Financial_Statement.xlsx'];
    for (let i = 0; i < rootFiles.length; i++) {
      await window.spire.FetchFileToVFS(rootFiles[i], "", `${process.env.PUBLIC_URL}/data/`);
      doc.Collection.Folders.AddFile({ filePath: rootFiles[i] });
    }

    // Load the Word document to be placed in a subfolder into the VFS
    await window.spire.FetchFileToVFS('test.docx', "", `${process.env.PUBLIC_URL}/data/`);
    // Create a subfolder named "Documents" in the file collection and add the Word document to it
    const subFolder = doc.Collection.Folders.CreateSubfolder('Documents');
    subFolder.AddFile({ filePath: 'test.docx' });

    // Define the output file name and save the document
    const outputFileName = 'Product_Portfolio.pdf';
    doc.SaveToFile(outputFileName);
    doc.Close();

    // Read the generated file from the VFS and trigger a download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Create PDF Portfolio</h1>
      <button onClick={createPortfolio}>
        Generate
      </button>
    </div>
  );
}

export default App;
The resulting PDF portfolio after creation
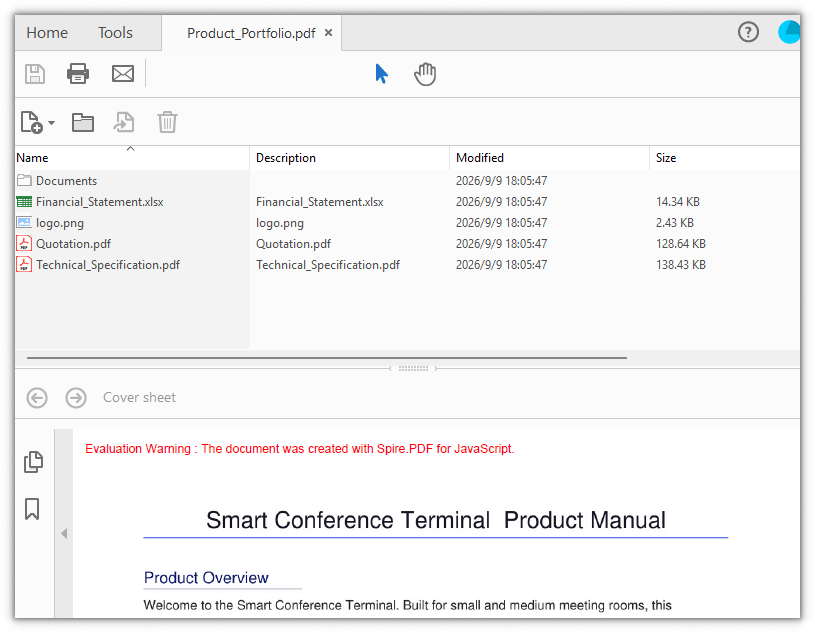
Identifying a PDF Portfolio
When you receive a PDF and need to tell whether it is a portfolio, use the PdfDocument.IsPortfolio property: load the document with LoadFromFile and read the Boolean property. A return value of true means the PDF is a portfolio, while false means it is a regular PDF document. This example loads a product portfolio sample to identify it, writes the "is a portfolio" result to a downloaded txt file, and also shows it below on the page so the conclusion can be seen at a glance.
function App() {
  const identifyPortfolio = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF to be identified into the VFS
    const inputFileName = 'Product_Portfolio.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Judge whether this PDF is a portfolio
    const isPortfolio = doc.IsPortfolio;
    const message = isPortfolio ? 'This PDF is a portfolio.' : 'This PDF is not a portfolio.';
    doc.Close();

    // Show the result below on the page
    const resultEl = document.getElementById('identify-result');
    if (resultEl) resultEl.innerText = message;

    // Write the result to a txt file and trigger a download
    const outputFileName = 'Identification_Result.txt';
    window.dotnetRuntime.Module.FS.writeFile(outputFileName, message);
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'text/plain' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Identify PDF Portfolio</h1>
      <button onClick={identifyPortfolio}>
        Check
      </button>
      <p id="identify-result" style={{ marginTop: '20px', fontWeight: 'bold' }}></p>
    </div>
  );
}

export default App;
The identification result shows that the PDF is a portfolio
FAQ
How can I confirm that the file is really a portfolio after creating it
Reason: A portfolio only "packages" the member files into the same PDF, so it may not be obvious at a glance whether the saving succeeded.
Solution: Use doc.IsPortfolio for a second check on the saved result — reload the generated file and a return value of true means it is a portfolio:
// Reload the generated file and check whether it is a portfolio
let doc = new pdfModule.PdfDocument();
doc.LoadFromFile('Product_Portfolio.pdf');
const isPortfolio = doc.IsPortfolio;
What is the difference between a portfolio and ordinary PDF attachments
Reason: Both portfolios and attachments "stuff" files into a PDF, so it is easy to confuse their purposes and how to tell them apart.
Solution: A PDF attachment (Attachment) attaches a file as an embedded file that appears in the attachment panel of the document, while the body itself is usually an independent document. A portfolio, on the other hand, organizes member files around a file collection (Collection), and the members can be several documents that appear as separate files in the portfolio view and can be expanded and saved individually. To tell them apart, use doc.Attachments to inspect attachments and doc.IsPortfolio to check whether the document is a portfolio; the two do not substitute for each other.
Can only PDF files be added to a portfolio
Reason: The example presents the PDF members first, which makes it easy to assume a portfolio can only hold PDFs.
Solution: AddFile adds any file that exists in the virtual file system, not just PDFs. Load the target file into the VFS with FetchFileToVFS and add it with { filePath: fileName }; to group files into one place, create a subfolder with CreateSubfolder and add the files to it. Word, Excel, images, and other files can all be packaged into a portfolio as members:
// Load an Excel file and add it as a portfolio member
await window.spire.FetchFileToVFS('Financial_Statement.xlsx', "", `${process.env.PUBLIC_URL}/data/`);
doc.Collection.Folders.AddFile({ filePath: 'Financial_Statement.xlsx' });
Get a Free Temporary License
If you want to remove the evaluation message from the result documents, or get rid of the function limitations, please contact our sales team to get a temporary license that is valid for 30 days.