Document Operation (16)
Read and Set Word Document Properties with JavaScript in React
2026-11-12 07:34:33 Written by Amy ZhaoDocument properties record information that lives outside the content itself: title, author, subject, keywords, company, revision count, and the custom fields written by line-of-business systems. During batch archiving, properties free a document from its file name; during content review, they explain where the document came from and which version it is. Moving property handling into the browser lets a user select a file and finish checking or completing the properties right there, without uploading anything to a server.
This article uses Spire.Doc for JavaScript to read and write Word document properties in the browser. The sample uses three documents: Archive.docx is an archived "2026 Third-Quarter Business Analysis Report" with a complete set of properties; Draft.docx is a "2027 Digital Transformation Project Proposal" whose properties still have to be completed; and Contract.docx is an "Intelligent Warehousing Equipment Purchase Contract" that carries custom properties such as the contract number. The whole process runs on the client side with WebAssembly, requires no Office installation and depends on no backend, so the documents are read and written locally and are not uploaded to a server by the library.
This article covers three features:
- Read the Built-in Summary Properties of a Word Document
- Set the Built-in Summary Properties of a Word Document
- Manage the Custom Properties of a Word Document
Word document properties fall into two categories, which differ in where they are stored and what they are used for:
| Category | Access point | Typical fields |
|---|---|---|
| Built-in properties | Document.BuiltinDocumentProperties |
Title, author, subject, keywords, company, revision count |
| Custom properties | Document.CustomDocumentProperties |
Business fields such as contract number, project number and review status |
Word defines the names and meanings of the built-in properties, and most of them can be seen in the File > Info panel. Custom properties are defined by the business side, with no restriction on name or purpose, and the type of the value is described by DocumentProperty.ValueType.
For installation and project setup, refer to Integrating Spire.Doc for JavaScript in a React Project. The examples below assume that Spire.Doc is installed and the WebAssembly module is initialized.
Read the Built-in Summary Properties of a Word Document
The built-in summary properties of a Word document are read through Document.BuiltinDocumentProperties. The property returns a collection in which fields such as title, author and subject are exposed with initial capitals, in the same form as C#, so they can be read by name directly. The result is usually used for checking: whether the title matches the file name, whether the author is empty, and whether the creation date falls within the archiving window.
The built-in properties fall into three groups by purpose:
| Group | Typical fields | Read behavior |
|---|---|---|
| Summary information | Title, Subject, Author, Keywords, Comments, LastAuthor, RevisionNumber, CreateDate, LastSaveDate |
Strings or dates, read directly |
| Extended information | Category, Company, Manager, ContentStatus, HyperLinkBase |
Strings, possibly empty when not set |
| Statistics | PageCount, WordCount, CharCount, ParagraphCount, LinesCount, BytesCount |
Read-only, taken from the statistics recorded when the file was saved |
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the font and
Archive.docx, create aDocumentobject and load the file. - Read the title, author, subject and other properties in turn through
BuiltinDocumentProperties. - Join the values into tab-separated text and write it to the VFS.
- Read the text file from the VFS and trigger a browser download.
The code for reading the built-in summary properties of a Word document is as follows:
function App() {
  const readBuiltinProperties = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the document to be checked
    await window.spire.FetchFileToVFS('Archive.docx', '', `${process.env.PUBLIC_URL}/data/`);

    const doc = new docModule.Document();
    doc.LoadFromFile('Archive.docx');

    // Date properties return Date objects; format them before joining the text
    const formatDate = (value) =>
      value instanceof Date ? value.toLocaleString('en-US', { hour12: false }) : '';

    const props = doc.BuiltinDocumentProperties;
    const report = [
      `Title\t${props.Title ?? ''}`,
      `Subject\t${props.Subject ?? ''}`,
      `Author\t${props.Author ?? ''}`,
      `Last Author\t${props.LastAuthor ?? ''}`,
      `Keywords\t${props.Keywords ?? ''}`,
      `Comments\t${props.Comments ?? ''}`,
      `Category\t${props.Category ?? ''}`,
      `Company\t${props.Company ?? ''}`,
      `Revision Number\t${props.RevisionNumber ?? ''}`,
      `Created\t${formatDate(props.CreateDate)}`,
      `Last Saved\t${formatDate(props.LastSaveDate)}`,
    ].join('\r\n');

    // Write to the VFS, then read it back as a Blob to trigger the download
    window.dotnetRuntime.Module.FS.writeFile('BuiltinProperties.txt', report);
    doc.Dispose();

    const fileArray = window.dotnetRuntime.Module.FS.readFile('BuiltinProperties.txt');
    const blob = new Blob([fileArray], { type: 'text/plain;charset=utf-8' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = 'BuiltinProperties.txt';
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Read Document Properties</h1>
      <button onClick={readBuiltinProperties}>Export Property List</button>
    </div>
  );
}

export default App;
The exported property list is shown below, with the archived document being checked on the left:
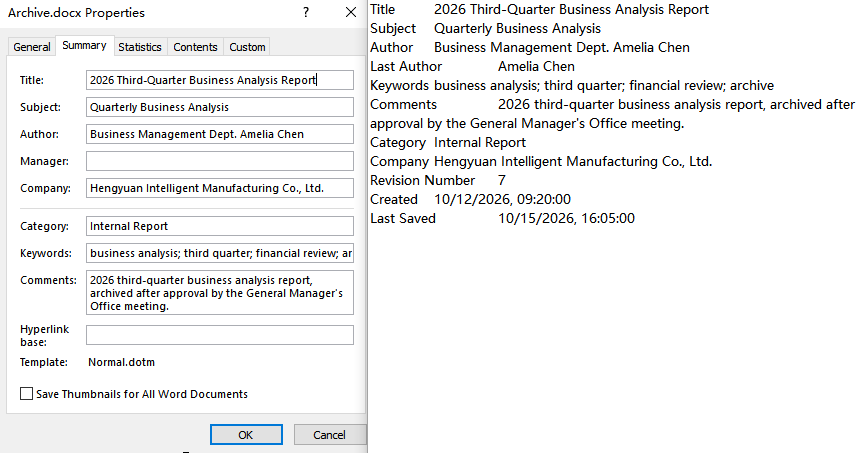
The list has 11 items. The title, subject, author, keywords, comments, category and company all match the archiving requirements; the revision number is 7; and the creation and last-saved times have been formatted as local time by toLocaleString, reading 10/12/2026, 09:20:00 and 10/15/2026, 16:05:00 respectively.
What Unset Properties Return
Most built-in properties that have not been set return an empty string; fields such as Keywords and ContentStatus return null when the document has no corresponding entry, as is the case for Draft.docx in the sample. Date properties return a JavaScript Date object, and when unset they hold the default value of year 1 rather than an empty string. Both null and an empty string therefore mean only that there is no readable value; neither can tell whether the property was never set or was set to an empty value. The ?? '' in the code only prevents null from being joined as undefined; it does not mean that the property actually exists.
Statistics and the Body Content
Statistics such as PageCount, WordCount, CharCount and ParagraphCount are read from the values recorded in docProps/app.xml when the file was saved, not recalculated from the current content. The sample document records no statistics, so WordCount, CharCount and ParagraphCount all read 0, and PageCount defaults to 1. After calling doc.UpdateWordCount(), the word, character and paragraph counts are recalculated from the current content (598, 3047 and 88 in the sample), while PageCount, LinesCount and BytesCount are not affected. When accurate statistics are needed, call that method first instead of reading the properties directly.
Set the Built-in Summary Properties of a Word Document
The built-in summary properties of a Word document are set by assigning values to the corresponding fields of BuiltinDocumentProperties. Archiving, delivery and review all require complete properties, and writing them once at generation time is more reliable than filling them in one by one in Word: take the document name as the title, the current department as the author and the business tags as the keywords, so that a batch of documents follows the same convention.
The sample completes the following fields for the discussion draft:
| Property | Value written | Description |
|---|---|---|
Title |
2027 Digital Transformation Project Proposal | Document title |
Subject |
Project Proposal | Subject |
Author |
Digital Transformation Office | Author |
Keywords |
digital transformation; project proposal; fiscal 2027 | Separate multiple keywords with semicolons |
Comments |
Summary properties added according to the archiving rules. | Comments |
Category |
Project Proposal Materials | Category |
Company |
Hengyuan Intelligent Manufacturing Co., Ltd. | Company |
RevisionNumber |
'5' |
Written as a string |
LastAuthor |
Digital Transformation Office | Last author |
CreateDate |
new Date('2026-10-08T10:00:00+08:00') |
Needs a Date object |
The specific steps are as follows:
- Get the WASM module, load the font and
Draft.docx, and load the document. - Assign the title, subject, author, keywords, comments, category and company.
- Write the revision number and last author as strings, and the creation date as a
Dateobject. - Save the document as
DraftWithProperties.docx. - Read the result from the VFS and trigger a browser download.
The code for setting the built-in summary properties of a Word document is as follows:
function App() {
  const setBuiltinProperties = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the document whose properties are to be completed
    await window.spire.FetchFileToVFS('Draft.docx', '', `${process.env.PUBLIC_URL}/data/`);

    const doc = new docModule.Document();
    doc.LoadFromFile('Draft.docx');

    const props = doc.BuiltinDocumentProperties;
    props.Title = '2027 Digital Transformation Project Proposal';
    props.Subject = 'Project Proposal';
    props.Author = 'Digital Transformation Office';
    props.Keywords = 'digital transformation; project proposal; fiscal 2027';
    props.Comments = 'Summary properties added according to the archiving rules.';
    props.Category = 'Project Proposal Materials';
    props.Company = 'Hengyuan Intelligent Manufacturing Co., Ltd.';
    // Revision number is written as a string; date properties need a Date object
    props.RevisionNumber = '5';
    props.LastAuthor = 'Digital Transformation Office';
    props.CreateDate = new Date('2026-10-08T10:00:00+08:00');

    const outputFileName = 'DraftWithProperties.docx';
    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });
    doc.Dispose();

    // Read the result from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], {
      type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document',
    });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Set Document Properties</h1>
      <button onClick={setBuiltinProperties}>Write Properties</button>
    </div>
  );
}

export default App;
After the result document is saved and loaded again, the properties read back are as follows:
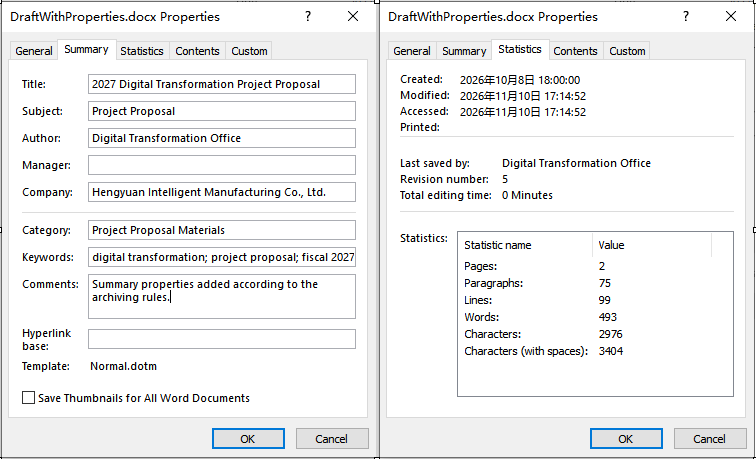
The 10 properties read back after reloading match the values that were written, which shows that the properties were saved with the document. The creation time was written as a Date object and is also displayed as local time after reading back, as 10/8/2026, 10:00:00.
Read-only Properties Cannot Be Written
Statistics such as PageCount, WordCount, CharCount, BytesCount and LinesCount expose only read accessors, and assigning to them does not write the result; in an ES module a direct assignment even throws a TypeError saying that the property has only a getter. Such values should be recalculated from the current content with doc.UpdateWordCount() before saving, instead of being assigned by hand.
Writing Types for the Revision Number and Date Properties
RevisionNumber is written as a string; passing a number reports Assert failed: Value is not a String. CreateDate, LastSaveDate and LastPrinted need a JavaScript Date object; passing a string reports Assert failed: Value is not a Date. The new Date('2026-10-08T10:00:00+08:00') in the sample still reads back as 10/8/2026, 10:00:00 after being written. Date properties round-trip as wall-clock time, so when a document moves across time zones, check first that the browser time zone matches the time zone the document belongs to.
How to Confirm That the Properties Have Been Saved
Whether the write succeeded is decided by the values read back after reloading. Create a new Document, load the result file and read the corresponding fields:
// Reload the result document after saving and read back the written values
const check = new docModule.Document();
check.LoadFromFile('DraftWithProperties.docx');

const checkProps = check.BuiltinDocumentProperties;
console.log(checkProps.Title);
console.log(checkProps.Author);
check.Dispose();
Why the Properties Are Not Visible in File Explorer
The details pane of Windows File Explorer shows only some summary fields and depends on property handlers. Fields such as Category and Company have to be viewed in Word under File > Info > Properties > Advanced Properties. Whether the write succeeded should be judged by the values read back after reloading the document, not by what the file list displays.
Manage the Custom Properties of a Word Document
The custom properties of a Word document are managed through the Document.CustomDocumentProperties collection. Business fields do not fit well into the built-in properties: information such as contract number, project number and review status is clearer in custom properties, where names are user-defined, do not collide, and can be searched by name. The collection supports adding, reading by name or index, updating and deleting.
The main members involved are as follows:
| Member | Effect |
|---|---|
CustomDocumentProperties.Add(name, value) |
Adds a property; the type is inferred from the JavaScript value |
CustomDocumentProperties.get_Item(name) |
Returns a DocumentProperty by name |
CustomDocumentProperties.get_Item(index) |
Returns a property by index, used for enumeration |
DocumentProperty.Name |
Property name |
DocumentProperty.Value |
Property value; reading returns a wrapper object that has to be turned into text with ToString() |
DocumentProperty.ValueType |
Property type enumeration |
CustomDocumentProperties.Remove(name) |
Removes a property by name |
CustomDocumentProperties.Count |
Total number of properties |
The sample contract already carries two custom properties, ContractNo (contract number) and Department (responsible department). The demo adds a review status and an archive box number, rewrites the contract number, deletes the archive box number, and finally enumerates all properties to build a list.
The specific steps are as follows:
- Get the WASM module, load the font and
Contract.docx, and load the document. - Add the two custom properties
ReviewStatusandArchiveBox. - Get the contract number property by name and rewrite its value with a wrapped string.
- Remove the archive box number property by name.
- Enumerate all custom properties to build a list, save the document and download both the document and the list.
The code for managing the custom properties of a Word document is as follows:
function App() {
  const manageCustomProperties = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the contract document
    await window.spire.FetchFileToVFS('Contract.docx', '', `${process.env.PUBLIC_URL}/data/`);

    const doc = new docModule.Document();
    doc.LoadFromFile('Contract.docx');

    const custom = doc.CustomDocumentProperties;

    // Add custom properties
    custom.Add('ReviewStatus', 'Pending review');
    custom.Add('ArchiveBox', 'A-03');

    // Get by name and update the value with a wrapped string
    custom.get_Item('ContractNo').Value = new docModule.String('HY-CG-2026-0418-REV2');

    // Remove by name
    custom.Remove('ArchiveBox');

    // Walk all properties to build the list
    let report = 'Name\tValue\tType\r\n';
    for (let i = 0; i < custom.Count; i++) {
      const prop = custom.get_Item(i);
      report += `${prop.Name}\t${prop.ToString()}\t${prop.ValueType}\r\n`;
    }
    window.dotnetRuntime.Module.FS.writeFile('CustomProperties.txt', report);

    const outputFileName = 'ContractWithProperties.docx';
    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });
    doc.Dispose();

    // Download the result document and the property list in turn
    const outputs = [
      [outputFileName, 'application/vnd.openxmlformats-officedocument.wordprocessingml.document'],
      ['CustomProperties.txt', 'text/plain;charset=utf-8'],
    ];
    for (const [fileName, mime] of outputs) {
      const fileArray = window.dotnetRuntime.Module.FS.readFile(fileName);
      const blob = new Blob([fileArray], { type: mime });
      const url = URL.createObjectURL(blob);
      const a = document.createElement('a');
      a.href = url;
      a.download = fileName;
      a.click();
      URL.revokeObjectURL(url);
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Manage Custom Properties</h1>
      <button onClick={manageCustomProperties}>Process Properties</button>
    </div>
  );
}

export default App;
The processed document and the property list are as follows:
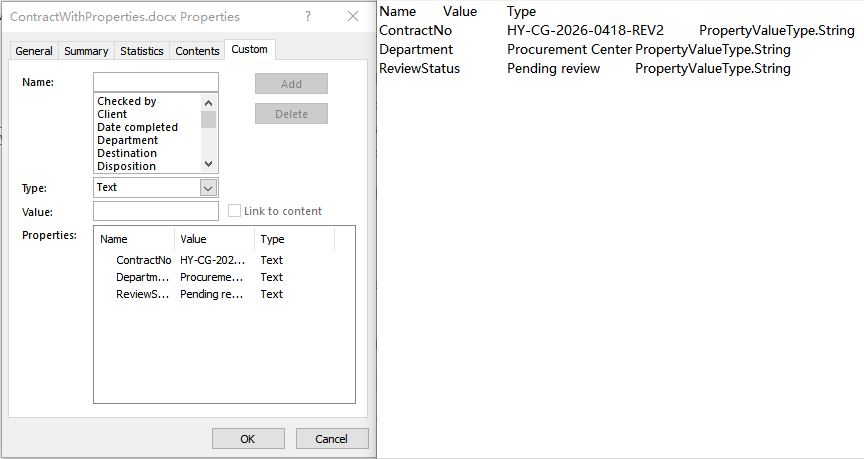
The contract number has been changed to HY-CG-2026-0418-REV2, the newly added ReviewStatus remains in the collection, ArchiveBox has been removed, and the existing Department is unchanged. The type column comes from DocumentProperty.ValueType, and all three items are PropertyValueType.String.
The Correct Way to Update an Existing Property
Calling Add() again for a property that already exists does not overwrite the original value; both the item count and the values in the collection stay the same, so Add() cannot be used to update. A string property has to be taken out with get_Item(), and the new value wrapped with new docModule.String() before it is assigned to Value; passing a bare string reports a null argument (ArgumentNull_Generic). Numeric and boolean properties need a wrapped value of the matching type, and the more straightforward route is to remove the property and add it again, so that Add() infers the type from the new value:
const custom = doc.CustomDocumentProperties;

// String values: wrap them with new docModule.String
custom.get_Item('ContractNo').Value = new docModule.String('HY-CG-2026-0418-REV2');

// Numeric or boolean values: remove first, then add so the type follows the new value
custom.Remove('Amount');
custom.Add('Amount', 367.2);
Name Case and Duplicate Additions
Custom property names are case-insensitive: when ContractNo already exists, calling Add('contractno', ...) does not add another item to the collection. Calling Add() again for an existing name is likewise ignored; it neither adds an entry nor rewrites the original value. To update an existing property, assign to Value as shown above, or remove it first and add it again.
How the Value Type Is Determined
Add(name, value) infers the type from the JavaScript value passed in: a string is stored as PropertyValueType.String, an integer as PropertyValueType.Int, a decimal as PropertyValueType.Double, and a boolean as PropertyValueType.Boolean. ValueType returns an enumeration object, and joining it into a string directly produces a name such as PropertyValueType.String, with no extra mapping required.
Date values are not supported yet: after a Date object is passed in, the collection does gain an item, but reading that item by name reports Property value is of unsupported type. Date information is better stored as an ISO string such as 2026-09-28 and converted when it is read.
Properties versus Document Variables
Document variables (doc.Variables) are key-value pairs that Word field codes can reference, and they appear in the body when the fields are updated; custom properties are document metadata and do not take part in body layout. When the contract number has to be displayed automatically in the body, write a document variable and insert the corresponding field in the body; when the information only has to be recorded, custom properties are enough.
FAQ
Do the files have to be uploaded to a server when reading and writing document properties
Not with the approach in this article. Spire.Doc for JavaScript runs in the browser on WebAssembly, and documents are read and written locally through the virtual file system (VFS): loading, reading, updating and saving all happen on the device, and the library itself does not send files to a server. Whether a file eventually leaves the device depends on the other code you add to the page.
Can custom properties store a date
In Spire.Doc for JavaScript, passing a Date object is not reliable in practice: after Add() is called the item count increases, but reading that item by name reports Property value is of unsupported type. Store date information as an ISO string such as 2026-09-28 and convert it as required after reading.
const custom = doc.CustomDocumentProperties;

// Store the date as a string and convert it when reading
custom.Add('SignDate', '2026-09-28');
Are the last author and last-saved time updated automatically after saving
Saving does not rewrite either field in practice: after LastAuthor and LastSaveDate are written, saved and the document is reloaded, the values read back are still the ones that were written; when they are not written, the original values of the file are kept. To make them reflect the current processing, assign them explicitly before saving.
Does a null property mean that the property does not exist
Not necessarily. Most built-in properties that have not been set return an empty string, while fields such as Keywords and ContentStatus may return null; both results mean only that there is no readable value and cannot distinguish "never set" from "set to empty". For checking purposes, judge by the document source and the business rules together rather than by the returned value alone.
Get a Free License
Spire.Doc for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Compare Word Documents and Extract Differences with JavaScript in React
2026-11-10 07:32:14 Written by Amy ZhaoContract revisions, proposal reviews and policy updates all end with the same question: what exactly changed between this version and the last one. Comparing page by page is slow and easy to miss; recording the comparison as tracked changes lets each item be confirmed in Word, and the differences can then be organized into a list for the reviewer.
This article uses Spire.Doc for JavaScript to do this work in the browser. The sample uses two versions of the same "Starlan Membership Data Platform Construction Project Cooperation Proposal": Original.docx is the October 15 draft and Revised.docx is the October 28 review draft. The two versions contain more than ten changes, including the preparation date, the contract amount, section headings and the header. The whole process runs on the client side with WebAssembly, requires no Office installation and depends on no backend, so the documents stay on the user's device.
This article covers three features:
- Compare Two Word Documents and Generate a Tracked Version
- Control the Scope of the Comparison with Options
- Extract and Export a List of Differences
The examples read Original.docx and Revised.docx from public/data; put both files into the public/data directory of the project before running them.
For installation and project setup, refer to Integrating Spire.Doc for JavaScript in a React Project. The examples below assume that Spire.Doc is installed and the WebAssembly module is initialized.
Compare Two Word Documents and Generate a Tracked Version
Comparing two Word documents and generating a tracked version is done with a single call to Document.Compare(). The method works with an "original + revised" model: the document that calls the method is the original, the document passed as the argument is the revised version, and the comparison result is written back into the calling document as tracked changes.
| Role | How it is provided | Description |
|---|---|---|
| Original | The document that calls Compare() |
Rewritten as the version with tracked changes after the comparison |
| Revised | The document passed as an argument | Only its content is read; it is not modified |
| Author | The string passed as the second argument | Written into every revision as the author name |
The comparison modifies the original object itself. When the original version has to be preserved, reload the file or save a copy instead of saving the original object after the comparison.
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the font and
Original.docx,Revised.docxinto the VFS. - Create two
Documentinstances and load the two documents. - Call
Compare()on the original and pass in the revised document and the author name. - Save the result document, read it from the VFS and trigger a browser download.
The code for comparing two Word documents is as follows:
function App() {
  const compareDocuments = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the two sample documents
    await window.spire.FetchFileToVFS('Original.docx', '', `${process.env.PUBLIC_URL}/data/`);
    await window.spire.FetchFileToVFS('Revised.docx', '', `${process.env.PUBLIC_URL}/data/`);

    // Load the original and the revised document separately
    const original = new docModule.Document();
    original.LoadFromFile('Original.docx');

    const revised = new docModule.Document();
    revised.LoadFromFile('Revised.docx');

    // Call Compare on the original; the tracked changes are written into it
    original.Compare(revised, 'Contract Review');

    // Save the result document with tracked changes
    const outputFileName = 'CompareResult.docx';
    original.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });

    // Release the two document instances
    revised.Dispose();
    original.Dispose();

    // Read the result from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], {
      type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document',
    });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Compare Two Word Documents</h1>
      <button onClick={compareDocuments}>Start Comparison</button>
    </div>
  );
}

export default App;
When the result document is opened in Word, it appears in the revision view: inserted content is underlined, deleted content is struck through, and the body structure and page margins are preserved:
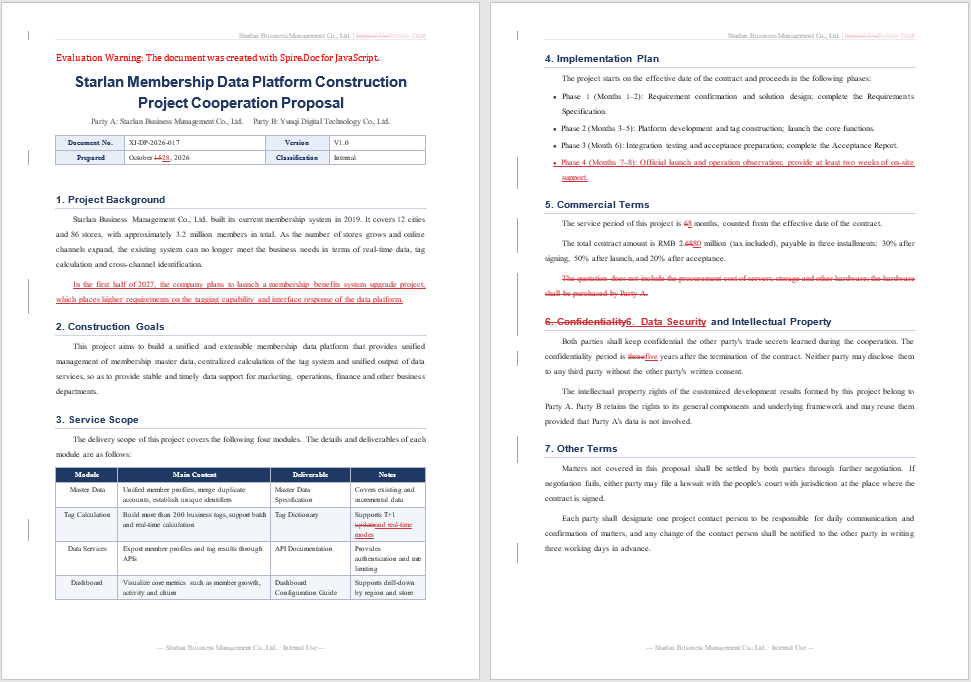
In the Preparation row, the old day number and the new day number appear side by side with a strikethrough and an underline, corresponding to a revision that replaces the old preparation date with the new one. The whole Phase 4 bullet is new content and is therefore underlined throughout. The paragraph "The quotation does not include the procurement cost of servers, storage and other hardware; the hardware shall be purchased by Party A." has been deleted and is shown with a strikethrough. The header label is likewise recorded as a revision.
Use HasChanges to Check Whether the Two Documents Differ
After the comparison, Document.HasChanges reports whether the document contains any revisions, so the check can be made before the result is saved. When the two documents are identical in content and formatting, the property is false and all four revision collections are empty:
original.Compare(revised, 'Contract Review');

// No need to save the result document when there is no difference
if (!original.HasChanges) {
  alert('The two documents are identical');
  return;
}
Control the Scope of the Comparison with Options
The scope of the comparison is determined by the four members of CompareOptions. By default, differences in formatting, tables and headers and footers are all recorded, while real-world scenarios often care about only part of them: a policy revision cares only about the wording of the clauses, a table version check looks only at the cell contents, and a formatting adjustment can be ignored altogether.
| Member | Default value | Effect |
|---|---|---|
IgnoreFormatting |
false |
Ignore differences in character and paragraph formatting |
IgnoreTable |
false |
Ignore tables; changes inside tables do not take part in the comparison |
IgnoreHeadersAndFooters |
false |
Ignore headers and footers |
TextCompareLevel |
TextDiffMode.Word |
Text comparison granularity; can be changed to TextDiffMode.Char |
The options have to be passed in object form, that is, Compare({ document, author, options }). Calling the method with positional arguments in the order "document, author, options" reports an ambiguous call; passing an object instead resolves it.
The specific steps are as follows:
- Load the font and the two documents, create the original and revised instances and load them separately.
- Create a
CompareOptionsinstance and enable the ignore switches as required. - Pass
document,authorandoptionsas an object and callCompare(). - Save the result document, read it from the VFS and trigger a browser download.
The code for comparing with options is as follows:
function App() {
  const compareWithOptions = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    await window.spire.FetchFileToVFS('Original.docx', '', `${process.env.PUBLIC_URL}/data/`);
    await window.spire.FetchFileToVFS('Revised.docx', '', `${process.env.PUBLIC_URL}/data/`);

    const original = new docModule.Document();
    original.LoadFromFile('Original.docx');

    const revised = new docModule.Document();
    revised.LoadFromFile('Revised.docx');

    // Set the comparison scope item by item
    const options = new docModule.CompareOptions();
    // Only text changes matter; font and paragraph adjustments are not recorded
    options.IgnoreFormatting = true;
    // Table contents are checked separately and are excluded from this comparison
    options.IgnoreTable = true;
    // Headers and footers are maintained by the template
    options.IgnoreHeadersAndFooters = true;

    // Pass the options as an object
    original.Compare({ document: revised, author: 'Contract Review', options });

    const outputFileName = 'CompareResultOptions.docx';
    original.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });

    revised.Dispose();
    original.Dispose();

    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], {
      type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document',
    });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Compare Two Word Documents with Options</h1>
      <button onClick={compareWithOptions}>Start Comparison</button>
    </div>
  );
}

export default App;
For the same documents, the default comparison and the comparison with the ignore options enabled look as follows:
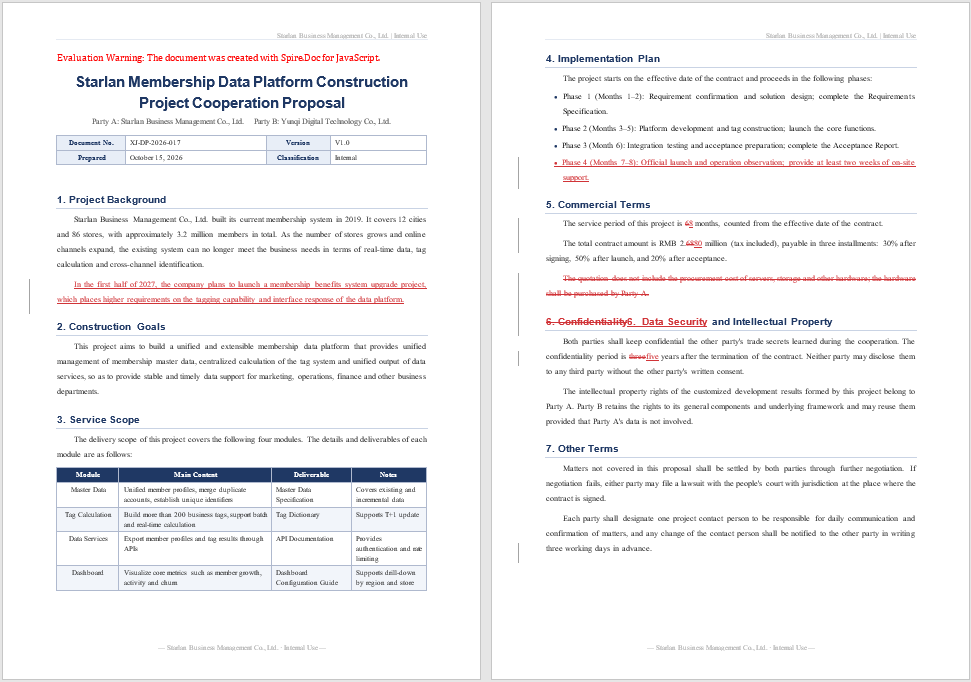
On the left is the default comparison: the header shows the change between "Internal Use" and "Review Draft", and the preparation date and the notes of the "Tag Calculation" row in the document info table are marked as revisions. On the right, with the three ignore options enabled, the header returns to the original text and the changes in the table no longer generate revision marks; the table keeps the original wording.
Compare Text Differences by Character
By default the comparison works word by word, so a replacement is recorded as whole words. In the sample, the confidentiality period is changed from "three" to "five", which is recorded as "Delete three" and "Insert five". With character-level comparison, only the characters that are the same before and after are kept as common content; the same change becomes "Delete thre" and "Insert fiv", and when several passages are rewritten at once, the number of scattered entries increases noticeably.
const options = new docModule.CompareOptions();

// Compare text by character, so that differences are located down to a single character
options.TextCompareLevel = docModule.TextDiffMode.Char;

original.Compare({ document: revised, author: 'Contract Review', options });
After Formatting Is Ignored, the Result Uses the Original Formatting
With IgnoreFormatting enabled, the result document no longer contains formatting revisions, and the affected paragraphs keep the font of the original; font changes made in the revised document are not written into the result. In the sample, the "7. Other Terms" heading is changed from Arial to Georgia in the revised version; with this option enabled, the result document still shows the original Arial.
const options = new docModule.CompareOptions();

// Compare text only; formatting changes do not generate revision marks
options.IgnoreFormatting = true;

original.Compare({ document: revised, author: 'Contract Review', options });
When the layout of the revised version has to be reflected in the result, do not enable this option; let the formatting differences be kept as revisions instead.
Extract and Export a List of Differences
Extracting and exporting a list of differences is based on DifferRevisions. Tracked changes are suitable for confirming items one by one in Word, while batch scenarios need a searchable list: DifferRevisions groups the revisions produced by the comparison by type, so the inserted, deleted, moved-to and moved-from content can be taken out separately and assembled into text for export.
| Member | Effect |
|---|---|
new DifferRevisions(doc) |
Creates a revision collection based on the compared document |
InsertRevisions |
The collection of inserted content |
DeleteRevisions |
The collection of deleted content |
MoveToRevisions |
The collection of content moved to another position |
MoveFromRevisions |
The collection of content moved from another position |
All four collections provide a Count property and a get(i) method, which take the elements out one by one by index.
The specific steps are as follows:
- Load the font and the two documents and complete the comparison.
- Create
DifferRevisionsbased on the compared document. - Iterate through the four revision collections in turn, take out the text objects and read their text.
- Assemble the result into tab-separated text, write it into the VFS, and save the comparison result document as well.
- Download the result document and the list file separately.
The code for extracting the list of differences is as follows:
function App() {
  const extractDifferences = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    await window.spire.FetchFileToVFS('Original.docx', '', `${process.env.PUBLIC_URL}/data/`);
    await window.spire.FetchFileToVFS('Revised.docx', '', `${process.env.PUBLIC_URL}/data/`);

    const original = new docModule.Document();
    original.LoadFromFile('Original.docx');

    const revised = new docModule.Document();
    revised.LoadFromFile('Revised.docx');

    original.Compare(revised, 'Contract Review');

    // Create the revision collections based on the compared document
    const revisions = new docModule.DifferRevisions(original);
    const rows = [];

    const collect = (collection, label) => {
      for (let i = 0; i < collection.Count; i++) {
        const item = collection.get(i);
        // The revision collections contain both paragraphs and text objects; take only text objects here
        if (item.DocumentObjectType !== docModule.DocumentObjectType.TextRange) continue;
        const text = docModule.TextRange.Convert(item).Text.trim();
        if (text) rows.push(`${label}\t${text}`);
      }
    };

    collect(revisions.InsertRevisions, 'Insert');
    collect(revisions.DeleteRevisions, 'Delete');
    collect(revisions.MoveToRevisions, 'Move To');
    collect(revisions.MoveFromRevisions, 'Move From');

    // The first column is the revision type and the second column is the revision content
    const report = `Type\tContent\r\n${rows.join('\r\n')}\r\n`;
    window.dotnetRuntime.Module.FS.writeFile('CompareReport.txt', report);

    // The comparison result and the list are generated from the same comparison
    original.SaveToFile({ fileName: 'CompareResult.docx', fileFormat: docModule.FileFormat.Docx2013 });

    revisions.Dispose();
    revised.Dispose();
    original.Dispose();

    // Download the result document and the list file in turn
    const outputs = [
      ['CompareResult.docx', 'application/vnd.openxmlformats-officedocument.wordprocessingml.document'],
      ['CompareReport.txt', 'text/plain;charset=utf-8'],
    ];
    for (const [fileName, mime] of outputs) {
      const fileArray = window.dotnetRuntime.Module.FS.readFile(fileName);
      const blob = new Blob([fileArray], { type: mime });
      const url = URL.createObjectURL(blob);
      const a = document.createElement('a');
      a.href = url;
      a.download = fileName;
      a.click();
      URL.revokeObjectURL(url);
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Extract a List of Word Document Differences</h1>
      <button onClick={extractDifferences}>Extract Differences</button>
    </div>
  );
}

export default App;
The exported list of differences is shown below, with 12 insertions and 8 deletions:
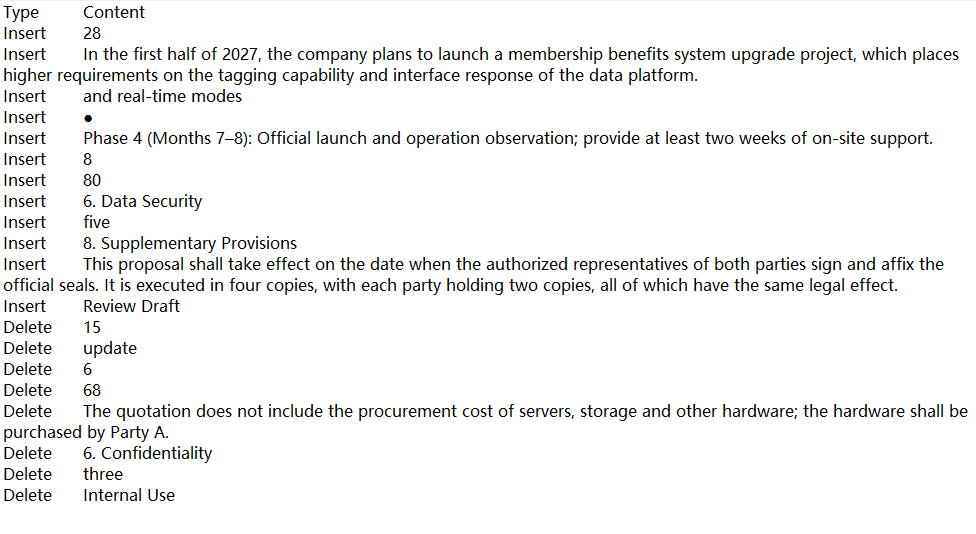
The entries are arranged in the order of the revision collections, with insertions first and deletions after. The preparation date is listed as "Insert 28" and "Delete 15"; the rewrite of the section heading is likewise split into "Delete 6. Confidentiality" and "Insert 6. Data Security"; the bullet marker "●" before the new paragraph and the body of Phase 4 each occupy a row as well.
Object Types and Text Extraction in the Revision Collections
The elements of the revision collections are document objects, which may be TextRange or Paragraph. TextRange.Convert() accepts only text objects and throws a cast error for paragraph objects; paragraphs should be read with Paragraph.Convert() instead. The example takes only text objects according to DocumentObjectType, so that one change occupies only one row:
for (let i = 0; i < collection.Count; i++) {
  const item = collection.get(i);

  // Text object: read the text with TextRange.Convert
  if (item.DocumentObjectType === docModule.DocumentObjectType.TextRange) {
    const text = docModule.TextRange.Convert(item).Text.trim();
  }

  // Paragraph object: read the text with Paragraph.Convert
  if (item.DocumentObjectType === docModule.DocumentObjectType.Paragraph) {
    const paragraphText = docModule.Paragraph.Convert(item).Text.trim();
  }
}
Moving a Paragraph Is Recorded as an Insertion and a Deletion
When a passage is moved forward or backward as a whole, the comparison usually records it as one deletion plus one insertion; in the tests, MoveToRevisions and MoveFromRevisions stay empty. The list is therefore dominated by the insertion and deletion types, and iterating the move collections is mainly a completeness check, so that nothing is missed when move revisions are produced:
// The move collections may be empty; no special check is needed before iterating, since the loop does not run when Count is 0
collect(revisions.MoveToRevisions, 'Move To');
collect(revisions.MoveFromRevisions, 'Move From');
FAQ
Do the files have to be uploaded to a server when comparing Word documents
Not in the usage described in this article. Spire.Doc for JavaScript runs in the browser with WebAssembly, the two documents are read and written locally through the virtual file system (VFS), and loading, comparison and saving all happen locally; the library itself does not send the files to a server. Whether the files eventually leave the device depends on the code you add to the page.
Why do numbers appear run together in the result document, for example "2.6880"
Cause: The tracked change places the deleted "68" and the inserted "80" next to each other at the same position. The deleted part is struck through and the inserted part is underlined, so at a small font size the two are easily read as one number; the "68 months" in the service period is the same case.
Solution: Check the changes one by one with the list of differences. The list splits the same change into two rows, so the old and the new values are clear at a glance:
// The same change is split into two rows in the list
// Delete    68
// Insert    80
Does the comparison require the two documents to have exactly the same formatting
No. The default comparison checks content and formatting together, and differences in fonts, paragraph spacing and so on are recorded as formatting revisions without affecting the identification of text differences. When those differences are not the focus of the review, enable IgnoreFormatting so that the list keeps only the text changes.
const options = new docModule.CompareOptions();
options.IgnoreFormatting = true;
original.Compare({ document: revised, author: 'Contract Review', options });
Why does the result still use the original font after formatting is ignored
Cause: IgnoreFormatting only stops formatting revisions from being recorded; the comparison result is still based on the original, and font adjustments made in the revised document are not written into the result. In the sample, the "7. Other Terms" heading is changed from Arial to Georgia, and with this option enabled the result document still shows Arial.
Solution: When the layout of the revised version has to be reflected in the result, keep the option at its default value and let the formatting differences be kept as revisions:
const options = new docModule.CompareOptions();
// Keep the formatting differences and let the reviewer confirm them one by one
options.IgnoreFormatting = false;
original.Compare({ document: revised, author: 'Contract Review', options });
Why do fragments such as "Delete thre" and "Insert fiv" appear after comparing by character
Cause: Word-by-word comparison records a replacement as whole words, so the change from "three" to "five" is recorded as "Delete three" and "Insert five". Character-level comparison compares character by character; the trailing "e" that is the same before and after is kept as common content, and the remaining "thre" and "fiv" become separate entries. When several lines in the same paragraph are rewritten at the same time, there are more such scattered fragments.
Solution: When the readability of the list matters most, keep the default TextDiffMode.Word; when the difference really has to be located down to a single character, switch to TextDiffMode.Char:
const options = new docModule.CompareOptions();

// Finer granularity: differences are located down to a single character
options.TextCompareLevel = docModule.TextDiffMode.Char;
original.Compare({ document: revised, author: 'Contract Review', options });
Get a Free License
Spire.Doc for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Accept or Reject Tracked Changes in Word with JavaScript in React
2026-11-07 05:18:15 Written by Amy ZhaoA Word document written by several people usually records its changes as revisions: inserted content is underlined, deleted content is kept with strikethrough, and formatting adjustments are marked as well. When the document is finalized, these revisions have to be resolved. Accepting a revision confirms the change, and the inserted content becomes part of the body text; rejecting a revision undoes the change, and the document returns to its state before the edit. Once the revisions have been processed, the revision records are cleared and the document can circulate as a formal version.
This article uses Spire.Doc for JavaScript to accept and reject revisions in the browser. The document is loaded through the virtual file system (VFS); when processing is finished, it is saved and downloaded directly. The whole process runs on the client side with WebAssembly, with no Office installation and no backend service required.
This article covers three features:
- Accept All Revisions in a Word Document
- Reject All Revisions in a Word Document
- Check Whether a Document Still Contains Unprocessed Revisions
For installation and project setup, refer to Integrating Spire.Doc for JavaScript in a React Project. The examples below assume that Spire.Doc is installed and the WebAssembly module is initialized.
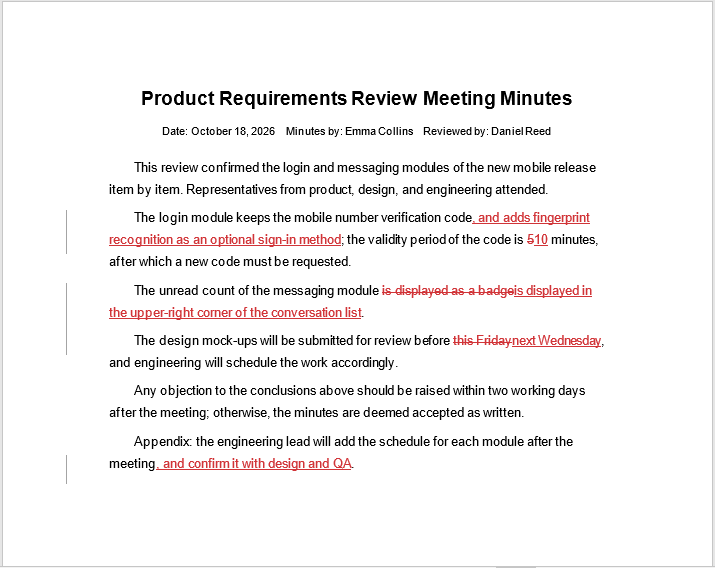
The sample document used in this article is a set of meeting minutes; its insertions, deletions, and replacements were all added by the reviewer during the review.
The meeting minutes with tracked changes:
Accept All Revisions in a Word Document
To accept all revisions in a Word document, call the Document.AcceptChanges() method. The method walks through the revision records in the document and handles each revision type separately; when it finishes, no revision marks remain in the document:
| Revision type | Result after accepting |
|---|---|
Insertion (RevisionType.Insertion) |
The inserted content is kept and becomes part of the body text |
Deletion (RevisionType.Deletion) |
The deleted content is removed permanently |
Format change (RevisionType.FormatChange) |
The changed formatting is adopted |
Move (RevisionType.Moving) |
The content stays at its new position |
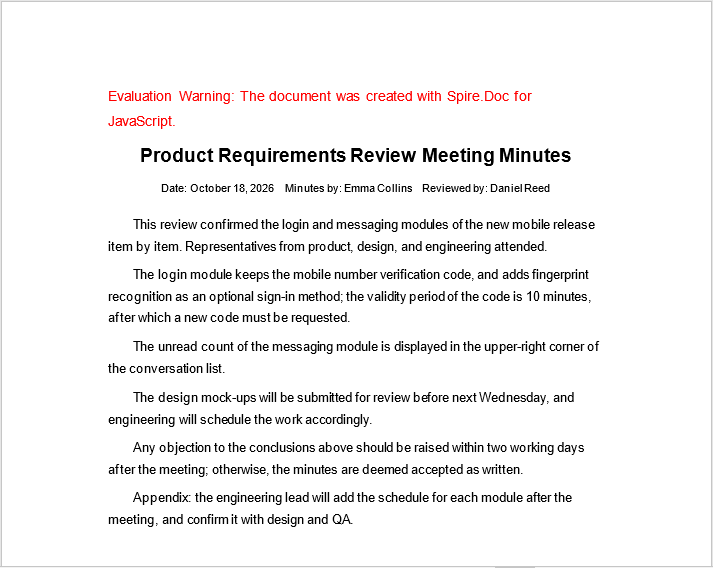
In the sample document, the reviewer changed the verification code validity period from 5 minutes to 10 minutes and moved the submission deadline for the design mock-ups from this Friday to next Wednesday. The code below loads the document and accepts all revisions; in the result file, the inserted content is kept and the deleted content is gone.
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the font, read the sample document into the VFS and load it as a
Document. - Call
Document.AcceptChanges()to accept all revisions in the document. - Save the result file with
SaveToFile(). - Read the result file from the VFS and trigger a browser download.
The code for accepting all revisions in a Word document is as follows:
function App() {
  const acceptChanges = async () => {
    // Get the Spire.Doc WASM module
    const wasmModule = window.wasmModule?.spiredoc;

    // Check if the module is ready
    if (!wasmModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the font and the document to be processed
    await window.spire.FetchFileToVFS('Sample.docx', '', `${process.env.PUBLIC_URL}/data/`);

    // Create a Document instance and load the document
    const doc = new wasmModule.Document();
    doc.LoadFromFile('Sample.docx');

    // Accept all revisions in the document
    doc.AcceptChanges();

    // Save the result file
    const outputFileName = 'AcceptChanges.docx';
    doc.SaveToFile({ fileName: outputFileName, fileFormat: wasmModule.FileFormat.Docx2013 });
    doc.Dispose();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Accept All Revisions in a Word Document</h1>
      <button onClick={acceptChanges}>
        Accept Revisions
      </button>
    </div>
  );
}

export default App;
The document after accepting all revisions:
Reject All Revisions in a Word Document
To reject all revisions in a Word document, call the Document.RejectChanges() method. The method also walks through the revision records in the document, but in the opposite direction: every change is undone, and the document returns to the state it had before the revisions were made:
| Revision type | Result after rejecting |
|---|---|
Insertion (RevisionType.Insertion) |
The inserted content is removed and the document returns to its state before the insertion |
Deletion (RevisionType.Deletion) |
The deleted content is restored to the body text |
Format change (RevisionType.FormatChange) |
The formatting is restored to what it was before the change |
Move (RevisionType.Moving) |
The content returns to its original position |
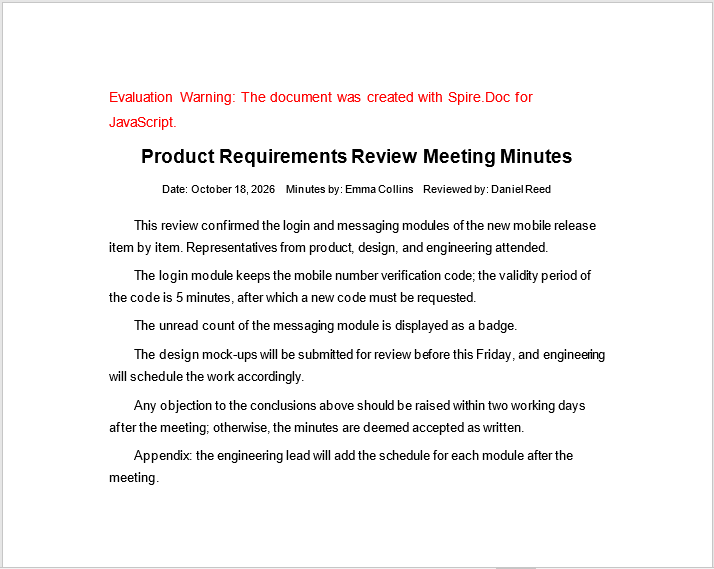
The code below loads the same meeting minutes, rejects all revisions and saves the result; in the result file every change is undone and the original text is restored.
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the font, read the sample document into the VFS and load it as a
Document. - Call
Document.RejectChanges()to reject all revisions in the document. - Save the result file with
SaveToFile(). - Read the result file from the VFS and trigger a browser download.
The code for rejecting all revisions in a Word document is as follows:
function App() {
  const rejectChanges = async () => {
    // Get the Spire.Doc WASM module
    const wasmModule = window.wasmModule?.spiredoc;

    // Check if the module is ready
    if (!wasmModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the font and the document to be processed
    await window.spire.FetchFileToVFS('Sample.docx', '', `${process.env.PUBLIC_URL}/data/`);

    // Create a Document instance and load the document
    const doc = new wasmModule.Document();
    doc.LoadFromFile('Sample.docx');

    // Reject all revisions in the document
    doc.RejectChanges();

    // Save the result file
    const outputFileName = 'RejectChanges.docx';
    doc.SaveToFile({ fileName: outputFileName, fileFormat: wasmModule.FileFormat.Docx2013 });
    doc.Dispose();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Reject All Revisions in a Word Document</h1>
      <button onClick={rejectChanges}>
        Reject Revisions
      </button>
    </div>
  );
}

export default App;
The document after rejecting all revisions:
Check Whether a Document Still Contains Unprocessed Revisions
To check whether a document still contains unprocessed revisions, read the Document.HasChanges property. The property is read-only: it returns true when revision records exist in the document, and false after all revisions have been accepted or rejected.
In batch processing, this property can decide whether an accept or reject operation is required: check first whether the document contains revisions, then process it according to the business rules, which avoids redundant writes to documents that have no revisions. The code below reads the property after loading the document, accepts all revisions only when revisions exist, and then saves the result.
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the font, read the sample document into the VFS and load it as a
Document. - Read the
Document.HasChangesproperty to check whether unprocessed revisions remain in the document. - When revisions exist, call
Document.AcceptChanges()to process them all, then save the result file. - Read the result file from the VFS and trigger a browser download.
The code for checking whether a document still contains unprocessed revisions is as follows:
function App() {
  const checkChanges = async () => {
    // Get the Spire.Doc WASM module
    const wasmModule = window.wasmModule?.spiredoc;

    // Check if the module is ready
    if (!wasmModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the font and the document to be processed
    await window.spire.FetchFileToVFS('Sample.docx', '', `${process.env.PUBLIC_URL}/data/`);

    // Create a Document instance and load the document
    const doc = new wasmModule.Document();
    doc.LoadFromFile('Sample.docx');

    // Check whether unprocessed revisions remain in the document
    if (doc.HasChanges) {
      // Accept all revisions when revisions exist
      doc.AcceptChanges();
    }

    // The property becomes false after the revisions have been processed
    console.log(doc.HasChanges);

    // Save the result file
    const outputFileName = 'CheckChanges.docx';
    doc.SaveToFile({ fileName: outputFileName, fileFormat: wasmModule.FileFormat.Docx2013 });
    doc.Dispose();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Check Whether a Document Still Contains Unprocessed Revisions</h1>
      <button onClick={checkChanges}>
        Check Revisions
      </button>
    </div>
  );
}

export default App;
FAQ
Why do revision marks still appear after revisions have been accepted
Accepting revisions modifies the document object in memory; if the result file is not saved, or if the original file rather than the processed file is opened, the revision marks remain in the document. In addition, the "Show Markup" option in Word only controls how revisions are displayed and does not change the revision records already saved in the document. Save the processed document as a new file, then open that file to confirm that the revisions have been cleared.
What is the difference between accepting and rejecting revisions
Accepting revisions confirms the reviewer's changes: inserted content is kept as body text, deleted content is removed, and formatting changes adopt the changed result. Rejecting revisions undoes those changes: inserted content is removed, deleted content is restored, and formatting returns to its state before the change. Both operations clear the revision records in the document, after which the document no longer distinguishes between the reviewer and the body text.
Can individual revisions be accepted or rejected one at a time
The current JavaScript binding provides the document-level Document.AcceptChanges() and Document.RejectChanges() methods. Document does not provide a collection for reading revisions one by one, nor an interface for accepting or rejecting a single revision. When a revision-by-revision decision is needed, handle it first in the Reviewing pane in Word, and then use the methods in this article to accept or reject the remaining revisions as a whole.
Are the author and time of revisions kept after accepting or rejecting them
No. When revisions are accepted or rejected, the revision records, together with the author and time recorded in them, are cleared, and the saved file no longer contains this information. If the origin of the changes has to be traced, keep the original document before processing, or archive the processing result and the original document separately.
Does calling AcceptChanges() on a document without revisions raise an error
No error is raised. Document.AcceptChanges() executes normally when the document contains no revision records, the document content stays unchanged, and the document can still be saved afterwards. To skip such documents in batch processing, read the Document.HasChanges property first and decide accordingly.
Get a Free License
Spire.Doc for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Count Words, Characters, Paragraphs, Lines and Pages in Word Documents with JavaScript in React
2026-11-06 01:07:13 Written by Amy ZhaoWord count, character count, paragraph count, line count and page count measure the content size and the layout result of a Word document: the word count reflects the total volume of text, the character count is used to account for length, the paragraph count shows the structure of the content, and the line count and page count are directly related to the print layout. When this kind of counting is performed on a web page, uploading the file to a server adds an extra transfer, while relying on desktop software makes it difficult to fit the process into an automated workflow.
This article reads these statistics in the browser with Spire.Doc for JavaScript. The whole process runs in the browser on WebAssembly, requires no Office installation and depends on no backend service, and the file always remains on the user's device.
This article covers the following topics:
- Count the Words, Characters, Paragraphs, Lines and Pages of a Word Document
- Count the Words and Characters of a Specified Paragraph
For installation and project setup, refer to Integrating Spire.Doc for JavaScript in a React Project. The examples below assume that Spire.Doc is installed and the WebAssembly module is initialized.
Count the Words, Characters, Paragraphs, Lines and Pages of a Word Document
The word count, character count, paragraph count, line count and page count of a Word document are read mainly through Document.BuiltinDocumentProperties. The property returns a BuiltinDocumentProperties object, and the statistics correspond to its properties as follows:
| Property | Meaning |
|---|---|
BuiltinDocumentProperties.WordCount |
Word count |
BuiltinDocumentProperties.CharCount |
Character count (excluding spaces) |
BuiltinDocumentProperties.CharCountWithSpace |
Character count (including spaces) |
BuiltinDocumentProperties.ParagraphCount |
Paragraph count |
BuiltinDocumentProperties.LinesCount |
Line count |
BuiltinDocumentProperties.PageCount |
Page count |
The statistics in the built-in properties come from the statistics saved inside the document. For a newly created document, or a document generated by another tool into which statistics have not yet been written, the word count, character count and paragraph count may be 0, so the example calls Document.UpdateWordCount() before reading to recalculate these three values. The line count and page count are layout statistics; UpdateWordCount() does not recalculate them, and their values depend on the statistics already saved in the document.
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the sample document and the font into the virtual file system (VFS), create a
Documentobject and load the file. - Call
Document.UpdateWordCount()to recalculate the word count, character count and paragraph count. - Read each statistic through
Document.BuiltinDocumentProperties. - Assemble the statistics as text, save them as a TXT file and trigger a browser download.
The code for counting the words, characters, paragraphs, lines and pages of a Word document is as follows:
function App() {
  const countDocument = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Make sure the WASM module has fully loaded
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the sample document and the font into VFS
    await window.spire.FetchFileToVFS('Sample Document.docx', "", `${process.env.PUBLIC_URL}/data/`);
    await window.spire.FetchFileToVFS('ARIALUNI.TTF', "/Library/Fonts/", `${process.env.PUBLIC_URL}/font/`);

    // Create a Document instance and load the document
    const doc = new docModule.Document();
    doc.LoadFromFile('Sample Document.docx');

    // Recalculate the word count, character count and paragraph count
    doc.UpdateWordCount();

    // Get the built-in document properties
    const properties = doc.BuiltinDocumentProperties;

    // Read each statistic
    const wordCount = properties.WordCount;
    const charCount = properties.CharCount;
    const charCountWithSpace = properties.CharCountWithSpace;
    const paragraphCount = properties.ParagraphCount;
    const lineCount = properties.LinesCount;
    const pageCount = properties.PageCount;

    // Assemble the results
    const report = [
      'Word count: ' + wordCount,
      'Characters (no spaces): ' + charCount,
      'Characters (with spaces): ' + charCountWithSpace,
      'Paragraphs: ' + paragraphCount,
      'Lines: ' + lineCount,
      'Pages: ' + pageCount,
    ].join('\r\n');

    doc.Dispose();

    // Save the results as a TXT file and trigger the download
    const outputFileName = 'Word Count Results.txt';
    const blob = new Blob([report], { type: 'text/plain;charset=utf-8' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Count Word Document Statistics</h1>
      <button onClick={countDocument}>
        Count Document Statistics
      </button>
    </div>
  );
}

export default App;
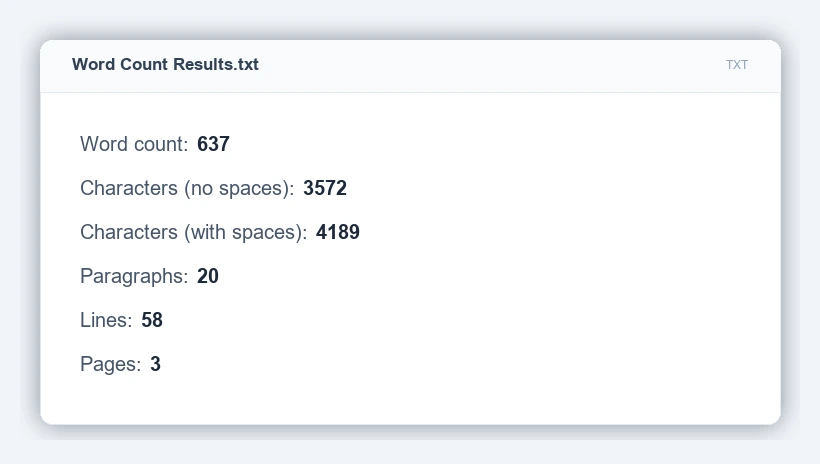
After the code above runs, the downloaded "Word Count Results.txt" contains the following:
Count the Words and Characters of a Specified Paragraph
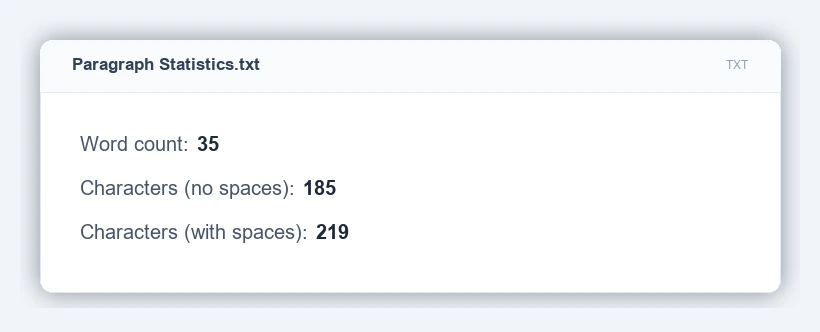
The words and characters of a specified paragraph in a Word document can be read with the three properties Paragraph.WordCount, Paragraph.CharCount and Paragraph.CharCountIncludeSpace. Unlike the built-in properties of the whole document, paragraph-level statistics are calculated directly from the paragraph content, and the document statistics do not have to be updated before reading.
| Property | Meaning |
|---|---|
Paragraph.WordCount |
Word count of the current paragraph |
Paragraph.CharCount |
Character count of the current paragraph, excluding spaces |
Paragraph.CharCountIncludeSpace |
Character count of the current paragraph, including spaces |
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the sample document and the font into the virtual file system (VFS), create a
Documentobject and load the file. - Get the second paragraph in the first section through
Document.Sections.get_Item(0).Paragraphs.get_Item(1). - Read the statistics of that paragraph through
Paragraph.WordCount,Paragraph.CharCountandParagraph.CharCountIncludeSpace. - Assemble the statistics as text, save them as a TXT file and trigger a browser download.
The code for counting the words and characters of a specified paragraph in a Word document is as follows:
function App() {
  const countParagraph = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Make sure the WASM module has fully loaded
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the sample document and the font into VFS
    await window.spire.FetchFileToVFS('Sample Document.docx', "", `${process.env.PUBLIC_URL}/data/`);
    await window.spire.FetchFileToVFS('ARIALUNI.TTF', "/Library/Fonts/", `${process.env.PUBLIC_URL}/font/`);

    // Create a Document instance and load the document
    const doc = new docModule.Document();
    doc.LoadFromFile('Sample Document.docx');

    // Get the second paragraph in the first section (index starts at 0)
    const paragraph = doc.Sections.get_Item(0).Paragraphs.get_Item(1);

    // Read the words and characters of that paragraph
    const wordCount = paragraph.WordCount;
    const charCount = paragraph.CharCount;
    const charCountIncludeSpace = paragraph.CharCountIncludeSpace;

    // Assemble the results
    const report = [
      'Word count: ' + wordCount,
      'Characters (no spaces): ' + charCount,
      'Characters (with spaces): ' + charCountIncludeSpace,
    ].join('\r\n');

    doc.Dispose();

    // Save the results as a TXT file and trigger the download
    const outputFileName = 'Paragraph Statistics.txt';
    const blob = new Blob([report], { type: 'text/plain;charset=utf-8' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Paragraph Statistics</h1>
      <button onClick={countParagraph}>
        Count Paragraph Statistics
      </button>
    </div>
  );
}

export default App;
After the code above runs, the downloaded "Paragraph Statistics.txt" contains the following:
FAQ
Why is the calculated word count or character count 0
Cause: The statistics in the built-in properties come from the statistics saved inside the document. For a newly created document, or a document generated by some tools without statistics written into it, the word count, character count and paragraph count read back may be 0.
Solution: The example calls Document.UpdateWordCount() before reading, which recalculates these three values from the current content; the call updates the statistics without modifying the document body.
Why do the line count and page count differ from what Word displays
Cause: The line count and page count are layout statistics kept in the built-in properties of the document, and Document.UpdateWordCount() does not recalculate them, so the values returned are those already saved in the document. When the content has been edited but the document has not been saved again, these values may remain in their previous state and differ from what Word currently displays.
Solution: To verify them, open the "Word Count" dialog in Word; for the words and characters of a paragraph, read Paragraph.WordCount and Paragraph.CharCount directly.
What is the difference between the word count and the two character counts
Cause: The three statistics measure different things: WordCount returns the word count of the document, while CharCount and CharCountWithSpace return the character count without and with spaces respectively, both including punctuation.
Solution: When accounting for length or layout capacity, use the character count with spaces, that is, CharCountWithSpace.
How do I count the words and characters of other paragraphs
Cause: The indexes of Sections.get_Item() and Paragraphs.get_Item() both start at 0, and the Paragraphs.get_Item(1) in the example points to the second paragraph in the first section.
Solution: Change the index to count the corresponding paragraph; check Paragraphs.Count before reading to avoid an index out of range.
Get a Free License
Spire.Doc for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Technical documentation, API references and release notes are increasingly maintained in Markdown: it is easy to keep in a code repository, easy to review, and easy to compare between versions. For external delivery, however, the recipient usually needs a Word or PDF document. Copying and pasting into a desktop application loses the formatting, and tables and code blocks have to be rearranged by hand; converting on a server takes the source file off the user's device.
This article converts Markdown to Word documents and PDF documents in the browser with Spire.Doc for JavaScript. The library runs in the browser as a WebAssembly module, the source file is read through a virtual file system (VFS), and the conversion result is written back to the VFS before the download is triggered. The whole process requires neither an Office installation nor any backend service.
This article covers three features:
- Convert a Markdown Document to Word
- Convert a Markdown Document to PDF
- Use Template Styles to Convert Markdown to Word
For installation and project setup, refer to Integrating Spire.Doc for JavaScript in a React Project. The examples below assume that Spire.Doc is installed and the WebAssembly module is initialized. The sample Markdown source and the template document are placed in the public/data/ directory, and the font files in the public/static/font/ directory. To make them easy to run directly, the code for each feature is a complete single file, so the content of App.js can be replaced with it wholesale.
Convert a Markdown Document to Word
Spire.Doc for JavaScript loads the source file with Document.LoadFromFile(), and the second parameter specifies the file format. Pass FileFormat.Markdown when loading Markdown: the library parses headings, paragraphs, lists, tables, quotes, code blocks and images according to Markdown syntax rules, and turns them into the corresponding Word document objects.
The syntax used in the source file and the styles applied after conversion correspond as follows:
| Markdown syntax | Style applied after conversion | Notes |
|---|---|---|
# to ###### |
Heading 1 to Heading 6 | The six heading levels map to the six built-in heading styles respectively |
| Ordinary paragraphs | Normal | Paragraph text and inline formatting such as bold and italic are kept |
> quotes |
Quote | Converted to an indented quote paragraph |
- lists, 1. lists |
List paragraphs | Bulleted and numbered lists become automatically numbered items |
| Pipe tables | Word tables | The first row becomes the header, and cells carry thin borders |
| Backtick inline code | InlineCode | A character-level style that affects only the marked text |
| Fenced code blocks | FencedCode plus the language name | A code block marked js, for example, is given FencedCodejs |
| Indented code blocks | FencedCode | Code blocks without a language label |
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the Markdown source file into the virtual file system (VFS).
- Create a
Documentinstance and load the source file withLoadFromFile()asFileFormat.Markdown. - Save the document with
SaveToFile()as a DOCX file. - Read the result file from the VFS and trigger its browser download.
The code for converting a Markdown document to a Word document is as follows:
function App() {
  const convertToWord = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Make sure the WASM module has fully loaded
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the Markdown source and the images it references into VFS
    await window.spire.FetchFileToVFS('Sample.md', "", `${process.env.PUBLIC_URL}/data/`);
    await window.spire.FetchFileToVFS('pipeline.png', "", `${process.env.PUBLIC_URL}/data/`);
    await window.spire.FetchFileToVFS('msyh.ttc', "/Library/Fonts/", `${process.env.PUBLIC_URL}/static/font/`);
    await window.spire.FetchFileToVFS('msyhbd.ttc', "/Library/Fonts/", `${process.env.PUBLIC_URL}/static/font/`);

    // Create a Document instance and load the source file as Markdown
    const doc = new docModule.Document();
    doc.LoadFromFile('Sample.md', docModule.FileFormat.Markdown);

    // Save as a Word document
    const outputFileName = 'MarkdownToWord.docx';
    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2016 });
    doc.Dispose();

    // Read the generated file from VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert Markdown to Word</h1>
      <button onClick={convertToWord}>
        Convert to Word
      </button>
    </div>
  );
}

export default App;
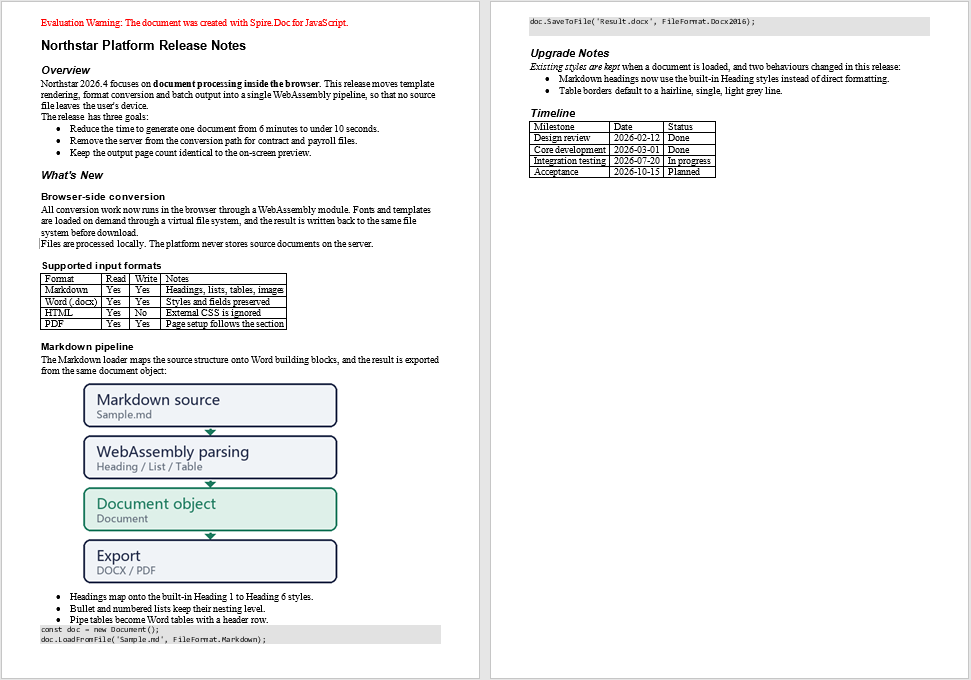
The converted Word document is shown below; the headings, lists, quotes, tables and code blocks have all been restored according to the structure of the source file:
Word document converted with the default styles
Convert a Markdown Document to PDF
Once Markdown has been loaded, the result is a complete Word document object, so the same object can be saved as DOCX or exported directly to PDF without reading the source file again. For export, simply change the fileFormat of SaveToFile() to FileFormat.PDF. The page size and margins follow the section settings of the document, and the pagination is determined by the layout computed during export.
Unlike DOCX, PDF requires the text to be genuinely rasterized, so before export the fonts used by the document should be loaded into the font directory of the virtual file system; the examples place the fonts in /Library/Fonts/.
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the Markdown source file and the font files into the virtual file system (VFS).
- Create a
Documentinstance and load the source file withLoadFromFile()asFileFormat.Markdown. - Export the document with
SaveToFile()as a PDF file. - Read the result file from the VFS and trigger its browser download.
The code for converting a Markdown document to a PDF document is as follows:
function App() {
  const convertToPdf = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Make sure the WASM module has fully loaded
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the Markdown source and the fonts into VFS
    await window.spire.FetchFileToVFS('Sample.md', "", `${process.env.PUBLIC_URL}/data/`);
    await window.spire.FetchFileToVFS('pipeline.png', "", `${process.env.PUBLIC_URL}/data/`);
    await window.spire.FetchFileToVFS('msyh.ttc', "/Library/Fonts/", `${process.env.PUBLIC_URL}/static/font/`);
    await window.spire.FetchFileToVFS('msyhbd.ttc', "/Library/Fonts/", `${process.env.PUBLIC_URL}/static/font/`);

    // Create a Document instance and load the source file as Markdown
    const doc = new docModule.Document();
    doc.LoadFromFile('Sample.md', docModule.FileFormat.Markdown);

    // Export as a PDF document
    const outputFileName = 'MarkdownToPdf.pdf';
    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.PDF });
    doc.Dispose();

    // Read the generated file from VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert Markdown to PDF</h1>
      <button onClick={convertToPdf}>
        Convert to PDF
      </button>
    </div>
  );
}

export default App;
The PDF document exported from the same Markdown is shown below:
PDF document exported from the same Markdown
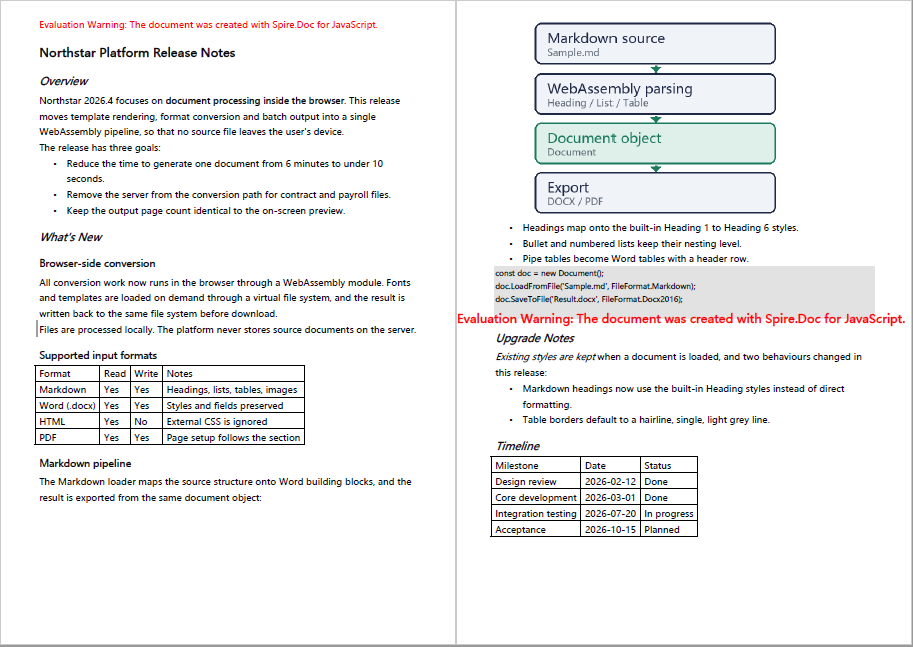
Use Template Styles to Convert Markdown to Word
The document produced by the default rules uses the built-in styles, whose fonts, color schemes and line spacing are generic in appearance. In actual delivery, a document often has to meet the layout requirements of a company or department: which font size the headings use, which line spacing the body text uses, whether a separator line appears below a heading. These requirements have usually already been organized into a Word template; all that is needed is to copy the styles of the template onto the conversion result.
The current JavaScript version does not provide a method that copies all template styles at once, so the example handles it as follows: first find the style of the same name in the target document, then copy the character formatting and paragraph formatting of the template style onto it item by item. The style names in the template therefore have to match the names of the styles produced by the conversion; the common correspondences are as follows:
| Template style name | Affected content | Settings in the sample template |
|---|---|---|
| Normal | Body paragraphs | Microsoft YaHei 10.5 pt, grey text, 1.35 line spacing |
| Heading 1 | # level-one headings |
18 pt bold, dark blue, separator line below |
| Heading 2 | ## level-two headings |
14 pt bold, dark green |
| Heading 3 | ### level-three headings |
12 pt bold, dark blue |
| Quote | > quote paragraphs |
10 pt italic, dark green, left indent |
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the Markdown source file and the template document into the virtual file system (VFS).
- Create a
Documentinstance and load the source file withLoadFromFile()asFileFormat.Markdown. - Create another
Documentinstance and load the template document, then take its styles by name. - Use the
copyStyle()helper to copy the character formatting and paragraph formatting of each template style onto the style of the same name in the target document. - Save the result file with
SaveToFile(), then read it from the VFS and trigger the download.
The code for converting Markdown with the template styles is as follows:
// Names of the styles to copy from the template; they must match the styles applied by the Markdown conversion
const TEMPLATE_STYLES = ['Normal', 'Heading 1', 'Heading 2', 'Heading 3', 'Quote'];

// Copy one style from the template document to the style of the same name in the target document
function copyStyle(src, dst) {
  // Character formatting: font, font size, bold, italic, text color
  const sf = src.CharacterFormat;
  const df = dst.CharacterFormat;
  df.FontName = sf.FontName;
  df.FontSize = sf.FontSize;
  df.Bold = sf.Bold;
  df.Italic = sf.Italic;
  df.TextColor = sf.TextColor;

  // Paragraph formatting: spacing before and after, line spacing, indent, alignment and pagination control
  const sp = src.ParagraphFormat;
  const dp = dst.ParagraphFormat;
  dp.BeforeSpacing = sp.BeforeSpacing;
  dp.AfterSpacing = sp.AfterSpacing;
  dp.LineSpacing = sp.LineSpacing;
  dp.LineSpacingRule = sp.LineSpacingRule;
  dp.LeftIndent = sp.LeftIndent;
  dp.FirstLineIndent = sp.FirstLineIndent;
  dp.HorizontalAlignment = sp.HorizontalAlignment;
  dp.KeepFollow = sp.KeepFollow;

  // Paragraph borders: the separator line below a heading
  const sb = sp.Borders.Bottom;
  const db = dp.Borders.Bottom;
  db.BorderType = sb.BorderType;
  db.LineWidth = sb.LineWidth;
  db.Color = sb.Color;
  db.Space = sb.Space;
}

function App() {
  const convertWithTemplate = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Make sure the WASM module has fully loaded
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the Markdown source and the template document into VFS
    await window.spire.FetchFileToVFS('Sample.md', "", `${process.env.PUBLIC_URL}/data/`);
    await window.spire.FetchFileToVFS('Template.docx', "", `${process.env.PUBLIC_URL}/data/`);
    await window.spire.FetchFileToVFS('msyh.ttc', "/Library/Fonts/", `${process.env.PUBLIC_URL}/static/font/`);
    await window.spire.FetchFileToVFS('msyhbd.ttc', "/Library/Fonts/", `${process.env.PUBLIC_URL}/static/font/`);

    // Load the source file as Markdown
    const doc = new docModule.Document();
    doc.LoadFromFile('Sample.md', docModule.FileFormat.Markdown);

    // Load the template document and take only its styles
    const template = new docModule.Document();
    template.LoadFromFile('Template.docx');

    // Copy each template style onto the style of the same name in the target document
    TEMPLATE_STYLES.forEach((name) => {
      const src = template.Styles.FindByName(name);
      const dst = doc.Styles.FindByName(name);
      if (src && dst) {
        copyStyle(src, dst);
      }
    });
    template.Dispose();

    // Save as a Word document
    const outputFileName = 'MarkdownToWordWithTemplate.docx';
    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2016 });
    doc.Dispose();

    // Read the generated file from VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert Markdown with Template Styles</h1>
      <button onClick={convertWithTemplate}>
        Convert and Apply Template Styles
      </button>
    </div>
  );
}

export default App;
The first page of the Word document after the template styles are applied is shown below; the headings, body text, quotes and tables all follow the fonts, color scheme and line spacing of the template:
First page of the Word document after applying the template styles
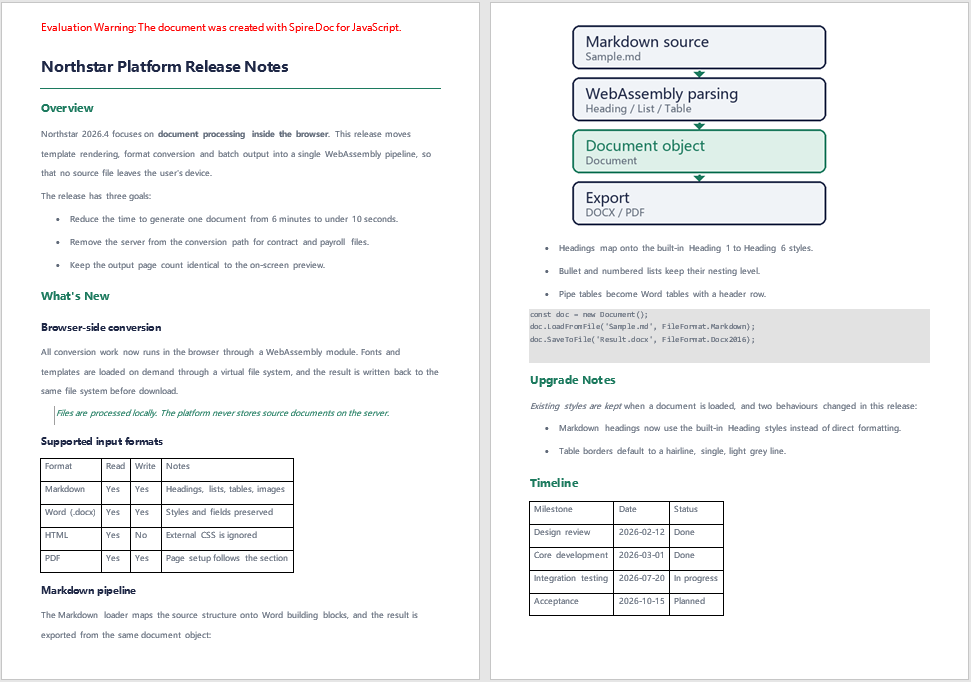
The Sample Markdown File
All three features share the same Sample.md, which is placed in the public/data/ directory. The sample is a product release note covering level-one to level-three headings, bulleted lists, quotes, pipe tables, fenced code blocks, inline code, images, and bold and italic text, so that the conversion result of each syntax in Word can be observed side by side.
Images are referenced by relative path; before conversion, the image files have to be loaded into the virtual file system under the same path as written in the Markdown.
The content of the sample Markdown file is as follows:
# Northstar Platform Release Notes
## Overview
Northstar 2026.4 focuses on **document processing inside the browser**. This release moves template rendering, format conversion and batch output into a single WebAssembly pipeline, so that no source file leaves the user's device.
The release has three goals:
- Reduce the time to generate one document from 6 minutes to under 10 seconds.
- Remove the server from the conversion path for contract and payroll files.
- Keep the output page count identical to the on-screen preview.
## What's New
### Browser-side conversion
All conversion work now runs in the browser through a WebAssembly module. Fonts and templates are loaded on demand through a virtual file system, and the result is written back to the same file system before download.
> Files are processed locally. The platform never stores source documents on the server.
### Supported input formats
| Format | Read | Write | Notes |
|---|---|---|---|
| Markdown | Yes | Yes | Headings, lists, tables, images |
| Word (.docx) | Yes | Yes | Styles and fields preserved |
| HTML | Yes | No | External CSS is ignored |
| PDF | Yes | Yes | Page setup follows the section |
### Markdown pipeline
The Markdown loader maps the source structure onto Word building blocks, and the result is exported from the same document object:

- Headings map onto the built-in Heading 1 to Heading 6 styles.
- Bullet and numbered lists keep their nesting level.
- Pipe tables become Word tables with a header row.
```js
const doc = new Document();
doc.LoadFromFile('Sample.md', FileFormat.Markdown);
doc.SaveToFile('Result.docx', FileFormat.Docx2016);
```
## Upgrade Notes
*Existing styles are kept* when a document is loaded, and two behaviours changed in this release:
- Markdown headings now use the built-in Heading styles instead of direct formatting.
- Table borders default to a hairline, single, light grey line.
## Timeline
| Milestone | Date | Status |
|---|---|---|
| Design review | 2026-02-12 | Done |
| Core development | 2026-03-01 | Done |
| Integration testing | 2026-07-20 | In progress |
| Acceptance | 2026-10-15 | Planned |
The template document Template.docx only provides styles; its body content does not take part in the conversion. The style names in the template have to match the names of the styles produced by the conversion (Normal, Heading 1, Heading 2, Heading 3, Quote); styles whose names do not match are not copied.
FAQ
Why is the first paragraph of the converted document a red line of English text
Cause: This line is an evaluation notice inserted by Spire.Doc for JavaScript when the file is saved. Its content is Evaluation Warning: The document was created with Spire.Doc for JavaScript., and it has nothing to do with the content of the source file.
Solution: The notice exists only in the evaluation version; once a license is applied, the saved file no longer contains this paragraph.
Why do the converted headings and body text not use the font and line spacing I expect
Cause: LoadFromFile() converts Markdown with the built-in styles — headings use Heading 1 to Heading 6 and body text uses Normal — and these styles themselves do not define the fonts and color schemes commonly used in corporate documents.
Solution: Organize the layout requirements into a Word template and copy the styles as described in Use Template Styles to Convert Markdown to Word; alternatively, after loading, modify the CharacterFormat and ParagraphFormat of the corresponding styles in doc.Styles directly.
Why do the entries after the first one in a multi-item ordered list end up merged into the first paragraph
Cause: The parser recognizes ordered lists by paragraph; when there is no blank line between items, the text of the second item onwards is treated as a continuation line of the first, and the number is kept in the paragraph as plain text.
Solution: Leave a blank line between items so that each one becomes an independently numbered list item; bulleted lists are not subject to this restriction and can be written consecutively:
1. First step.

2. Second step.

3. Third step.
Why are the images in the Markdown not displayed, or displayed exceptionally large
Cause: Images are read from the virtual file system by the path written in the Markdown; when the file has not been loaded into the VFS it cannot be embedded. Image size is converted from the original pixel dimensions at 96 dpi, so an image with a large pixel width may exceed the text width on an A4 page.
Solution: Load the image into the VFS first, under the same path as written in the Markdown:
await window.spire.FetchFileToVFS('pipeline.png', "", `${process.env.PUBLIC_URL}/data/`);
To specify a width, write the image as an HTML img tag; the width attribute is written into the document in pixels:
<img src="pipeline.png" width="360">
What should I do when the Chinese font in the exported PDF is wrong, or appears blank or as boxes
Cause: A DOCX records only font names, which Word resolves when the file is opened; PDF requires the text to be rendered as graphics, so when the font file has not been loaded, the export can only use a substitute font or leave the text blank.
Solution: Before exporting to PDF, load the fonts used by the document into the font directory of the virtual file system; the examples place them in /Library/Fonts/. When there are many Chinese fonts, it is advisable to load both the regular and the bold face:
await window.spire.FetchFileToVFS('msyh.ttc', "/Library/Fonts/", `${process.env.PUBLIC_URL}/static/font/`);
await window.spire.FetchFileToVFS('msyhbd.ttc', "/Library/Fonts/", `${process.env.PUBLIC_URL}/static/font/`);
Get a Free License
Spire.Doc for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Add a Table of Contents to an Existing Word Document with JavaScript in React
2026-09-18 06:15:33 Written by Amy ZhaoA more common situation in real-world work is a document that is already written and has a complete chapter structure, but no table of contents was generated at the time. There is no need to rearrange the content — adding a TOC field on top of the existing heading styles is enough to produce a complete table of contents with page numbers and hyperlinks. The table of contents is generated and saved entirely in the browser, so files such as contracts and proposals never have to be uploaded to a server, which removes one step from the handling process.
This article takes a "2026 Annual Product and Technology Report" as an example and introduces four ways to add a table of contents to an existing document. The sample is based on Spire.Doc for JavaScript. The library runs in the browser as a WebAssembly module, and reads and writes fonts and document files through a virtual file system (VFS).
Compared with creating a new document, adding a table of contents to an existing document involves two extra key steps: loading the original document from VFS with LoadFromFile, and specifying the position of the TOC paragraph with Paragraphs.Insert. AddParagraph always appends a new paragraph to the end of its section, so inserting the TOC field directly on it makes the table of contents appear at the end of the document, which is the most common problem with existing documents.
This article covers the following topics:
- Add a Table of Contents at the Start of the Document
- Add a Table of Contents at a Specified Position
- Add a Custom Table of Contents
- Update the Page Numbers of an Existing Table of Contents
For installation and project setup, refer to Integrating Spire.Doc for JavaScript in a React Project. The examples below assume that Spire.Doc is installed and the WebAssembly module is initialized, and that the sample document AddTocToExisting.docx is placed in the public/data/ directory of the project.
Add a Table of Contents at the Start of the Document
To add a table of contents at the start of the document, first write the TOC field into a new paragraph with AppendTOC, then move that paragraph to the very beginning of the document with Paragraphs.Insert(0, tocPara). AppendTOC takes a start level and an end level, and the table of contents collects only the headings that fall within that range:
| Usage | Scope |
|---|---|
AppendTOC(1, 3) |
Heading 1 to Heading 3 |
AppendTOC(1, 2) |
Heading 1 to Heading 2 |
AppendTOC(2, 3) |
Heading 2 to Heading 3 |
The example passes (1, 3), so the table of contents collects four chapters, ten second-level headings and two third-level headings, 16 entries in total. A page break is appended to the end of the TOC paragraph, so the existing content moves back by one page and the table of contents takes page 1 on its own.
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the body font
msyh.ttc, the bold fontmsyhbd.ttcand the sample documentAddTocToExisting.docxinto the virtual file system (VFS). - Create a
Documentobject, load the existing document withLoadFromFile, and get the first section. - Create a new paragraph, call
AppendTOC(1, 3)to write the TOC field, and append a page break withAppendBreak. - Move the TOC paragraph to the very beginning of the document with
Paragraphs.Insert(0, tocPara), and insert a "Table of Contents" heading paragraph above it. - Call
UpdateTableOfContentsto update the entries and page numbers, save the document withSaveToFile, and read the result from VFS to trigger the download.
The code for adding a table of contents at the start of the document is as follows:
function App() {
  const addTocAtStart = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Make sure the WASM module has fully loaded
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the fonts and the sample document into VFS
    await window.spire.FetchFileToVFS('msyh.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    await window.spire.FetchFileToVFS('msyhbd.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'AddTocToExisting.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Create a document instance and load the existing document
    const doc = new docModule.Document();
    doc.LoadFromFile({ fileName: inputFileName });

    // Get the first section of the document
    const section = doc.Sections.get_Item(0);

    // Create a new paragraph and insert the TOC field, collecting Heading 1 through Heading 3 entries
    const tocPara = section.AddParagraph();
    tocPara.AppendTOC(1, 3);

    // The TOC takes a page of its own, so the existing content starts on a new page
    tocPara.AppendBreak(docModule.BreakType.PageBreak);

    // Move the TOC paragraph to the very beginning of the document
    section.Paragraphs.Insert(0, tocPara);

    // TOC page header: the TOC entries carry no heading line, so a "Table of Contents" line is added here
    const titleFormat = new docModule.CharacterFormat(doc);
    titleFormat.FontName = 'Microsoft YaHei';
    titleFormat.FontSize = 18;
    titleFormat.Bold = true;
    titleFormat.TextColor = docModule.Color.FromArgb(31, 40, 70);
    const titlePara = section.AddParagraph();
    titlePara.AppendText('Table of Contents').ApplyCharacterFormat(titleFormat);
    titlePara.Format.AfterSpacing = 14;
    section.Paragraphs.Insert(0, titlePara);

    // Update the TOC to fill in entries and page numbers
    doc.UpdateTableOfContents();

    // Define the output file name and save
    const outputFileName = 'Add a TOC at the Start of the Document.docx';
    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });

    // Release resources
    doc.Dispose();

    // Read the generated file from VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add a Table of Contents at the Start of the Document</h1>
      <button onClick={addTocAtStart}>
        Generate
      </button>
    </div>
  );
}

export default App;
The table of contents is placed at the very beginning of the document and takes a page of its own, while the original cover, body text and footer page numbering stay unchanged. Because the table of contents occupies page 1, Chapter 1 of the body moves to page 3, and the page numbers in the table of contents are refreshed accordingly:
Table of contents page after adding a table of contents at the start of the document
Add a Table of Contents at a Specified Position
To add a table of contents at a specified position, only one thing changes: the index passed to Paragraphs.Insert is no longer 0 but the target position. The index is calculated in the order of the child objects in the body, and every paragraph and table takes one position, so the index in the paragraph collection cannot be used directly to find the insertion point. The example first walks Body.ChildObjects, finds the paragraph that has the Heading 1 style applied, and passes that object position to Paragraphs.Insert, so the table of contents lands before Chapter 1: the cover stays on page 1 and the table of contents starts on page 2.
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the body font
msyh.ttc, the bold fontmsyhbd.ttcand the sample documentAddTocToExisting.docxinto the virtual file system (VFS). - Create a
Documentobject, load the existing document, and get the first section. - Walk the
Body.ChildObjectsof the first section, find the position of the first Heading 1 paragraph, and use it as the insertion index for the table of contents. - Create a new paragraph, call
AppendTOC(1, 3)to write the TOC field and append a page break, insert it before Chapter 1 withParagraphs.Insert(index, tocPara), and add the "Table of Contents" heading paragraph. - Call
UpdateTableOfContentsto update the entries and page numbers, save the document, and read the result from VFS to trigger the download.
The code for adding a table of contents at a specified position is as follows:
function App() {
  const addTocAtPosition = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Make sure the WASM module has fully loaded
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the fonts and the sample document into VFS
    await window.spire.FetchFileToVFS('msyh.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    await window.spire.FetchFileToVFS('msyhbd.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'AddTocToExisting.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Create a document instance and load the existing document
    const doc = new docModule.Document();
    doc.LoadFromFile({ fileName: inputFileName });

    // Get the first section of the document
    const section = doc.Sections.get_Item(0);

    // Locate the Chapter 1 heading among the body objects; tables also take a position, so paragraph-collection indexes cannot be used directly
    let insertIndex = 0;
    const children = section.Body.ChildObjects;
    for (let i = 0; i < children.Count; i++) {
      const obj = children.get_Item(i);
      if (obj.DocumentObjectType === docModule.DocumentObjectType.Paragraph && obj.StyleName === 'Heading1') {
        insertIndex = i;
        break;
      }
    }

    // Create a new paragraph and insert the TOC field, collecting Heading 1 through Heading 3 entries
    const tocPara = section.AddParagraph();
    tocPara.AppendTOC(1, 3);
    tocPara.AppendBreak(docModule.BreakType.PageBreak);

    // Insert the TOC before Chapter 1: cover → TOC → body
    section.Paragraphs.Insert(insertIndex, tocPara);

    // TOC page header
    const titleFormat = new docModule.CharacterFormat(doc);
    titleFormat.FontName = 'Microsoft YaHei';
    titleFormat.FontSize = 18;
    titleFormat.Bold = true;
    titleFormat.TextColor = docModule.Color.FromArgb(31, 40, 70);
    const titlePara = section.AddParagraph();
    titlePara.AppendText('Table of Contents').ApplyCharacterFormat(titleFormat);
    titlePara.Format.AfterSpacing = 14;
    section.Paragraphs.Insert(insertIndex, titlePara);

    // Update the TOC to fill in entries and page numbers
    doc.UpdateTableOfContents();

    // Define the output file name and save
    const outputFileName = 'Add a TOC at a Specified Position.docx';
    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });

    // Release resources
    doc.Dispose();

    // Read the generated file from VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add a Table of Contents at a Specified Position</h1>
      <button onClick={addTocAtPosition}>
        Generate
      </button>
    </div>
  );
}

export default App;
The table of contents lands between the cover and the body text: the cover is still page 1, the table of contents starts on page 2, and the body starts on page 3:
Table of contents inserted after the cover
Add a Custom Table of Contents
To add a custom table of contents, construct a TableOfContent object instead and pass a field switch string to its constructor. The difference from AppendTOC lies in how it is inserted: the TOC object has to be added to a paragraph manually, the field separator and field end marks have to be completed, and the object then has to be assigned to Document.TOC. The commonly used field switches are as follows:
| Switch | Description |
|---|---|
\o "1-2" |
Collects entries by built-in heading styles; here it means collecting Heading 1 to Heading 2 |
\h |
Writes hyperlinks for the TOC entries, so that a click jumps to the corresponding chapter |
\z |
Hides page numbers and tab leaders in Web Layout view |
\u |
Collects entries by the outline level of the paragraphs |
The example uses \o "1-2" \h \z \u, so the table of contents collects only four chapters and ten second-level headings, 14 entries in total, and third-level headings such as 2.2.1 and 2.2.2 no longer appear.
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the body font
msyh.ttc, the bold fontmsyhbd.ttcand the sample documentAddTocToExisting.docxinto the virtual file system (VFS). - Create a
Documentobject, load the existing document, and get the first section. - Construct the TOC object with
new TableOfContent(doc, '{\\o "1-2" \\h \\z \\u}'), add it to a new paragraph, and complete the field separator and field end marks. - Assign the TOC object to
doc.TOC, insert it at the very beginning of the document withParagraphs.Insert(0, tocPara), and add the "Table of Contents" heading paragraph. - Call
UpdateTableOfContentsto update the entries and page numbers, save the document, and read the result from VFS to trigger the download.
The code for adding a custom table of contents is as follows:
function App() {
  const addCustomToc = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Make sure the WASM module has fully loaded
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the fonts and the sample document into VFS
    await window.spire.FetchFileToVFS('msyh.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    await window.spire.FetchFileToVFS('msyhbd.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'AddTocToExisting.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Create a document instance and load the existing document
    const doc = new docModule.Document();
    doc.LoadFromFile({ fileName: inputFileName });

    // Get the first section of the document
    const section = doc.Sections.get_Item(0);

    // Build a TOC object with custom field switches: collect Heading 1 to Heading 2, with hyperlinked entries
    const toc = new docModule.TableOfContent(doc, '{\\o "1-2" \\h \\z \\u}');
    const tocPara = section.AddParagraph();
    tocPara.Items.Add(toc);

    // Complete the field separator and field end marks
    tocPara.AppendFieldMark(docModule.FieldMarkType.FieldSeparator);
    tocPara.AppendText('TOC');
    tocPara.AppendFieldMark(docModule.FieldMarkType.FieldEnd);
    tocPara.AppendBreak(docModule.BreakType.PageBreak);

    // Bind this TOC to the document
    doc.TOC = toc;

    // Move the TOC paragraph to the very beginning of the document
    section.Paragraphs.Insert(0, tocPara);

    // TOC page header
    const titleFormat = new docModule.CharacterFormat(doc);
    titleFormat.FontName = 'Microsoft YaHei';
    titleFormat.FontSize = 18;
    titleFormat.Bold = true;
    titleFormat.TextColor = docModule.Color.FromArgb(31, 40, 70);
    const titlePara = section.AddParagraph();
    titlePara.AppendText('Table of Contents').ApplyCharacterFormat(titleFormat);
    titlePara.Format.AfterSpacing = 14;
    section.Paragraphs.Insert(0, titlePara);

    // Update the TOC to fill in entries and page numbers
    doc.UpdateTableOfContents();

    // Define the output file name and save
    const outputFileName = 'Add a Custom TOC.docx';
    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });

    // Release resources
    doc.Dispose();

    // Read the generated file from VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add a Custom Table of Contents</h1>
      <button onClick={addCustomToc}>
        Generate
      </button>
    </div>
  );
}

export default App;
The TOC entries stop at second-level headings, and the original third-level headings no longer enter the table of contents:
Two-level table of contents generated by the custom table of contents
Limit the Collected Levels with Field Switches
The field switch string determines the behavior of the table of contents, and adjusting the level range after \o changes the collection scope: change it to \o "1-3" and third-level headings enter the table of contents again; remove \h and the entries no longer carry hyperlinks, so the table of contents becomes a plain text page reference:
// Collect third-level headings and no longer write hyperlinks
const toc = new docModule.TableOfContent(doc, '{\\o "1-3" \\z \\u}');
Update the Page Numbers of an Existing Table of Contents
To update the page numbers of an existing table of contents, call UpdateTableOfContents before saving. The TOC entries and page numbers are the result of a field calculation, and they are written according to the layout at the moment the field is updated, so the TOC object does not have to be rebuilt. The example loads a document that already has a table of contents (the result of the first feature), appends Chapter 5 to the end of the body text, and then updates the table of contents.
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the fonts and the sample document
WithTOC.docx, which already has a table of contents, into the virtual file system (VFS). - Create a
Documentobject, load the document, and get the first section. - Append a page break, a Chapter 5 heading and a paragraph of body text to the end of the body: apply the Heading 1 style to the heading, and keep the font and size of the original document for the body text.
- Call
UpdateTableOfContentsto update the table of contents, so that the entry and page number of the new chapter are written as well. - Save the result with
SaveToFile, and read the file from VFS to trigger the download.
The code for updating the page numbers of an existing table of contents is as follows:
function App() {
  const updateToc = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Make sure the WASM module has fully loaded
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the fonts and the sample document that already has a TOC into VFS
    await window.spire.FetchFileToVFS('msyh.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    await window.spire.FetchFileToVFS('msyhbd.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'WithTOC.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Create a document instance and load the existing document
    const doc = new docModule.Document();
    doc.LoadFromFile({ fileName: inputFileName });

    // Get the first section of the document
    const section = doc.Sections.get_Item(0);

    // Append a chapter at the end of the body: page break first, then the heading and the text
    const breakPara = section.AddParagraph();
    breakPara.AppendBreak(docModule.BreakType.PageBreak);

    const headingPara = section.AddParagraph();
    headingPara.AppendText('Chapter 5  Follow-up Plan');
    headingPara.ApplyStyle({ builtinStyle: docModule.BuiltinStyle.Heading1 });

    // The appended text keeps the font of the original document
    const bodyFormat = new docModule.CharacterFormat(doc);
    bodyFormat.FontName = 'Microsoft YaHei';
    bodyFormat.FontSize = 10.5;
    const bodyPara = section.AddParagraph();
    bodyPara.AppendText('The 2027 plan brings template management and permission auditing into the platform and opens a batch-fill API for business systems to call directly.').ApplyCharacterFormat(bodyFormat);

    // Update the TOC so the new chapter's entry and page number are written
    doc.UpdateTableOfContents();

    // Define the output file name and save
    const outputFileName = 'Update TOC Page Numbers.docx';
    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });

    // Release resources
    doc.Dispose();

    // Read the generated file from VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Update the Page Numbers of an Existing Table of Contents</h1>
      <button onClick={updateToc}>
        Generate
      </button>
    </div>
  );
}

export default App;
After the page numbers are updated, a "Chapter 5 Follow-up Plan" entry is added at the end of the table of contents, its page number points to page 9, and the original entries stay unchanged:
Chapter 5 appended to the end of the table of contents after its page numbers are updated
FAQ
Why does the table of contents I add appear at the end of the document
Cause: AddParagraph appends the new paragraph to the end of its section, so calling AppendTOC on it or adding a TableOfContent object to it naturally places the table of contents at the end. The content of an existing document has already been laid out, and its position does not move forward by itself.
Solution: Create the TOC paragraph first, then move it to the target position with Paragraphs.Insert:
const tocPara = section.AddParagraph();
tocPara.AppendTOC(1, 3);
section.Paragraphs.Insert(0, tocPara);
Why are the body headings missing from the table of contents
Cause: The table of contents collects entries by heading style or outline level. If the chapter headings in the original document were only made bold manually or given a larger font size, without built-in heading styles such as Heading 1 to Heading 3 applied, no collectable paragraph can be found after updating, and the table of contents may be empty or only report "No table of contents entries found".
Solution: After loading the document, call ApplyStyle on the paragraphs that should appear in the table of contents to apply a built-in heading style, and then update the table of contents:
const headingPara = section.Paragraphs.get_Item(2);
headingPara.ApplyStyle({ builtinStyle: docModule.BuiltinStyle.Heading1 });
Why is the position of the table of contents a few paragraphs off after specifying an index with Paragraphs.Insert
Cause: The index of Paragraphs.Insert is calculated in the order of the child objects in the body, and every paragraph and table takes one position. The more tables a document contains, the further the position of the same paragraph drifts between the paragraph collection and the body objects, so using the index of the paragraph collection directly is often a few paragraphs off.
Solution: Walk Body.ChildObjects to find the target paragraph and use its object position as the index:
let insertIndex = 0;
const children = section.Body.ChildObjects;
for (let i = 0; i < children.Count; i++) {
  const obj = children.get_Item(i);
  if (obj.DocumentObjectType === docModule.DocumentObjectType.Paragraph && obj.StyleName === 'Heading1') {
    insertIndex = i;
    break;
  }
}
The page numbers in the table of contents do not match the actual pages
Cause: The page numbers of the table of contents are written from the layout at the moment the field is updated, and they are not synchronized automatically if content or headings are added or removed afterwards. In addition, inserting a table of contents at the start of the document moves the existing content back as a whole, so the page numbers change accordingly, which is an expected result.
Solution: Call UpdateTableOfContents again before saving, so that the entries and page numbers are recalculated from the latest content:
doc.UpdateTableOfContents();
doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });
Updating a custom table of contents throws ArgumentOutOfRange, or shows only the word TOC
Cause: After a TableOfContent object is added to a paragraph, if the field separator, the field end mark, or the assignment to Document.TOC is missing, the TOC field is incomplete: without the marks the page may show only placeholder text, and without the binding, updating is likely to throw an index-out-of-range exception.
Solution: The following three steps have to be completed together before the update is called:
const toc = new docModule.TableOfContent(doc, '{\\o "1-2" \\h \\z \\u}');
const tocPara = section.AddParagraph();
tocPara.Items.Add(toc);

tocPara.AppendFieldMark(docModule.FieldMarkType.FieldSeparator);
tocPara.AppendText('TOC');
tocPara.AppendFieldMark(docModule.FieldMarkType.FieldEnd);

doc.TOC = toc;
Get a Free License
Spire.Doc for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Add a Table of Contents to a New Word Document with JavaScript in React
2026-09-18 06:01:11 Written by Amy ZhaoA table of contents is a standard part of a long document. Its entries follow the heading hierarchy and carry page numbers, so readers can locate a section quickly; when content is added or removed, the entries and page numbers can also be updated together before saving, without checking page by page.
This article takes a "2026 Annual Product and Technology Report" as an example: it creates a Word document from scratch — cover, table-of-contents page, four chapters of body text and data tables — and then adds a table of contents to it. The sample is based on Spire.Doc for JavaScript. The library runs in the browser as a WebAssembly module, reads and writes fonts and document files through a virtual file system (VFS), and requires no backend service, so files never leave the user's device.
This article covers the following topics:
- Build the Sample Document
- Add a Default Table of Contents
- Set the Heading Levels Collected by the Table of Contents
- Add a Custom Table of Contents
- Modify the Table of Contents Entry Styles
For installation and project setup, refer to Integrating Spire.Doc for JavaScript in a React Project. The examples below assume that Spire.Doc is installed and the WebAssembly module is initialized. So that each feature can be run directly, every code sample below is a complete single-file program: the builder for the sample document and the calling code are merged into the same block, which can replace the contents of App.js and run as it is.
Build the Sample Document
The code that builds the sample document is kept in report.js: the cover, the table-of-contents page heading, the four chapters of body text and the footer are all generated by this module, and an insertToc callback is reserved on the table-of-contents page, so that the four features that follow decide how the TOC field is written. Each section below inlines this builder as well, so report.js does not have to be created separately.
The sample document has four chapters and sixteen headings, spanning three levels from Heading 1 to Heading 3, and contains three data tables and one security notice block. The full heading hierarchy makes it easy to observe how the table of contents collects headings at different levels; the layout uses a consistent font, color scheme and line spacing, and a page break separates the table-of-contents page from the body text.
The specific steps are as follows:
- Create a
Documentand aSection, and set the A4 page margins, the footer distance and the footer content. - Write the cover: brand line, document-category block, title, subtitle and key figures row.
- Write the table-of-contents page heading and note, and call the
insertToccallback so that each feature can decide how the TOC field is inserted. - Write the four chapters of body text, applying the built-in Heading 1, Heading 2 and Heading 3 styles to chapter, section and subsection headings respectively.
- After the body text is written, call
UpdateTableOfContentsto update the table of contents, and return the completedDocumentobject.
The code that builds the sample document is as follows:
// Sample document builder: cover → TOC → four chapters
// The caller decides how the TOC is written through the insertToc callback; the body content and layout are shared by the four features

const FONT = 'Microsoft YaHei';
const NAVY = [31, 40, 70];
const TEAL = [28, 122, 94];
const GREY = [95, 105, 120];
const LIGHT = [240, 243, 247];
const ALT = [248, 250, 252];
const RULE = [210, 216, 224];
const WHITE = [255, 255, 255];
const CONTENT = 439; // A4 page width 595 pt, minus 78 pt on each side

// Layout helpers: a consistent font, color, line spacing and paragraph spacing
function createLayout(docModule, doc, section) {
  const color = (rgb) => docModule.Color.FromArgb(rgb[0], rgb[1], rgb[2]);
  const lines = (n) => n * 12; // Line spacing is measured in points; 12 pt is single spacing

  const format = (size, rgb, bold = false, spacing = 0) => {
    const cf = new docModule.CharacterFormat(doc);
    cf.FontName = FONT;
    cf.FontSize = size;
    cf.TextColor = color(rgb);
    cf.Bold = bold;
    cf.CharacterSpacing = spacing;
    return cf;
  };

  const paragraph = (content, o = {}) => {
    const p = section.AddParagraph();
    if (content) p.AppendText(content).ApplyCharacterFormat(format(o.size || 10.5, o.color || GREY, o.bold, o.spacing));
    p.Format.LineSpacingRule = docModule.LineSpacingRule.Multiple;
    p.Format.LineSpacing = lines(o.ls || 1.55);
    p.Format.AfterSpacing = o.after === undefined ? 9 : o.after;
    p.Format.BeforeSpacing = o.before || 0;
    if (o.indent) p.Format.LeftIndent = o.indent;
    if (o.align) p.Format.HorizontalAlignment = o.align;
    if (o.rule) {
      p.Format.Borders.Bottom.BorderType = docModule.BorderStyle.Single;
      p.Format.Borders.Bottom.LineWidth = o.ruleWidth || 0.75;
      p.Format.Borders.Bottom.Color = color(o.rule);
      p.Format.Borders.Bottom.Space = o.ruleSpace === undefined ? 4 : o.ruleSpace;
    }
    return p;
  };

  // Blank line with an exact height, used for spacing on the cover
  const spacer = (height) => {
    const p = section.AddParagraph();
    p.Format.LineSpacingRule = docModule.LineSpacingRule.Exactly;
    p.Format.LineSpacing = height;
    p.Format.BeforeSpacing = 0;
    p.Format.AfterSpacing = 0;
    return p;
  };

  // Apply a built-in style to heading paragraphs; the TOC collects entries by style
  const heading = (content, level, o = {}) => {
    const p = section.AddParagraph();
    const size = level === 1 ? 16 : level === 2 ? 12.5 : 11;
    p.AppendText(content).ApplyCharacterFormat(format(size, level === 2 ? TEAL : NAVY, true, level === 1 ? 0.6 : 0));
    p.ApplyStyle({ builtinStyle: [null, docModule.BuiltinStyle.Heading1, docModule.BuiltinStyle.Heading2, docModule.BuiltinStyle.Heading3][level] });
    p.Format.LineSpacingRule = docModule.LineSpacingRule.Multiple;
    p.Format.LineSpacing = lines(1.25);
    p.Format.BeforeSpacing = o.before === undefined ? (level === 1 ? 21 : 13) : o.before;
    p.Format.AfterSpacing = level === 1 ? 9 : 4;
    p.Format.KeepFollow = true;
    if (level === 1) {
      p.Format.Borders.Bottom.BorderType = docModule.BorderStyle.Single;
      p.Format.Borders.Bottom.LineWidth = 1.5;
      p.Format.Borders.Bottom.Color = color(TEAL);
      p.Format.Borders.Bottom.Space = 5;
    }
    return p;
  };

  const table = (header, rows, widths) => {
    const t = section.AddTable(true);
    t.ResetCells(rows.length + 1, header.length);
    t.SetBorders(docModule.BorderStyle.Hairline, 0.5, color(RULE));
    t.Format.HorizontalAlignment = docModule.HorizontalAlignment.Center;
    widths.forEach((w, i) => t.SetColumnWidth(i, CONTENT * w / 100, docModule.WidthType.Twip));
    const fill = (row, i, value, bg, textColor, bold, size) => {
      const c = row.Cells.get_Item(i);
      const p = c.AddParagraph();
      p.AppendText(value).ApplyCharacterFormat(format(size, textColor, bold));
      p.Format.LineSpacingRule = docModule.LineSpacingRule.Multiple;
      p.Format.LineSpacing = lines(1.2);
      p.Format.AfterSpacing = 0;
      c.CellFormat.BackColor = color(bg);
      c.CellFormat.Paddings.Left = 10;
      c.CellFormat.Paddings.Right = 10;
      c.CellFormat.Paddings.Top = 7;
      c.CellFormat.Paddings.Bottom = 7;
      c.CellFormat.VerticalAlignment = docModule.VerticalAlignment.Middle;
    };
    header.forEach((h, i) => fill(t.Rows.get_Item(0), i, h, NAVY, WHITE, true, 9));
    rows.forEach((r, ri) => r.forEach((v, i) => fill(t.Rows.get_Item(ri + 1), i, v, ri % 2 ? ALT : WHITE, i === 0 ? NAVY : GREY, i === 0, 9.5)));
    for (let i = 0; i < t.Rows.Count; i++) {
      const row = t.Rows.get_Item(i);
      row.RowFormat.IsBreakAcrossPages = false;
      if (i === 0) row.IsHeader = true;
    }
    return t;
  };

  // Notice block: light cell plus a color bar on the left; no heading style, so it stays out of the TOC
  const callout = (title, lines_) => {
    const t = section.AddTable(false);
    t.ResetCells(1, 1);
    t.Format.HorizontalAlignment = docModule.HorizontalAlignment.Center;
    t.SetColumnWidth(0, CONTENT, docModule.WidthType.Twip);
    const c = t.Rows.get_Item(0).Cells.get_Item(0);
    c.CellFormat.BackColor = color(LIGHT);
    c.CellFormat.Paddings.Left = 15;
    c.CellFormat.Paddings.Right = 15;
    c.CellFormat.Paddings.Top = 12;
    c.CellFormat.Paddings.Bottom = 12;
    c.CellFormat.Borders.Left.BorderType = docModule.BorderStyle.Single;
    c.CellFormat.Borders.Left.LineWidth = 2.5;
    c.CellFormat.Borders.Left.Color = color(TEAL);
    const head = c.AddParagraph();
    head.AppendText(title).ApplyCharacterFormat(format(9.5, NAVY, true));
    head.Format.LineSpacingRule = docModule.LineSpacingRule.Multiple;
    head.Format.LineSpacing = lines(1.4);
    head.Format.AfterSpacing = 3;
    lines_.forEach((line) => {
      const p = c.AddParagraph();
      p.AppendText(line).ApplyCharacterFormat(format(9, GREY));
      p.Format.LineSpacingRule = docModule.LineSpacingRule.Multiple;
      p.Format.LineSpacing = lines(1.5);
      p.Format.AfterSpacing = 2;
    });
    // The single-cell notice must not split across pages, so the color block is never cut
    t.Rows.get_Item(0).RowFormat.IsBreakAcrossPages = false;
  };

  return { format, paragraph, spacer, heading, table, callout, color, lines };
}

// Footer: note text on the left, page number on the right
function addFooter(docModule, section, L) {
  const footer = section.HeadersFooters.Footer.AddParagraph();
  footer.Format.LineSpacingRule = docModule.LineSpacingRule.Multiple;
  footer.Format.LineSpacing = 12;
  footer.Format.AfterSpacing = 0;
  footer.Format.Borders.Top.BorderType = docModule.BorderStyle.Single;
  footer.Format.Borders.Top.LineWidth = 0.5;
  footer.Format.Borders.Top.Color = L.color(RULE);
  footer.Format.Borders.Top.Space = 6;
  footer.Format.Tabs.AddTab(CONTENT, docModule.TabJustification.Right, docModule.TabLeader.NoLeader);
  footer.AppendText('NORTHSTAR TECHNOLOGY  ·  PRODUCT & ENGINEERING  ·  INTERNAL').ApplyCharacterFormat(L.format(8, GREY));
  footer.AppendText('\t').ApplyCharacterFormat(L.format(8, GREY));
  footer.AppendText('Page ').ApplyCharacterFormat(L.format(8, GREY));
  footer.AppendField('PAGE', docModule.FieldType.FieldPage);
}

// Cover
function addCover(docModule, section, L) {
  const { paragraph, spacer, format, color } = L;

  paragraph('NORTHSTAR TECHNOLOGY  ·  PRODUCT & ENGINEERING', { size: 8.5, color: TEAL, bold: true, spacing: 1.8, after: 6, rule: NAVY, ruleWidth: 1.5, ruleSpace: 8 });

  // Color block plus document category, the visual anchor of the cover
  const badge = section.AddTable(false);
  badge.ResetCells(1, 1);
  badge.Format.HorizontalAlignment = docModule.HorizontalAlignment.Left;
  badge.SetColumnWidth(0, 120, docModule.WidthType.Twip);
  const badgeCell = badge.Rows.get_Item(0).Cells.get_Item(0);
  badgeCell.CellFormat.BackColor = color(TEAL);
  badgeCell.CellFormat.Paddings.Left = 8;
  badgeCell.CellFormat.Paddings.Right = 8;
  badgeCell.CellFormat.Paddings.Top = 3;
  badgeCell.CellFormat.Paddings.Bottom = 3;
  const badgePara = badgeCell.AddParagraph();
  badgePara.AppendText('ANNUAL TECHNICAL DOCUMENT').ApplyCharacterFormat(format(8, WHITE, true, 1.2));
  badgePara.Format.LineSpacingRule = docModule.LineSpacingRule.Multiple;
  badgePara.Format.LineSpacing = 13;
  badgePara.Format.AfterSpacing = 0;
  badgePara.Format.HorizontalAlignment = docModule.HorizontalAlignment.Center;

  spacer(34);
  paragraph('2026 Annual Product and Technology Report', { size: 30, color: NAVY, bold: true, after: 8, ls: 1.1 });
  paragraph('Capability building, rollout progress and acceptance plan for the online document processing platform', { size: 12.5, color: GREY, after: 22, ls: 1.4 });

  // Key figures row
  const stat = section.AddTable(false);
  stat.ResetCells(1, 3);
  [['5', 'Capability Domains'], ['12', 'Key Features'], ['98%', 'Pass Rate']].forEach(([value, label], i) => {
    const c = stat.Rows.get_Item(0).Cells.get_Item(i);
    const p1 = c.AddParagraph();
    p1.AppendText(value).ApplyCharacterFormat(format(18, TEAL, true));
    p1.Format.LineSpacingRule = docModule.LineSpacingRule.Multiple;
    p1.Format.LineSpacing = 22;
    p1.Format.AfterSpacing = 3;
    const p2 = c.AddParagraph();
    p2.AppendText(label).ApplyCharacterFormat(format(9, GREY));
    p2.Format.LineSpacingRule = docModule.LineSpacingRule.Multiple;
    p2.Format.LineSpacing = 14;
    p2.Format.AfterSpacing = 0;
    c.CellFormat.BackColor = color(LIGHT);
    c.CellFormat.Paddings.Left = 15;
    c.CellFormat.Paddings.Right = 12;
    c.CellFormat.Paddings.Top = 14;
    c.CellFormat.Paddings.Bottom = 14;
    c.CellFormat.VerticalAlignment = docModule.VerticalAlignment.Middle;
  });

  spacer(96);
  paragraph('Document No.  NS-TR-2026-018    Version  V2.1 (Review Draft)', { size: 9, color: GREY, after: 5, rule: RULE });
  paragraph('Prepared by  Product & Engineering    Published  October 2026', { size: 9, color: GREY, after: 0 });
}

// Body outline: the first item is the heading level, and the level decides whether the entry is collected
const OUTLINE = [
  [1, 'Chapter 1  Project Overview', [
    'The online document processing platform was started in 2025, with the goal of letting business departments generate and circulate contracts, reports and statements without installing desktop software. Work in 2026 concentrates on three main lines: closing capability gaps, delivery cadence and quality assurance.',
  ]],
  [2, '1.1  Background', [
    'Business departments need to generate about 42,000 documents in fixed formats every month. This used to depend on scattered desktop tools and manual checking, at about 6 minutes per document. After the platform moved this work to the browser, generating a single document takes less than 9 seconds.',
    'Documents no longer pass through a server either: both the source files and the result files stay on the user\'s device, which removes one step from the handling of sensitive content such as contracts and payroll.',
  ]],
  [2, '1.2  Delivery Scope for This Phase', [
    'The delivery scope for this year covers four areas: document creation, content editing, format conversion and batch processing. The modules and their status are listed in the table below.',
  ], ['Module', 'Deliverables', 'Status'], [
    ['Document creation', 'Paragraphs, tables, images, headers and footers', 'Delivered'],
    ['Content editing', 'Styles, tables of contents, bookmarks, find and replace', 'Delivered'],
    ['Format conversion', 'PDF, images, HTML, Markdown', 'Delivered'],
    ['Batch processing', 'Multi-file queues and template filling', 'In integration testing'],
  ], [26, 50, 24], 'Delivery in this phase assumes that processing is completed in the browser; only two kinds of data, templates and permissions, remain on the server.'],
  [2, '1.3  Document Structure Conventions', [
    'The report follows a uniform structure of three chapters plus an appendix: chapters are Heading 1, sections are Heading 2, and items that need further breakdown are Heading 3. The chapter number and the heading text are separated by two spaces, so that entries stay aligned at each level of indentation in the table of contents.',
    'Every data table in the body text carries a header row, and the header repeats automatically when a table breaks across pages; column widths are allocated in proportion to the content rather than fixed, so that the same document stays readable at different page sizes.',
  ]],
  [1, 'Chapter 2  Technical Architecture', [
    'The platform separates the front end from the back end: the browser parses and renders documents, while the server handles storage, permissions and auditing. The interface between the two sides is bounded by the document object model, which avoids transferring files back and forth between the browser and the server.',
  ]],
  [2, '2.1  Overall Architecture', [
    'The document processing core is loaded as a WebAssembly module, and static resources such as fonts and templates are loaded on demand through a virtual file system. The application layer only calls the interfaces of the document object model and does not deal with memory management or thread scheduling underneath.',
  ]],
  [2, '2.2  Key Modules', [
    'The key modules are divided by responsibility into three groups: parsing, rendering and security. Parsing and rendering are two independent processing stages and can be replaced separately.',
  ]],
  [3, '2.2.1  Document Parsing Engine', [
    'The parsing engine reads the document structure and restores paragraphs, tables, images and field codes into an object tree in memory. Parsing does not modify the source file, so the same document can be read repeatedly by multiple workflows.',
  ]],
  [3, '2.2.2  Rendering and Export', [
    'The rendering module computes the layout from the page size and margins, and the export module writes the result in the target format. Both share the same pagination rules, so the export matches the page count of the on-screen preview.',
  ]],
  [2, '2.3  Data and Security', [
    'Documents are processed in the browser and source files never pass through the server; result files that need to be retained are uploaded by the user explicitly, and access permissions are set along two dimensions, department and project.',
  ], null, null, null, null, ['Security Notice', [
    'Document parsing and rendering are both completed inside the user\'s browser; the platform does not keep source files on the server.',
    'If a result file needs to be archived, the user should upload it explicitly and set an access period per project.',
  ]]],
  [1, 'Chapter 3  Implementation Plan', [
    'Implementation proceeds in four phases, with a phase review at the end of each phase; work moves on to the next phase once the review is passed.',
  ]],
  [2, '3.1  Milestones', [
    'The start and end dates and the deliverables of each phase are listed in the table below; dates are given in calendar months.',
  ], ['Phase', 'Timeline', 'Deliverables'], [
    ['Design', 'February 2026', 'Architecture specification, interface list'],
    ['Core development', 'March–June 2026', 'Parsing and rendering modules'],
    ['Integration testing', 'July–August 2026', 'End-to-end demo environment'],
    ['Acceptance and launch', 'September–October 2026', 'Acceptance report, operations manual'],
  ], [24, 32, 44]],
  [2, '3.2  Risks and Mitigation', [
    'The main risk identified so far is pagination drift caused by missing font resources. The mitigation is to ship the font files with the application and validate the font list at startup.',
  ], ['Risk', 'Impact', 'Mitigation'], [
    ['Missing fonts', 'Page breaks shift', 'Ship fonts with the bundle and validate the list'],
    ['Very long paragraphs', 'Longer generation time', 'Split paragraphs by chapter and process in segments'],
    ['Browser differences', 'Preview and export disagree', 'Use the export result as the acceptance baseline'],
  ], [24, 32, 44]],
  [1, 'Chapter 4  Acceptance Criteria', [
    'Acceptance is based on two items, functional completeness and performance metrics; if either is not met, the work enters a remediation process.',
  ]],
  [2, '4.1  Functional Acceptance', [
    'Functional acceptance covers 12 key features, executed one by one against the acceptance script; the pass rate is currently 98%. The two failures both concern progress feedback in batch processing.',
  ]],
  [2, '4.2  Performance Metrics', [
    'Performance is measured in three areas: generation time, batch processing and memory usage. The target and measured values are listed in the table below.',
  ], ['Metric', 'Target', 'Measured'], [
    ['Generate one 30-page document', '15 seconds or less', '9.4 seconds'],
    ['Process 20 documents in batch', '5 minutes or less', '3 minutes 12 seconds'],
    ['Peak memory usage', '600 MB or less', '468 MB'],
  ], [40, 32, 28]],
];

function addBody(section, L) {
  const { paragraph, heading, table, callout } = L;
  OUTLINE.forEach(([level, title, texts, header, rows, widths, tail, calloutData]) => {
    heading(title, level);
    texts.forEach((content) => paragraph(content, { after: header ? 10 : 9 }));
    if (header) table(header, rows, widths);
    if (tail) paragraph(tail, { size: 9, after: 0, before: 10 });
    if (calloutData) callout(calloutData[0], calloutData[1]);
  });
  paragraph('The metrics above are summarized quarterly; the retest results for the fourth quarter will be updated in the next report.', { size: 9.5, after: 0, before: 10 });
}

// Heading bar and note on the table-of-contents page
function addTocHeading(L) {
  L.paragraph('CONTENTS', { size: 8, color: TEAL, bold: true, spacing: 2.4, after: 4, ls: 1.1 });
  L.paragraph('Table of Contents', { size: 19, color: NAVY, bold: true, spacing: 1.6, after: 8, ls: 1.1, rule: TEAL, ruleWidth: 1, ruleSpace: 8 });
  L.paragraph('The entries below are generated automatically from the heading styles applied in the document, and the page numbers refresh whenever the body text changes.', { size: 9, after: 14 });
}

function addPageBreak(docModule, section) {
  const p = section.AddParagraph();
  p.AppendBreak(docModule.BreakType.PageBreak);
  p.Format.LineSpacingRule = docModule.LineSpacingRule.Exactly;
  p.Format.LineSpacing = 1;
  p.Format.AfterSpacing = 0;
}

// Notice block below the TOC: no heading style, so it does not enter the TOC
const TOC_NOTES = [
  '· TOC entries are generated from the paragraphs that have a heading style applied; the scope depends on the heading levels specified when the TOC is inserted.',
  '· Page numbers come from the layout computed at save time, so the TOC has to be updated again after content is added to or removed from the body.',
  '· The cover and the table-of-contents page are counted in the page numbering, so Chapter 1 of the body starts on page 3.',
];

// Build the whole document; insertToc(doc, section) inserts the TOC field on the contents page
export function buildReport(docModule, insertToc) {
  const doc = new docModule.Document();
  const section = doc.AddSection();
  section.PageSetup.Margins.Left = 78;
  section.PageSetup.Margins.Right = 78;
  section.PageSetup.Margins.Top = 72;
  section.PageSetup.Margins.Bottom = 70;
  section.PageSetup.FooterDistance = 36;

  const L = createLayout(docModule, doc, section);
  addFooter(docModule, section, L);
  addCover(docModule, section, L);

  // Page break after the cover so the contents page stands on its own
  addPageBreak(docModule, section);
  addTocHeading(L);

  // Each feature decides how the TOC field is written
  insertToc(doc, section);

  // Notice block below the TOC
  L.spacer(16);
  L.callout('Reading Notes', TOC_NOTES);

  // Page break after the TOC so the body starts on a new page
  addPageBreak(docModule, section);
  addBody(section, L);

  // Update the TOC to fill in entries and page numbers
  doc.UpdateTableOfContents();
  return doc;
}

// Read the generated file from VFS and trigger a browser download
export function download(fileName) {
  const fileArray = window.dotnetRuntime.Module.FS.readFile(fileName);
  const blob = new Blob([fileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
  const url = URL.createObjectURL(blob);
  const a = document.createElement('a');
  a.href = url;
  a.download = fileName;
  a.click();
  URL.revokeObjectURL(url);
}
Add a Default Table of Contents
To add a default table of contents, insert the TOC field on the contents page with the AppendTOC method. The method takes a start level and an end level, and the table of contents collects only the headings that fall within that range:
| Usage | Scope |
|---|---|
AppendTOC(1, 3) |
Heading 1 to Heading 3 |
AppendTOC(1, 2) |
Heading 1 to Heading 2 |
AppendTOC(2, 3) |
Heading 2 to Heading 3 |
The example passes (1, 3), so the table of contents collects headings at three levels — Chapter 1, 1.1 and 2.2.1 — and the page numbers are connected to the entries by a tab leader.
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the body font
msyh.ttcand the bold fontmsyhbd.ttcinto the virtual file system (VFS). - Call
buildReportto build the sample document, and insert the default TOC field on the contents page withAppendTOC(1, 3). - Save the document with the
SaveToFilemethod under the file name "Create a Default TOC in Word Document.docx". - Call the
downloadmethod to read the result file from VFS and trigger the browser download.
The code for adding a default table of contents is as follows:
function App() {
  const addDefaultToc = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Make sure the WASM module has fully loaded
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the fonts into VFS
    await window.spire.FetchFileToVFS('msyh.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/static/font/`);
    await window.spire.FetchFileToVFS('msyhbd.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/static/font/`);

    // Build the sample document and insert the default TOC field on the contents page
    const report = buildReport(docModule, (doc, section) => {
      const tocPara = section.AddParagraph();
      tocPara.AppendTOC(1, 3);
    });

    // Save the result file
    const outputFileName = 'Create a Default TOC in Word Document.docx';
    report.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });
    report.Dispose();

    // Read the generated file from VFS and trigger the download
    download(outputFileName);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add a Default Table of Contents to a New Document</h1>
      <button onClick={addDefaultToc}>
        Generate
      </button>
    </div>
  );
}

export default App;
Once the table of contents has been updated, the contents page holds entries that collect three heading levels, with page numbers and tab leaders:
Default table of contents generated with AppendTOC(1, 3)
Set the Heading Levels Collected by the Table of Contents
To set the heading levels collected by the table of contents, adjust the two parameters of AppendTOC. With the end level changed from 3 to 2, the table of contents keeps only Heading 1 and Heading 2 entries, and third-level headings such as 2.2.1 and 2.2.2 no longer appear; with the start level changed to 2, Heading 1 entries are left out in the same way.
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the body font
msyh.ttcand the bold fontmsyhbd.ttcinto the virtual file system (VFS). - Call
buildReportto build the sample document, and insert a TOC field withAppendTOC(1, 2)on the contents page so that only two heading levels are collected. - Save the document with the
SaveToFilemethod under the file name "Create a Two-Level TOC in Word Document.docx". - Call the
downloadmethod to read the result file from VFS and trigger the browser download.
The code for setting the collection levels is as follows:
function App() {
  const addTwoLevelToc = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Make sure the WASM module has fully loaded
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the fonts into VFS
    await window.spire.FetchFileToVFS('msyh.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/static/font/`);
    await window.spire.FetchFileToVFS('msyhbd.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/static/font/`);

    // Start level 1, end level 2: collect only Heading 1 and Heading 2 entries
    const report = buildReport(docModule, (doc, section) => {
      const tocPara = section.AddParagraph();
      tocPara.AppendTOC(1, 2);
    });

    // Save the result file
    const outputFileName = 'Create a Two-Level TOC in Word Document.docx';
    report.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });
    report.Dispose();

    // Read the generated file from VFS and trigger the download
    download(outputFileName);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add a Two-Level Table of Contents to a New Document</h1>
      <button onClick={addTwoLevelToc}>
        Generate
      </button>
    </div>
  );
}

export default App;
With the collection levels set, the entries in the table of contents stop at Heading 2, and 2.2.1 and 2.2.2 no longer appear:
Two-level table of contents generated with AppendTOC(1, 2)
Add a Custom Table of Contents
To add a custom table of contents, construct a TableOfContent object instead and pass a field switch string to its constructor. The difference from AppendTOC lies in how it is inserted: the TOC object has to be added to a paragraph manually, the field separator and field end marks have to be completed, and the object then has to be assigned to Document.TOC.
The commonly used field switches are as follows:
| Switch | Description |
|---|---|
\o "1-3" |
Collects entries by built-in heading styles; here it means collecting Heading 1 to Heading 3 |
\h |
Writes hyperlinks for the TOC entries, so that a click jumps to the corresponding chapter |
\z |
Hides page numbers and tab leaders in Web Layout view |
\u |
Collects entries by the outline level of the paragraphs |
Changing the switch string to \o "1-2" makes the table of contents collect only Heading 1 and Heading 2 entries; removing \h means hyperlinks are no longer written for the entries. The example keeps \o "1-3" \h \z \u, so its collection scope matches that of the default table of contents.
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the body font
msyh.ttcand the bold fontmsyhbd.ttcinto the virtual file system (VFS). - Call
buildReportto build the sample document; on the contents page, construct aTableOfContentobject with field switches, add it to a paragraph, complete the field marks and assign it toDocument.TOC. - Save the document with the
SaveToFilemethod under the file name "Create a Custom TOC in Word Document.docx". - Call the
downloadmethod to read the result file from VFS and trigger the browser download.
The code for adding a custom table of contents is as follows. It also inlines the builder for the sample document, so the whole block can replace the entire contents of App.js:
function App() {
  const addCustomToc = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Make sure the WASM module has fully loaded
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the fonts into VFS
    await window.spire.FetchFileToVFS('msyh.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/static/font/`);
    await window.spire.FetchFileToVFS('msyhbd.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/static/font/`);

    // Build the sample document and insert a custom TOC on the contents page
    const report = buildReport(docModule, (doc, section) => {
      // Construct a TOC object with custom field switches
      const toc = new docModule.TableOfContent(doc, '{\\o "1-3" \\h \\z \\u}');
      const tocPara = section.AddParagraph();
      tocPara.Items.Add(toc);

      // Complete the field separator and field end marks
      tocPara.AppendFieldMark(docModule.FieldMarkType.FieldSeparator);
      tocPara.AppendText('TOC');
      tocPara.AppendFieldMark(docModule.FieldMarkType.FieldEnd);

      // Bind this TOC to the document
      doc.TOC = toc;
    });

    // Save the result file
    const outputFileName = 'Create a Custom TOC in Word Document.docx';
    report.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });
    report.Dispose();

    // Read the generated file from VFS and trigger the download
    download(outputFileName);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add a Custom Table of Contents to a New Document</h1>
      <button onClick={addCustomToc}>
        Generate
      </button>
    </div>
  );
}

export default App;
The entry levels and hyperlinks of a custom table of contents are determined by the switch string, and the example collects the same range as the default table of contents:
Table of contents generated with TableOfContent and custom field switches
Modify the Table of Contents Entry Styles
To modify the entry styles of the table of contents, rewrite the three paragraph styles TOC 1 to TOC 3. After the table of contents is updated, entries at each level use the corresponding style, so restyling the styles changes the font, size and indentation of all entries at once, without setting them one by one.
| Style | Controls |
|---|---|
TOC 1 |
Entries generated from Heading 1 |
TOC 2 |
Entries generated from Heading 2 |
TOC 3 |
Entries generated from Heading 3 |
The example sets first-level entries to 11 pt and bold, with 3 pt of space before, and second- and third-level entries to 10.5 pt, with a left indent that grows by 18 pt per level.
The specific steps are as follows:
- Get the Spire.Doc WASM module and confirm that it is ready.
- Load the body font
msyh.ttcand the bold fontmsyhbd.ttcinto the virtual file system (VFS). - Call
buildReportto build the sample document, and insert the default TOC field on the contents page withAppendTOC(1, 3). - Once the table of contents has been updated, get the TOC 1 to TOC 3 styles and set the font, size, bold, line spacing and left indent.
- Save the document with the
SaveToFilemethod, then call thedownloadmethod to read the result file from VFS and trigger the download.
The code for modifying the entry styles is as follows:
function App() {
  const styleTocEntries = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Make sure the WASM module has fully loaded
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load the fonts into VFS
    await window.spire.FetchFileToVFS('msyh.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/static/font/`);
    await window.spire.FetchFileToVFS('msyhbd.ttc', '/Library/Fonts/', `${process.env.PUBLIC_URL}/static/font/`);

    // Build the sample document and insert the default TOC field on the contents page
    const report = buildReport(docModule, (doc, section) => {
      const tocPara = section.AddParagraph();
      tocPara.AppendTOC(1, 3);
    });

    // Once the TOC has been updated, rewrite the three entry styles TOC 1 to TOC 3
    for (let level = 1; level <= 3; level++) {
      const style = report.Styles.get_Item('TOC ' + level);
      if (!style) continue;
      style.CharacterFormat.FontName = 'Microsoft YaHei';
      style.CharacterFormat.FontSize = level === 1 ? 11 : 10.5;
      style.CharacterFormat.Bold = level === 1;
      style.ParagraphFormat.LineSpacingRule = docModule.LineSpacingRule.Multiple;
      style.ParagraphFormat.LineSpacing = 16;
      style.ParagraphFormat.BeforeSpacing = level === 1 ? 3 : 0;
      style.ParagraphFormat.AfterSpacing = 1;
      style.ParagraphFormat.LeftIndent = (level - 1) * 18;
    }

    // Save the result file
    const outputFileName = 'Set Word TOC Entry Styles.docx';
    report.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });
    report.Dispose();

    // Read the generated file from VFS and trigger the download
    download(outputFileName);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Modify the Table of Contents Entry Styles in Word</h1>
      <button onClick={styleTocEntries}>
        Generate
      </button>
    </div>
  );
}

export default App;
After the styles are rewritten, first-level entries are larger and bold, and second- and third-level entries are indented by level:
Table of contents after the TOC 1 to TOC 3 styles are rewritten
FAQ
What should I do when the table of contents reports "No table of contents entries found" after updating
Cause: The table of contents collects entries by heading style or outline level. If a paragraph is only made bold or given a larger size, without a built-in heading style such as Heading 1 to Heading 3 applied, no collectable entry can be found when the field is updated.
Solution: Call ApplyStyle on the paragraphs that should appear in the table of contents to apply a built-in heading style:
const p = section.AddParagraph();
p.AppendText('Chapter 1 Project Overview');
p.ApplyStyle({ builtinStyle: docModule.BuiltinStyle.Heading1 });
The table of contents shows only the word TOC, with no entries or page numbers
Cause: AppendTOC and TableOfContent insert a TOC field, and the entries and page numbers are written when the field is updated. If UpdateTableOfContents is not called before saving, the page shows only the placeholder text.
Solution: Update the table of contents before SaveToFile:
doc.UpdateTableOfContents();
Updating a custom table of contents throws an ArgumentOutOfRange error
Cause: After a TableOfContent object is added to a paragraph, if the field separator, the field end mark, or the assignment to Document.TOC is missing, the TOC field is incomplete, and updating it may throw an index-out-of-range exception.
Solution: All three steps below have to be completed together:
const toc = new docModule.TableOfContent(doc, '{\\o "1-3" \\h \\z \\u}');
const tocPara = section.AddParagraph();
tocPara.Items.Add(toc);

tocPara.AppendFieldMark(docModule.FieldMarkType.FieldSeparator);
tocPara.AppendText('TOC');
tocPara.AppendFieldMark(docModule.FieldMarkType.FieldEnd);

doc.TOC = toc;
The page numbers in the table of contents do not match the actual pages
Cause: The page numbers of the table of contents are written from the layout at the moment the field is updated, so they do not follow changes made to the body text or headings afterwards. In the example the cover and the table of contents each take one page, so Chapter 1 of the body starts on page 3; that is an expected result.
Solution: Call UpdateTableOfContents again before saving, so that the entries and page numbers are recalculated from the latest content:
doc.UpdateTableOfContents();
doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });
Can only the headings of some chapters be collected
Solution: The levels to collect can be limited through the start and end levels of AppendTOC; for example, AppendTOC(1, 2) collects only two heading levels. Paragraphs that should not appear in the table of contents can avoid heading styles and be formatted directly instead, and a custom table of contents can limit the collection range with the \o switch.
Get a Free License
Spire.Doc for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Combining several contract attachments into one complete document, appending supplementary content at the end of a report, or merging multiple chapters into a single output — these requirements are common in web applications. Handling them on the server means files must first be uploaded and leave the user's device; asking users to install desktop software and stitch documents together by hand is equally hard to fit into a batch-oriented web workflow.
This article uses Spire.Doc for JavaScript to merge Word documents directly in the browser. The whole process runs client-side on WebAssembly, requires no Office installation and no backend, and reads and writes documents locally through a virtual file system (VFS), so files stay on the user's device the entire time.
This article covers two core features:
For installation and project configuration, refer to Integrating Spire.Doc for JavaScript in a React Project. The examples below assume Spire.Doc has been installed and the WebAssembly module has been initialized.
Merge Word Documents by Section
Spire.Doc for JavaScript appends a section to the end of the target document with the Sections.Add() method, and Section.Clone() makes it possible to copy a section without modifying the source document. A cloned section keeps its own page setup, so in the merged document it usually starts on a new page.
The steps are as follows:
- Obtain the Spire.Doc WASM module and confirm that it is ready.
- Read both sample Word documents into VFS, create a
Documentobject and load the target document. - Create another
Documentobject and load the source document. - Iterate over the source document's
Sectionscollection and useSections.Add(section.Clone())to clone each section and append it to the end of the target document. - Save the result with the
Document.SaveToFile()method. - Read the result file back from VFS and trigger a browser download.
The code for merging Word documents by section is as follows:
function App() {
  const mergeBySection = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Check if the module is ready
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Read both sample documents into VFS
    const inputFileName1 = 'Template_Docx_1.docx';
    await window.spire.FetchFileToVFS(inputFileName1, '', `${process.env.PUBLIC_URL}static/data/`);
    const inputFileName2 = 'Template_Docx_2.docx';
    await window.spire.FetchFileToVFS(inputFileName2, '', `${process.env.PUBLIC_URL}static/data/`);

    // Load the target document
    const TarDoc = new docModule.Document();
    TarDoc.LoadFromFile(inputFileName1);

    // Load the source document
    const SouDoc = new docModule.Document();
    SouDoc.LoadFromFile(inputFileName2);

    // Clone every section of the source document and append it to the end of the target document
    for (let i = 0; i < SouDoc.Sections.Count; i++) {
      let section = SouDoc.Sections.get_Item(i);
      TarDoc.Sections.Add(section.Clone());
    }

    // Define the output file name
    const outputFileName = 'MergeBySection_out.docx';

    // Save the merged document
    TarDoc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });

    // Read the merged file from VFS and trigger the download
    const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([modifiedFileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);

    // Release resources
    TarDoc.Dispose();
    SouDoc.Dispose();
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Merge Word Documents by Section</h1>
      <button onClick={mergeBySection}>
        Merge Documents
      </button>
    </div>
  );
}

export default App;
After merging by section, each section of the source document occupies its own page in the target document:
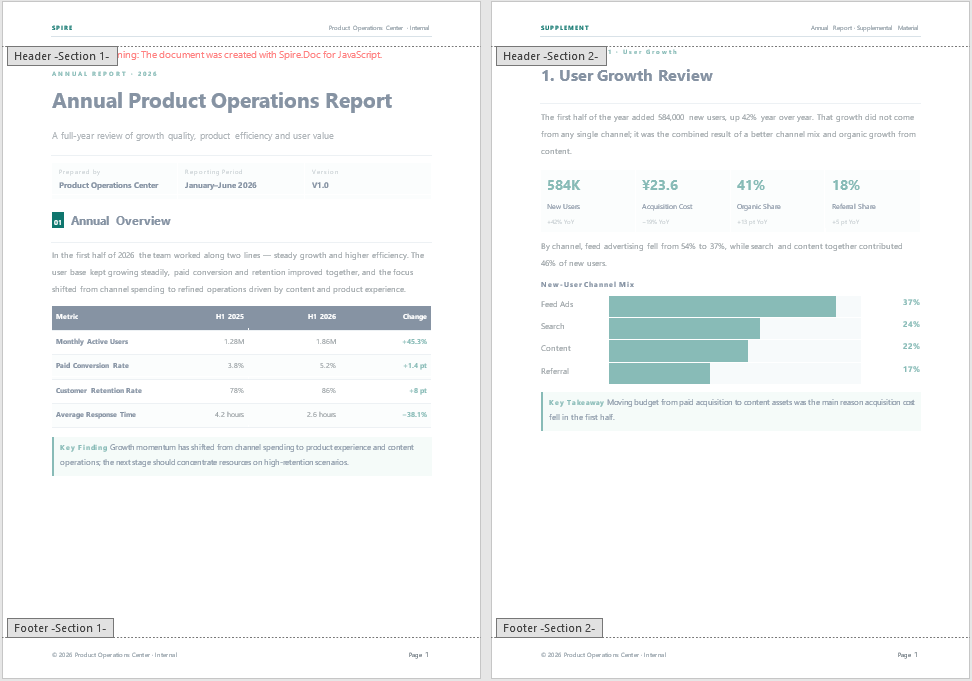
Merge Only Selected Sections from the Source Document
If only a few sections of the source document are required, there is no need to iterate over the entire Sections collection; retrieve the desired section by index and clone it:
// Clone only the first section of the source document and append it to the end of the target document
const section = SouDoc.Sections.get_Item(0);
TarDoc.Sections.Add(section.Clone());
Merge Word Documents on the Same Page
Same-page merging differs from section-by-section merging in that it does not create new sections for the source document. Instead, it clones the paragraphs, tables, images and other elements of the source document one by one and appends them to the same section of the target document. The two approaches map to the following APIs:
| Approach | Content Appended | Pagination |
|---|---|---|
Sections.Add(section.Clone()) |
A complete section of the source document | Each section starts on a new page |
Body.ChildObjects.Add(obj.Clone()) |
One content element from a section of the source document | Content flows continuously without creating a new section |
The steps are as follows:
- Obtain the Spire.Doc WASM module and confirm that it is ready.
- Read both sample Word documents into VFS, create a
Documentobject and load the target document. - Record the target document's current section count so that the last section can be located.
- Create another
Documentobject and load the source document, then iterate over theBody.ChildObjectsof each of its sections with two nested loops. - Use
ChildObjects.Add(obj.Clone())to append each content element to the end of the last section'sChildObjectscollection in the target document. - Save the result with the
Document.SaveToFile()method. - Read the result file back from VFS and trigger a browser download.
The code for merging Word documents on the same page is as follows:
function App() {
  const mergeOnSamePage = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Check if the module is ready
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

	// Read both sample documents into VFS
    const inputFileName1 = 'Template_Docx_1.docx';
    await window.spire.FetchFileToVFS(inputFileName1, '', `${process.env.PUBLIC_URL}static/data/`);
    const inputFileName2 = 'Template_Docx_2.docx';
    await window.spire.FetchFileToVFS(inputFileName2, '', `${process.env.PUBLIC_URL}static/data/`);

    // Load the target document
    const destinationDocument = new docModule.Document();
    destinationDocument.LoadFromFile(inputFileName1);

    // Record the current section count of the target document
    let count = destinationDocument.Sections.Count;

    // Load the source document
    const doc = new docModule.Document();
    doc.LoadFromFile(inputFileName2);

    // Iterate over every content element of the source document and clone it into the last section of the target document
    for (let i = 0; i < doc.Sections.Count; i++) {
      let section = doc.Sections.get_Item(i);
      for (let j = 0; j < section.Body.ChildObjects.Count; j++) {
        let obj = section.Body.ChildObjects.get_Item(j);
        destinationDocument.Sections.get_Item(count - 1).Body.ChildObjects.Add(obj.Clone());
      }
    }

    // Define the output file name
    const outputFileName = 'MergeOnSamePage_out.docx';

    // Save the merged document
    destinationDocument.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });

    // Read the merged file from VFS and trigger the download
    const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([modifiedFileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);

    // Release resources
    destinationDocument.Dispose();
    doc.Dispose();
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Merge Word Documents on the Same Page</h1>
      <button onClick={mergeOnSamePage}>
        Merge Documents
      </button>
    </div>
  );
}

export default App;
After same-page merging, the source document's content is appended continuously to the last section of the target document, producing no page breaks:
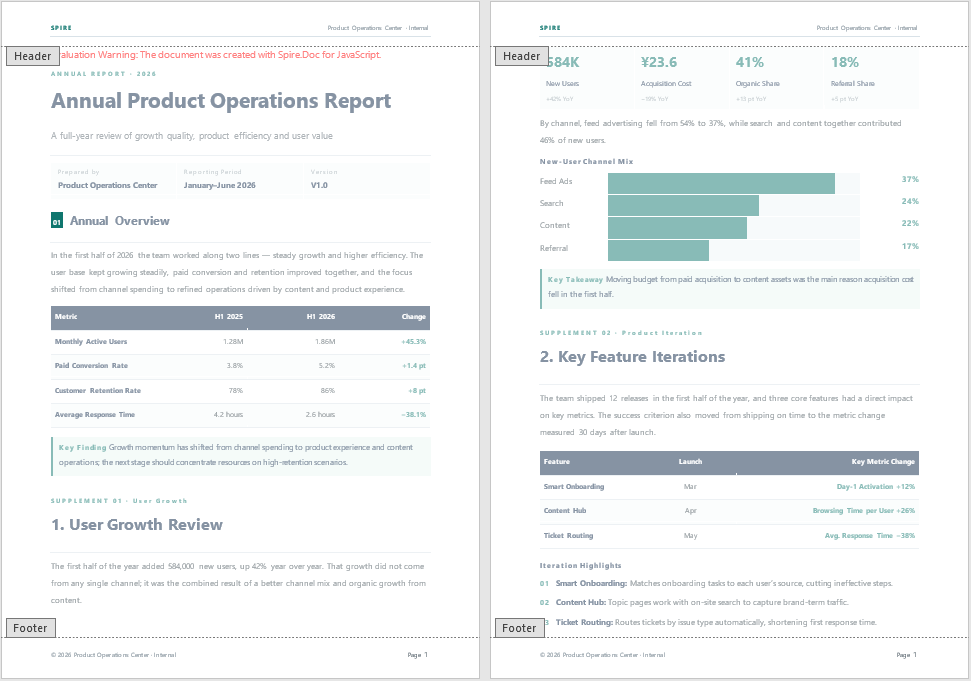
FAQ
Will the merged file be uploaded to a server?
No. Spire.Doc for JavaScript runs in the browser on WebAssembly, reads and writes documents locally through a virtual file system (VFS), and performs merging and saving entirely on the client; the library itself never sends files to a server. Whether the file ultimately leaves the device depends on any other code you add to the page.
Can multiple Word documents be merged at once?
Yes — simply process them in a loop. Load each source document in turn; when merging by section, call Sections.Add(section.Clone()) for every section of every source document, and when merging on the same page, loop over Body.ChildObjects for each source document. With a large number of documents, keep an eye on browser memory and call Dispose() promptly to release Document objects that are no longer needed.
Why does the source content start on a new page after merging by section?
Cause: Section.Clone() copies a complete section, including its own page setup. Once the section is appended to the target document, the merged content therefore usually starts on a new page.
Solution: When the content has to flow continuously, switch to same-page merging and append the source document's paragraphs, tables and other elements one by one to the last section of the target document:
// Append element by element without creating a new section
destinationDocument.Sections.get_Item(count - 1).Body.ChildObjects.Add(obj.Clone());
What should I do if the merged Word document cannot be opened?
Cause: The save format does not match the file extension, or the Blob's MIME type does not match the actual file format at download time, so the browser or Word may fail to identify the file correctly.
Solution: Keep the save format, the extension and the MIME type consistent. When fileFormat in SaveToFile() is Docx2013, keep the .docx extension in the output file name and use the corresponding DOCX type for the Blob's type:
const blob = new Blob([fileArray], {
  type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document'
});
Are images and tables preserved after merging?
Generally yes. Merging by section clones whole sections, while same-page merging clones the paragraphs, tables and other child objects under a section's Body; this content is written to the target document along with the clone, and images inside paragraphs are usually preserved as well. After merging, open the result file to check the layout.
Get a Free License
Spire.Doc for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Tables are core elements for organizing and presenting data in Word documents, and proper table layout directly impacts readability and professionalism. Spire.Doc for JavaScript runs entirely in the browser via WebAssembly, enabling you to auto-fit tables directly using a virtual file system (VFS) to manage fonts and files — no backend server required.
This article covers three core features:
For installation and project setup, refer to Integrating Spire.Doc for JavaScript in a React Project. The examples below assume Spire.Doc is installed and the WebAssembly module is initialized.
1. AutoFit to Contents
Auto-fitting a table to its contents involves three steps: first, load the font files and the target document into the WASM virtual file system via FetchFileToVFS; then instantiate a Document, load the file, retrieve the target table, and call AutoFit with the AutoFitToContents parameter; finally, save the document, read the generated file from VFS, wrap it as a Blob, and trigger a browser download.
function App() {
  const autoFitToContents = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Check if the module is ready
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load fonts and the document file into VFS
    await window.spire.FetchFileToVFS('ARIALUNI.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    const inputFileName = 'TableSample.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Load the document
    const doc = new docModule.Document();
    doc.LoadFromFile(inputFileName);

    // Get the first table in the first section
    let section = doc.Sections.get_Item(0);
    let table = section.Tables.get_Item(0);

    // Auto-fit column widths based on cell content
    table.AutoFit(docModule.AutoFitBehaviorType.AutoFitToContents);

    // Define the output file name
    const outputFileName = "AutoFitToContents_output.docx";

    // Save the document
    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });

    // Release resources
    doc.Dispose();

    // Read the generated file from VFS and trigger download
    const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([modifiedFileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>AutoFit to Contents</h1>
      <button onClick={autoFitToContents}>
        Generate
      </button>
    </div>
  );
}

export default App;
After applying the AutoFitToContents mode, each column width shrinks to match the actual length of its cell content, resulting in a compact table with no extra whitespace.
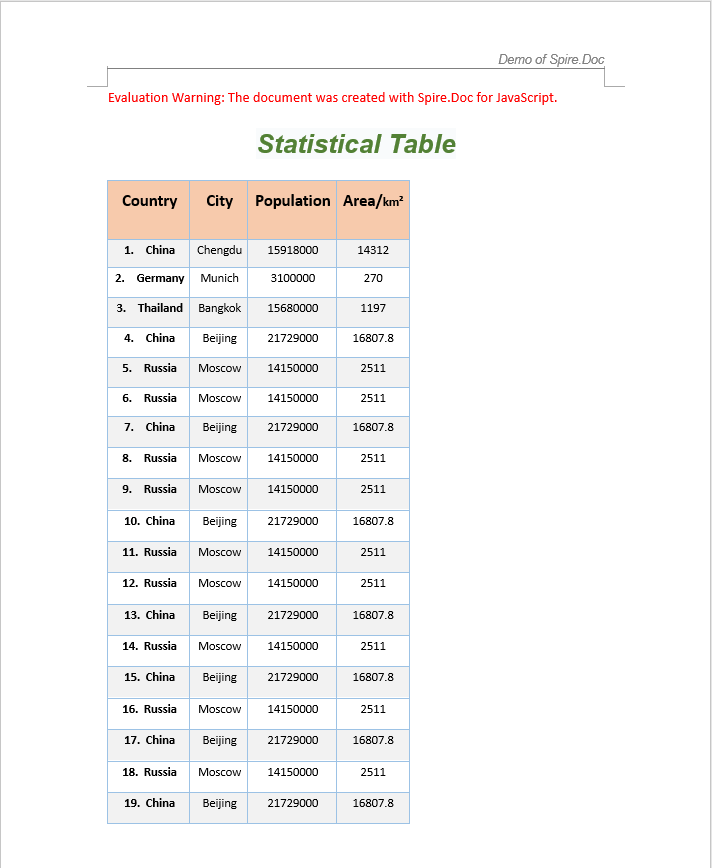
2. AutoFit to Window
Auto-fitting a table to the window allows the table width to adapt to the page width, which is ideal for scenarios where the table should fill the full page width.
function App() {
  const autoFitToWindow = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Check if the module is ready
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load fonts and the document file into VFS
    await window.spire.FetchFileToVFS('ARIALUNI.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    const inputFileName = 'TableSample.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Load the document
    const doc = new docModule.Document();
    doc.LoadFromFile(inputFileName);

    // Get the first table in the first section
    let section = doc.Sections.get_Item(0);
    let table = section.Tables.get_Item(0);

    // Auto-fit the table to the page width
    table.AutoFit(docModule.AutoFitBehaviorType.AutoFitToWindow);

    // Define the output file name
    const outputFileName = "AutoFitToWindow_output.docx";

    // Save the document
    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });

    // Release resources
    doc.Dispose();

    // Read the generated file from VFS and trigger download
    const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([modifiedFileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>AutoFit to Window</h1>
      <button onClick={autoFitToWindow}>
        Generate
      </button>
    </div>
  );
}

export default App;
After applying the AutoFitToWindow mode, the table width expands to match the page width, with columns distributed proportionally.
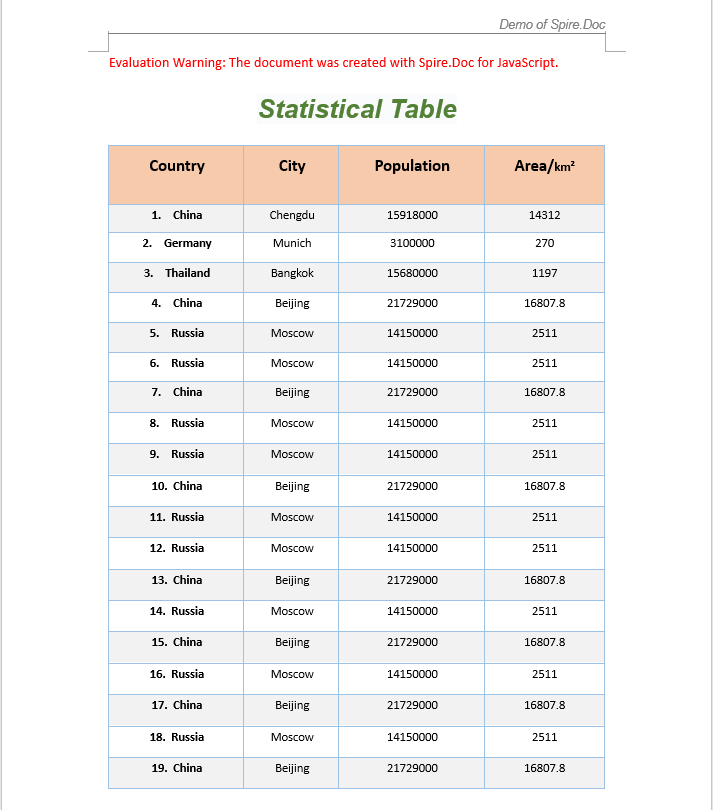
3. Fixed Column Widths
When a table already has carefully designed column widths that should not change as content is added or removed, you can use the fixed column widths mode to prevent Word from automatically resizing columns.
function App() {
  const fixedColumnWidths = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Check if the module is ready
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    // Load fonts and the document file into VFS
    await window.spire.FetchFileToVFS('ARIALUNI.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    const inputFileName = 'TableSample.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}/data/`);

    // Load the document
    const doc = new docModule.Document();
    doc.LoadFromFile(inputFileName);

    // Get the first table in the first section
    let section = doc.Sections.get_Item(0);
    let table = section.Tables.get_Item(0);

    // Fix column widths to prevent auto-resizing
    table.AutoFit(docModule.AutoFitBehaviorType.FixedColumnWidths);

    // Define the output file name
    const outputFileName = "FixedColumnWidths_output.docx";

    // Save the document
    doc.SaveToFile({ fileName: outputFileName, fileFormat: docModule.FileFormat.Docx2013 });

    // Release resources
    doc.Dispose();

    // Read the generated file from VFS and trigger download
    const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([modifiedFileArray], { type: 'application/vnd.openxmlformats-officedocument.wordprocessingml.document' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Fixed Column Widths</h1>
      <button onClick={fixedColumnWidths}>
        Generate
      </button>
    </div>
  );
}

export default App;
With fixed column widths enabled, the column sizes remain unchanged regardless of changes to cell content, ensuring consistent layout.
FAQ
AutoFit method does not change the table layout
Cause: The parameter type passed to the AutoFit method is incorrect, or the table is locked and does not allow layout adjustments.
Solution: Ensure you use the correct AutoFitBehaviorType enum value:
// AutoFit to contents
table.AutoFit(docModule.AutoFitBehaviorType.AutoFitToContents);

// AutoFit to window
table.AutoFit(docModule.AutoFitBehaviorType.AutoFitToWindow);

// Fixed column widths
table.AutoFit(docModule.AutoFitBehaviorType.FixedColumnWidths);
Index out of range when accessing a table
Cause: The document does not contain a section or table at the specified index. Indexing starts from 0, but the document may have no corresponding object.
Solution: Check the section and table counts before accessing them:
if (document.Sections.Count > 0 && document.Sections.get_Item(0).Tables.Count > 0) {
  let section = document.Sections.get_Item(0);
  let table = section.Tables.get_Item(0);
  table.AutoFit(docModule.AutoFitBehaviorType.AutoFitToContents);
}
Get a Free License
Spire.Doc for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
In document management systems, splitting Word documents is a common requirement — separating merged multi-chapter documents into independent files by section breaks, or dividing long documents into shorter ones by page breaks. Spire.Doc for JavaScript performs document splitting directly in the browser via WebAssembly, using a virtual file system (VFS) to manage input and output files — no backend server required.
This article covers two core features:
For installation and project setup, refer to Integrating Spire.Doc for JavaScript in a React Project. The examples below assume Spire.Doc is installed and the WebAssembly module is initialized.
Split by Section Break
Section breaks in a Word document separate different chapters or page layouts. Each section can have its own headers, footers, page numbering, and page setup. Splitting by section breaks is the most common and stable approach, ideal for restoring merged multi-chapter documents back into independent files.
The core workflow consists of three stages: first, load the font files and the target Word file into the WASM virtual file system; then instantiate a Document, load the file, iterate through all sections, and clone each section into a new Document object via Section.Clone(); finally, package the split files into a ZIP archive and trigger a browser download.
function App() {
  const splitBySectionBreak = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Check if the module is ready
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    const inputFileName = 'Template_Docx_4.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}data/`);

    // Create output directory
    let outputDir = 'output/';
    window.dotnetRuntime.Module.FS.mkdirTree(outputDir);

    // Load the document
    const doc = new docModule.Document();
    doc.LoadFromFile(inputFileName);

    // Iterate through each section and clone into independent documents
    for (let i = 0; i < doc.Sections.Count; i++) {
      const newWord = new docModule.Document();
      newWord.Sections.Add(doc.Sections.get_Item(i).Clone());
      newWord.SaveToFile({
        fileName: outputDir + `Section-${i}.docx`,
        fileFormat: docModule.FileFormat.Docx2013
      });
      newWord.Dispose();
    }
    doc.Dispose();

    // Read output files from VFS and package into ZIP for download
    const JSZip = require('jszip');
    const zip = new JSZip();
    let items = window.dotnetRuntime.Module.FS.readdir(outputDir);
    items = items.filter(item => item !== '.' && item !== '..');
    for (const item of items) {
      const fileData = window.dotnetRuntime.Module.FS.readFile(outputDir + item);
      zip.file(item, fileData);
    }
    const zipBlob = await zip.generateAsync({ type: 'blob' });
    const url = URL.createObjectURL(zipBlob);
    const a = document.createElement('a');
    a.href = url;
    a.download = 'SplitBySectionBreak.zip';
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Split Word Document By Section Break</h1>
      <button onClick={splitBySectionBreak}>Generate</button>
    </div>
  );
}

export default App;
Independent Word documents generated after splitting by section break
Split by Page Break
Page breaks are manual or automatic pagination markers inserted within a document. Splitting by page breaks is suitable for dividing long documents by page, saving each page's content as an independent document — commonly used for report pagination, contract clause splitting, and similar scenarios.
Unlike splitting by section breaks, page breaks reside at the child-object level within paragraphs. This requires traversing the document's sections, paragraphs, and paragraph child objects layer by layer to detect Break elements with the PageBreak type. When splitting, you also need to clone the original document's styles and themes using methods such as CloneDefaultStyleTo, CloneThemesTo, and CloneCompatibilityTo to ensure the split documents retain full formatting.
function App() {
  const splitByPageBreak = async () => {
    // Get the Spire.Doc WASM module
    const docModule = window.wasmModule?.spiredoc;

    // Check if the module is ready
    if (!docModule) {
      alert('Spire.Doc is not ready yet');
      return;
    }

    const inputFileName = 'SplitWordFileByPageBreak.docx';
    await window.spire.FetchFileToVFS(inputFileName, '', `${process.env.PUBLIC_URL}data/`);

    // Create output directory
    let outputDir = 'output/';
    window.dotnetRuntime.Module.FS.mkdirTree(outputDir);

    // Load the original document
    const original = new docModule.Document();
    original.LoadFromFile(inputFileName);

    // Create a new document and clone styles and themes
    let newWord = new docModule.Document();
    let section = newWord.AddSection();
    original.CloneDefaultStyleTo(newWord);
    original.CloneThemesTo(newWord);
    original.CloneCompatibilityTo(newWord);

    let index = 0;

    // Iterate through all sections
    for (let i = 0; i < original.Sections.Count; i++) {
      let sec = original.Sections.get_Item(i);

      // Iterate through all child objects in the section (paragraphs, tables, etc.)
      for (let j = 0; j < sec.Body.ChildObjects.Count; j++) {
        let obj = sec.Body.ChildObjects.get_Item(j);

        if (obj instanceof docModule.Paragraph) {
          let para = obj;
          sec.CloneSectionPropertiesTo(section);
          section.Body.ChildObjects.Add(para.Clone());

          // Detect page breaks within paragraph child objects
          for (let k = 0; k < para.ChildObjects.Count; k++) {
            let parobj = para.ChildObjects.get_Item(k);
            if (parobj instanceof docModule.Break &&
                parobj.BreakType === docModule.BreakType.PageBreak) {

              let breakIndex = para.ChildObjects.IndexOf(parobj);

              // Remove the page break from the paragraph
              section.Body.LastParagraph.ChildObjects.RemoveAt(breakIndex);

              // Save the current document
              newWord.SaveToFile({
                fileName: outputDir + `Page-${index}.docx`,
                fileFormat: docModule.FileFormat.Docx2013
              });
              index++;

              // Create a new document to continue
              newWord = new docModule.Document();
              section = newWord.AddSection();
              original.CloneDefaultStyleTo(newWord);
              original.CloneThemesTo(newWord);
              original.CloneCompatibilityTo(newWord);
              sec.CloneSectionPropertiesTo(section);

              // Handle remaining content after the page break
              section.Body.ChildObjects.Add(para.Clone());
              if (section.Paragraphs.get_Item(0).ChildObjects.Count === 0) {
                section.Body.ChildObjects.RemoveAt(0);
              } else {
                while (breakIndex >= 0) {
                  section.Paragraphs.get_Item(0).ChildObjects.RemoveAt(breakIndex);
                  breakIndex--;
                }
              }
            }
          }
        }

        if (obj instanceof docModule.Table) {
          section.Body.ChildObjects.Add(obj.Clone());
        }
      }
    }

    // Save the last document
    newWord.SaveToFile({
      fileName: outputDir + `Page-${index}.docx`,
      fileFormat: docModule.FileFormat.Docx2013
    });

    original.Dispose();
    newWord.Dispose();

    // Package into ZIP for download
    const JSZip = require('jszip');
    const zip = new JSZip();
    let items = window.dotnetRuntime.Module.FS.readdir(outputDir);
    items = items.filter(item => item !== '.' && item !== '..');
    for (const item of items) {
      const fileData = window.dotnetRuntime.Module.FS.readFile(outputDir + item);
      zip.file(item, fileData);
    }
    const zipBlob = await zip.generateAsync({ type: 'blob' });
    const url = URL.createObjectURL(zipBlob);
    const a = document.createElement('a');
    a.href = url;
    a.download = 'SplitByPageBreak.zip';
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Split Word Document By Page Break</h1>
      <button onClick={splitByPageBreak}>Generate</button>
    </div>
  );
}

export default App;
Word documents generated after splitting by page break
FAQ
Split document formatting differs from the original
Cause: When splitting by page break, only the paragraph content is cloned without also cloning the original document's styles, themes, and section properties. This causes the split documents to lose formatting information such as fonts, colors, and page setup.
Solution: After creating a new document, clone the original document's styles and themes using the following methods:
original.CloneDefaultStyleTo(newWord);
original.CloneThemesTo(newWord);
original.CloneCompatibilityTo(newWord);
sec.CloneSectionPropertiesTo(section);
Page break cannot be detected
Cause: Page breaks reside within paragraph child objects and are identified via the BreakType enumeration. If the traversal hierarchy is incorrect, or the instanceof check is not used to determine the object type, the page break may not be properly recognized.
Solution: Ensure detection follows the order: Paragraph.ChildObjects → instanceof Break → BreakType == BreakType.PageBreak:
for (let k = 0; k < para.ChildObjects.Count; k++) {
  let parobj = para.ChildObjects.get_Item(k);
  if (parobj instanceof docModule.Break &&
      parobj.BreakType === docModule.BreakType.PageBreak) {
    // Page break found
  }
}
Get a Free License
Spire.Doc for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.