How to Compress PDF Documents with JavaScript in React
PDF keeps its layout fixed and identical across devices, which makes it the format of choice for distributing contracts, reports, and photo albums. But PDFs that contain many high-resolution images or embedded fonts are often very large: they eat up storage space and slow down emailing, web uploads, and downloads. If the document can be “slimmed down” directly in the browser while keeping it readable, distribution and loading get noticeably better — without uploading the file to a server and waiting for processing.
Spire.PDF for JavaScript runs on WebAssembly and completes the loading, compression, and saving of PDFs entirely in the browser, managing input and output files through a virtual file system (VFS) with no backend required. It ships a dedicated PdfCompressor, whose Options control the compression strategy along three dimensions: first ImageCompressionOptions resizes and re-compresses the images in the document, second TextCompressionOptions compresses font data or even removes embedded fonts, and third CompressContents re-compresses the page content streams. The three can be freely combined in a single pass to balance visual quality against file size.
This article first introduces the three compression dimensions of PdfCompressor, and then gives a complete runnable example that combines them:
- Compressing Images in a PDF
- Compressing Fonts and Unembedding Fonts in a PDF
- Compressing PDF Content Streams
- Combining All Three Approaches to Compress a PDF
For installation and project configuration, refer to Integrating Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module has been initialized.
Compressing Images in a PDF
High-resolution bitmaps on a page are usually the main source of a PDF's size. Options.ImageCompressionOptions controls image scaling and re-encoding with three properties:
| Property | What it does | Effect and trade-off |
|---|---|---|
ResizeImages |
Scales images down proportionally and re-encodes them | Noticeably reduces the size; suited to very large, high-resolution images |
CompressImage |
Performs lossy compression on images | Smaller file at the cost of a little image quality |
ImageQuality |
Controls the quality tier used for re-encoding | High gives better quality but a larger file; Low gives a smaller file but images may look softer |
For an image-heavy document, a typical approach is to enable ResizeImages and CompressImage first, then pick the ImageQuality tier that matches your tolerance for quality loss:
// Compress images in the document: resize, re-compress, and lower the quality
compressor.Options.ImageCompressionOptions.ResizeImages = true;
compressor.Options.ImageCompressionOptions.CompressImage = true;
compressor.Options.ImageCompressionOptions.ImageQuality = pdfModule.ImageQuality.Low;
Compressing Fonts and Unembedding Fonts in a PDF
A PDF embeds the fonts used in its text as subsets inside the file, and several fonts with multiple weights can add up to a fair amount of size. Options.TextCompressionOptions offers two ways to handle fonts:
| Property | What it does | Effect and trade-off |
|---|---|---|
CompressFonts |
Compresses the embedded font data and keeps the fonts | Same rendering, smaller file, no display risk |
UnembedFonts |
Removes the fonts and lets the reader render with system fonts | Even smaller file; glyphs may be substituted if the target system lacks the fonts |
UnembedFonts shrinks the file further but carries a display risk, so whether to enable it depends on where the document will be viewed:
// Compress font data; UnembedFonts goes further and removes the embedded fonts
compressor.Options.TextCompressionOptions.CompressFonts = true;
compressor.Options.TextCompressionOptions.UnembedFonts = true;
Compressing PDF Content Streams
The text and vector drawing commands on a PDF page are stored as “content streams”. They are usually compressed when generated, but after repeated edits or processing by different tools they can still hold redundancy. Options.CompressContents re-compresses the document's content streams, which can also free up some space in text-heavy, layout-complex documents:
// Re-compress the document content streams
compressor.Options.CompressContents = true;
Combining All Three Approaches to Compress a PDF
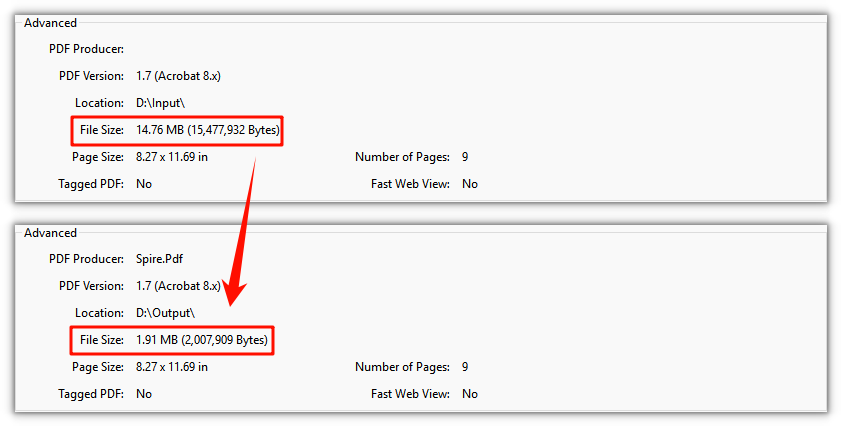
Combining the three approaches above gives a complete compression flow that balances effect and speed: after loading the PDF, enable image, font, and content compression in one pass, then call CompressToFile to write the result to a new file. The example below enables ResizeImages, CompressImage (with the High quality tier), CompressFonts, UnembedFonts, and CompressContents all at once on a PDF that contains both high-resolution images and text, and produces a new document that is clearly smaller:
function App() {
  const compressPdfDocument = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check that the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF to be compressed into the VFS
    const inputFileName = 'ImageDocument.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfCompressor and point it at the PDF to compress
    let compressor = new pdfModule.PdfCompressor({ filePath: inputFileName });

    // 1. Image compression: resize and re-compress images, with a higher quality tier
    compressor.Options.ImageCompressionOptions.ResizeImages = true;
    compressor.Options.ImageCompressionOptions.CompressImage = true;
    compressor.Options.ImageCompressionOptions.ImageQuality = pdfModule.ImageQuality.High;

    // 2. Font compression: compress font data and remove embedded fonts
    compressor.Options.TextCompressionOptions.CompressFonts = true;
    compressor.Options.TextCompressionOptions.UnembedFonts = true;

    // 3. Content compression: re-compress the document content streams
    compressor.Options.CompressContents = true;

    // Define the output file name and compress to it
    const outputFileName = 'CompressedDocument.pdf';
    compressor.CompressToFile(outputFileName);

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Compress PDF Document</h1>
      <button onClick={compressPdfDocument}>
        Generate
      </button>
    </div>
  );
}

export default App;
PDF document compressed by combining all three approaches
FAQ
Why is the file still large after compression when the PDF has few images
Reason: The size does not always come from images. When the pages are text-heavy, the size is more likely to come from the embedded fonts and the page content streams, so enabling image compression alone helps little.
Solution: Cover the other dimensions as well — compress font data with TextCompressionOptions (using UnembedFonts to remove embedded fonts when appropriate) and re-compress the content streams with CompressContents, so that text-heavy documents also shrink noticeably.
Will unembedding fonts cause the text to display incorrectly
Reason: UnembedFonts removes the font programs from the PDF, so the reader renders the text with fonts installed on the system; if the target environment lacks those fonts, glyph substitution or spacing changes may occur.
Solution: For documents distributed to users whose font environments are unknown, keep the fonts embedded and only use CompressFonts to compress the font data; enable UnembedFonts only when you are sure the target system has the corresponding fonts:
// Keep fonts embedded but compress the font data to avoid display risks after unembedding
compressor.Options.TextCompressionOptions.UnembedFonts = false;
compressor.Options.TextCompressionOptions.CompressFonts = true;
How should I trade off the image quality tier against the compression methods
Reason: ImageQuality only affects the quality and size of the re-encoded images; depending on the document, the part that contributes the most to its size differs, so a single dimension rarely reaches an ideal compression ratio.
Solution: For image-heavy documents, enable ResizeImages and CompressImage first and choose between the High/Low tiers; for text-heavy documents, focus on font compression and content compression. If fonts must stay embedded, just turn off UnembedFonts — the other compression options are unaffected:
// For image-heavy documents, choose the lower quality tier for a smaller file
compressor.Options.ImageCompressionOptions.ImageQuality = pdfModule.ImageQuality.Low;
Get a Free License
If you want to remove the evaluation message from the result documents or get rid of feature limitations, please contact sales to obtain a free 30-day temporary license.
How to Split PDF Documents Using JavaScript in React
Splitting PDF documents is a common requirement in web applications. For example, you may need to divide a long report into single-page files, extract the cover page separately, or separate the first page from the remaining pages for further processing. Instead of uploading files to a server, you can perform these operations directly in a React application with JavaScript.
Spire.PDF for JavaScript enables developers to load, manipulate, and save PDF documents in browser-based applications. It works with WebAssembly and a virtual file system, allowing PDF files to be processed on the client side.
This article demonstrates how to split PDF documents using JavaScript in React with Spire.PDF for JavaScript.
Install Spire.PDF for JavaScript in a React Project
Open a terminal in the root directory of your React project and install the spire.office package:
npm i spire.office
After the installation is complete, copy the following runtime files and folder from the installed package to the React project's public folder:
public/
├── _framework/
├── spire.pdf.js
├── Spire.Pdf.Wasm.zip
├── spire.common.js
└── Spire.Common.Wasm.zip
The JavaScript loader, WebAssembly resources, and supporting framework files must remain accessible as static assets when the application runs. For detailed setup instructions and the exact integration process, see How to Integrate Spire.PDF for JavaScript in a React Project.
In the examples below, the PDF file to be split is named input.pdf. Place this file in the public folder as well, so that it can be loaded in the React application.
public/
├── input.pdf
└── ...
Split a PDF into Individual Files by Page in JavaScript
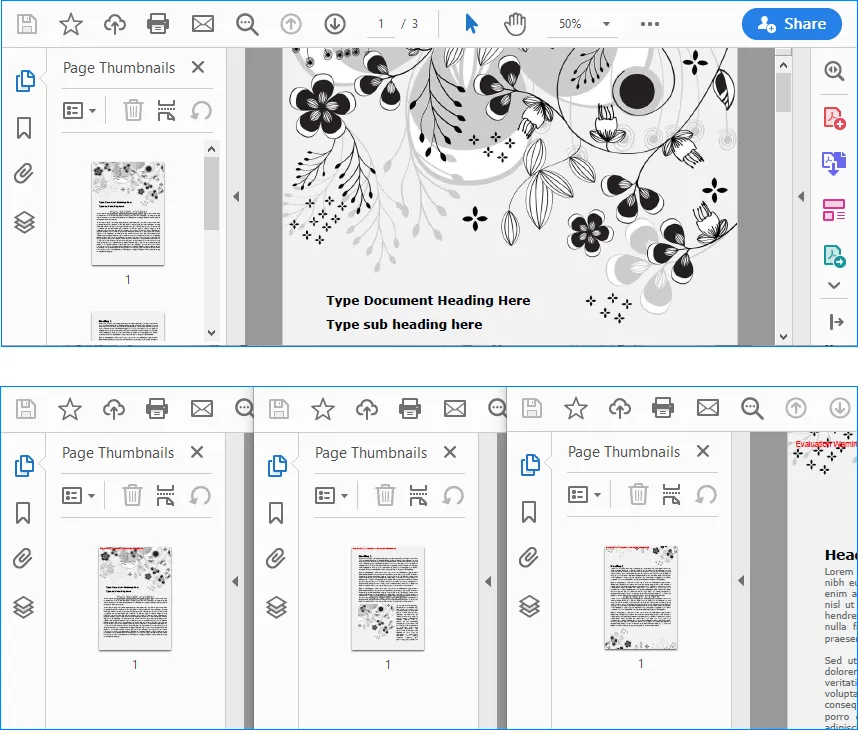
If you want to split a PDF document into multiple single-page PDF files, you can use the Split() method. This method separates the original PDF into individual documents and saves each page as a new PDF file.
The following example loads input.pdf, splits it page by page, and downloads each generated PDF file in the browser.
import React, { useState, useEffect } from 'react';

function App() {
  const [wasmModule, setWasmModule] = useState(null);

  useEffect(() => {
    (async () => {
      const publicUrl = process.env.PUBLIC_URL || '';
      const spireModule = await import(/* webpackIgnore: true */ `${publicUrl}/spire.pdf.js`);
      const rawModule = spireModule.default || spireModule;
      window.wasmModule = typeof rawModule === 'function'
        ? await rawModule({ locateFile: p => p.endsWith('.wasm') ? `${publicUrl}/${p}` : p })
        : rawModule;
      setWasmModule(window.wasmModule);
    })();
  }, []);

  const loadPdfToVfs = async (fileName) => {
    const publicUrl = process.env.PUBLIC_URL || '';
    const response = await fetch(`${publicUrl}/${fileName}`);
    const fileBytes = new Uint8Array(await response.arrayBuffer());
    window.dotnetRuntime.Module.FS.writeFile(fileName, fileBytes, { flags: 'w+' });
    return fileName;
  };

  const SplitPdf = async () => {
    const wasmModule = window.wasmModule?.spirepdf;
    if (!wasmModule) return;

    const inputFile = await loadPdfToVfs('input.pdf');

    const doc = new wasmModule.PdfDocument();
    doc.LoadFromFile(inputFile);

    const pageCount = doc.Pages.Count;
    const outFileName = 'SplitDocument_result-{0}.pdf';
    doc.Split(outFileName);

    for (let i = 0; i < pageCount; i++) {
      const splitFileName = `SplitDocument_result-${i}.pdf`;
      const fileArray = window.dotnetRuntime.Module.FS.readFile(splitFileName);
      const file = new Blob([fileArray], { type: 'application/pdf' });
      const url = URL.createObjectURL(file);
      const a = document.createElement('a');
      a.href = url;
      a.download = splitFileName;
      document.body.appendChild(a);
      a.click();
      document.body.removeChild(a);
      URL.revokeObjectURL(url);
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Split PDF Documents in React</h1>
      <button onClick={SplitPdf} disabled={!wasmModule}>
        Split PDF
      </button>
    </div>
  );
}

export default App;
Output:
Code Explanation
The code first imports and initializes the Spire.PDF WebAssembly module when the React component is mounted.
const spireModule = await import(/* webpackIgnore: true */ `${publicUrl}/spire.pdf.js`);
Then, the loadPdfToVfs() function loads input.pdf from the public folder and writes it into the virtual file system:
window.dotnetRuntime.Module.FS.writeFile(fileName, fileBytes, { flags: 'w+' });
After the PDF file is loaded, a PdfDocument object is created and the source PDF is opened:
const doc = new wasmModule.PdfDocument();
doc.LoadFromFile(inputFile);
The Split() method splits the PDF document into separate PDF files. The {0} placeholder in the output file name is replaced by the page index:
const outFileName = 'SplitDocument_result-{0}.pdf';
doc.Split(outFileName);
Finally, the generated PDF files are read from the virtual file system, converted into Blob objects, and downloaded in the browser.
Split a PDF by Page Range in JavaScript
In some cases, you may not want to split every page into a separate file. Instead, you may want to extract one page as an individual PDF and save the remaining pages as another PDF. This can be done by creating new PdfDocument objects and inserting selected pages from the source document.
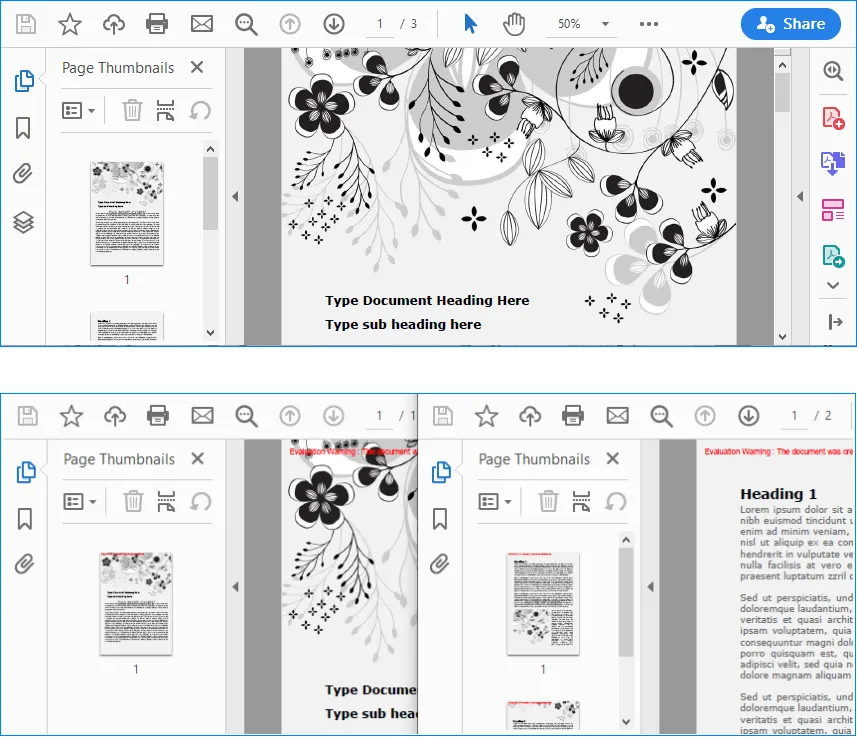
The following example splits input.pdf into two files:
Split-1.pdf: contains the first pageSplit-2.pdf: contains the remaining pages
import React, { useState, useEffect } from 'react';

function App() {
  const [wasmModule, setWasmModule] = useState(null);

  useEffect(() => {
    (async () => {
      const publicUrl = process.env.PUBLIC_URL || '';
      const spireModule = await import(/* webpackIgnore: true */ `${publicUrl}/spire.pdf.js`);
      const rawModule = spireModule.default || spireModule;
      window.wasmModule = typeof rawModule === 'function'
        ? await rawModule({ locateFile: p => p.endsWith('.wasm') ? `${publicUrl}/${p}` : p })
        : rawModule;
      setWasmModule(window.wasmModule);
    })();
  }, []);

  const loadPdfToVfs = async (fileName) => {
    const publicUrl = process.env.PUBLIC_URL || '';
    const response = await fetch(`${publicUrl}/${fileName}`);
    const fileBytes = new Uint8Array(await response.arrayBuffer());
    window.dotnetRuntime.Module.FS.writeFile(fileName, fileBytes, { flags: 'w+' });
    return fileName;
  };

  const SplitPdf = async () => {
    const wasmModule = window.wasmModule?.spirepdf;
    if (!wasmModule) return;

    const inputFile = await loadPdfToVfs('input.pdf');

    const doc = new wasmModule.PdfDocument();
    doc.LoadFromFile(inputFile);

    const newDoc1 = new wasmModule.PdfDocument();
    const newDoc2 = new wasmModule.PdfDocument();

    newDoc1.InsertPage(doc, 0);
    newDoc2.InsertPageRange(doc, 1, doc.Pages.Count - 1);

    newDoc1.SaveToFile('Split-1.pdf');
    newDoc2.SaveToFile('Split-2.pdf');

    for (const splitFileName of ['Split-1.pdf', 'Split-2.pdf']) {
      const fileArray = window.dotnetRuntime.Module.FS.readFile(splitFileName);
      const file = new Blob([fileArray], { type: 'application/pdf' });
      const url = URL.createObjectURL(file);
      const a = document.createElement('a');
      a.href = url;
      a.download = splitFileName;
      document.body.appendChild(a);
      a.click();
      document.body.removeChild(a);
      URL.revokeObjectURL(url);
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Split PDF Documents in React</h1>
      <button onClick={SplitPdf} disabled={!wasmModule}>
        Split PDF
      </button>
    </div>
  );
}

export default App;
Output:
Code Explanation
This example also starts by loading the source PDF file into the virtual file system and opening it with PdfDocument.
const doc = new wasmModule.PdfDocument();
doc.LoadFromFile(inputFile);
Then, two new PDF documents are created:
const newDoc1 = new wasmModule.PdfDocument();
const newDoc2 = new wasmModule.PdfDocument();
The first page of the source PDF is inserted into newDoc1:
newDoc1.InsertPage(doc, 0);
The remaining pages are inserted into newDoc2 with InsertPageRange():
newDoc2.InsertPageRange(doc, 1, doc.Pages.Count - 1);
Here, page indexes are zero-based. The number 1 means the second page of the original PDF, and doc.Pages.Count - 1 means all remaining pages after the first page.
After inserting the selected pages, the two new PDF documents are saved:
newDoc1.SaveToFile('Split-1.pdf');
newDoc2.SaveToFile('Split-2.pdf');
Finally, both output files are read from the virtual file system and downloaded to the local computer.
Conclusion
This article demonstrated how to split PDF documents in a React application using Spire.PDF for JavaScript. With the Split() method, you can divide a PDF into separate single-page documents. With InsertPage() and InsertPageRange(), you can extract specific pages or page ranges into new PDF files.
These methods are useful for building browser-based PDF tools, document management systems, online file-processing applications, and other React applications that require PDF splitting without server-side processing.
FAQs
Can I split a PDF into one file per page in React?
Yes. You can use the Split() method provided by Spire.PDF for JavaScript to split a PDF document into separate PDF files. Each page of the original PDF will be saved as an individual PDF file.
Can I split only a specific page range from a PDF?
Yes. Instead of splitting every page, you can create a new PdfDocument object and use InsertPage() or InsertPageRange() to copy selected pages from the source PDF into a new PDF document.
Are page indexes zero-based in Spire.PDF for JavaScript?
Yes. Page indexes start from 0. For example, page index 0 refers to the first page, and page index 1 refers to the second page. When using InsertPageRange(), make sure the start index and page count are set correctly.
Do I need a server to split PDF documents in React?
No. With Spire.PDF for JavaScript, the PDF can be loaded, processed, and saved in the browser using WebAssembly and the virtual file system. This makes it possible to split PDF documents directly in a React application without sending the file to a server.
How to Merge PDF Documents Using JavaScript in React
Combining PDF files is a common requirement in document management applications. For example, a React application may need to assemble invoices, reports, contracts, or scanned pages into a single PDF before the file is archived or shared. When the source documents do not need to be uploaded to a server, performing the operation in the browser can also simplify the workflow.
In this tutorial, you will learn how to merge PDF documents in a React application using Spire.PDF for JavaScript. The first example combines several complete PDF files in one operation. The second example provides more precise control by taking selected pages from different PDFs and adding them to a new document.
On this page:
- Install Spire.PDF for JavaScript in a React Project
- Merge Multiple PDF Documents in React
- Merge Selected Pages from Different PDF Documents in React
- Important Implementation Notes
- Conclusion
Install Spire.PDF for JavaScript in a React Project
Open a terminal in the root directory of your React project and install the spire.office package:
npm i spire.office
After the installation is complete, copy the following runtime files and folder from the installed package to the React project's public folder:
public/
├── _framework/
├── spire.pdf.js
├── Spire.Pdf.Wasm.zip
├── spire.common.js
└── Spire.Common.Wasm.zip
The JavaScript loader, WebAssembly resources, and supporting framework files must remain accessible as static assets when the application runs. For detailed setup instructions and the exact integration process, see How to Integrate Spire.PDF for JavaScript in a React Project.
For the examples in this article, also place the input PDF files in the public folder so that the application can retrieve them with fetch():
public/
├── input_1.pdf
├── input_2.pdf
├── input_3.pdf
└── ...
Merge Multiple PDF Documents in React
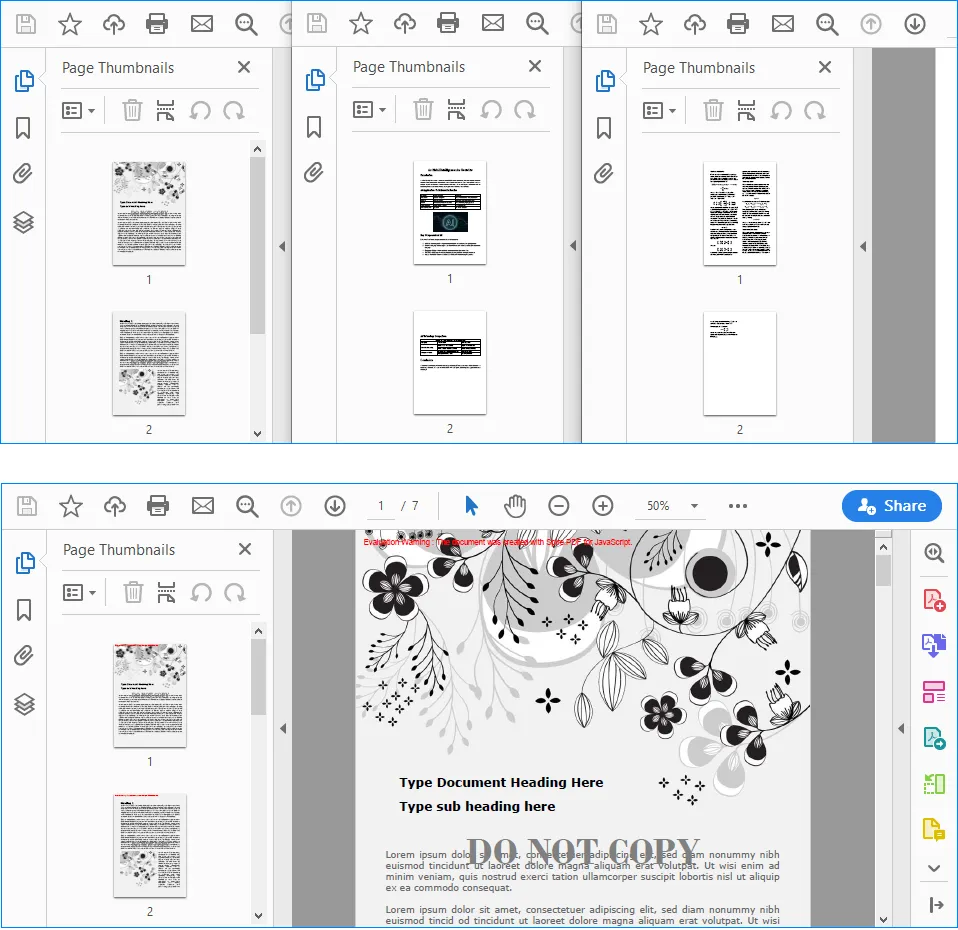
If every page in every source file should appear in the result, the most direct approach is to use the PdfMerger.Merge() method. It accepts an array of input file paths, merges the files in the order in which they appear in the array, and writes the result to the WebAssembly virtual file system.
The following React component merges input_1.pdf, input_2.pdf, and input_3.pdf into a single document named MergedPdf.pdf:
import React, { useState, useEffect } from 'react';

function App() {
  const [wasmModule, setWasmModule] = useState(null);
  const [isGenerating, setIsGenerating] = useState(false);
  const [errorMessage, setErrorMessage] = useState('');

  useEffect(() => {
    (async () => {
      try {
        const publicUrl = process.env.PUBLIC_URL || '';
        const spireModule = await import(/* webpackIgnore: true */ `${publicUrl}/spire.pdf.js`);
        const rawModule = spireModule.default || spireModule;
        window.wasmModule = typeof rawModule === 'function'
          ? await rawModule({ locateFile: p => p.endsWith('.wasm') ? `${publicUrl}/${p}` : p })
          : rawModule;
        setWasmModule(window.wasmModule);
      } catch (error) {
        console.error('Failed to load spire.pdf.js:', error);
      }
    })();
  }, []);

  const loadPdfToVfs = async (fileName) => {
    const publicUrl = process.env.PUBLIC_URL || '';
    const response = await fetch(`${publicUrl}/${fileName}`);

    if (!response.ok) {
      throw new Error(`Failed to load ${fileName}: ${response.status} ${response.statusText}`);
    }

    const fileBytes = new Uint8Array(await response.arrayBuffer());
    const pdfHeader = String.fromCharCode(...fileBytes.slice(0, 4));

    if (pdfHeader !== '%PDF') {
      throw new Error(`${fileName} was loaded, but it is not a valid PDF file.`);
    }

    window.dotnetRuntime.Module.FS.writeFile(fileName, fileBytes, { flags: 'w+' });
    return fileName;
  };

  const MergePdfs = async () => {
    const wasmModule = window.wasmModule?.spirepdf;
    if (!wasmModule || isGenerating) {
      return;
    }

    setIsGenerating(true);
    setErrorMessage('');

    try {
      const inputFiles = await Promise.all([
        loadPdfToVfs('input_1.pdf'),
        loadPdfToVfs('input_2.pdf'),
        loadPdfToVfs('input_3.pdf'),
      ]);

      const outputFileName = 'MergedPdf.pdf';
      const mergeOp = new wasmModule.MergerOptions();
      wasmModule.PdfMerger.Merge({
        inputFiles,
        outputFile: outputFileName,
        pdfMergeOptions: mergeOp
      });

      const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
      const modifiedFile = new Blob([modifiedFileArray], { type: 'application/pdf' });
      const url = URL.createObjectURL(modifiedFile);
      const a = document.createElement('a');

      a.href = url;
      a.download = outputFileName;
      document.body.appendChild(a);
      a.click();
      document.body.removeChild(a);
      URL.revokeObjectURL(url);
    } catch (error) {
      console.error('Failed to merge PDFs:', error);
      setErrorMessage(error.message || 'Failed to merge PDFs.');
    } finally {
      setIsGenerating(false);
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Merge PDF Documents in React</h1>
      <button onClick={MergePdfs} disabled={!wasmModule || isGenerating}>
        {isGenerating ? 'Generating...' : 'Generate'}
      </button>
      {errorMessage && <p style={{ color: 'crimson' }}>{errorMessage}</p>}
    </div>
  );
}

export default App;
Output:
How the Code Works
The component first loads spire.pdf.js inside useEffect(). Because the module is initialized asynchronously, the Generate button remains disabled until the runtime is ready.
The loadPdfToVfs() function then performs three tasks for each source document:
- It retrieves the PDF from the
publicdirectory withfetch(). - It checks the first four bytes for the
%PDFsignature to help catch missing files or non-PDF responses. - It writes the file bytes to the WebAssembly virtual file system, where Spire.PDF can access them.
After all three files have been loaded, PdfMerger.Merge() combines them in the order specified by inputFiles. The output is read from the virtual file system, converted to a PDF Blob, and downloaded through a temporary object URL.
To change the merge order, simply rearrange the entries in the array. For example, the following order would place input_3.pdf first:
const inputFiles = await Promise.all([
  loadPdfToVfs('input_3.pdf'),
  loadPdfToVfs('input_1.pdf'),
  loadPdfToVfs('input_2.pdf'),
]);
Merge Selected Pages from Different PDF Documents in React
Merging complete documents is not always necessary. You may instead need to create a new PDF from a cover page in one file and a page range in another file. In this situation, load the source files as PdfDocument objects and use InsertPage() and InsertPageRange() to construct the output document.
The following example takes the first page from input_1.pdf, appends every page from input_2.pdf, and saves the selected content as MergedPdf.pdf:
import React, { useState, useEffect } from 'react';

function App() {
  const [wasmModule, setWasmModule] = useState(null);
  const [isGenerating, setIsGenerating] = useState(false);
  const [errorMessage, setErrorMessage] = useState('');

  useEffect(() => {
    (async () => {
      try {
        const publicUrl = process.env.PUBLIC_URL || '';
        const spireModule = await import(/* webpackIgnore: true */ `${publicUrl}/spire.pdf.js`);
        const rawModule = spireModule.default || spireModule;
        window.wasmModule = typeof rawModule === 'function'
          ? await rawModule({ locateFile: p => p.endsWith('.wasm') ? `${publicUrl}/${p}` : p })
          : rawModule;
        setWasmModule(window.wasmModule);
      } catch (error) {
        console.error('Failed to load spire.pdf.js:', error);
      }
    })();
  }, []);

  const loadPdfToVfs = async (fileName) => {
    const publicUrl = process.env.PUBLIC_URL || '';
    const response = await fetch(`${publicUrl}/${fileName}`);

    if (!response.ok) {
      throw new Error(`Failed to load ${fileName}: ${response.status} ${response.statusText}`);
    }

    const fileBytes = new Uint8Array(await response.arrayBuffer());
    const pdfHeader = String.fromCharCode(...fileBytes.slice(0, 4));

    if (pdfHeader !== '%PDF') {
      throw new Error(`${fileName} was loaded, but it is not a valid PDF file.`);
    }

    window.dotnetRuntime.Module.FS.writeFile(fileName, fileBytes, { flags: 'w+' });
    return fileName;
  };

  const MergePdfs = async () => {
    const wasmModule = window.wasmModule?.spirepdf;
    if (!wasmModule || isGenerating) {
      return;
    }

    setIsGenerating(true);
    setErrorMessage('');

    try {
      const [firstInputFile, secondInputFile] = await Promise.all([
        loadPdfToVfs('input_1.pdf'),
        loadPdfToVfs('input_2.pdf'),
      ]);

      const outputFileName = 'MergedPdf.pdf';
      const firstDocument = new wasmModule.PdfDocument();
      const secondDocument = new wasmModule.PdfDocument();
      const mergedDocument = new wasmModule.PdfDocument();

      firstDocument.LoadFromFile({ fileName: firstInputFile });
      secondDocument.LoadFromFile({ fileName: secondInputFile });

      if (firstDocument.Pages.Count < 1) {
        throw new Error('The first PDF does not contain any pages.');
      }

      if (secondDocument.Pages.Count < 1) {
        throw new Error('The second PDF does not contain any pages.');
      }

      mergedDocument.InsertPage({ ldDoc: firstDocument, pageIndex: 0 });
      mergedDocument.InsertPageRange(secondDocument, 0, secondDocument.Pages.Count - 1);
      mergedDocument.SaveToFile({ fileName: outputFileName });

      const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
      const modifiedFile = new Blob([modifiedFileArray], { type: 'application/pdf' });
      const url = URL.createObjectURL(modifiedFile);
      const a = document.createElement('a');

      a.href = url;
      a.download = outputFileName;
      document.body.appendChild(a);
      a.click();
      document.body.removeChild(a);
      URL.revokeObjectURL(url);
    } catch (error) {
      console.error('Failed to merge PDFs:', error);
      setErrorMessage(error.message || 'Failed to merge PDFs.');
    } finally {
      setIsGenerating(false);
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Merge PDF Documents in React</h1>
      <button onClick={MergePdfs} disabled={!wasmModule || isGenerating}>
        {isGenerating ? 'Generating...' : 'Generate'}
      </button>
      {errorMessage && <p style={{ color: 'crimson' }}>{errorMessage}</p>}
    </div>
  );
}

export default App;
Output:
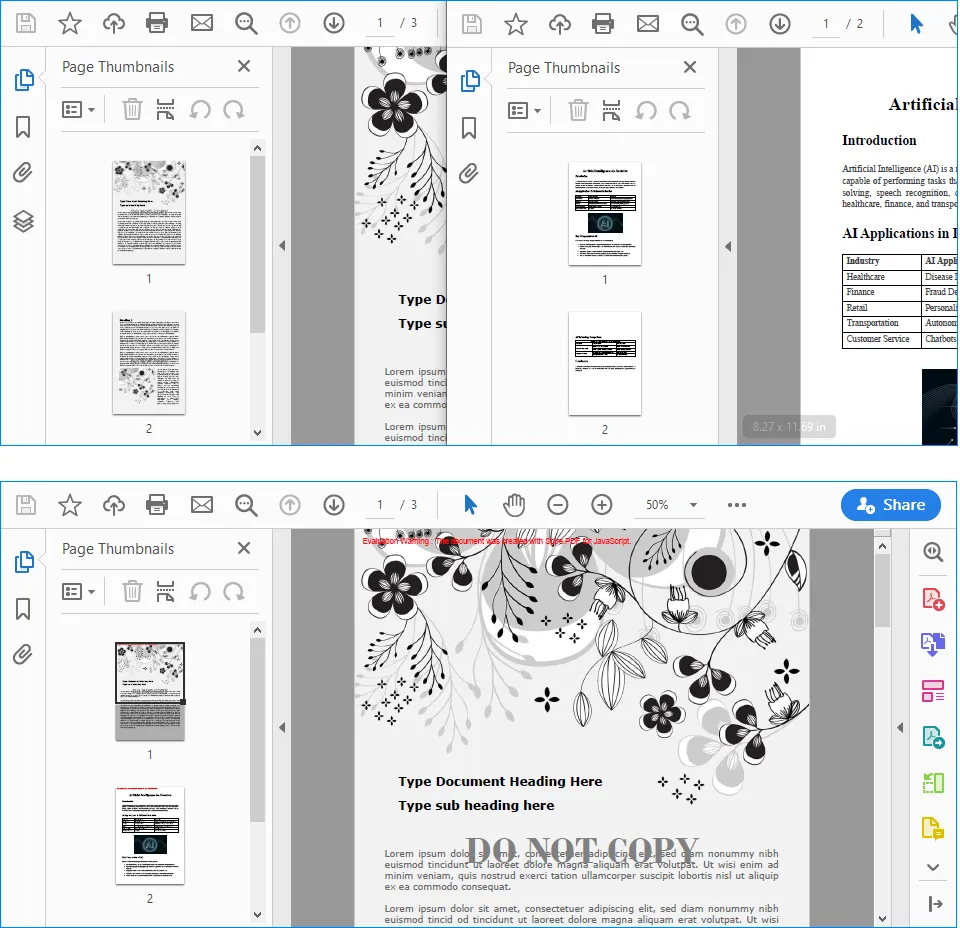
Understanding the Page Selection Logic
The three PdfDocument instances have different roles:
firstDocumentrepresentsinput_1.pdf.secondDocumentrepresentsinput_2.pdf.mergedDocumentis the new PDF that receives the selected pages.
PDF page indexes are zero-based in this example. Therefore, pageIndex: 0 refers to the first page:
mergedDocument.InsertPage({ ldDoc: firstDocument, pageIndex: 0 });
The following statement inserts a continuous range from secondDocument. Its start index is 0, while its end index is secondDocument.Pages.Count - 1, so the complete document is appended:
mergedDocument.InsertPageRange(
  secondDocument,
  0,
  secondDocument.Pages.Count - 1
);
You can change these indexes to merge only the pages required by your application. For instance, this statement inserts pages 2 through 5 from secondDocument because their zero-based indexes are 1 through 4:
mergedDocument.InsertPageRange(secondDocument, 1, 4);
Before using fixed page indexes, make sure the source document contains enough pages. The sample already checks for empty PDFs, but a production application should also validate user-supplied start and end indexes against Pages.Count.
Important Implementation Notes
Keep Runtime and Input Paths Correct
Files stored in the React public directory are requested by URL at runtime. The code uses process.env.PUBLIC_URL so it can construct paths correctly when the application is deployed under a non-root public path. A missing or incorrect file path may return an HTML error page instead of a PDF, which is why the sample verifies the %PDF header before writing the data to the virtual file system.
Wait for WebAssembly Initialization
Spire.PDF cannot process a document until its runtime has finished loading. The wasmModule state controls the button's disabled status, while isGenerating prevents the same operation from being started repeatedly before the current merge has finished.
Validate Page Ranges
When pages are chosen dynamically, check that the start and end indexes are non-negative, that the start index does not exceed the end index, and that both values fall within the source document's page count. This avoids invalid range errors and makes it easier to show a useful message in the React interface.
Release the Download URL
URL.createObjectURL() creates a temporary URL for the generated Blob. Calling URL.revokeObjectURL(url) after the download starts releases that URL and prevents it from remaining in browser memory longer than necessary.
Conclusion
Spire.PDF for JavaScript enables React applications to combine PDF content through a WebAssembly-based workflow. When all pages are required, PdfMerger.Merge() provides a concise way to merge several complete documents in a defined order. When the output must contain only specific content, PdfDocument, InsertPage(), and InsertPageRange() provide page-level control over the result.
With the runtime files configured in the public directory, these techniques can be integrated into document portals, reporting tools, contract workflows, and other React applications that need to assemble PDFs directly in the browser.