Convert PDF to PCL in React with JavaScript
Many printers and print services only speak PCL (Printer Command Language). When the contract or manual at hand is a PDF, the old routes were to install a driver and save the file under a new format from desktop software, or to hand the file to a server that does the conversion — the first cannot be folded into a web workflow, and the second means the document leaves the user's device.
This article shows how to convert a PDF to PCL with Spire.PDF for JavaScript. Built on WebAssembly, it loads and saves PDF documents directly in the browser, so the whole conversion stays local and files are read and written through a virtual file system (VFS) with no backend service required.
For installation and project configuration, refer to Integrating Spire.PDF for JavaScript in a React Project. The following example assumes Spire.PDF is installed and the WebAssembly module has been initialized.
Convert PDF to PCL
To hand a document to a print pipeline that only accepts PCL, use PdfDocument.SaveToFile to write the whole document out as a PCL file — pass FileFormat.PCL as the second argument and the output is HP-PCL XL (PCL6).
function App() {
  const convertPdfToPcl = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // The conversion needs the Arial Unicode MS font, load it into the VFS first
    await window.spire.FetchFileToVFS('ARIAL UNICODE MS.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);

    // Load the PDF file to be converted into the VFS
    const inputFileName = 'Business_Data_Overview.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Define the output file name
    const outputFileName = 'Business_Data_Overview.pcl';

    // Load the PDF document and pass FileFormat.PCL to write out a PCL file
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);
    doc.SaveToFile(outputFileName, pdfModule.FileFormat.PCL);
    doc.Close();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/octet-stream' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF to PCL</h1>
      <button onClick={convertPdfToPcl}>
        Start Converting
      </button>
    </div>
  );
}

export default App;
The generated PCL file, whose header states the PCL-XL language:
FAQ
The output file name ends with .pcl, so why is the file still a PDF
Reason: The single-argument overload SaveToFile(fileName) always writes in PDF format — the extension takes no part in deciding the format, so a file whose name ends with .pcl still comes out as a document whose content is PDF.
Solution: Pass the output format explicitly as the second argument:
// Single argument: writes PDF
doc.SaveToFile(outputFileName);

// FileFormat.PCL: writes a real PCL file
doc.SaveToFile(outputFileName, pdfModule.FileFormat.PCL);
What to do about Cannot found font(Arial) installed on the system.
Reason: Converting to PCL means turning the text on the page into font subsetting instructions a printer can read, and the converter looks for fonts in /Library/Fonts/ in the virtual file system — an empty directory raises this error.
Solution: Send the font into the VFS before loading the PDF:
// Placed before LoadFromFile, the font is already in the VFS when the conversion runs
await window.spire.FetchFileToVFS('ARIAL UNICODE MS.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
What format is the generated PCL file, and how do I open it
Reason: The output is PCL-XL (PCL6), and the file begins with ESC%-12345X@PJL ENTER LANGUAGE = PCLXL, followed by binary HP-PCL XL;2;0 data. It is not text, so opening it in an editor only shows garbage.
Solution: Hand it straight to a printer or print service that supports PCL; there is no need to open it by hand. To confirm the format is right, read the PJL declaration at the start of the file.
Get a Free License
If you wish to remove the evaluation message from the result document or remove feature limitations, please contact sales to obtain a temporary license valid for 30 days.
Convert PDF to Grayscale or Linearized PDF in React with JavaScript
Color documents burn ink when printed, and once filed away that color is of no use; a PDF also stores its objects in the order they were written, so a reader has to download the whole file before it can render the first page — open a manual that runs to tens of megabytes and you stare at a blank screen first. Both jobs used to need desktop software, one file at a time, with no way into a web workflow.
This article uses Spire.PDF for JavaScript to convert PDF documents into grayscale and into linearized PDF files. Grayscaling changes the colors on the page, while linearization only changes how the objects are arranged inside the file, so the two do not affect each other. The library is built on WebAssembly and loads, modifies and saves PDF documents directly in the browser, reading and writing files through a virtual file system (VFS) with no backend service required.
This article covers two core features:
For installation and project configuration, refer to Integrating Spire.PDF for JavaScript in a React Project. The following examples assume Spire.PDF is installed and the WebAssembly module has been initialized.
Convert PDF to Grayscale
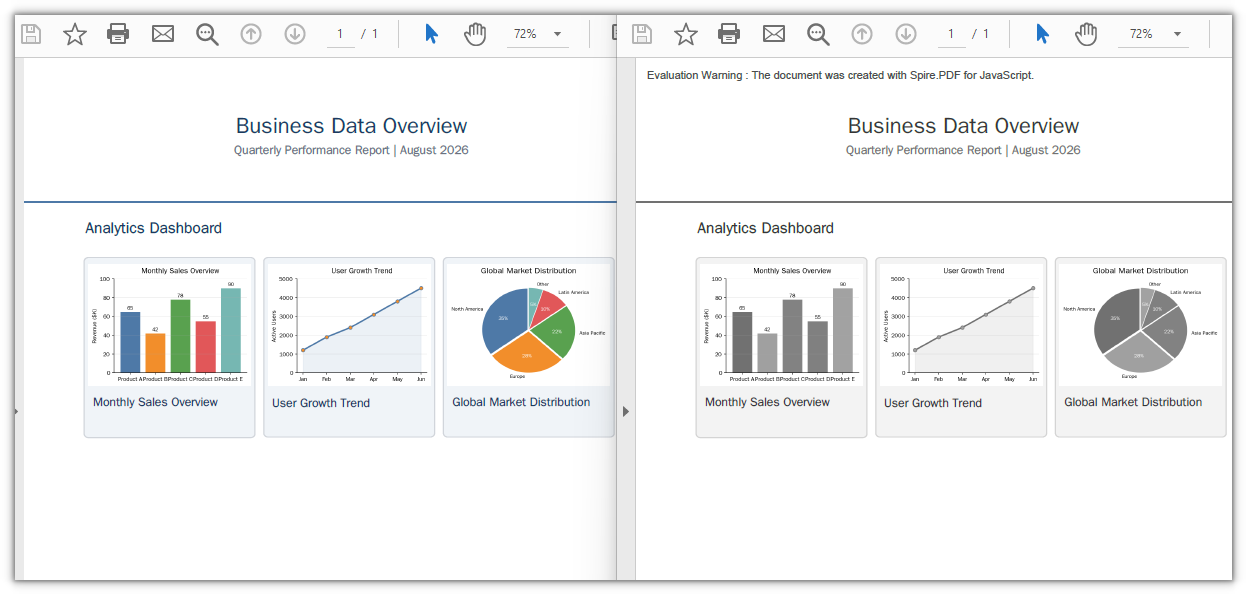
Grayscaling a document before printing or archiving saves color ink. Pass the input file to the PdfGrayConverter constructor and call ToGrayPdf to write out the grayscale document — the color images on the page are re-encoded as grayscale, and the text stays searchable.
function App() {
  const convertToGrayscale = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be converted into the VFS
    const inputFileName = 'Business_Data_Overview.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Define the output file name
    const outputFileName = 'GrayscaleDocument.pdf';

    // Construct the grayscale converter from the input file and write out the grayscale document
    const converter = new pdfModule.PdfGrayConverter({ filePath: inputFileName });
    converter.ToGrayPdf({ filePath: outputFileName });
    converter.Dispose();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF to Grayscale</h1>
      <button onClick={convertToGrayscale}>
        Start Converting
      </button>
    </div>
  );
}

export default App;
The sample document after grayscaling, with the color charts turned to grayscale
Linearize a PDF
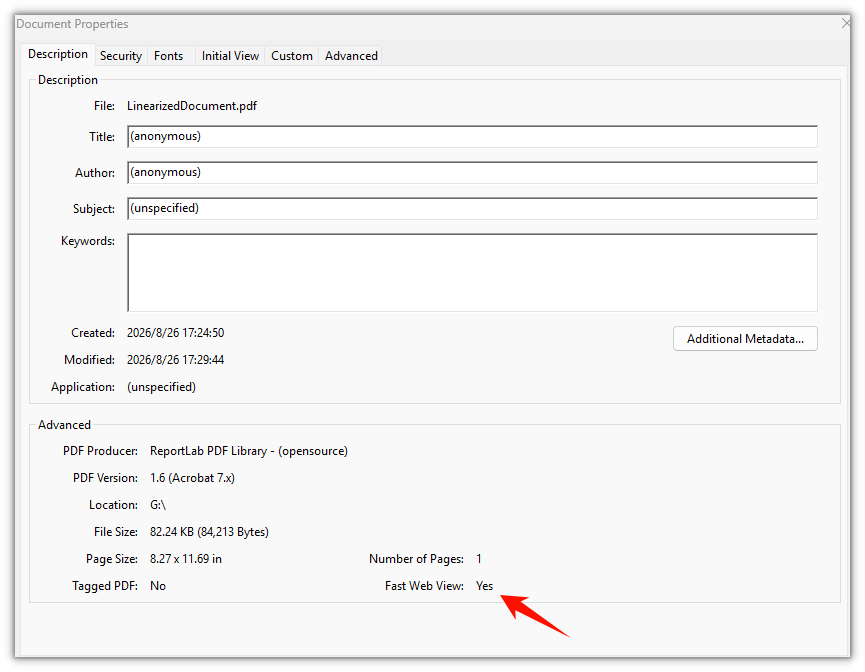
Linearization is what fast web view is built on: a reader does not have to wait for the whole file to arrive before it renders the first page. The usage is the same as in the first feature — pass the input file to the PdfToLinearizedPdfConverter constructor and call ToLinearizedPdf to write out the result, and the document keeps its appearance and content unchanged.
function App() {
  const convertToLinearized = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check whether the module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file to be converted into the VFS
    const inputFileName = 'Business_Data_Overview.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Define the output file name
    const outputFileName = 'LinearizedDocument.pdf';

    // Construct the linearization converter from the input file and write out the linearized document
    const converter = new pdfModule.PdfToLinearizedPdfConverter({ filePath: inputFileName });
    converter.ToLinearizedPdf({ filePath: outputFileName });
    converter.Dispose();

    // Read the generated file from the VFS and trigger the download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Linearize a PDF</h1>
      <button onClick={convertToLinearized}>
        Start Converting
      </button>
    </div>
  );
}

export default App;
The linearized document looks no different on the page, the change is inside the file structure
FAQ
Why does the converted document contain an extra Evaluation Warning line
Reason: An unlicensed Spire.PDF inserts a line Evaluation Warning : The document was created with Spire.PDF for JavaScript. into the output document. It is appended per call — convert the same file twice and the warning appears twice.
Solution: Request a temporary 30-day license and the output document no longer carries the warning. See "Get a Free License" at the end of this article.
Why is the grayscale file smaller
Reason: Grayscaling works by re-encoding color images as single-channel DeviceGray images, and the space they take drops along with the channel count. The color images in the sample document were 3-channel PNGs totaling about 66 KB, and come out at about 31 KB; the whole file went from 82 KB down to 44 KB.
Solution: This is the normal result of image re-encoding and needs no extra handling. The page count and the text content are unchanged, the text is still searchable and copyable, and only the colors are rewritten.
Get a Free License
If you wish to remove the evaluation message from the result document or remove feature limitations, please contact sales to obtain a temporary license valid for 30 days.
Convert PDF to Images and Vice Versa with JavaScript in React
Images are one of the most intuitive forms of content presentation and distribution, while PDF documents preserve the original layout and are widely used for the storage and transmission of formal files. When displaying PDF content on web pages, mini programs, social platforms, or emails, distributing PDF files directly is often inconvenient — converting them to image formats such as PNG or JPEG first enables quick preview and sharing. Conversely, consolidating scanned documents or image assets into PDF makes batch archiving and cross-platform distribution easier. Real-world business often requires flexible switching between the two forms: converting PDF contracts to images for online preview and quick sharing, or converting scanned image assets to PDF for unified archiving and circulation.
Spire.PDF for JavaScript performs bidirectional conversion between PDF and images entirely in the browser via WebAssembly, managing input and output files through a virtual file system (VFS) with no backend server required.
This article covers two core features:
For installation and project setup, refer to Integrating Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Convert PDF to Image
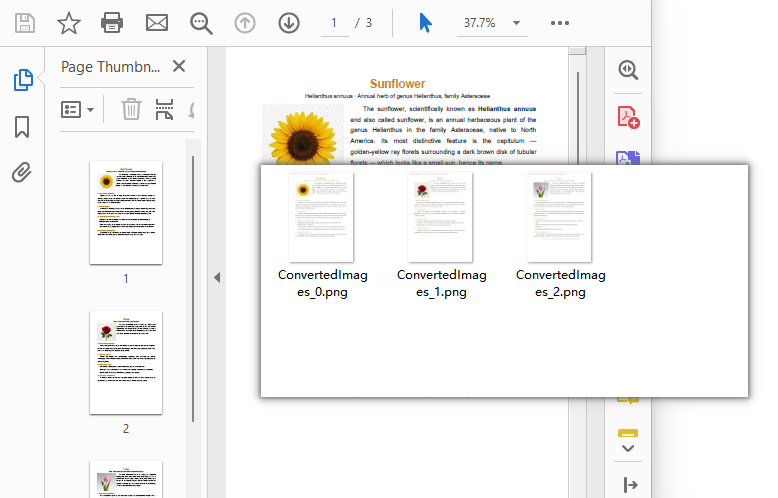
The core of PDF-to-image conversion is to render the content, fonts, and graphics elements of every page in a PDF document into independent bitmap data. Spire.PDF for JavaScript generates an image stream for each page through the PdfDocument object's SaveAsImage method, loops through all Pages.Count pages and saves each page as a PNG image with stream.Save, then bundles the images into a ZIP file with JSZip for a one-click download, without needing to handle pixel and page coordinate mapping manually.
import JSZip from "jszip";

function App() {
  const convertToImage = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file and fonts into VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'Flowers.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Create an output directory to hold the converted images
    let outputDirectoryName = "ImagesFolders/";
    window.dotnetRuntime.Module.FS.mkdirTree(outputDirectoryName);

    // Loop through each page and save it as an image
    for (let i = 0; i < doc.Pages.Count; i++) {
      const outputFileName = outputDirectoryName + "ConvertedImages_" + i + ".png";
      let stream = doc.SaveAsImage({ pageIndex: i });
      stream.Save(outputFileName);
      stream.Dispose();
    }

    doc.Dispose();

    // Read the converted files from VFS and trigger download
    const zip = new JSZip();
    let items = await window.dotnetRuntime.Module.FS.readdir(outputDirectoryName);
    items = items.filter((item) => item !== "."

      && item !== "..");
    for (const item of items) {
      const itemPath = `${outputDirectoryName}/${item}`;
      const fileData = await window.dotnetRuntime.Module.FS.readFile(itemPath);
      zip.file(item, fileData);
    }

    // Convert the ZIP to a Blob and trigger the browser download
    const zipBlob = await zip.generateAsync({ type: "blob" });
    const url = URL.createObjectURL(zipBlob);
    const a = document.createElement('a');
    a.href = url;
    a.download = 'ImagesFolders';
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF To Image</h1>
      <button onClick={convertToImage}>
        Generate
      </button>
    </div>
  );
}

export default App;
Each page of the PDF exported as a PNG image via SaveAsImage and bundled into a ZIP file for download
Adjust the DPI Resolution of Exported Images
When exporting images with the
SaveAsImagemethod, the default resolution is 96 DPI, which is suitable for screen preview, but text and lines may appear jagged or blurry when zoomed in. For sharper images, specify the resolution via thedpiXanddpiYparameters ofSaveAsImage, for example set it to 150 DPI:
// Export each page as an image at 150 DPI
for (let i = 0; i < doc.Pages.Count; i++) {
  let stream = doc.SaveAsImage({ pageIndex: i, dpiX: 150, dpiY: 150 });
  stream.Save(outputDirectoryName + "highres_" + i + ".png");
  stream.Dispose();
}
The higher the DPI value, the sharper the exported image, but the larger the file size. Choose a balance between clarity and file size based on your actual use case.
Convert Image to PDF
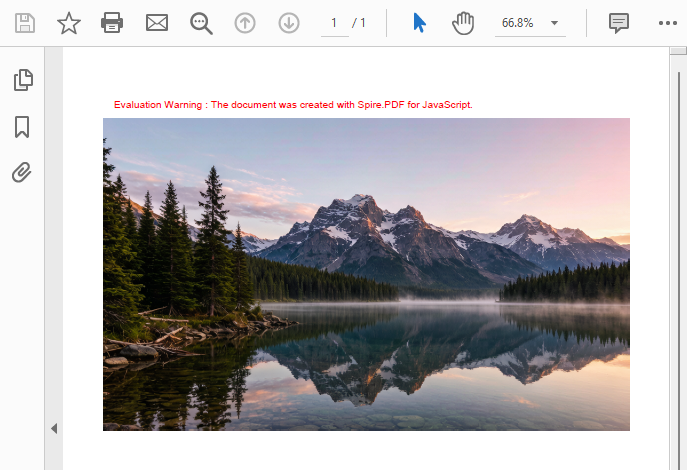
Image-to-PDF conversion is commonly used to consolidate scanned documents or design assets into PDF for archiving. Spire.PDF for JavaScript creates a new document with the PdfDocument object, loads the image with the PdfImage.FromFile method, adds a page via Pages.Add, draws the image onto the page at its original size with the Canvas.DrawImage method, and finally saves it as a standard PDF with the SaveToFile method using the FileFormat.PDF enum value.
function App() {
  const convertImageToPDF = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the image file into VFS
    const inputFileName = 'Scenery.png';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object
    let doc = new pdfModule.PdfDocument();

    // Add a page
    let page = doc.Pages.Add();

    // Load the image
    let image = pdfModule.PdfImage.FromFile(inputFileName);

    // Calculate the scale ratio so the image fits the page completely
    let widthFitRate = image.PhysicalDimension.Width / page.Canvas.ClientSize.Width;
    let heightFitRate = image.PhysicalDimension.Height / page.Canvas.ClientSize.Height;
    let fitRate = Math.max(widthFitRate, heightFitRate);

    // Calculate the scaled dimensions of the image
    let fitWidth = image.PhysicalDimension.Width / fitRate;
    let fitHeight = image.PhysicalDimension.Height / fitRate;

    // Draw the image onto the page
    page.Canvas.DrawImage({ image: image, x: 0, y: 30, width: fitWidth, height: fitHeight });

    const outputFileName = 'ImageToPDF.pdf';

    // Save as PDF format
    doc.SaveToFile({ fileName: outputFileName, fileFormat: pdfModule.FileFormat.PDF });
    doc.Close();

    // Read the converted file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert Image To PDF</h1>
      <button onClick={convertImageToPDF}>
        Generate
      </button>
    </div>
  );
}

export default App;
PDF document generated after loading an image via PdfImage.FromFile and drawing it with Canvas.DrawImage
Load Images from a Memory Stream
Besides loading directly from a file with
PdfImage.FromFile, images can also be loaded from a memory stream via thePdfImage.FromStreammethod. This approach suits scenarios where the image data comes from an API response or a database field, or where bytes need to be read before processing. See the code below:
// Read image bytes from VFS and build a memory stream
let bytes = window.dotnetRuntime.Module.FS.readFile(inputFileName);
let stream = new pdfModule.Stream(bytes);

// Load the image from the memory stream
let image = pdfModule.PdfImage.FromStream(stream);
The image can then be drawn onto a PDF page with the page.Canvas.DrawImage method and saved as a standard PDF using SaveToFile.
FAQ
Garbled text in the converted image
Reason: PDF relies on font embedding to ensure consistent cross-platform rendering. If the input PDF uses non-embedded fonts and the corresponding font files are not loaded in the VFS, text may appear garbled after conversion.
Solution: Make sure the required TrueType font files (e.g., ARIALUNI.TTF) are loaded into the /Library/Fonts/ directory in VFS before calling the conversion. ARIALUNI.TTF covers common CJK characters and is the recommended font for ensuring conversion quality.
Which image formats are supported for conversion?
Reason: Different business scenarios require different bitmap formats. For example, PNG is commonly used for web preview and JPEG for photos.
Solution: Spire.PDF for JavaScript can render PDF pages to common bitmap formats such as PNG, JPEG, and BMP. After generating the image stream with SaveAsImage, simply replace the file extension of the output file name with the target format (e.g., .jpg, .bmp, .png) in stream.Save to output the corresponding image format.
Get a Free License
If you want to remove the evaluation messages in the resulting documents or get rid of functional limitations, contact sales to obtain a 30-day temporary license.
Convert PDF to XPS and Vice Versa with JavaScript in React
XPS (XML Paper Specification) is a fixed-layout document format introduced by Microsoft, widely used in electronic document printing, archiving, and distribution scenarios, with native support in the Windows platform ecosystem. XPS describes document structure based on XML, offering advantages such as clear structure, easy validation, and digital signing. Meanwhile, PDF remains indispensable as an internationally recognized document format for cross-platform distribution. Real-world business often requires flexible switching between the two formats: converting existing PDF contracts to XPS for printing and archiving in Windows environments, or converting XPS documents to PDF for cross-platform distribution and collaboration.
Spire.PDF for JavaScript performs bidirectional conversion between PDF and XPS entirely in the browser via WebAssembly, managing input and output files through a virtual file system (VFS) with no backend server required.
This article covers two core features:
For installation and project setup, refer to Integrating Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Convert PDF to XPS
The core of PDF-to-XPS conversion is to re-encode the page content, fonts, and graphics elements from a PDF document into an XML description structure compliant with the XPS standard. Spire.PDF for JavaScript accomplishes this in one step through the PdfDocument object's SaveToFile method with the FileFormat.XPS enum value, eliminating the need to handle underlying format differences manually.
function App() {
  const convertToXPS = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load fonts and PDF file into VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'Reading_EN.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Define the output file name for XPS format
    const outputFileName = 'OutputXPS.xps';

    // Save as XPS format
    doc.SaveToFile({ fileName: outputFileName, fileFormat: pdfModule.FileFormat.XPS });
    doc.Close();

    // Read the converted file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/vnd.ms-xpsdocument' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF To XPS</h1>
      <button onClick={convertToXPS}>
        Generate
      </button>
    </div>
  );
}

export default App;
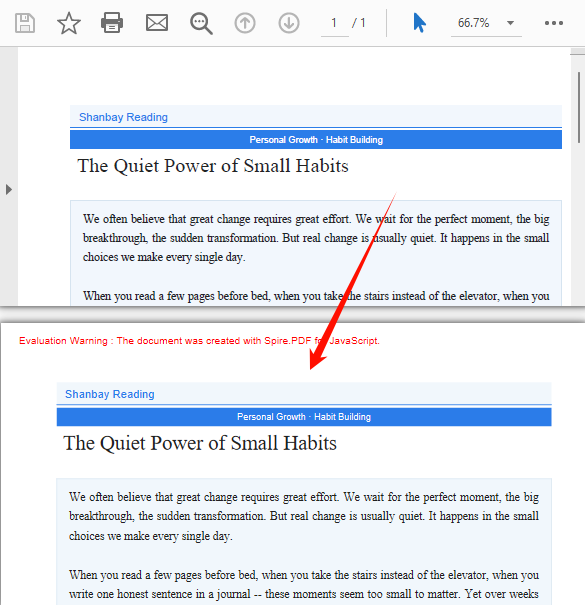
XPS output generated after conversion via SaveToFile with FileFormat.XPS
Convert XPS to PDF
XPS-to-PDF conversion is a common requirement in document cross-platform distribution scenarios. Spire.PDF for JavaScript loads XPS fixed-layout documents through the PdfDocument object's LoadFromXPS method and then exports them as standard PDF files via the SaveToFile method with the FileFormat.PDF enum value, preserving the original document's layout and visual appearance.
function App() {
  const convertXPSToPDF = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the XPS file into VFS
    const inputFileName = 'Lease_Agreement_EN.xps';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create PdfDocument object and load the XPS document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromXPS(inputFileName);

    // Define the output file name for PDF format
    const outputFileName = 'OutputPDF.pdf';

    // Save as PDF format
    doc.SaveToFile({ fileName: outputFileName, fileFormat: pdfModule.FileFormat.PDF });
    doc.Close();

    // Read the converted file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert XPS To PDF</h1>
      <button onClick={convertXPSToPDF}>
        Generate
      </button>
    </div>
  );
}

export default App;
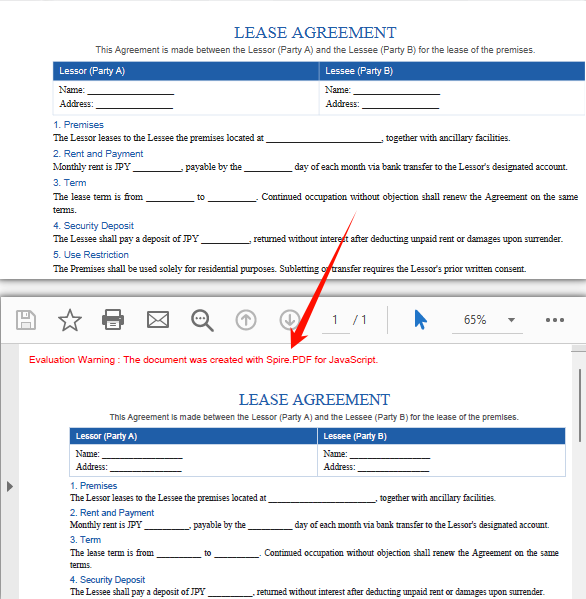
PDF document generated after loading XPS via the PdfDocument LoadFromXPS method and converting
FAQ
Can encrypted PDFs be converted to XPS?
Password-protected encrypted PDFs cannot be saved as XPS directly via SaveToFile — the document must be decrypted first.
Solution: Provide the password when loading the PDF via the second parameter of LoadFromFile, then save as XPS:
// Load a password-protected PDF document
let doc = new pdfModule.PdfDocument();
doc.LoadFromFile(inputFileName, "password");

// Save as XPS format
doc.SaveToFile({ fileName: outputFileName, fileFormat: pdfModule.FileFormat.XPS });
doc.Close();
Get a Free License
If you want to remove the evaluation messages in the resulting documents or get rid of functional limitations, contact sales to obtain a 30-day temporary license.
Convert PDF to OFD and Vice Versa with JavaScript in React
OFD (Open Fixed-layout Document) is a national standard fixed-layout document format widely used in e-invoices, e-certificates, administrative approvals, and other government and financial scenarios. OFD describes document structure based on XML, offering advantages such as independent control and information security. Meanwhile, PDF remains indispensable as an internationally recognized document format for cross-platform distribution. Real-world business often requires flexible switching between the two formats: receiving OFD-format e-invoices and converting them to PDF for printing and distribution, or converting existing PDF contracts to OFD to meet government platform upload requirements.
Spire.PDF for JavaScript performs bidirectional conversion between PDF and OFD entirely in the browser via WebAssembly, managing input and output files through a virtual file system (VFS) with no backend server required.
This article covers two core features:
For installation and project setup, refer to Integrating Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Convert PDF to OFD
The core of PDF-to-OFD conversion is to re-encode the page content, fonts, and graphics elements from a PDF document into an XML description structure compliant with the OFD standard. Spire.PDF for JavaScript accomplishes this in one step through the PdfDocument object's SaveToFile method with the FileFormat.OFD enum value, eliminating the need to handle underlying format differences manually.
function App() {
  const convertToOFD = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load fonts and PDF file into VFS
    await window.spire.FetchFileToVFS('ARIAL.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'TemplateIntroduction-en.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Define the output file name for OFD format
    const outputFileName = 'OutputOFD.ofd';

    // Save as OFD format
    doc.SaveToFile({ fileName: outputFileName, fileFormat: pdfModule.FileFormat.OFD });
    doc.Close();

    // Read the converted file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/ofd' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF To OFD</h1>
      <button onClick={convertToOFD}>
        Generate
      </button>
    </div>
  );
}

export default App;
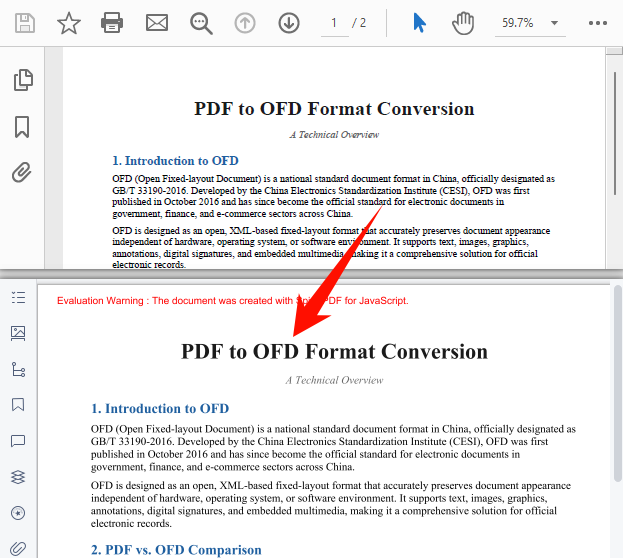
OFD output generated after conversion via SaveToFile with FileFormat.OFD
Convert OFD to PDF
OFD-to-PDF conversion is a common requirement in government electronic document distribution scenarios. Spire.PDF for JavaScript provides the OfdConverter component, which is specifically designed to parse OFD fixed-layout documents and export them as standard PDF files while preserving the original document's layout and visual appearance.
function App() {
  const convertOFDToPDF = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load fonts and OFD file into VFS
    await window.spire.FetchFileToVFS('Arial.TTF', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'Invoice_EN.ofd';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create OfdConverter object and pass the OFD file path
    let converter = new pdfModule.OfdConverter(inputFileName);

    // Define the output file name for PDF format
    const outputFileName = 'OutputPDF.pdf';

    // Convert to PDF format
    converter.ToPdf(outputFileName);
    converter.Dispose();

    // Read the converted file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert OFD To PDF</h1>
      <button onClick={convertOFDToPDF}>
        Generate
      </button>
    </div>
  );
}

export default App;
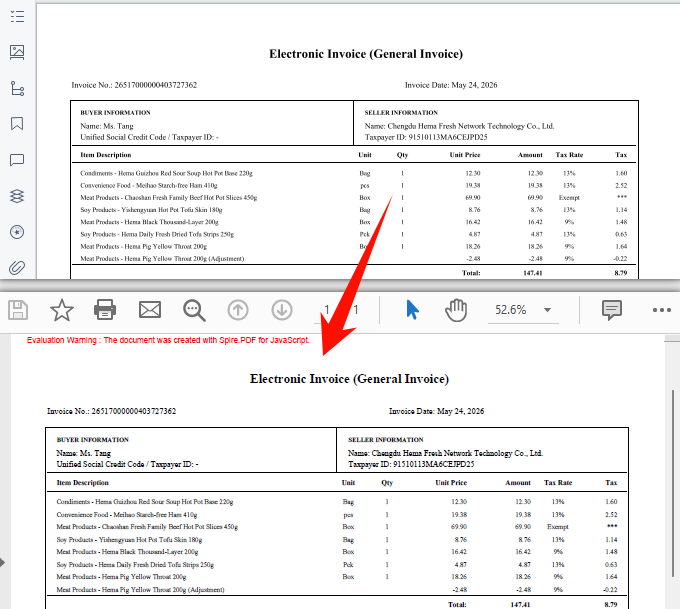
Standard PDF output generated after conversion via OfdConverter
FAQ
Can encrypted PDFs be converted to OFD?
Password-protected encrypted PDFs cannot be saved as OFD directly via SaveToFile — the document must be decrypted first.
Solution: Provide the password when loading the PDF via the second parameter of LoadFromFile, then save as OFD:
// Load a password-protected PDF document
let doc = new pdfModule.PdfDocument();
doc.LoadFromFile(inputFileName, "password");

// Save as OFD format
doc.SaveToFile({ fileName: outputFileName, fileFormat: pdfModule.FileFormat.OFD });
doc.Close();
Garbled text in the converted OFD document
OFD relies on font embedding to ensure consistent cross-platform rendering. If the input PDF uses non-embedded fonts and the corresponding font files are not loaded in the VFS, text may appear garbled after conversion.
Solution: Make sure the required TrueType font files (e.g., ARIALUNI.TTF) are loaded into the /Library/Fonts/ directory in VFS before calling the conversion. ARIALUNI.TTF covers common CJK characters and is the recommended font for ensuring conversion quality.
Get a Free License
Spire.PDF for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Convert PDF to PDF/A and Vice Versa with JavaScript in React
PDF/A is an ISO-standardized long-term archival format that embeds fonts, color profiles, and metadata into a unified compliance level, ensuring documents remain faithfully reproducible for decades regardless of the PDF reader used. In contrast, standard PDF offers greater flexibility for everyday editing and content extraction. Real-world business often requires switching between these two formats: converting contracts to PDF/A for regulatory compliance during archiving, and restoring them to standard PDF for text extraction during audit review.
Spire.PDF for JavaScript performs bidirectional PDF/PDF/A conversion entirely in the browser via WebAssembly, managing input and output files through a virtual file system (VFS) with no backend server required.
This article covers two core features:
For installation and project setup, refer to Integrating Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Convert PDF to PDF/A
The core of PDF/A archival conversion is to consolidate fonts, color profiles, and metadata in a standard PDF into ISO-compliant levels. Spire.PDF handles this in one step through the PdfStandardsConverter component, supporting multiple compliance levels including PDF/A-1a, PDF/A-1b, PDF/A-2a, PDF/A-2b, PDF/A-3a, and PDF/A-3b.
The conversion standards supported by PdfStandardsConverter and their use cases are as follows:
| Method | Standard | Description |
|---|---|---|
ToPdfA1B |
PDF/A-1b | Based on PDF 1.4, guarantees visual appearance reproducibility only — the most commonly used archival level |
ToPdfA1A |
PDF/A-1a | Requires document tags and structure information on top of 1b, supports accessible reading |
ToPdfA2A |
PDF/A-2a | Based on PDF 1.7, requires tags and structure info, supports layers and transparency |
ToPdfA2B |
PDF/A-2b | PDF/A-2 basic conformance level, allows transparency, layers, and embedded OLE objects |
ToPdfA3A |
PDF/A-3a | Allows embedding XML, Excel, and other arbitrary format files as attachments on top of 2a |
ToPdfA3B |
PDF/A-3b | PDF/A-3 basic conformance level, supports embedding arbitrary format attachments |
ToPdfX1A2001 |
PDF/X-1a:2001 | Print exchange standard, suitable for publishing and printing workflows |
The following example demonstrates converting a PDF to PDF/A-2B using ToPdfA2B:
function App() {
  const convertToPDFA = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load fonts and PDF file into VFS
    await window.spire.FetchFileToVFS('arial.ttf', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'MovieCatalog.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create PdfStandardsConverter
    let converter = new pdfModule.PdfStandardsConverter({ filePath: inputFileName });

    // Convert to PDF/A-2B format
    const outputFileName = 'ToPDFA_result.pdf';
    converter.ToPdfA2B({ filePath: outputFileName });

    // // Convert to PDF/A-1a
    // converter.ToPdfA1A({ filePath: outputFileName });

    // // Convert to PDF/A-2a
    // converter.ToPdfA2A({ filePath: outputFileName });

    // // Convert to PDF/A-2b
    // converter.ToPdfA2B({ filePath: outputFileName });

    // // Convert to PDF/A-3a
    // converter.ToPdfA3A({ filePath: outputFileName });

    // // Convert to PDF/A-3b
    // converter.ToPdfA3B({ filePath: outputFileName });

    // // Convert to PDF/X-1a:2001
    // converter.ToPdfX1A2001({ filePath: outputFileName });

    // Read the converted file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);

    // Release resources
    converter.Dispose();
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF To PDF/A</h1>
      <button onClick={convertToPDFA}>
        Generate
      </button>
    </div>
  );
}

export default App;
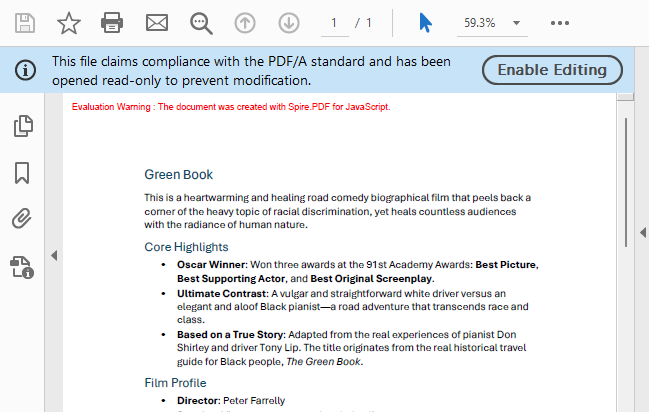
PDF/A output generated after conversion via PdfStandardsConverter
Convert PDF/A to PDF
PDF/A is the standard format for long-term archiving, but in everyday editing and content extraction scenarios, you may need to restore PDF/A back to standard PDF. Spire.PDF for JavaScript achieves this reverse conversion by loading the PDF/A document and copying content page by page into a new document, ensuring the output standard PDF is free of PDF/A compliance constraints.
function App() {
  const convertToNormalPDF = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load fonts and PDF file into VFS
    await window.spire.FetchFileToVFS('arial.ttf', '/Library/Fonts/', `${process.env.PUBLIC_URL}/font/`);
    const inputFileName = 'PDFA_Sample.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create PdfDocument object
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Create a new PDF document to draw content onto
    let newDoc = new pdfModule.PdfNewDocument();
    newDoc.CompressionLevel = pdfModule.PdfCompressionLevel.None;

    // Iterate through each page in the original document
    for (let i = 0; i < doc.Pages.Count; i++) {
      let page = doc.Pages.get_Item(i);
      // Get the current page size
      let size = page.Size;

      // Add a new page with the same size and no margins
      let newPage = newDoc.Pages.Add({ size: size, margins: new pdfModule.PdfMargins() });

      // Draw the original page content onto the new page
      let template = page.CreateTemplate();
      let layoutWidget = new pdfModule.PdfLayoutWidget(template.H);
      layoutWidget.Draw({ page: newPage, x: 0, y: 0 });
      // page.CreateTemplate().Draw({page: newPage, x: 0, y: 0});
    }

    // Define the output file name
    const outputFileName = "PDFAToPdf_result.pdf";

    // Save the document to the specified path
    newDoc.Save(outputFileName);

    // Read the generated file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);

    // Release resources
    newDoc.Dispose();
    doc.Dispose();
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF/A To Normal PDF</h1>
      <button onClick={convertToNormalPDF}>
        Generate
      </button>
    </div>
  );
}

export default App;
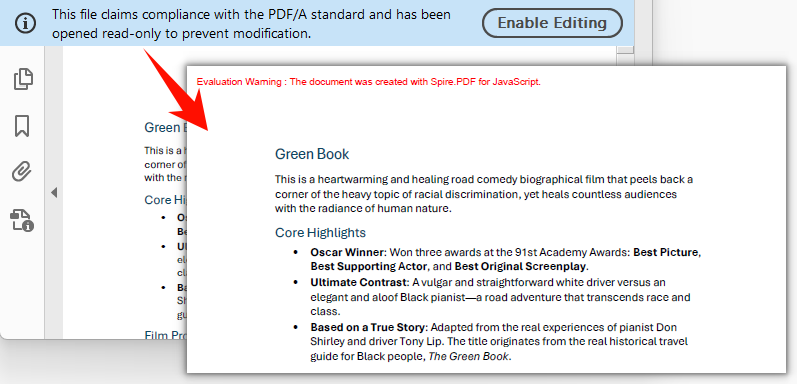
Standard PDF output generated by creating a new document and copying pages
FAQ
Converted PDF/A file size is much larger than the original
PDF/A requires all fonts used in the document to be fully embedded to ensure correct rendering on any device. If the original document uses non-embedded system fonts, the font data will be written completely into the output file during conversion, resulting in a larger file size. This is an inherent requirement of PDF/A compliance. To minimize file size, consider using font subsetting (embedding only the characters actually used) or compressing image content before generating the source PDF.
Can encrypted PDFs be converted to PDF/A?
Encrypted PDFs that require a password to open cannot be processed directly by PdfStandardsConverter. The password must be provided when loading the document.
The PdfStandardsConverter constructor supports a password parameter for converting password-protected PDFs to PDF/A:
// Create PdfStandardsConverter with password
let converter = new pdfModule.PdfStandardsConverter({ filePath: inputFileName, password: "123456" });
converter.ToPdfA2A({ filePath: outputFileName });
converter.Dispose();
"File not found" or "Invalid PDF format" error when loading PDF/A
PDF/A documents must first be converted via PdfStandardsConverter, or properly loaded into the virtual file system (VFS) via FetchFileToVFS. Common mistakes include passing the wrong file name or path, or executing subsequent operations before the file has finished loading. Verify that the file has been loaded into VFS via FetchFileToVFS and that the file name (including extension) matches exactly. Use await to ensure the file is ready before proceeding.
Get a Free License
Spire.PDF for JavaScript offers a 30-day full-featured free trial license with no functional limitations. Apply here to evaluate before purchasing.
Add, Replace, Delete, or Extract Images in PDF with JavaScript in React
Product images, screenshots, charts, and stamps in a PDF often need to be updated or reused: inserting new images into a PDF, replacing an old Logo with a new Logo, deleting outdated illustrations, or extracting images from a PDF for use in other documents. Because the PDF layout is fixed, directly modifying these images with an editor is often very difficult.
Spire.PDF for JavaScript processes PDF documents directly in the browser via WebAssembly, managing input and output files through a virtual file system (VFS) with no backend server required. With PdfImage, the DrawImage method of the page canvas, and the PdfImageHelper helper class, you can easily add, replace, delete, and extract images in PDFs.
This article covers four core features:
For installation and project setup, refer to Integrating Spire.PDF for JavaScript in a React Project. The examples below assume Spire.PDF is installed and the WebAssembly module is initialized.
Add Images to a PDF
Adding images is one of the most common image operations. The core idea is: first load the image file with the PdfImage.FromFile method, then use the DrawImage method of the page canvas to draw the image at a specified position and size on the page. The x and y parameters determine the coordinates of the top-left corner of the image, and the width and height parameters determine the display size of the image. You can add an image to a specified page of an existing document, or draw the image in a new blank document as in the example below.
function App() {
  const addImageToPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the image into VFS
    const inputImageName = 'TreePic.png';
    await window.spire.FetchFileToVFS(inputImageName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object
    let doc = new pdfModule.PdfDocument();

    // Add a page
    let page = doc.Pages.Add();

    // Load the image and scale its display size proportionally
    let image = pdfModule.PdfImage.FromFile(inputImageName);
    let width = image.Width * 0.6;
    let height = image.Height * 0.6;

    // Calculate the horizontal center position and set the vertical position
    let x = (page.Canvas.ClientSize.Width - width) / 2;
    let y = 60;

    // Draw the image at the specified position on the page
    page.Canvas.DrawImage({ image: image, x: x, y: y, width: width, height: height });

    // Define the output file name in PDF format
    const outputFileName = 'AddImage.pdf';

    // Save as PDF format
    doc.SaveToFile({ fileName: outputFileName });
    doc.Close();

    // Read the generated PDF file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Add Image To PDF</h1>
      <button onClick={addImageToPdf}>
        Generate
      </button>
    </div>
  );
}

export default App;
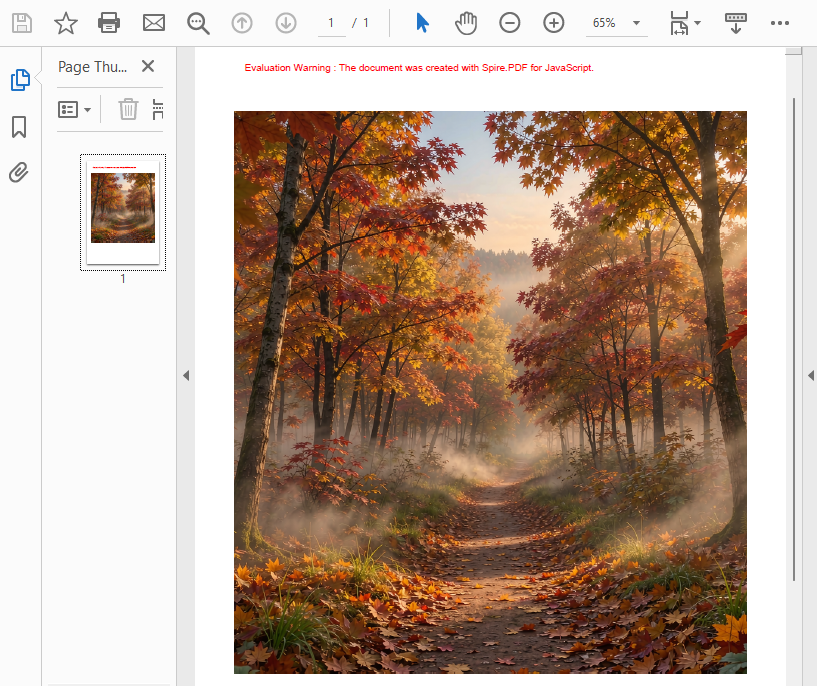
PDF document generated after adding an image
Replace Images in a PDF
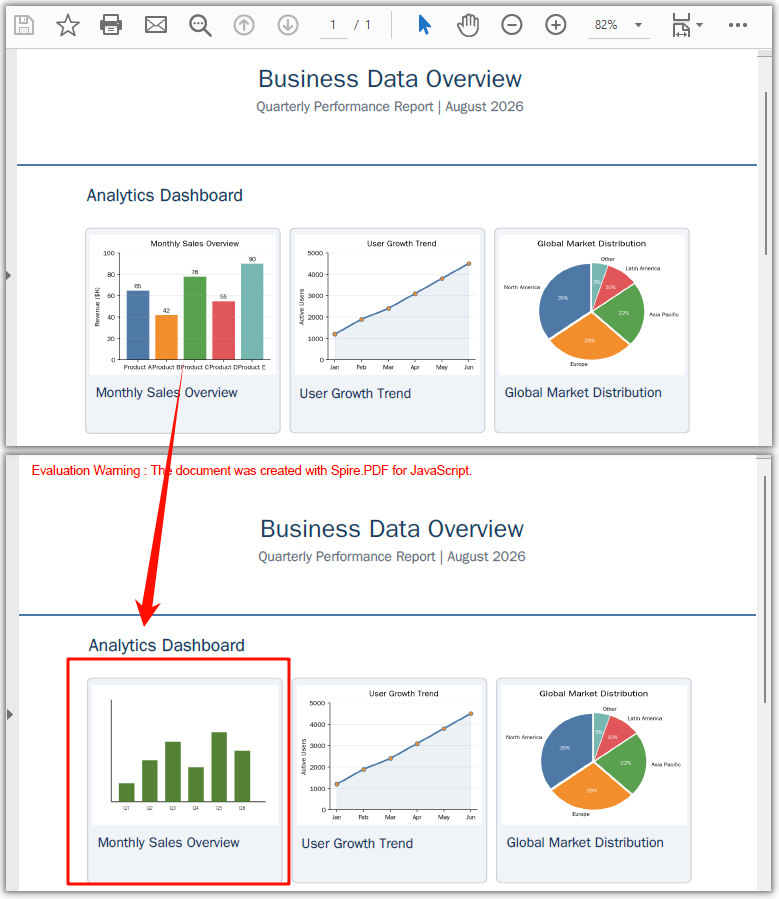
Replacing an image means replacing the content of an image on the page with a new image while keeping the original position and placeholder size unchanged. First, use the GetImagesInfo method of PdfImageHelper to get the array of image information on the page, then load the new image, and call the ReplaceImage method to replace the image at the specified index with the new image. After replacement, the new image automatically inherits the original image's position and size on the page, so the overall layout remains unchanged.
function App() {
  const replaceImageInPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file into VFS
    const inputFileName = 'Business_Data_Overview.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Load the new image used for replacement into VFS
    const newImageName = 'ChartImage.png';
    await window.spire.FetchFileToVFS(newImageName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Get the first page
    let page = doc.Pages.get_Item(0);

    // Create a PdfImageHelper object and get the image information on the page
    let helper = new pdfModule.PdfImageHelper();
    let images = helper.GetImagesInfo(page);

    // Load the new image and replace the first image on the page
    let newImage = pdfModule.PdfImage.FromFile(newImageName);
    helper.ReplaceImage(images[0], newImage);

    // Define the output file name in PDF format
    const outputFileName = 'ReplaceImage.pdf';

    // Save as PDF format
    doc.SaveToFile({ fileName: outputFileName });
    doc.Close();

    // Read the generated PDF file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Replace Image In PDF</h1>
      <button onClick={replaceImageInPdf}>
        Generate
      </button>
    </div>
  );
}

export default App;
PDF document generated after replacing an image
Delete Images from a PDF
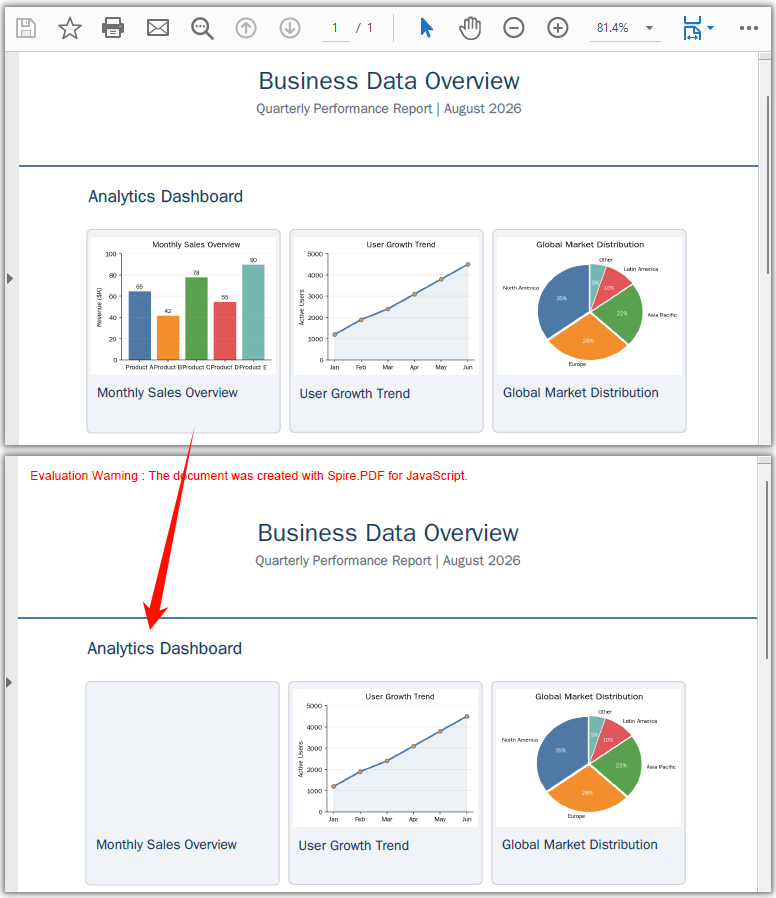
Deleting an image removes an image object that is no longer needed from the page. Similar to replacement, first use the GetImagesInfo method of PdfImageHelper to get the array of image information on the page, then call the DeleteImage method and pass in the corresponding image information object to delete the image. After deletion, the original position is left blank, and the text, graphics, and overall layout on the page are unaffected.
function App() {
  const deleteImageFromPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file into VFS
    const inputFileName = 'Business_Data_Overview.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Get the first page
    let page = doc.Pages.get_Item(0);

    // Create a PdfImageHelper object and get the image information on the page
    let helper = new pdfModule.PdfImageHelper();
    let images = helper.GetImagesInfo(page);

    // Delete the first image on the page
    helper.DeleteImage({ imageInfo: images[0] });

    // Define the output file name in PDF format
    const outputFileName = 'DeleteImage.pdf';

    // Save as PDF format
    doc.SaveToFile({ fileName: outputFileName });
    doc.Close();

    // Read the generated PDF file from VFS and trigger download
    const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
    const blob = new Blob([fileArray], { type: 'application/pdf' });
    const url = URL.createObjectURL(blob);
    const a = document.createElement('a');
    a.href = url;
    a.download = outputFileName;
    a.click();
    URL.revokeObjectURL(url);
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Delete Image From PDF</h1>
      <button onClick={deleteImageFromPdf}>
        Generate
      </button>
    </div>
  );
}

export default App;
PDF document generated after deleting an image
Extract Images from a PDF
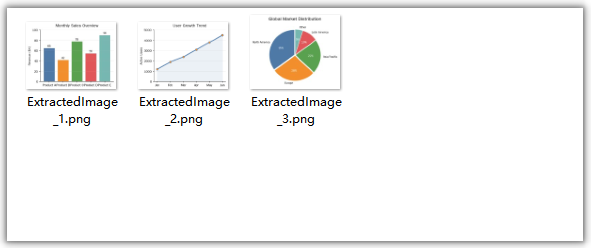
Extracting images exports existing images from PDF pages as separate image files, making them easy to reuse in other documents or systems. After getting the array of image information with the GetImagesInfo method of PdfImageHelper, access the Image property of each image information object one by one, call its Save method to save the image to VFS, then read the file from VFS and trigger download. Extraction is a read-only operation and does not modify the original PDF document.
function App() {
  const extractImagesFromPdf = async () => {
    // Get the Spire.PDF WASM module
    const pdfModule = window.wasmModule?.spirepdf;

    // Check if the WASM module is ready
    if (!pdfModule) {
      alert('Spire.PDF is not ready yet');
      return;
    }

    // Load the PDF file into VFS
    const inputFileName = 'Business_Data_Overview.pdf';
    await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}/data/`);

    // Create a PdfDocument object and load the PDF document
    let doc = new pdfModule.PdfDocument();
    doc.LoadFromFile(inputFileName);

    // Get the first page
    let page = doc.Pages.get_Item(0);

    // Create a PdfImageHelper object and get the image information on the first page
    let helper = new pdfModule.PdfImageHelper();
    let images = helper.GetImagesInfo(page);

    // Iterate through the images on the page, save each as a separate image file, and trigger download
    for (let i = 0; i < images.length; i++) {
      const outputFileName = `ExtractedImage_${i + 1}.png`;
      images[i].Image.Save({ fileName: outputFileName });

      // Read the extracted image file from VFS and trigger download
      const fileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
      const blob = new Blob([fileArray], { type: 'image/png' });
      const url = URL.createObjectURL(blob);
      const a = document.createElement('a');
      a.href = url;
      a.download = outputFileName;
      a.click();
      URL.revokeObjectURL(url);
    }

    doc.Close();
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Extract Images From PDF</h1>
      <button onClick={extractImagesFromPdf}>
        Generate
      </button>
    </div>
  );
}

export default App;
Image files extracted from the PDF
FAQ
How to identify which image to replace or delete
Reason: GetImagesInfo returns an array of information for all images on the page; the order of the array is related to how the images are arranged on the page.
Solution: You can access a specific image through the array index, for example images[0] represents the first image on the page; you can also read the Bounds property of the image information object to determine the region where the image is located, and then filter out the target image based on the position. The following example demonstrates how to delete images based on the region they occupy:
// Get the image information on the page
let helper = new pdfModule.PdfImageHelper();
let images = helper.GetImagesInfo(page);

// Iterate through the images and delete those within the specified region
for (let i = 0; i < images.length; i++) {
  let rect = new pdfModule.RectangleF({ x: 100, y: 300, width: 30, height: 40 });
  if (images[i].Bounds.IntersectsWith({ rect: rect })) {
    helper.DeleteImage({ imageInfo: images[i] });
  }
}
How to precisely control the position and size of an image when adding it
Reason: The coordinate and size parameters of DrawImage directly determine how the image is displayed on the page.
Solution: x and y are the coordinates of the top-left corner of the image, and width and height are the display size. To scale by the original proportion, first read image.Width and image.Height, then multiply by a scale factor to calculate the target size; to center the image, read page.Canvas.ClientSize.Width to calculate the horizontal coordinate, for example x = (page.Canvas.ClientSize.Width - width) / 2.
Will replacing or deleting images affect the text and other content in the PDF?
Reason: The replace and delete operations only act on the image objects themselves.
Solution: When replacing an image, the new image inherits the original image's position and placeholder size, and the rest of the page remains unchanged; after deleting an image, the original position is left blank, and the other text, graphics, and layout on the page are unaffected. Extracting images is a read-only operation and does not modify the original document.
Get a Free License
If you want to remove the evaluation messages in the resulting documents or get rid of functional limitations, contact sales to obtain a 30-day temporary license.
Convert PDF to HTML with JavaScript in React
Converting PDF to HTML is important for improving accessibility and interactivity in web environments. While PDFs are widely used for their reliable layout and ease of sharing, they can be restrictive when it comes to online use. HTML provides greater flexibility, allowing content to be displayed more effectively on websites and mobile devices. By converting a PDF document into HTML, developers can enhance search engine visibility, enable easier editing, and create more user-friendly experiences. In this article, we will demonstrate how to convert PDF to HTML in React with JavaScript and the Spire.PDF for JavaScript library.
- Convert PDF to HTML in React
- Customize PDF to HTML Conversion Settings in React
- Convert PDF to HTML Stream in React
Install Spire.PDF for JavaScript
To get started with converting PDF to HTML with JavaScript in a React application, you can either download Spire.PDF for JavaScript from our website or install it via npm with the following command:
npm i spire.office
The downloaded product package integrates Spire.Doc for JavaScript, Spire.XLS for JavaScript, Spire.PDF for JavaScript, and Spire.Presentation for JavaScript. To use Spire.PDF for JavaScript functionality, you need to copy the corresponding files (spire.pdf.js, Spire.Pdf.Wasm.zip, spire.common.js, Spire.Common.Wasm.zip, and the _framework folder) to the public folder of your project. Additionally, to ensure proper text rendering, font files can be added to a custom path of your choice. In the following example, the font addition path is: public\static\font.
For more details, refer to the documentation: How to Integrate Spire.PDF for JavaScript in a React Project
Convert PDF to HTML in React
The PdfDocument.SaveToFile() method offered by Spire.PDF for JavaScript allows developers to effortlessly convert a PDF file into HTML format. The detailed steps are as follows.
- Load the required font file and the input PDF file into the Virtual File System (VFS).
- Create a PdfDocument object with the wasmModule.PdfDocument() method.
- Load the PDF file using the PdfDocument.LoadFromFile() method.
- Save the PDF file to HTML format using the PdfDocument.SaveToFile() method.
- JavaScript
import React, { useState, useEffect } from 'react';

function App() {
   const [wasmModule, setWasmModule] = useState(null);
   useEffect(() => {
    (async () => {
      try {
        const publicUrl = process.env.PUBLIC_URL || '';
        const spireModule = await import(/* webpackIgnore: true */ `${publicUrl}/spire.pdf.js`);
        const rawModule = spireModule.default || spireModule;
        window.wasmModule = typeof rawModule === 'function'
          ? await rawModule({ locateFile: p => p.endsWith('.wasm') ? `${publicUrl}/${p}` : p })
          : rawModule;
        setWasmModule(window.wasmModule);
      } catch (error) {
        console.error('Failed to load spire.pdf.js:', error);
      }
    })();
  }, []);

  const ConvertPdfToHTML= async () => {
    // Get WASM module
    const wasmModule = window.wasmModule.spirepdf;

    if (wasmModule) {
      // Load font file to virtual file system (VFS)
      await window.spire.FetchFileToVFS("arial.ttf","/Library/Fonts/",`${process.env.PUBLIC_URL}static/font/`);

      // PDF file name to convert
      let inputFileName = "ToHTML.pdf";

      // Load PDF file to virtual file system (VFS)
      await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}static/data/`);

      // Create a PdfDocument object
      let doc =new wasmModule.PdfDocument();

      // Load the PDF file
      doc.LoadFromFile(inputFileName);

      // Define the output file name
      const outputFileName = 'PdfToHtml.html';

      // Save the document to an HTML file
      doc.SaveToFile({fileName: outputFileName, fileFormat: wasmModule.FileFormat.HTML});

      // Read the saved file and convert to a Blob object
      const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
      const modifiedFile = new Blob([modifiedFileArray], { type: "text/html" });

      // Create a URL for the Blob
      const url = URL.createObjectURL(modifiedFile);

      // Create an anchor element to trigger the download
      const a = document.createElement('a');
      a.href = url;
      a.download = outputFileName ;
      document.body.appendChild(a);
      a.click();
      document.body.removeChild(a);
      URL.revokeObjectURL(url);
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF to HTML in React Using JavaScript</h1>
      <button onClick={ConvertPdfToHTML} disabled={!wasmModule}>
        Convert
      </button>
    </div>
  );

}

export default App;
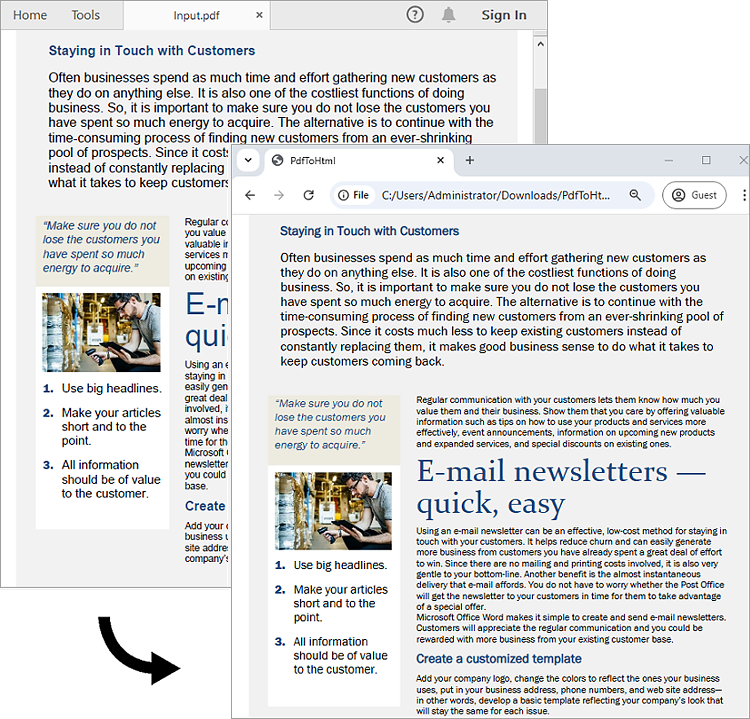
Run the code to launch the React app at localhost:3000. Once it's running, click on the "Convert" button to convert the PDF file to HTML format:
Here is the screenshot of the input PDF file and the converted HTML file:
Customize PDF to HTML Conversion Settings in React
Developers can use the PdfDocument.ConvertOptions.SetPdfToHtmlOptions() method to customize settings during the PDF to HTML conversion process. For instance, they can choose whether to embed SVG or images in the resulting HTML and set the maximum number of pages included in each HTML file. The detailed steps are as follows.
- Load the required font file and the input PDF file into the Virtual File System (VFS).
- Create a PdfDocument object with the wasmModule.PdfDocument() method.
- Load the PDF file using the PdfDocument.LoadFromFile() method.
- Customize the PDF to HTML conversion settings using the PdfDocument.ConvertOptions.SetPdfToHtmlOptions() method.
- Save the PDF document to HTML format using the PdfDocument.SaveToFile() method.
- JavaScript
import React, { useState, useEffect } from 'react';

function App() {
   const [wasmModule, setWasmModule] = useState(null);
   useEffect(() => {
    (async () => {
      try {
        const publicUrl = process.env.PUBLIC_URL || '';
        const spireModule = await import(/* webpackIgnore: true */ `${publicUrl}/spire.pdf.js`);
        const rawModule = spireModule.default || spireModule;
        window.wasmModule = typeof rawModule === 'function'
          ? await rawModule({ locateFile: p => p.endsWith('.wasm') ? `${publicUrl}/${p}` : p })
          : rawModule;
        setWasmModule(window.wasmModule);
      } catch (error) {
        console.error('Failed to load spire.pdf.js:', error);
      }
    })();
  }, []);


  const downloadFileFromVFS = (fileName) => {
    const fileArray = window.dotnetRuntime.Module.FS.readFile(fileName);
    const fileBlob = new Blob([fileArray], { type: 'text/html' });
    const url = URL.createObjectURL(fileBlob);
    const a = document.createElement('a');
    a.href = url;
    a.download = fileName;
    document.body.appendChild(a);
    a.click();
    document.body.removeChild(a);
    URL.revokeObjectURL(url);
  };

  const ConvertPdfToHTML = async () => {
    const wasmModule = window.wasmModule.spirepdf;

    if (wasmModule) {
      await window.spire.FetchFileToVFS("MSYH.TTC", "/Library/Fonts/", `${process.env.PUBLIC_URL}static/font/`);

      // Load the input PDF file into the VFS
      let inputFileName = "ToHTML.pdf";
      await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}static/data/`);
      let doc = new wasmModule.PdfDocument();
      doc.LoadFromFile(inputFileName);

      const totalPages = doc.Pages.Count;

      // Customize the conversion settings
      doc.ConvertOptions.SetPdfToHtmlOptions({ useEmbeddedSvg: false, useEmbeddedImg: true, maxPageOneFile: 1 });

       // Save the document to an HTML file
      const outputFileName = 'PdfToHtmlOptions.html';
      doc.SaveToFile({ fileName: outputFileName, fileFormat: wasmModule.FileFormat.HTML });

      doc.Close();
      doc.Dispose();

      console.log(`totalPages: ${totalPages}`);

      for (let i = 1; i <= totalPages; i++) {
        const fileName = `PdfToHtmlOptions_${i}-${i}.html`;
        downloadFileFromVFS(fileName);
      }
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF to HTML in React Using JavaScript</h1>
      <button onClick={ConvertPdfToHTML}>
        Convert
      </button>
    </div>
  );
}

export default App;
Convert PDF to HTML Stream in React
Spire.PDF for JavaScript also supports converting a PDF to an HTML stream using the PdfDocument.SaveToStream() method. The detailed steps are as follows.
- Load the required font file and the input PDF file into the Virtual File System (VFS).
- Create a PdfDocument object with the wasmModule.PdfDocument() method.
- Load the PDF file using the PdfDocument.LoadFromFile() method.
- Create a memory stream using the wasmModule.Stream() method.
- Save the PDF document as an HTML stream using the PdfDocument.SaveToStream() method.
- Write the content of the stream to an HTML file using the window.dotnetRuntime.Module.FS.readFile() method.
- JavaScript
import React, { useState, useEffect } from 'react';

function App() {
   const [wasmModule, setWasmModule] = useState(null);
   useEffect(() => {
    (async () => {
      try {
        const publicUrl = process.env.PUBLIC_URL || '';
        const spireModule = await import(/* webpackIgnore: true */ `${publicUrl}/spire.pdf.js`);
        const rawModule = spireModule.default || spireModule;
        window.wasmModule = typeof rawModule === 'function'
          ? await rawModule({ locateFile: p => p.endsWith('.wasm') ? `${publicUrl}/${p}` : p })
          : rawModule;
        setWasmModule(window.wasmModule);
      } catch (error) {
        console.error('Failed to load spire.pdf.js:', error);
      }
    })();
  }, []);

  const ConvertPdfToHTML = async () => {
    const wasmModule = window.wasmModule.spirepdf;

    if (wasmModule) {
      await window.spire.FetchFileToVFS("MSYH.TTC", "/Library/Fonts/", `${process.env.PUBLIC_URL}static/font/`);

      // Load the input PDF file into the VFS
      let inputFileName = "ToHTML.pdf";
      await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}static/data/`);
      let doc = new wasmModule.PdfDocument();
      doc.LoadFromFile(inputFileName);

      // Define the output file name
      const outputFileName = 'PdfToHtmlStream.html';
      // Create a new memory stream
     let ms = new wasmModule.Stream();

     // Save the file as HTML stream
     doc.SaveToStream({stream: ms, fileformat: wasmModule.FileFormat.HTML});
     ms.Save(outputFileName);

     // Release resources
     ms.Close();
     doc.Close();

     // Read the saved HTML file and convert to a Blob object
     const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
     const modifiedFile = new Blob([modifiedFileArray], { type: "text/html" });

     // Create a Blob URL and trigger download
     const url = URL.createObjectURL(modifiedFile);
     const a = document.createElement('a');
     a.href = url;
     a.download = outputFileName;
     document.body.appendChild(a);
     a.click();
     document.body.removeChild(a);
     URL.revokeObjectURL(url);
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF to HTML in React Using JavaScript</h1>
      <button onClick={ConvertPdfToHTML}>
        Convert
      </button>
    </div>
  );
}

export default App;
Get a Free License
To fully experience the capabilities of Spire.PDF for JavaScript without any evaluation limitations, you can request a free 30-day trial license.
Convert PDF to Word with JavaScript in React
Converting PDF files to Word documents is essential for modern web applications focused on document management and editing. Using JavaScript and React, developers can easily integrate this functionality with libraries like Spire.PDF for JavaScript. This guide will walk you through implementing a PDF-to-Word conversion feature in a React application, showing how to load files, configure settings, and enable users to download their converted documents effortlessly.
Install Spire.PDF for JavaScript
To get started with converting PDF to Word with JavaScript in a React application, you can either download Spire.PDF for JavaScript from our website or install it via npm with the following command:
npm i spire.office
The downloaded product package integrates Spire.Doc for JavaScript, Spire.XLS for JavaScript, Spire.PDF for JavaScript, and Spire.Presentation for JavaScript. To use Spire.PDF for JavaScript functionality, you need to copy the corresponding files (spire.pdf.js, Spire.Pdf.Wasm.zip, spire.common.js, Spire.Common.Wasm.zip, and the _framework folder) to the public folder of your project. Additionally, to ensure proper text rendering, font files can be added to a custom path of your choice. In the following example, the font addition path is: public\static\font.
For more details, refer to the documentation: How to Integrate Spire.PDF for JavaScript in a React Project
Convert PDF to Word Using PdfToDocConverter Class
The PdfToDocConverter class from Spire.PDF for JavaScript facilitates the conversion of PDF files to Word documents. It includes the DocxOptions property, allowing developers to customize conversion settings, including document properties. The conversion is performed using the SaveToDocx() method.
Steps to convert PDF to Word using the PdfToDocConverter class in React:
- Load the necessary font files and input PDF file into the virtual file system (VFS).
- Instantiate a PdfToDocConverter object using the wasmModule.PdfToDocConverter() method, passing the PDF file path.
- Customize the generated Word file's properties using the DocxOptions property.
- Use the SaveToDocx() method to convert the PDF document.
- Trigger the download of the resulting Word file.
- JavaScript
import React, { useState, useEffect } from 'react';

function App() {
   const [wasmModule, setWasmModule] = useState(null);
   useEffect(() => {
    (async () => {
      try {
        const publicUrl = process.env.PUBLIC_URL || '';
        const spireModule = await import(/* webpackIgnore: true */ `${publicUrl}/spire.pdf.js`);
        const rawModule = spireModule.default || spireModule;
        window.wasmModule = typeof rawModule === 'function'
          ? await rawModule({ locateFile: p => p.endsWith('.wasm') ? `${publicUrl}/${p}` : p })
          : rawModule;
        setWasmModule(window.wasmModule);
      } catch (error) {
        console.error('Failed to load spire.pdf.js:', error);
      }
    })();
  }, []);

  const ConvertPdfToWord= async () => {
    // Get WASM module
    const wasmModule = window.wasmModule.spirepdf;

    if (wasmModule) {
      // Load font file to virtual file system (VFS)
      await window.spire.FetchFileToVFS("arial.ttf","/Library/Fonts/",`${process.env.PUBLIC_URL}static/font/`);

      // PDF file name to convert
      let inputFileName = "ToDocx.pdf";
      // Load PDF file to virtual file system (VFS)
      await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}static/data/`);

      // Create a PdfToDocConverter object
      let converter =new wasmModule.PdfToDocConverter({filePath: inputFileName});

      // Set document properties of the generated Word file
      converter.DocxOptions.Subject = "Convert PDF to Word";
      converter.DocxOptions.Authors = "E-ICEBLUE"

      // Define the output file name
      const outputFileName = "ToWord.docx";

      // Convert PDF as a Docx file
      converter.SaveToDocx({fileName: outputFileName});

      // Read the saved file and convert to a Blob object
      const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
      const modifiedFile = new Blob([modifiedFileArray], { type: "msword" });

      // Create a URL for the Blob
      const url = URL.createObjectURL(modifiedFile);

      // Create an anchor element to trigger the download
      const a = document.createElement('a');
      a.href = url;
      a.download = outputFileName ;
      document.body.appendChild(a);
      a.click();
      document.body.removeChild(a);
      URL.revokeObjectURL(url);
    }
  };

    return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF to Word in React</h1>
      <button onClick={ConvertPdfToWord}>
        Convert
      </button>
    </div>
  );
}

export default App;
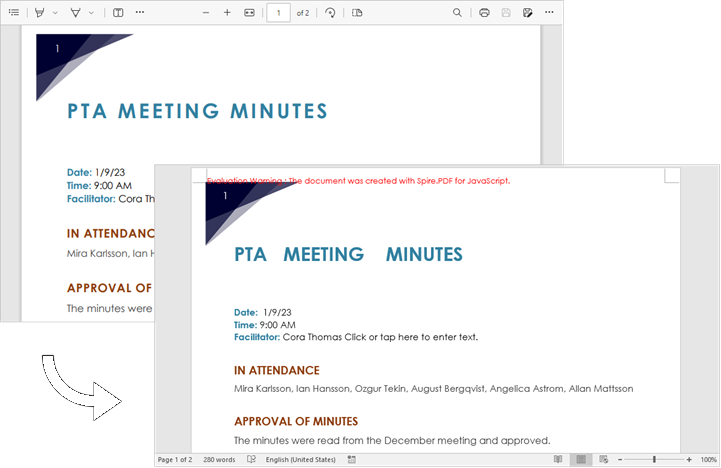
Run the code to launch the React app at localhost:3000. Click "Convert," and a "Save As" window will appear, prompting you to save the output file in your chosen folder.

Below is a screenshot showing the input PDF file and the output Word file:
Convert PDF to Word Using PdfDocument Class
To convert PDF to Word, you can also use the PdfDocument class. This class allows developers to load an existing PDF document, make modifications, and save it as a Word file. This feature is particularly useful for users who need to edit or enhance their PDFs before conversion.
Steps to convert PDF to Word Using the PdfDocument class in React:
- Load the necessary font files and input PDF file into the virtual file system (VFS).
- Create a PdfDocument object using the wasmModule.PdfDocument() method
- Load the PDF document using the PdfDocument.LoadFromFile() method.
- Convert the PDF document to a Word file using the PdfDocument.SaveToFile() method.
- Trigger the download of the resulting Word file.
- JavaScript
import React, { useState, useEffect } from 'react';

function App() {
   const [wasmModule, setWasmModule] = useState(null);
   useEffect(() => {
    (async () => {
      try {
        const publicUrl = process.env.PUBLIC_URL || '';
        const spireModule = await import(/* webpackIgnore: true */ `${publicUrl}/spire.pdf.js`);
        const rawModule = spireModule.default || spireModule;
        window.wasmModule = typeof rawModule === 'function'
          ? await rawModule({ locateFile: p => p.endsWith('.wasm') ? `${publicUrl}/${p}` : p })
          : rawModule;
        setWasmModule(window.wasmModule);
      } catch (error) {
        console.error('Failed to load spire.pdf.js:', error);
      }
    })();
  }, []);

  const ConvertPdfToWord= async () => {
    // Get WASM module
    const wasmModule = window.wasmModule.spirepdf;

    if (wasmModule) {
      // Load font file to virtual file system (VFS)
      await window.spire.FetchFileToVFS("arial.ttf","/Library/Fonts/",`${process.env.PUBLIC_URL}static/font/`);

      // PDF file name to convert
      let inputFileName = "ToDocx.pdf";

      // Load PDF file to virtual file system (VFS)
      await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}static/data/`);

      // Create a PdfDocument object
      let doc =new wasmModule.PdfDocument();

      // Load the PDF file
      doc.LoadFromFile(inputFileName);

      // Define the output file name
      const outputFileName = "ToWord.docx";

      // Convert PDF as a Docx file
      doc.SaveToFile({fileName: outputFileName,fileFormat: wasmModule.FileFormat.DOCX});

      // Read the saved file and convert to a Blob object
      const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
      const modifiedFile = new Blob([modifiedFileArray], { type: "msword" });

      // Create a URL for the Blob
      const url = URL.createObjectURL(modifiedFile);

      // Create an anchor element to trigger the download
      const a = document.createElement('a');
      a.href = url;
      a.download = outputFileName ;
      document.body.appendChild(a);
      a.click();
      document.body.removeChild(a);
      URL.revokeObjectURL(url);
    }
  };

  return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF to Word in React</h1>
      <button onClick={ConvertPdfToWord}>
        Convert
      </button>
    </div>
  );

}

export default App;
Get a Free License
To fully experience the capabilities of Spire.PDF for JavaScript without any evaluation limitations, you can request a free 30-day trial license.
Convert PDF to Excel Using JavaScript in React
In data-driven workflows, converting PDF documents with tables to Excel improves accessibility and usability. While PDFs preserve document integrity, their static nature makes data extraction challenging, often leading to error-prone manual work. By leveraging JavaScript in React, developers can automate the conversion process, seamlessly transferring structured data like financial reports into Excel worksheets for real-time analysis and collaboration. This article explores how to use Spire.PDF for JavaScript to efficiently convert PDFs to Excel files with JavaScript in React applications.
- Steps to Convert PDF to Excel Using JavaScript
- Simple PDF to Excel Conversion in JavaScript
- Convert PDF to Excel with XlsxLineLayoutOptions
- Convert PDF to Excel with XlsxTextLayoutOptions
Install Spire.PDF for JavaScript
To get started with converting PDF to Excel with JavaScript in a React application, you can either download Spire.PDF for JavaScript from our website or install it via npm with the following command:
npm i spire.office
The downloaded product package integrates Spire.Doc for JavaScript, Spire.XLS for JavaScript, Spire.PDF for JavaScript, and Spire.Presentation for JavaScript. To use Spire.PDF for JavaScript functionality, you need to copy the corresponding files (spire.pdf.js, Spire.Pdf.Wasm.zip, spire.common.js, Spire.Common.Wasm.zip, and the _framework folder) to the public folder of your project. Additionally, to ensure proper text rendering, font files can be added to a custom path of your choice. In the following example, the font addition path is: public\static\font.
For more details, refer to the documentation: How to Integrate Spire.PDF for JavaScript in a React Project
Steps to Convert PDF to Excel Using JavaScript
With the Spire.PDF for JavaScript WebAssembly module, PDF documents can be loaded from the Virtual File System (VFS) using the PdfDocument.LoadFromFile() method and converted into Excel workbooks using the PdfDocument.SaveToFile() method.
In addition to direct conversion, developers can customize the process by configuring conversion options through the XlsxLineLayoutOptions and XlsxTextLayoutOptions classes, along with the PdfDocument.ConvertOptions.SetPdfToXlsxOptions() method.
The following steps demonstrate how to convert a PDF document to an Excel file using Spire.PDF for JavaScript:
- Load the Spire.Pdf.Base.js file to initialize the WebAssembly module.
- Fetch the PDF file into the Virtual File System (VFS) using the window.spire.FetchFileToVFS() method.Create an instance of the PdfDocument class using the wasmModule.PdfDocument() method.
- Fetch the font files used in the PDF document to the “/Library/Fonts/” folder in the VFS using the wasmModule.FetchFileToVFS() method.
- Create an instance of the PdfDocument class using the wasmModule.PdfDocument() method.
- Load the PDF document from the VFS into the PdfDocument instance using the PdfDocument.LoadFromFile() method.
- (Optional) Customize the conversion options:
- Create an instance of the XlsxLineLayoutOptions or XlsxTextLayoutOptions class and specify the desired conversion settings.
- Apply the conversion options using the PdfDocument.ConvertOptions.SetPdfToXlsxOptions() method.
- Convert the PDF document to an Excel file using the PdfDocument.SaveToFile({ filename: string, wasmModule.FileFormat.XLSX }) method.
- Retrieve the converted file from the VFS for download or further use.
Simple PDF to Excel Conversion in JavaScript
Developers can directly load a PDF document from the VFS and convert it to an Excel file using the default conversion settings. These settings map one PDF page to one Excel worksheet, preserve rotated and overlapped text, allow cell splitting, and enable text wrapping.
Below is a code example demonstrating this process:
- JavaScript
import React, { useState, useEffect } from 'react';

function App() {
   // Store WASM module instance
   const [wasmModule, setWasmModule] = useState(null);

   // Load WASM module when component mounts
   useEffect(() => {
    const loadSpire = async () => {
      try {
        // Get public directory path
        const publicUrl = process.env.PUBLIC_URL || '';
        // Path to WASM JS glue code
        const moduleUrl = `${publicUrl}/spire.pdf.js`;

        // Dynamically import WASM module
        const spireModule = await import(
          /* webpackIgnore: true */
          moduleUrl
        );

        // Extract module exports
        let Module = spireModule.default || spireModule;

        // Handle WASM initialization
        if (typeof Module === 'function') {
          Module = await Module({
            // Callback when WASM runtime initialization is complete
            onRuntimeInitialized: () => {
              console.log('Spire WASM runtime initialized');
              // Set module state after initialization
              setWasmModule(Module);
            },
            // Handle WASM file paths
            locateFile: (path) => {
              if (path.endsWith('.wasm')) {
                return `${publicUrl}/${path}`;
              }
              return path;
            }
          });
        } else {
          // If not a function, set module directly
          setWasmModule(Module);
        }

        // Mount module to window object for global access
        window.Module = Module;
        window.wasmModule = Module;

        return Module;

      } catch (error) {
        console.error('Failed to load spire.pdf.js:', error);
        throw error;
      }
    };

    // Execute load function
    loadSpire();
  }, []);

  const ConvertPDFToExcel= async () => {
    // Get WASM module
    const wasmModule = window.wasmModule.spirepdf;

    if (wasmModule) {
      // Load font file to virtual file system (VFS)
      await window.spire.FetchFileToVFS("arial.ttf","/Library/Fonts/",`${process.env.PUBLIC_URL}static/font/`);

      // PDF file name to convert
      let inputFileName = "ChartSample.pdf";

      // Load PDF file to virtual file system (VFS)
      await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}static/data/`);

      // Create PDF document object
      let doc = new wasmModule.PdfDocument();

      // Load PDF file
      doc.LoadFromFile(inputFileName);

      // Define the output file name
      const outputFileName = "ToXLSX_result.xlsx";

      // Save the document to the specified path
      doc.SaveToFile({fileName: outputFileName,fileFormat: wasmModule.FileFormat.XLSX});
      doc.Close();

      // Read the saved file and convert to a Blob object
      const modifiedFileArray = window.dotnetRuntime.Module.FS.readFile(outputFileName);
      const modifiedFile = new Blob([modifiedFileArray], { type: "application/vnd.openxmlformats-officedocument.spreadsheetml.sheet" });

      // Create a URL for the Blob
      const url = URL.createObjectURL(modifiedFile);

      // Create an anchor element to trigger the download
      const a = document.createElement('a');
      a.href = url;
      a.download = outputFileName ;
      document.body.appendChild(a);
      a.click();
      document.body.removeChild(a);
      URL.revokeObjectURL(url);
    }
  };

   return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF to Excel in React</h1>
      <button onClick={ConvertPDFToExcel}>
        Convert
      </button>
    </div>
  );
}

export default App;
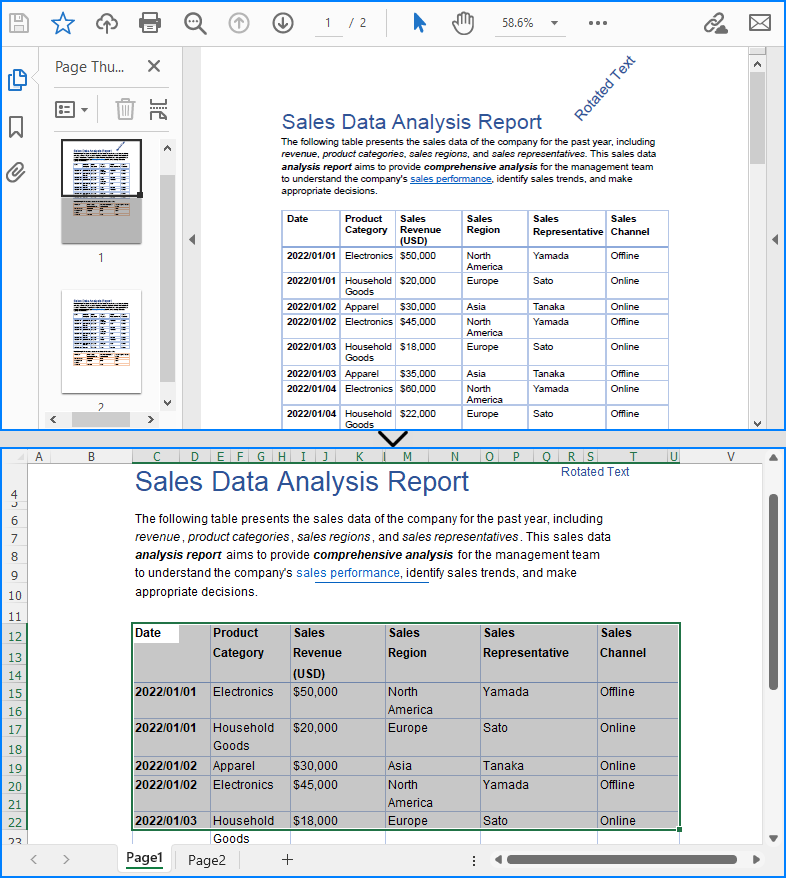
Convert PDF to Excel with XlsxLineLayoutOptions
Spire.PDF for JavaScript provides the XlsxLineLayoutOptions class for configuring line-based conversion settings when converting PDFs to Excel. By adjusting these options, developers can achieve different conversion results, such as merging all PDF pages into a single worksheet.
The table below outlines the available parameters in XlsxLineLayoutOptions:
| Parameter (bool) | Function |
| convertToMultipleSheet | Specifies whether to convert each page into a separate worksheet. |
| rotatedText | Specifies whether to retain rotated text. |
| splitCell | Specifies whether to split cells. |
| wrapText | Specifies whether to wrap text within cells. |
| overlapText | Specifies whether to retain overlapped text. |
Special attention should be given to the splitCell parameter, as it significantly impacts the way tables are converted. Setting it to false preserves table cell structures, making the output table cells more faithful to the original PDF. Conversely, setting it to true allows plain text to be split smoothly in cells, which may be useful for text-based layouts rather than structured tables.
Below is a code example demonstrating PDF-to-Excel conversion using XlsxLineLayoutOptions:
- JavaScript
import React, { useState, useEffect } from 'react';

function App() {
   const [wasmModule, setWasmModule] = useState(null);
   useEffect(() => {
    (async () => {
      try {
        const publicUrl = process.env.PUBLIC_URL || '';
        const spireModule = await import(/* webpackIgnore: true */ `${publicUrl}/spire.pdf.js`);
        const rawModule = spireModule.default || spireModule;
        window.wasmModule = typeof rawModule === 'function'
          ? await rawModule({ locateFile: p => p.endsWith('.wasm') ? `${publicUrl}/${p}` : p })
          : rawModule;
        setWasmModule(window.wasmModule);
      } catch (error) {
        console.error('Failed to load spire.pdf.js:', error);
      }
    })();
  }, []);

  const ConvertPDFToExcelXlsxLineLayoutOptions = async () => {
    // Get WASM module
    const wasmModule = window.wasmModule.spirepdf;

    if (wasmModule) {
      // Load font file to virtual file system (VFS)
      await window.spire.FetchFileToVFS("arial.ttf","/Library/Fonts/",`${process.env.PUBLIC_URL}static/font/`);

      // PDF file name to convert
      let inputFileName = "PdfToExcel.pdf";

      // Load PDF file to virtual file system (VFS)
      await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}static/data/`);

      // Create PDF document object
      let doc = new wasmModule.PdfDocument();

      // Load PDF file
      doc.LoadFromFile(inputFileName);

      doc.ConvertOptions.SetPdfToXlsxOptions(
          new wasmModule.XlsxLineLayoutOptions({convertToMultipleSheet: false, rotatedText: true, splitCell: true}));

      // Define the output file name
      const outputFileName = "PdfToExcelOptions_out.xlsx";

      // Save the document to the specified path
      doc.SaveToFile({fileName: outputFileName,fileFormat: wasmModule.FileFormat.XLSX});
      doc.Close();

      // Read the generated JPG file
      const modifiedFileArray =window.dotnetRuntime.Module.FS.readFile(outputFileName);
      // Create a Blob object from the JPG file
      const modifiedFile = new Blob([modifiedFileArray], { type: "application/vnd.openxmlformats-officedocument.spreadsheetml.sheet" });
      // Create a URL for the Blob
      const url = URL.createObjectURL(modifiedFile);

      // Create an anchor element to trigger the download
      const a = document.createElement('a');
      a.href = url;
      a.download = outputFileName;
      document.body.appendChild(a);
      a.click();
      document.body.removeChild(a);
      URL.revokeObjectURL(url);

    }
  };

   return (
    <div style={{ textAlign: 'center', height: '300px' }}>
      <h1>Convert PDF to Excel with XlsxLineLayoutOptions Using JavaScript in React</h1>
        <button onClick={ConvertPDFToExcelXlsxLineLayoutOptions}>
          Convert and Download
        </button>
    </div>
  );
}

export default App;
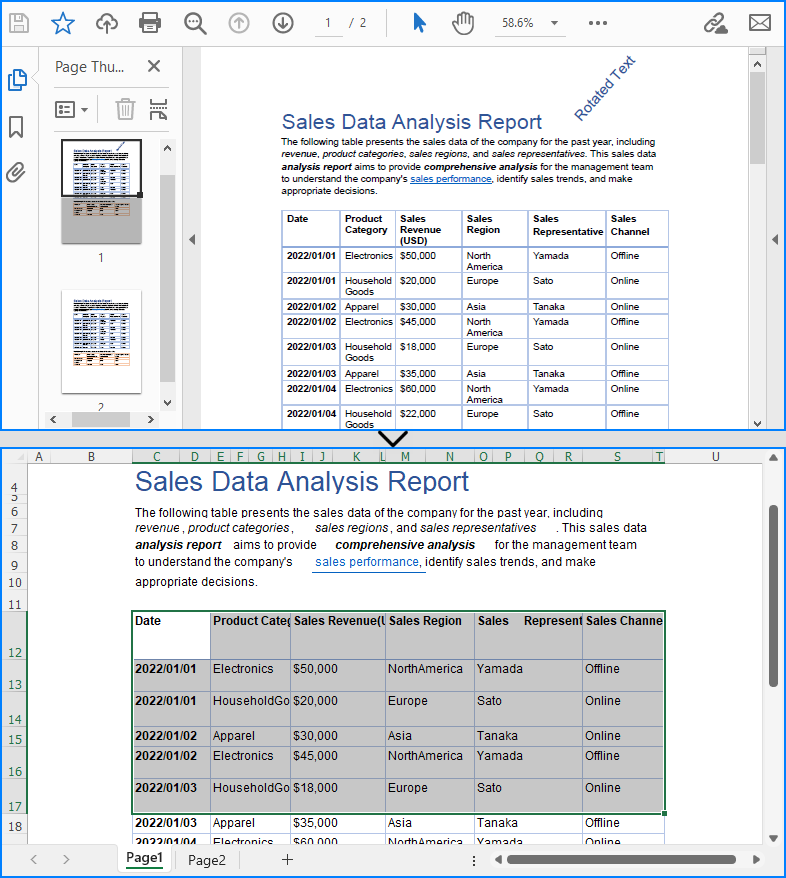
Convert PDF to Excel Using XlsxTextLayoutOptions
Developers can also customize conversion settings using the XlsxTextLayoutOptions class, which focuses on text-based layout formatting. The table below lists its parameters:
| Parameter (bool) | Function |
| convertToMultipleSheet | Specifies whether to convert each page into a separate worksheet. |
| rotatedText | Specifies whether to retain rotated text. |
| overlapText | Specifies whether to retain overlapped text. |
Below is a code example demonstrating PDF-to-Excel conversion using XlsxTextLayoutOptions:
- JavaScript
import React, { useState, useEffect } from 'react';

function App() {
   const [wasmModule, setWasmModule] = useState(null);
   useEffect(() => {
    (async () => {
      try {
        const publicUrl = process.env.PUBLIC_URL || '';
        const spireModule = await import(/* webpackIgnore: true */ `${publicUrl}/spire.xls.js`);
        const rawModule = spireModule.default || spireModule;
        window.wasmModule = typeof rawModule === 'function'
          ? await rawModule({ locateFile: p => p.endsWith('.wasm') ? `${publicUrl}/${p}` : p })
          : rawModule;
        setWasmModule(window.wasmModule);
      } catch (error) {
        console.error('Failed to load spire.pdf.js:', error);
      }
    })();
  }, []);

  const ConvertPDFToExcelXlsxTextLayoutOptions = async () => {
    // Get WASM module
    const wasmModule = window.wasmModule.spirepdf;

    if (wasmModule) {
      // Load font file to virtual file system (VFS)
      await window.spire.FetchFileToVFS("arial.ttf","/Library/Fonts/",`${process.env.PUBLIC_URL}static/font/`);

      // PDF file name to convert
      let inputFileName = "PdfToExcel.pdf";

      // Load PDF file to virtual file system (VFS)
      await window.spire.FetchFileToVFS(inputFileName, "", `${process.env.PUBLIC_URL}static/data/`);

      // Create PDF document object
      let doc = new wasmModule.PdfDocument();

      // Load PDF file
      doc.LoadFromFile(inputFileName);

      // Create an instance of the XlsxTextLayoutOptions class and specify the conversion options
      const options =new wasmModule.XlsxTextLayoutOptions({ convertToMultipleSheet: false, rotatedText: true, overlapText: true});

      // Set the XlsxTextLayoutOptions instance as the conversion options
      doc.ConvertOptions.SetPdfToXlsxOptions(options);

      // Define the output file name
      const outputFileName = "PDFToExcelXlsxTextLayoutOptions.xlsx";

      // Save the document to the specified path
      doc.SaveToFile({fileName: outputFileName,fileFormat: wasmModule.FileFormat.XLSX});
      doc.Close();

      // Read the generated JPG file
      const modifiedFileArray =window.dotnetRuntime.Module.FS.readFile(outputFileName);
      // Create a Blob object from the JPG file
      const modifiedFile = new Blob([modifiedFileArray], { type: "application/vnd.openxmlformats-officedocument.spreadsheetml.sheet" });
      // Create a URL for the Blob
      const url = URL.createObjectURL(modifiedFile);

      // Create an anchor element to trigger the download
      const a = document.createElement('a');
      a.href = url;
      a.download = outputFileName;
      document.body.appendChild(a);
      a.click();
      document.body.removeChild(a);
      URL.revokeObjectURL(url);

    }
  };

   return (
      <div style={{ textAlign: 'center', height: '300px' }}>
        <h1>Convert PDF to Excel with XlsxTextLayoutOptions Using JavaScript in React</h1>
        <button onClick={ConvertPDFToExcelXlsxTextLayoutOptions}>
          Convert and Download
        </button>
      </div>
  );
}

export default App;
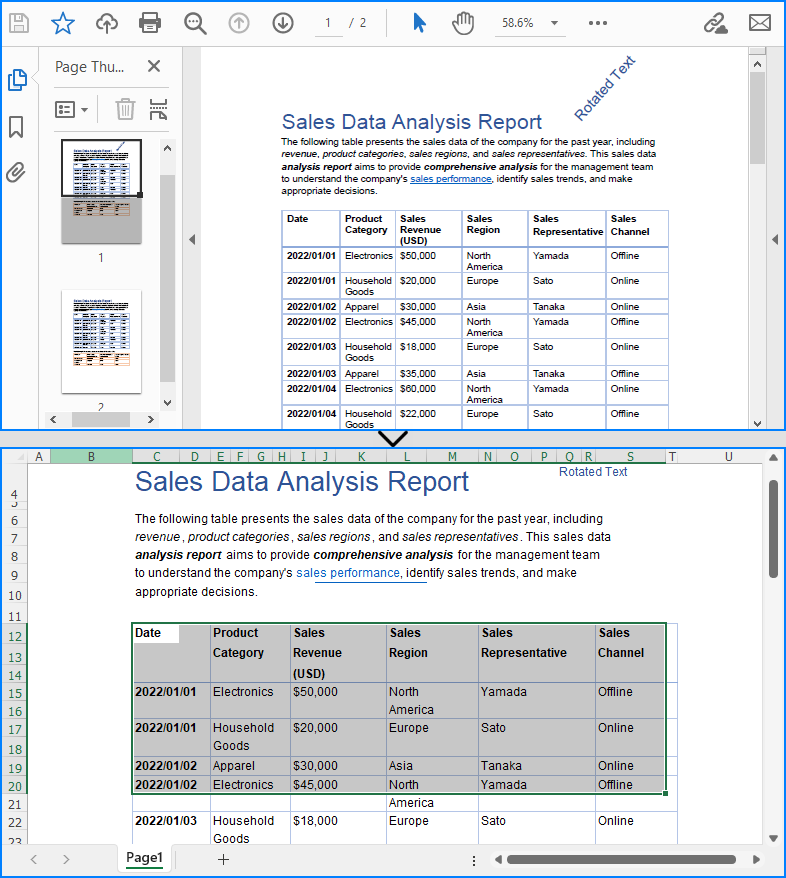
Get a Free License
To fully experience the capabilities of Spire.PDF for JavaScript without any evaluation limitations, you can request a free 30-day trial license.